Why Your Allele Frequency Data Looks Wrong
I spent three months trying to figure out why my SNP data from a supposedly stable population of island frogs showed random fluctuations across generations that I couldn't attribute to anything environmental. The samples were collected at consistent times, reared under identical lab conditions, and the population size looked massive on paper. It took a junior grad student pointing out that I was measuring census size instead of effective population size before I realized what was happening. The frogs had a severe reproductive skew. A handful of males were fathering most offspring. That mistake costs time. It costs credibility with reviewers. But it also forces you to actually understand what you're looking at rather than assuming the data should behave the way you expect it to.Uncovering The Forces Of Change Unveiling The Mysteries Of Genetic Drift In Biology
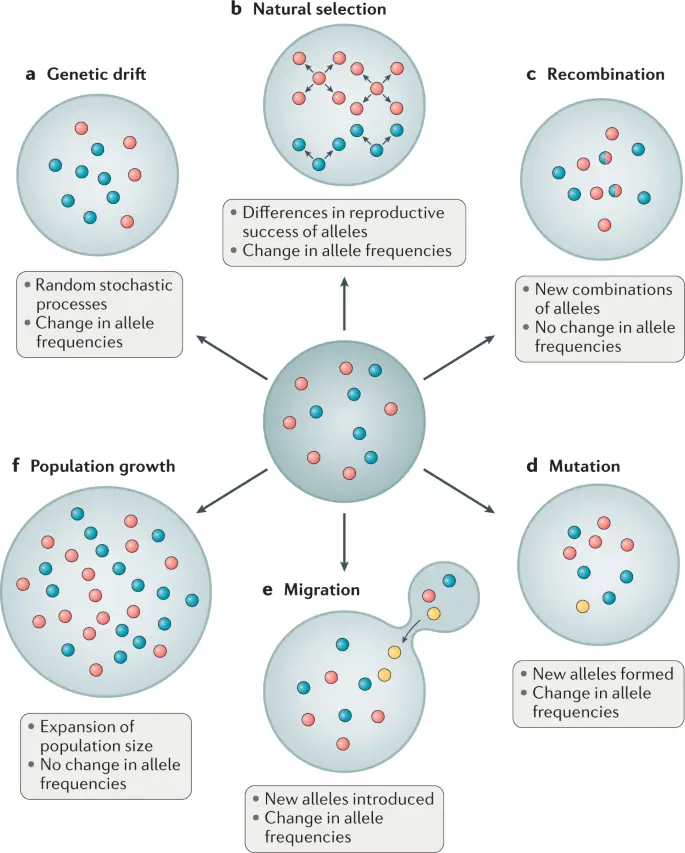
Genetic drift is the change in allele frequencies that occurs purely by chance across generations. That's the textbook definition. The actual behavior is messier and far more consequential than that sentence suggests. Every finite population experiences drift. The question is never whether it's happening. The question is how much it matters relative to selection, migration, or mutation in your particular system. Consider what happens when you have a population of 1,000 organisms carrying a neutral allele at frequency 0.5. The expected change in that allele frequency from one generation to the next is zero. But the variance of that change is p times q divided by two N e. With those numbers, you're looking at a standard deviation of roughly 0.016 per generation. In any single generation, your observed frequency might jump to 0.47 or 0.53 purely by sampling error in gamete formation. Over twenty generations, the cumulative effect becomes substantial. The allele could drift to fixation or be lost entirely without any selective pressure whatsoever. I used to think drift only mattered for small populations. That's backwards. Drift operates in every population. It's just that the signal gets drowned out by selection in large populations. When your effective population size drops below a few hundred, drift starts competing with weak selection. Below fifty, drift dominates almost everything except strong positive or negative selection. This is why captive breeding programs for endangered species routinely lose genetic diversity even when managers try to maintain large headcounts. The effective population size of a managed population is almost always a fraction of the census size.
The math here is straightforward but easy to misapply. The rate of heterozygosity loss per generation due to drift alone equals one divided by two N e. If your effective population size is 100, you lose half a percent of heterozygosity each generation. Over one hundred generations, that compounds to roughly a thirty-nine percent reduction. Not linear. Compounding. People often model this as linear because it's simpler to calculate by hand, and they end up dramatically overestimating long-term diversity retention.
Effective Population Size Is Not What You Think It Is
Census population size and effective population size are related concepts that get treated as interchangeable in too many papers. They are not interchangeable. Effective population size accounts for the fact that not every individual contributes equally to the next generation. Sex ratio skew reduces it. Variation in reproductive success reduces it. Overlapping generations reduce it. Fluctuating population sizes across generations reduce it to the harmonic mean, which is heavily influenced by the smallest values in your series. Here's a practical example. Suppose your population bounces between 200 and 2000 individuals over ten generations. The arithmetic mean is 1100. The harmonic mean, which determines the effective size for drift purposes, comes out to roughly 363. A population that spends most of its time at moderate size can still behave like a much smaller population because bottlenecks exert disproportionate influence on genetic diversity loss. I encountered this when analyzing historical DNA samples from a rodent population that supposedly remained abundant throughout the twentieth century. The genetic data told a different story. Land use changes had created episodic bottlenecks that reduced the effective size to well below two hundred for extended periods, even though census estimates during good years suggested thousands of individuals. If you're working with non-model organisms and need to estimate N e from genetic data, the linkage disequilibrium method generally outperforms temporal methods when you have only a single sample. Temporal methods require samples from at least two generations, which is fine if you're doing prospective work or have archived specimens. The LD method estimates N e from the background correlation between loci, which builds up after a single generation of drift in a finite population. The tradeoff is that LD methods assume random mating and no recent migration, and they can overestimate N e if there's population structure. I use both methods cross-validate when possible. When they agree, I have more confidence. When they diverge, I investigate structure and mating patterns before trusting either number.
Get the Full Details

Simulating Drift: Practical Approaches
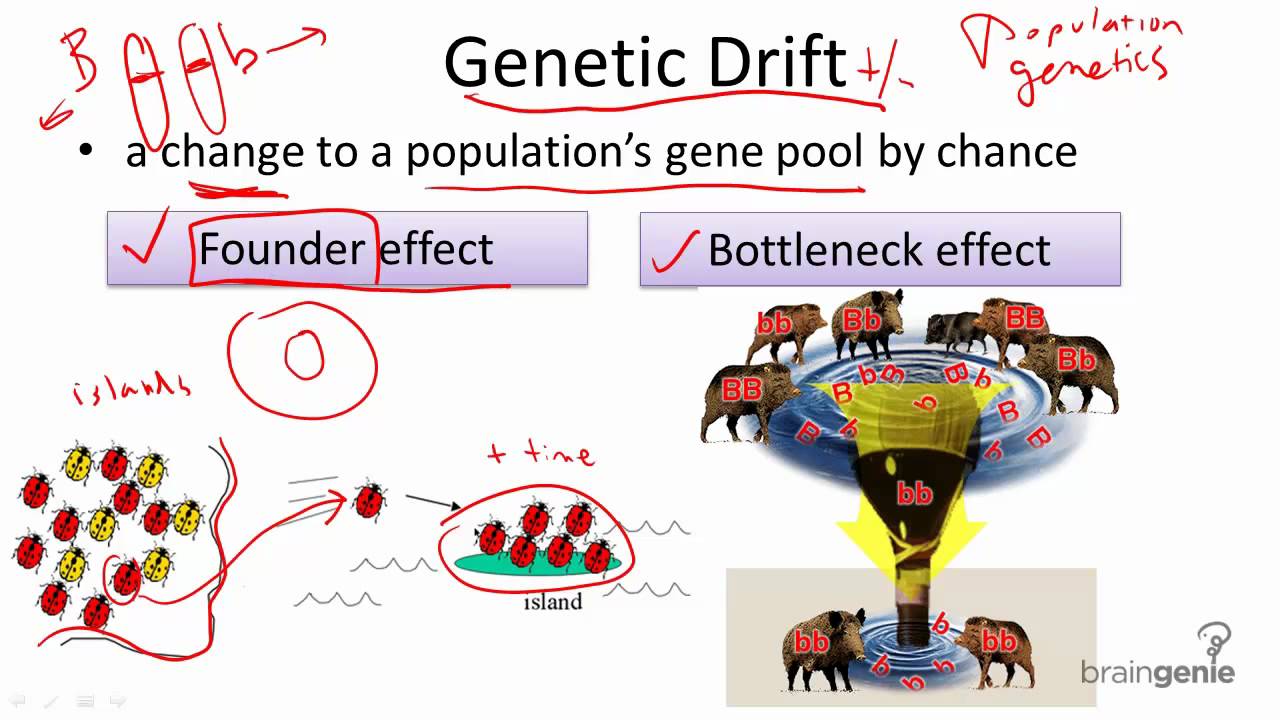
The Wright-Fisher model is the standard simulation framework. Each generation, you draw 2N e gametes with replacement from the parental gene pool. The probability of drawing a particular allele equals its current frequency. Implementing this requires only basic random number generation. A Python script using numpy can simulate hundreds of generations for thousands of loci in under a second on modern hardware. The bottleneck configuration I ran for the frog study simulated a population that dropped to fifty individuals for five generations before recovering to five hundred. Starting allele frequencies were fixed at 0.5 for all simulated loci. After the bottleneck phase, approximately forty percent of loci had lost one allele entirely. Recovery to a larger population size did not restore lost variation. Drift during the bottleneck phase permanently reduced heterozygosity, and the subsequent population growth could not reverse that. This is a pattern you see repeatedly in conservation genetics data. The genetic signature of a past bottleneck persists for many generations after demographic recovery. For larger simulations where computational efficiency matters, the coalescent approach is far superior. Instead of simulating forward generation by generation, you trace lineages backward in time to their most recent common ancestor. The expected time to coalescence for two lineages in a diploid population is two N e generations. This means you can model the ancestry of a sample without simulating the entire population history. MrCoalescent and msprime are the standard tools. They handle variable population sizes, migration between demes, and recombination between loci. The downside is that coalescent simulations assume neutrality and the standard Wright-Fisher assumptions. If you need to model selection explicitly, you're back to forward simulation.
When I simulate drift to generate null distributions for hypothesis testing, I usually run at least ten thousand replicates. Fewer than that and the tail of the distribution becomes unreliable, which matters because significance testing depends on the extreme values. For a genome-wide scan detecting loci under selection against a neutral drift backdrop, I need accurate tail estimates. Ten thousand replicates takes roughly fifteen seconds with msprime on a standard laptop. Twenty thousand gives me tighter confidence intervals on the null distribution. The marginal gain diminishes after that, so I rarely go beyond that threshold.
Reading Drift Signals in Real Data
Fst outlier scans remain the most common approach for detecting selection in the presence of drift. The logic is straightforward. Loci under selection will show greater differentiation between populations than neutral loci, which drift differentiates uniformly. BayeScan and Arlequin implement this framework. The challenge is that demographic events like bottlenecks and migration create correlated allele frequency shifts across many loci, which can mimic selection signals if you don't account for population structure properly. I learned this the hard way when scanning a fish population for adaptive loci. The initial Fst outlier analysis flagged dozens of loci as candidates for selection. Replication in a completely independent dataset revealed that most of those signals were artifacts of unsampled substructure. The population I was studying contained two cryptic breeding groups separated by a shallow ridge. Migration between them was low but nonzero. Drift operated somewhat differently in each group, creating allele frequency divergence that outlier detection interpreted as selection. Once I accounted for the structure using a Bayesian clustering approach, the outlier signal dropped to three loci. Three was still biologically interesting. The original fifty were noise. Heterozygosity excess tests detect recent bottlenecks by comparing observed heterozygosity to the heterozygosity expected under mutation-drift equilibrium given the observed number of alleles. Bottleneck software implements this. The test assumes the infinite allele model or the two-phase model for microsatellite mutations. It has low power for ancient bottlenecks because the heterozygosity excess signal decays over time while allele number decreases more slowly. A population that experienced a severe bottleneck five hundred generations ago may show no heterozygosity excess at all, even though it lost substantial allelic diversity. The allele count reflects older demographic events. Heterozygosity reflects more recent ones. Using both metrics together gives you a rough timeline of when the bottleneck occurred.
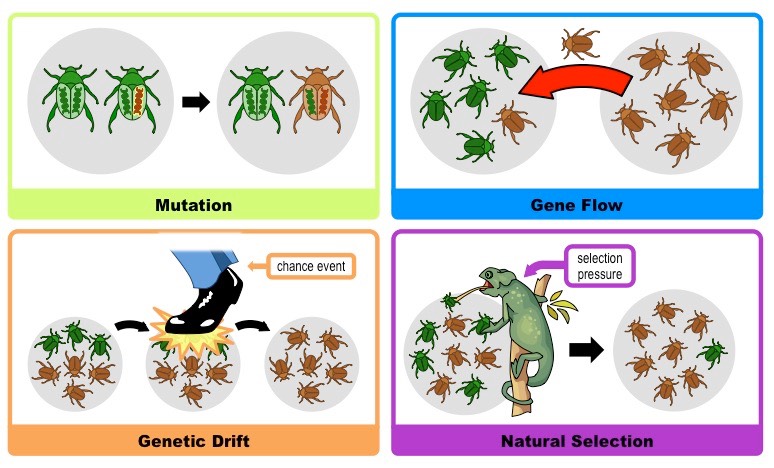
Another signal people overlook is the site frequency spectrum. Drift skews the distribution of allele frequencies in predictable ways. A population that has recently expanded shows an excess of rare alleles because new mutations haven't had time to drift to higher frequencies. A bottlenecked population also shows an excess of rare alleles for a different reason. The bottleneck purges intermediate-frequency alleles, leaving mostly rare variants and a few that happened to drift high. Distinguishing expansion from bottleneck signals requires additional information like spatial structure or paleoclimate data. The SFS alone often cannot resolve the ambiguity.
Common Pitfalls and Where This Approach Fails
The biggest mistake I see is treating genetic drift as a null hypothesis that can be ignored rather than a force that must be modeled explicitly. Many population genomics pipelines treat neutral variation as background noise and focus entirely on detecting selection. That works if your effective population size is large and stable. It produces false positives at alarming rates when N e is small, structure is present, or demographic history is complex. You cannot separate drift from selection without an explicit demographic model. A second pitfall is assuming that genetic drift increases adaptiveness over time. It does not. Drift is blind to fitness. In small populations, drift can fix deleterious alleles and purge beneficial ones purely by chance. This is Muller's ratchet in asexual populations and the general principle of mutational meltdown in small sexual populations. The idea that drift guides populations toward better adaptation is a misconception that persists in introductory textbooks. It does not. Selection does that. Drift introduces noise. Drift also fails to explain patterns in systems where gene flow is high. When migration rates exceed one divided by four N e per generation, population differentiation due to drift is effectively countered. The Wright island model shows this clearly. Populations connected by sufficient gene flow behave as a single large population for neutral markers. Drift signals become invisible across the metapopulation even though they operate within local demes. If you're sampling a single deme in a well-connected metapopulation, you'll detect drift effects in that sample. If you're comparing multiple demes, the drift signal between them may be too weak to measure. The solution is increasing sample size per deme or increasing the number of neutral markers. Ten thousand SNPs from two demes will give you a clearer picture than ten SNPs from twenty demes.
There is also a computational limit. Forward-time simulations of drift become intractable for large populations with recombination across long genomic regions. Simulating a diploid population of ten thousand individuals with recombination across a ten megabase chromosome requires tracking thousands of linked loci across hundreds of generations. The memory and processing demands scale linearly with population size and recombination rate. Coalescent simulations handle this efficiently, but they cannot incorporate arbitrary selection models. If you need to simulate drift plus selection plus recombination in a large population, you're looking at specialized software like SLiM or fwdpy11. These tools are powerful but have steep learning curves. The documentation assumes familiarity with population genetics theory that most biologists do not have. Budget time for that learning curve if this direction becomes necessary for your work. The bottom line is that genetic drift is unavoidable in any finite population, and its effects scale inversely with effective population size. Understanding the difference between census and effective size, choosing the right simulation method for your question, and accounting for demographic history before claiming selection are the practical skills that separate reliable analyses from artifacts. I wish I had internalized those points before wasting three months on the frog data.