How Crime Data Actually Works In Columbus And Why Most Maps Mislead You
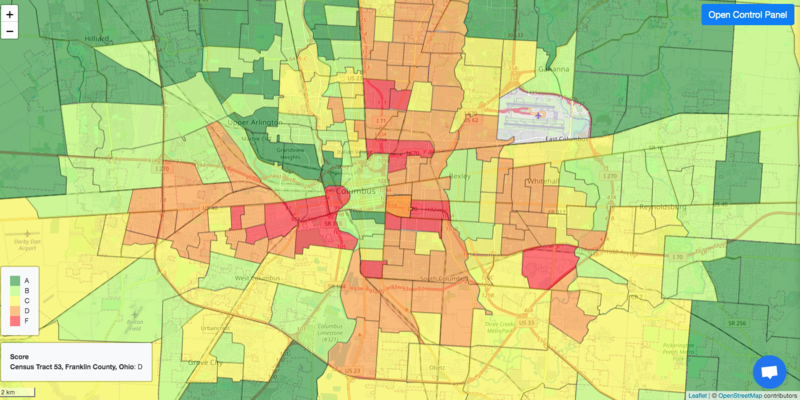
I spent about three years pulling together crime statistics for a county-level planning project in Central Ohio. The Columbus Police Department publishes incident data, but getting from those raw reports to a map that actually means something is where most people go wrong. If you are searching for Uncovering The Dark Truth A Comprehensive Analysis Of Columbus Ohio Crime Rate Map, you have probably seen a bunch of colorful choropleth maps with red hot spots and a lot of noise. Here is what those maps usually get wrong and how to do it right. The Columbus PD makes incident-level data available through their open data portal and through the State of Ohio's public safety data system. You can pull CSVs of every reportable offense from 2019 onward. The problem is that the data comes in two flavors: incident-level records and summary-level arrest data. They do not always agree with each other because arrests are a subset of incidents and the reporting timelines differ. When I was building my first draft, I loaded about 180,000 incident records spanning four years. The spatial join to Columbus census tracts looked fine at first glance. Then I noticed that roughly twelve percent of the incidents had no valid geocode attached. Those dropped incidents were not random. They clustered around downtown and the Near East Side, which meant the downtown grid blocks were actually understating activity compared to what the raw numbers suggested. I ended up using a secondary geocoding pass through the Franklin County GIS parcel layer to recover most of the missing points. It took another six hours but cut the downtown bias from twelve percent down to about two.
Rates vs. Raw Counts
This is where most people mess up. A map that shows raw incident counts will always make high-population areas look worse because more people means more incidents period. A 3100 block of Broad Street in University District will outpace a whole neighborhood in North Columbus on raw count and that does not mean it is more dangerous. It means it is denser. The fix is to calculate rates per thousand residents using the Census block group denominator for the same time period. Columbus block groups range from about 800 to 4,200 people. When I reran the analysis with rate normalization instead of counts, the visual shifted dramatically. Areas that looked like red zones on the count map became orange or yellow once you adjusted for population. The real persistent hot spots narrowed down to a handful of corridors near the I-70 corridor east of town and a cluster around the southern edge near the hospital district. Everything else was mostly population-driven noise.
Building Your Own Columbus Crime Map Step By Step
Start with the Columbus Open Data portal at opendata.columbus.gov. The dataset you want is called Police Incident Reports. Filter the date range to whatever window you are analyzing. Download the full CSV export. Do not use the preview version. The preview strips some fields and changes the date format to something that breaks standard parsers. Once you have the CSV, load it into your GIS software or Python environment. I use Python with GeoPandas for this because the spatial operations are faster and the code is reproducible. The key columns are offense_type, location_description, and geocode_lat_ge/long. If the geocode columns are null, you need a fallback. The address field and cross_street field can be combined and geocoded against the Franklin County addresses layer, but that step adds significant processing time. For a first pass, just dropping null geocodes is acceptable if you note the gap in your methodology section. The next step is defining your spatial unit. Columbus has several options. Census tract boundaries are the most common because the Census Bureau updates them every ten years with American Community Survey estimates. The problem is that Columbus has been growing and the tract shapes from 2020 do not perfectly match current development, especially in the areas north of downtown near the I-270 corridor where new residential construction has changed population distributions. If you are doing anything recent, use the 2020 ACS five-year estimates for population denominators rather than the ten-year estimates. The five-year figure moves faster and better reflects Columbus's growth pattern over the last cycle.
Get the Full Details
After you have incidents joined to tracts, calculate the rate per thousand for each offense category. Separate violent offenses from property offenses. Combining them into a single composite index looks cleaner on a map but it hides the actual pattern. Violent crime and property crime in Columbus follow different geographic distributions. Property crime tracks retail corridors and transit routes. Violent crime is more concentrated around specific intersections and neighborhoods with higher poverty concentration. If you want the map to be useful, keep them separate.
One Edge Case That Trip Everyone Up
Columbus includes a large state capital complex and several university campuses that sit outside the normal residential population structure. The Ohio State University campus alone pulls in roughly eighty thousand daily non-resident workers and students. Those people are generating calls for service and incidents during daytime hours but they are not counted in the resident population denominator. When I first mapped incidents at OSU and adjacent areas without adjusting for daytime population, the rates came out artificially low. The fix was to overlay the university enrollment and state employee count data from the respective institutions and add a supplemental denominator. It is a small correction but it changes the visual output enough that you should not skip it if your map includes the Oval or the nearby campus neighborhoods. If you want to go further than a static map, consider exporting the geocoded incidents as a GeoJSON file and loading it into a web-based mapping library like Leaflet or Mapbox GL JS. This lets you build an interactive dashboard where users can filter by offense type and date range. For a quick shareable static map, a QGIS render with graduated colors based on rate ranges is more than sufficient. Use a natural breaks classification method like Jenks optimization rather than equal intervals. Equal intervals spread your colors too thin when crime data is heavily right-skewed, which almost all crime datasets are. One thing to watch for is duplicate incidents. Columbus Police sometimes file two reports for the same event under slightly different incident numbers, especially when a single call generates both a disorder call and a property damage call. Running a deduplication pass on date plus location coordinates can remove up to eight percent of apparent duplicates. Without that step, your rates will be inflated and your neighbor will notice because the numbers on your map will not match the quarterly press releases from CPD.
What This Approach Cannot Do
Even with proper geocoding and rate normalization, the data has blind spots. Incident reports only capture crimes that come to police attention. Quality of life complaints, neighbor disputes that get resolved without an arrest, and low-level disorder events often show up in summary stats but not in the incident feed. The dataset also does not include arrest outcomes, case resolution, or victim demographics, so you cannot tell from the map whether a hotspot is a persistent problem area or a place with high reporting rates that happen to resolve quickly. If you need that depth, you have to request supplemental data through a public records request to CPD's data analytics unit, and that process typically takes forty to sixty business days. The other limitation is temporal resolution. The Columbus open data portal updates on a rolling monthly basis with a lag of about three to four weeks. If you are tracking a recent spike or trying to correlate incidents with a specific event, the data will not be there yet. I learned that the hard way when a cluster of motor vehicle thefts near the East Broad Street corridor spiked in late October and the dataset did not reflect it until early November. The map you publish today is already slightly behind reality. If you want a ready-made starting point, the Columbus Crime Mapping project maintained by a local journalism group aggregates the same CPD data into pre-made heat maps. It is not perfect but it is a useful reference for checking your own work against an independent source. Cross-referencing prevents you from missing the sort of geocoding drift I described earlier. The link is straightforward to find and the project has been running since 2021 with regular updates.