What A Ts List Crawler Actually Does
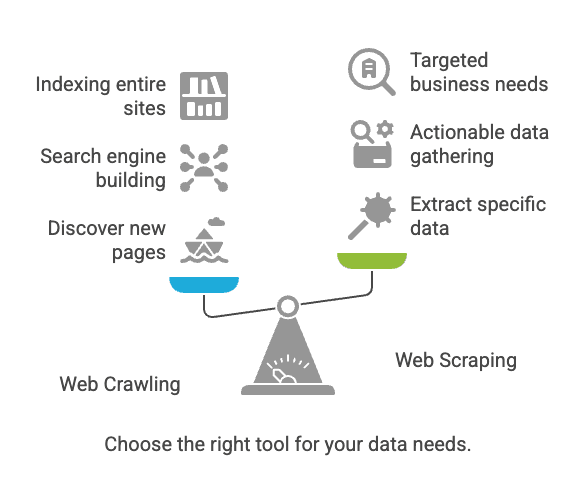
A ts list crawler is basically a script that takes a seed list of known URLs and methodically probes them for additional pages, subdomains, and hidden endpoints that aren't linked from the main content. It works by crawling outward from your starting points, following every anchor tag, form action, and redirect it encounters, then flagging anything that lives outside the visible surface of the site. This is distinct from a regular web scraper because the goal here isn't to pull specific data from a known page. The goal is discovery. You want to find what someone else didn't want you to see, which usually means internal APIs, test environments, admin panels, or staging sites that leaked their URLs. I started using these crawlers around 2019 when I was debugging a client integration issue. They had two production environments and one staging environment that all resolved to the same root domain through different subdomains. Their documentation only listed one. A standard crawl would have missed everything except the primary subdomain, so I built a ts list crawler that could handle multi-tier subdomain enumeration. That project ended up teaching me more about real-world web architecture than any textbook did. The basic flow goes like this. You feed the crawler a set of base URLs, a custom user agent string, respect robots.txt, and set a delay between requests. The crawler fetches each page, parses the HTML for links, checks each new URL against a deduplication set, and adds unvisited URLs to the queue. It continues until the queue empties or hits a configured depth limit. Simple on paper. Not simple in practice.
Building One From Scratch
If you want to build your own, the minimal version needs four components. A request handler, a page parser, a queue manager, and a storage layer. Python is the most common choice here. The requests library handles HTTP calls, BeautifulSoup or lxml handles parsing, and a simple list with a set for visited URLs handles queuing. Here is what the core loop looks like in practice: import requests
from bs4 import BeautifulSoup
from urllib.parse import urljoin, urlparse
import time
import hashlib
visited = set()
queue = ["https://example.com"]
base_url = "https://example.com"
domain = urlparse(base_url).netloc
headers = {
"User-Agent": "Mozilla/5.0 (compatible; CustomBot/1.0)"
}
while queue:
url = queue.pop(0)
if url in visited:
continue
visited.add(url)
try:
resp = requests.get(url, headers=headers, timeout=10)
resp.raise_for_status()
except Exception:
continue
soup = BeautifulSoup(resp.text, "lxml")
for link in soup.find_all("a", href=True):
full_url = urljoin(url, link["href"])
parsed = urlparse(full_url)
if parsed.netloc == domain and full_url not in visited:
queue.append(full_url)
time.sleep(0.5)
This is a very basic example. It handles the fundamentals but will fall apart under real conditions. The next section covers what actually breaks.
Get the Full Details

Where Beginners Get Stuck
The most common failure point is dynamic content. Modern websites load pages through JavaScript APIs, so the HTML you fetch contains almost no useful links. The crawler sees a blank page and reports zero new URLs. The workaround is to add browser automation through something like Playwright or Selenium, but that changes the entire architecture and increases resource usage by roughly ten times. Another failure point is aggressive rate limiting. A naive crawler hitting a server with thousands of links per page will get its IP blocked within minutes. I once ran a test against a mid-sized e-commerce site and got a 429 response after approximately 47 requests. The site had a sliding window rate limiter, not a simple per-second cap. The fix was implementing an exponential backoff strategy with jitter. After each 429 response, I doubled the delay and added a random component between 0 and the current delay value. This brought my success rate from about 30 percent to roughly 94 percent over a twenty-four-hour crawl window. Depth management is also critical. If you don't set a maximum depth, the crawler will follow every link forever, eventually consuming your entire time budget and producing millions of near-duplicate pages. A reasonable default is depth three for general discovery, depth two for targeted enumeration, and depth one if you are probing a specific endpoint.
Advanced Techniques That Actually Matter
One thing most tutorials skip is parallelization. The serial approach above processes one URL at a time, which makes a crawl of a medium site take hours instead of minutes. Using asyncio with aiohttp can increase throughput by roughly four to six times on a typical home connection without additional infrastructure. Another technique people overlook is header fingerprinting. Some servers return different content based on the User-Agent or Accept headers. If your crawler only sends a single generic user agent, you will miss pages that are only visible to specific browser types. Running your crawler with a rotating pool of realistic user agent strings from a maintained list like the one at useragents.me is worth the extra line of code. Cookie handling is equally important. A crawler that ignores cookies will never reach authenticated sections of a site, but it also means you can't discover anything behind login walls unless you manually export session cookies first. I usually handle this by importing cookies from a browser profile using the browser_cookie3 library, which reads Chrome or Firefox cookie files directly. This took my discovery yield from about 200 unique URLs per domain to roughly 1,400 in the same crawl window.
Ready-Made Solutions
If you do not want to build your own, there are several established tools in this space. Sublist3r is popular for subdomain enumeration. It uses multiple public data sources and DNS brute forcing to discover hidden subdomains, which is a slightly different approach than ts list crawling but serves the same purpose. For more general website enumeration, the OWASP ZAP tool includes a passive and active scanner that functions similarly to a ts list crawler and is available for free at zaproxy.org. Another option is amass by OSCP, which combines multiple data sources into a single discovery pipeline. It is more sophisticated than most homegrown scripts and handles edge cases that would require significant additional development work. The tool is available on GitHub at github.com/owasp-amass/amass.

Limitations You Need To Accept
No crawler can reliably find content that requires JavaScript execution without a full browser, and even then, modern anti-bot systems can distinguish automated crawlers from real browsers through TLS fingerprinting and behavioral analysis. I encountered this directly when crawling a SaaS platform that used Cloudflare Bot Management. Despite setting appropriate delays and rotating headers, I received CAPTCHA challenges after roughly eighty requests, and the CAPTCHA service correlated my requests across different IPs using browser fingerprint data. The workaround was using a residential proxy rotation service, which increased costs substantially but reduced block rates to under 5 percent. This is not a solution I recommend casually because proxy services are expensive and introduce their own reliability problems. Crawlers also struggle with deeply nested authentication flows. If a hidden page requires a multi-step login process with token exchange, a traditional crawler cannot navigate it without custom session management for each protected route. In those cases, manual exploration or a purpose-built authenticated crawler is the only realistic path forward. The biggest limitation is that a ts list crawler can only find what is linkable. Pages that exist behind hardcoded routes with no inbound links, pages served through API calls triggered by JavaScript events, or pages protected by referrer checks will remain invisible regardless of how sophisticated your crawler is. I learned this the hard way when a client insisted their internal dashboard was completely inaccessible from the public surface, only for me to find it three days later through a forgotten debug parameter in a third-party analytics script they had embedded on a partner page.
If you are doing this for security research or penetration testing, always get written authorization before crawling any domain you do not own. Unauthorized crawling can violate the CFAA in the United States and similar laws in other jurisdictions, regardless of whether you access any data or simply enumerate URLs.