Scatter Plots Are The First Tool You Should Reach For, Even When You Think You Already Know The Answer
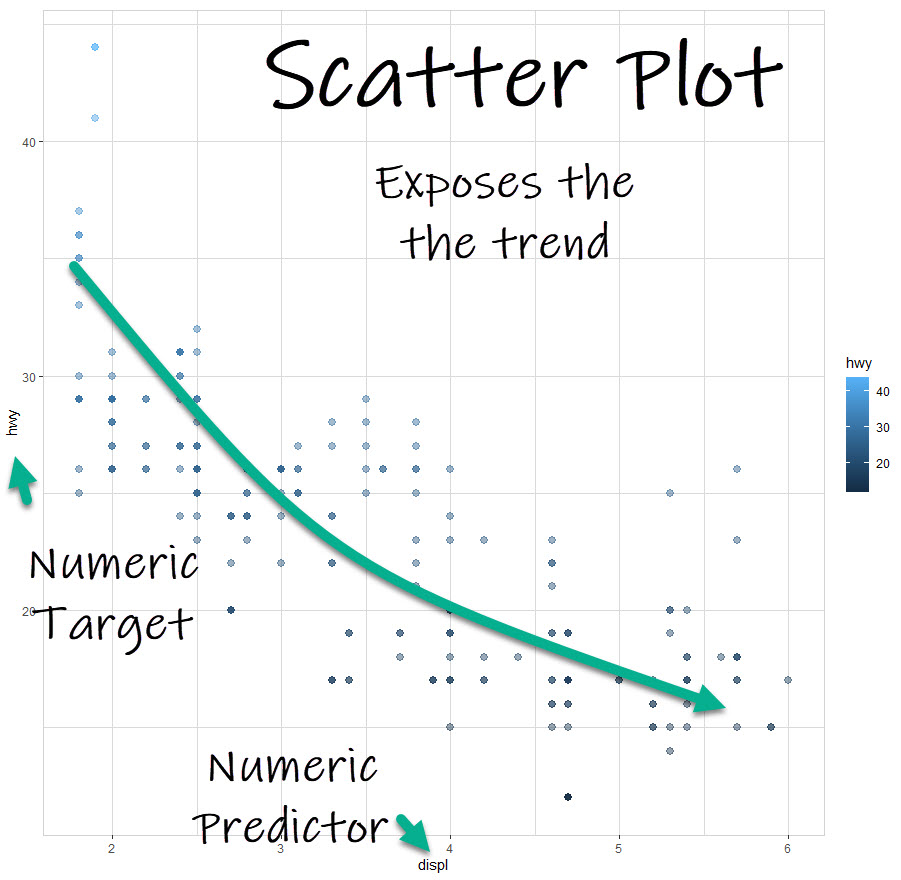
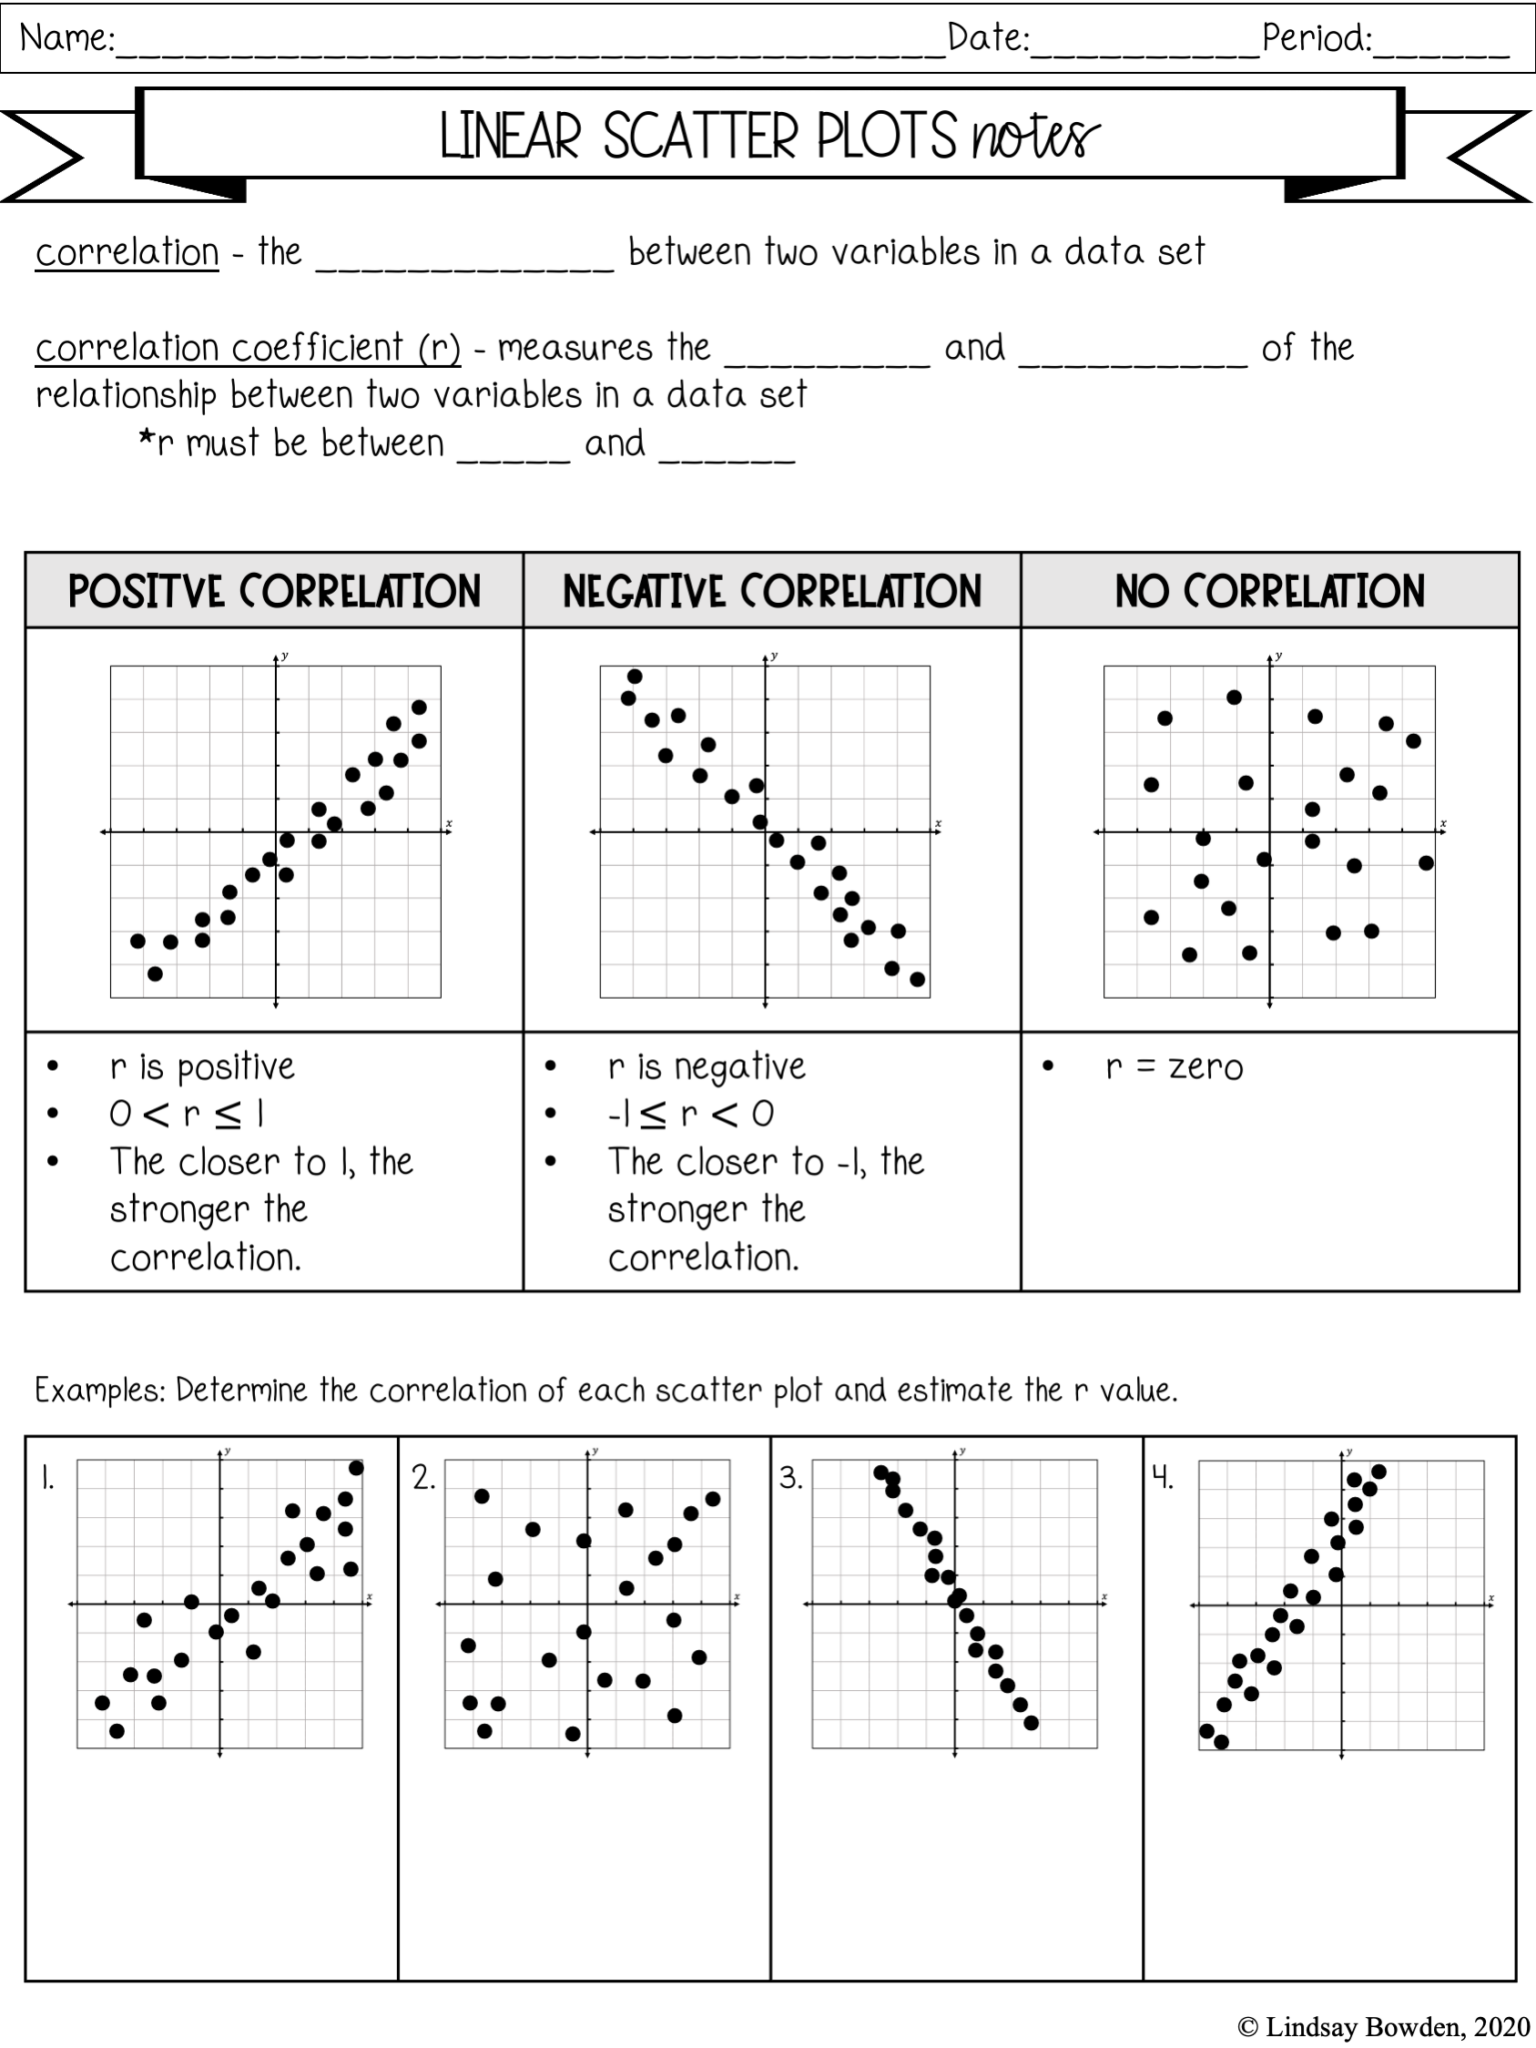
I spent about three years in a role where I was handed cleaned datasets and told to find relationships between variables that supposedly had none. Every. Single. Time. The first thing I did was plot them against each other. Nearly every significant finding came from those simple X/Y plots before I ever touched a regression model or a dashboard build. It sounds like advice you would have read a dozen times, but it is one of those things that only makes sense after you have been burned by trusting automated analysis too quickly. Scatter plots expose outliers, clusters, and non-linear relationships faster than any statistical summary you can generate in Excel or Python. A correlation coefficient of 0.15 looks meaningless until you see a tight cluster in the lower left and a separate curved band dragging the average down. The number tells you one story. The plot tells you the real one.
Uncovering Hidden Patterns The Power Of Scatter Plots And Data Analysis Answer Key In Unraveling Complex Data
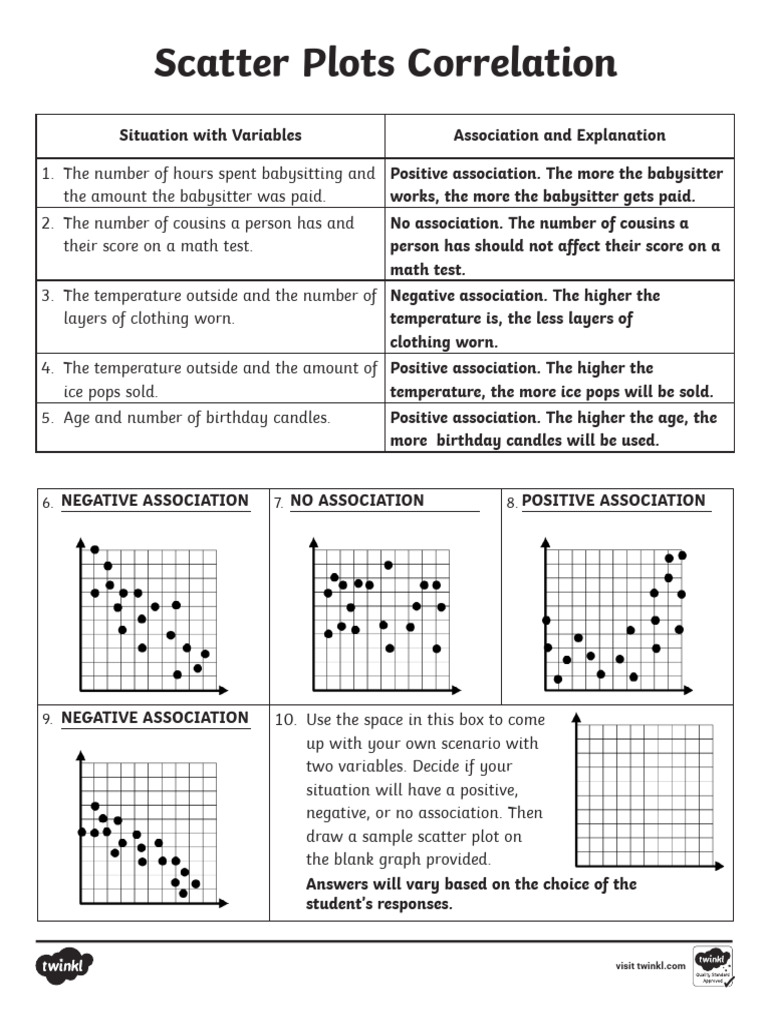
When people ask me about answer keys for scatter plot analysis, they usually mean they want a shortcut for interpreting what they are seeing. There is no real answer key. What works instead is a repeatable checklist you run through before you conclude anything. I keep it on a single sheet in my notes and use it every time, even when the dataset is straightforward. Here is how the process actually works in practice. You start with the raw scatter plot. No smoothing, no trend lines, no color coding yet. Just points on axes. You look at three things immediately: density, direction, and gaps. If the points are evenly spread with no visible pattern, then there likely is no simple linear relationship, and you move on. If you see a cloud sloping upward, you check whether the slope is consistent across the range or whether it bends. Bending means you need a transformation or a non-linear model. Gaps between clusters usually indicate subgroups that are being averaged together, which is one of the most common sources of false conclusions in business analytics.
After the initial visual pass, you add one trend line and look at the residuals. Residuals are the distances between each actual data point and the fitted line. If the residuals form a random cloud around zero, the linear model is probably adequate. If the residuals curve, you have missed something. I once spent two weeks debugging a model that kept showing poor predictive performance on new data. The scatter plot of actual versus predicted values had a distinct fan shape. Variance was increasing as the predicted value increased. Heteroscedasticity. The fix was not a better algorithm. It was weighting the observations and using a logarithmic transformation on the dependent variable. That alone corrected the predictive drift. The scatter plot showed it in about ten seconds. Color and size encodings come after you understand the base pattern. Adding a third dimension by mapping a category to color or a magnitude to point size helps you spot subgroup effects. But you should only do this after the simple black-and-white plot reveals what you need. Too many people jump straight to colored bubble charts and then cannot tell whether a pattern is real or just an artifact of overlapping translucent points. For the technical side, here is what I actually use. In R, ggplot2 handles most of the heavy lifting with geom_point for the base plot, geom_smooth for quick trend lines, and stat_density_2d when overplotting becomes a problem. Overplotting is a real issue when you have more than a few thousand points. Small datasets do not need it, but anything above that threshold will look like a solid blob unless you handle transparency or density contours. I use alpha blending sparingly. Setting alpha to about 0.3 or 0.4 usually works. Too low and the plot becomes a gray mess. Too high and you lose the ability to see density.
Get the Full Details

In Python, seaborn's regplot and lmplot are the go-to tools. They combine scatter and regression in one call, which is convenient but sometimes hides problems because the automatic confidence interval shading can make a weak relationship look stronger than it is. I prefer to separate the steps: plot the points first, then add the trend line, then check residuals separately. It takes two extra lines of code but it prevents misinterpretation. Excel still gets used everywhere, and it is fine for quick exploration if you know its limits. Custom chart types and dynamic color mapping are weak there. The trend line option adds a basic least-squares fit, but you have to calculate residuals manually if you want to do a proper diagnostic check. I usually export to R or Python once I suspect anything non-trivial is going on. One specific pitfall I want to mention because it costs people more time than almost anything else is the ecological fallacy. When you aggregate data before plotting, you can create patterns that disappear at the individual level. I saw this in a project involving regional health outcomes and income levels. The aggregated scatter plot showed a strong negative correlation. The individual-level plot showed almost no relationship. The aggregated pattern was driven by a few high-income regions with large populations skewing the results. Aggregation artifacts like this are invisible unless you plot both levels and compare them.
Another thing that catches people out is the range restriction problem. If your data only covers a narrow slice of the possible values, correlation estimates become unstable. A local segment of a curved relationship can look linear within that segment and lead you to apply a linear model incorrectly. I always plot the full range first and only then consider zooming in for detail. Zooming first is how people miss the bigger picture. When you are working with large datasets and need to summarize patterns quickly, binned scatter plots help. You divide one axis into intervals and plot the mean of the other axis within each bin. This reduces visual clutter and shows the functional form more clearly than raw points when you have tens of thousands of observations. It is a standard technique in economics and has practical value in business contexts too. If you are looking for downloadable resources, the most useful ones are not answer keys but reference sheets. I keep a printed checklist of common scatter plot patterns and their interpretations: linear positive, linear negative, curvilinear, clustered, funnel-shaped, uniformly scattered, and outlier-dominated. I also have a short script library for common transformations and residual checks. These are freely available from academic sources and open-source communities. The value is in having them ready, not in searching for them during a live analysis.
Scatter plots do not solve everything. They cannot replace proper experimental design or causal inference methods when that is what you need. They also struggle with high-dimensional data where relationships involve three or more variables simultaneously. For those cases, you need dimensionality reduction techniques like PCA or t-SNE before you can even begin to visualize meaningful structure. Scatter plots are a starting point, not a complete methodology. The practical takeaway is that building the habit of plotting before modeling saves more time than any tool you could download. A five-minute scatter plot can prevent hours of wrong-model speculation. That is the answer key most people never find because they skip straight to the statistical machinery.