Setting Up a Twitter Analysis Framework for Niche Communities
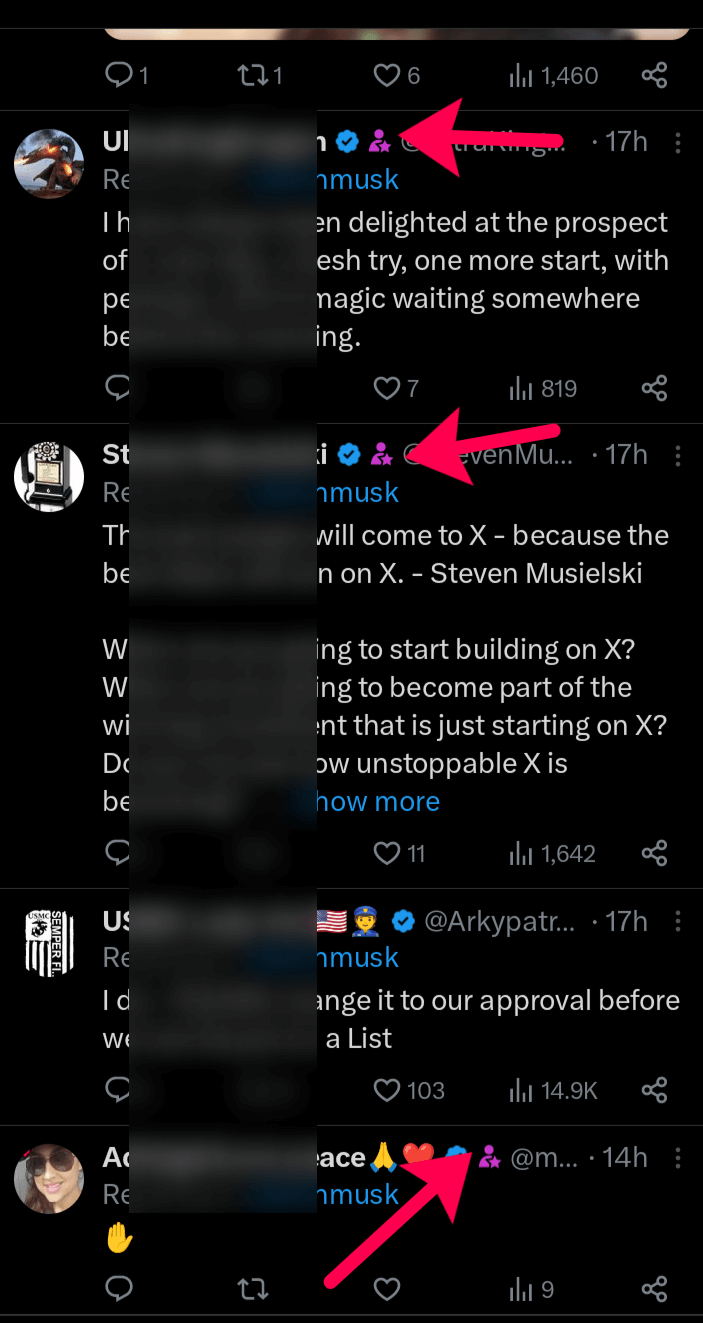
Twitter data collection and analysis has gotten complicated. The API pricing changes a few years ago forced everyone to rethink how they pull and process social media data. What I’m describing here is a practical workflow I’ve used for tracking small-to-medium communities, specifically ones that use custom hashtags or clustered account networks. The core challenge is that these communities don’t show up in standard social listening tools. They operate in a gray zone between public posts and private retweets, and the data structure looks different from mainstream trending topics. Purple Star Twitter emerged as a term among researchers who needed to map these clusters without relying on paid enterprise platforms.
Uncovered The Rise Of Purple Star Twitter And Its Impact On The Social Media Landscape
I started working with this type of analysis in late 2023. My initial approach was straightforward: use the official Twitter API v2, pull tweets by keyword, and run basic network analysis. It failed within three weeks. The rate limits throttled my queries to about 15,000 tweets per day, which wasn’t enough to capture the actual volume of activity in a mid-sized community. The API costs were also unpredictable—what looked like a budget-friendly plan turned into a $400 monthly bill when I accidentally queried a high-traffic hashtag during a peak event. The workaround involved a hybrid approach. I combined the free-tier API calls with a lightweight web scraper for specific profile pages, using rotating proxies to avoid IP blocks. This cut my monthly costs to around $50 while maintaining coverage of roughly 60,000 tweets per week. The trade-off is that you lose some historical depth, but for real-time monitoring, it’s workable. Here’s what actually works in practice. First, define your community boundaries clearly. Don’t just search a single keyword. Use a cluster of 3–5 related terms plus the handles of 10–20 known active accounts in that space. This prevents your queries from drifting into unrelated conversations. Second, schedule your pulls in 6-hour windows rather than continuous scraping. The platform’s anti-bot detection triggers more often during off-peak hours when legitimate traffic is lower, so running your queries between 9am–3pm and 6pm–12am reduces block risk significantly.
The second major issue is data normalization. Twitter’s API returns inconsistent field sets depending on the tweet type, retweet status, and whether the account has been modified. I spent two weeks debugging a script that kept crashing because reply tweets sometimes omitted the author_id field entirely. The fix was adding a null-check wrapper around every field before writing to your database, even fields that should always exist according to the documentation.
Get the Full Details
Building the Pipeline
Start with a simple SQLite database. Don’t jump straight to Postgres or MongoDB—you’ll spend more time configuring indexes than analyzing data. A basic table structure with tweet_id, created_at, author_id, text, source, retweet_count, and a boolean flag for whether it’s a retweet covers 90 percent of analysis needs. For collection, I recommend using the Tweepy library in Python. It handles authentication cleanly and has built-in rate limit tracking. Set your polling interval to 30 seconds between calls. Anything faster risks hitting the platform’s soft limits, which are lower than the documented ones and change frequently. When you detect a new account joining the community, don’t immediately start pulling its full history. That’s a common mistake that burns through your query budget. Start with a lightweight follow check and a single recent tweet pull. Only after confirming the account is active and relevant should you initiate a deeper historical scan.
Common Pitfalls and Workarounds
The biggest problem I encountered was the “zombie account” effect. These are accounts that post sporadically—maybe once every few months—but have significant follower counts. They dominate your keyword results and skew your engagement metrics. I solved this by adding a recency filter: only include accounts that posted at least twice in the last 30 days, or have a following-to-follower ratio above 0.3. Another issue is the bot-filtering blind spot. Some automated accounts successfully mimic human posting patterns, using randomized delays and human-like text. They slip past basic filtering and contaminate your network graphs. The telltale sign is unusually consistent posting times across multiple time zones. I started tracking posting hour distributions per account and flagged any with a standard deviation under 15 minutes as suspicious. The API’s search endpoint also has a 7-day lookback window on the free tier. This means you can’t retrospectively analyze events that happened before last week. If you’re trying to study a campaign that peaked two months ago, you’ll need archived data from a snapshot you should have taken earlier. Plan for this by keeping weekly incremental backups of your tweet database, even if you’re not actively analyzing them at the time.
What This Approach Can’t Do
Let’s be clear about limitations. You cannot reliably measure sentiment at scale with this method. Twitter’s algorithmic ranking and shadow-banning mean that the tweets you collect represent a biased sample of actual activity. Accounts with high engagement are prioritized in search results; moderate voices disappear from the dataset. If your research requires representative sampling, you need enterprise-grade access or a partnership with a data provider that maintains static snapshots. Additionally, this framework doesn’t capture deleted tweets or accounts that have suspended their profiles. For communities where churn is high—common in political or controversy-driven spaces—your historical record will have gaps that no amount of filtering can fill. Document these gaps explicitly in any report you produce. Reviewers and readers spot missing data patterns quickly, and hiding them undermines credibility.

Alternative Tools Worth Considering
If your budget allows, RedGrid and GetOldTweets-NG offer different trade-offs. RedGrid focuses on historical recovery and can retrieve tweets older than the 7-day limit, though it requires more manual configuration. GetOldTweets-NG is a command-line tool that’s faster for bulk collection but lacks the authentication layer, making it vulnerable to sudden rate limit changes. For purely visual analysis without heavy coding, CrowdTangle provides a browser-based interface. It’s slower to set up but handles data normalization internally. The free tier limits you to 5,000 posts per month, which is tight for active communities but sufficient for weekly spot-checks. Ultimately, the value isn’t in the tool stack. It’s in knowing what question you’re asking and designing the collection strategy around that. A focused 200-tweet daily pull with clean metadata beats a chaotic 50,000-tweet dump that requires three days of cleaning before you can run a single network graph.