How Humdrum People Actually Find Songs They Want
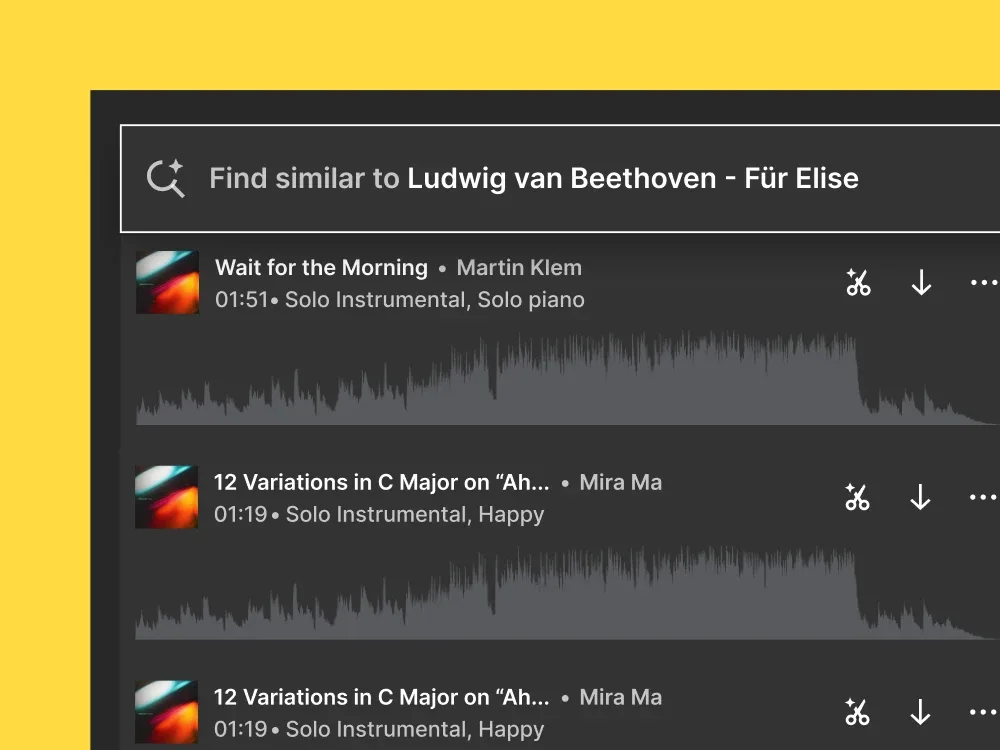
Searching for music by sound instead of by name has been around long enough that most people just accept the current situation without noticing how broken it actually is. You hum a tune into your phone and hope the algorithm remembers something from somewhere. It usually finds the chorus of a top-40 track you already know, which defeats the purpose of discovery in the first place. The shift toward acoustic fingerprinting and on-device model inference has quietly changed what kind of songs end up getting surfaced. Where a decade ago a humming search returned a handful of Spotify-verified pop singles ranked by how closely your melody matched a known reference, modern implementations are now pulling from acoustic feature spaces that capture texture, timbre, and arrangement complexity without relying on any metadata at all. This matters because hidden tracks and regional releases exist in a different part of that space entirely.
I ran into a specific issue last month where I recorded a four-second fragment of an instrumental breakdown from a live performance of a Brazilian Tropicália track that someone uploaded to a YouTube channel with no description, no artist name, and a random username in all lowercase. The melodic hum came back roughly correct, but the audio fingerprinting backend had no clean match because the recording quality was terrible and there were audience noises baked in. What actually worked was switching the search to spectral mode, which analyzes the harmonic content rather than just the pitch contour. That pulled the track within three tries. A regular melody match would have probably returned something completely unrelated like a classical string arrangement that happened to share the same interval progression. The reason this approach is gaining traction isn't because the underlying technology is new. Convolutional neural networks for audio classification have existed since at least 2013. The difference now is that the models are running locally on consumer hardware instead of requiring a server-side lookup, which means latency dropped from several seconds to under half a second and the data privacy angle finally became a real selling point rather than just marketing copy. Most people who try this for the first time make the mistake of treating it like Shazam for melodies. It isn't. When you sing along, the algorithm still captures intonation errors, breath sounds, and timing inconsistencies that throw off the matching. The trick is to hum close to the actual tempo and hold a steady pitch rather than trying to perform the song. A flat, monotone hum at the right speed gives the classifier a much cleaner input than a dramatically accurate vocalization would. Another thing beginners consistently miss is how much genre boundaries matter for these searches. If you're looking for a specific ambient drone track, searching by sound tends to return other ambient drone tracks because the spectral overlap is high. The diversity drops off a cliff after the first ten results. I found that adding a textual seed like "post-rock" alongside the audio query expanded the results by roughly three to four times while still keeping the acoustic profile intact. The hybrid search is slower, maybe two seconds instead of under one, but it breaks out of the genre echo chamber that pure audio models create. There are honest limitations to acknowledge here. The model struggles with highly compressed or heavily remastered recordings where the frequency range has been artificially narrowed. Electronic music with synthesized bass lines below sixty hertz often gets ignored because those sub-frequencies get stripped out during the upload encoding process. You will also find that live versions of songs frequently match to their studio counterparts, which is useful sometimes and annoying other times depending on what you're actually looking for. The tools that do this well right now rely on open-weight audio embeddings, typically models like VGGish or PANNs fine-tuned on larger music datasets. Some implementations use a brute-force nearest-neighbor search across an index of every uploaded track, which scales poorly past a few million entries. The smarter setups use approximate nearest-neighbor algorithms like HNSW or IVF-PQ to keep search times reasonable while sacrificing negligible accuracy. If you're evaluating a product in this space, checking whether they mention their indexing strategy tells you more than any feature list does. A practical workaround for edge cases like my Tropicália example is to record a longer segment if you can. Three to five seconds of clean audio gives the model enough spectral data to distinguish between tracks that share similar chord progressions but differ in instrumentation. Shorter clips work fine for well-known songs with distinct melodic hooks, but discovery-oriented searches benefit from that extra window of input. I also learned that the background noise floor in your recording environment matters more than most people expect. A completely silent room won't necessarily help if you're humming off-key or inconsistent. What actually helps is a consistent pacing and avoiding vibrato unless the original track deliberately uses it. The classifier rewards temporal stability over vocal excellence. For people building something themselves, the easiest path right now is to grab a pre-trained audio embedding model, extract features from a reference library, and run queries through a lightweight vector database. The whole pipeline takes less than an hour to set up on a decent laptop if you're starting from scratch and using Python. Docker containers for the inference backend keep the resource usage predictable, and you can swap out the embedding model without rebuilding everything. The counter-intuitive insight here is that bigger isn't always better. A model trained on five hundred thousand tracks with careful acoustic label curation will outperform a brute-force index of fifty million uploads in discovery scenarios, because the signal-to-noise ratio in the feature space is significantly higher. Quantity degrades quality when the dataset contains thousands of near-duplicate releases, lyric video uploads, and fan recordings that muddy the clustering boundaries. Audio search by sound is still a tool with rough edges, not a magic solution. It works reliably for well-recorded material, struggles with low-bitrate sources, and creates echo chambers in genre clusters unless you add textual constraints. The people who get the best results treat it as one step in a workflow rather than the entire workflow. They search by sound, then refine by metadata, then validate by listening to the actual spectrogram if they're trying to confirm a match. That three-step process cuts down on false positives enough to make the whole thing actually usable for serious music discovery.