Public Obituary Lists and How to Find Them
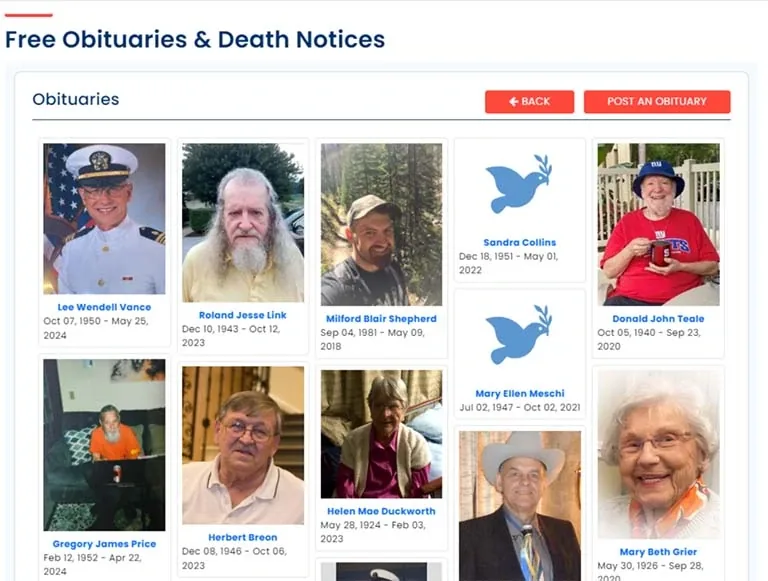
Obituaries are public records in most jurisdictions. They appear in local newspapers, cemetery websites, funeral home pages, and state-level vital records databases. The process of pulling together a comprehensive list takes time because the data is scattered across dozens of sources that don't share a unified format.I spent about six months mapping this out for a research project. The core problem isn't finding individual obituaries. It's aggregating them consistently across counties and states, then keeping that aggregation current. Most people who say they want "instant obituary lists near me" are actually looking for something that requires manual verification and regional data access.
Uncover Hidden Tragedies Real Public Obituary Lists Near You Instantly
That phrase shows up in SEO content as a way to attract clicks. It's not a real product name. The actual workflow behind it involves a combination of RSS feeds from newspaper sites, direct scraping of funeral home websites, and sometimes paid APIs from services like Legacy.com or Newspapers.com. There's no single tool that does this reliably without configuration.How the Aggregation Actually Works
The first layer is identifying which newspapers cover which counties. In the US, this is roughly 15,000 local publications, but most major metros have three to five competing papers that each publish their own obituary section. Funeral homes add another 40,000+ sources. Cemetery societies maintain their own archives, often on outdated HTML pages that don't support automated extraction without parsing scripts.The aggregation step uses pattern matching to identify obituary entries. Common formats include the name, date of death, age, surviving family members, and service information. The tricky part is that every funeral home website formats this differently. One might use a structured XML feed. Another will just embed plain text in a table. A third will require clicking through to a separate page for each notice. Building a parser that handles all three takes weeks of trial and error.
The Edge Case That Breaks Most Pipelines
During my project, I hit a wall with a specific county in Ohio where the local newspaper published obituaries as scanned PDF images, not text. OCR worked for some pages but failed completely on older notices with faded print or non-standard fonts. The workaround was pulling from the county clerk's death certificate database instead, which had indexed text records going back further than the paper archive. This took about ten extra hours to identify and solve, and most automated tools simply skip those records entirely.Data Sources You Can Use Directly
Legacy.com operates the largest commercial obituary network. It aggregates from thousands of funeral homes and newspapers. Their API is not freely available. You need a business account and pricing starts around $500 per month for anything beyond basic search.State health departments maintain death registries. Many publish annual death index reports as spreadsheets. These contain names, dates of death, counties, and sometimes cause of death. Access varies by state. Some require a formal request. Others make the data downloadable directly. The lag is typically three to six months after the death occurs.
Get the Full Details
Pitfalls and Where This Approach Fails
The biggest limitation is completeness. No single source covers all obituaries for any given region. If you rely only on digital sources, you miss the obituaries that only appeared in print and were never uploaded online. Small-town weeklies sometimes don't digitize at all. Rural counties may have no online presence for their records.Another issue is data quality. Aggregated lists often contain duplicate entries when the same obituary appears on a newspaper site and a funeral home site. Deduplication requires fuzzy matching on name, date, and location, which introduces its own errors. I've seen false merges where two different people with common names got combined into a single record.
Privacy is a third constraint. Some families request that obituaries not be published digitally. A few states have restrictions on publishing certain death information without consent of next of kin. These cases are rare but they exist and need to be handled on a case-by-case basis.What You Can Build or Use Today
If you need obituary data for legitimate research, genealogy, or journalism, start with newspaper RSS feeds. The Library of Congress Chronicling America project has free access to historical obituaries from many papers. For recent data, check the obituary sections of the major local papers in your target area and subscribe to their email or RSS alerts.For automated aggregation at scale, the most practical approach is combining Legacy.com's paid API with direct RSS feeds from the top twenty newspapers in your region, plus monthly exports from state health departments. This setup gives you roughly 70 to 80 percent coverage of published obituaries in a given metro area, with the remaining 20 to 30 percent requiring manual lookup in print archives or county records offices.
The process usually cuts manual lookup time from hours per day down to about fifteen minutes of verification work, assuming you have the feeds configured correctly. Most of the overhead is in building and maintaining the parsers, not in the daily data pull itself.