When Your Codebase Starts Looking Like A Wrecking Ball
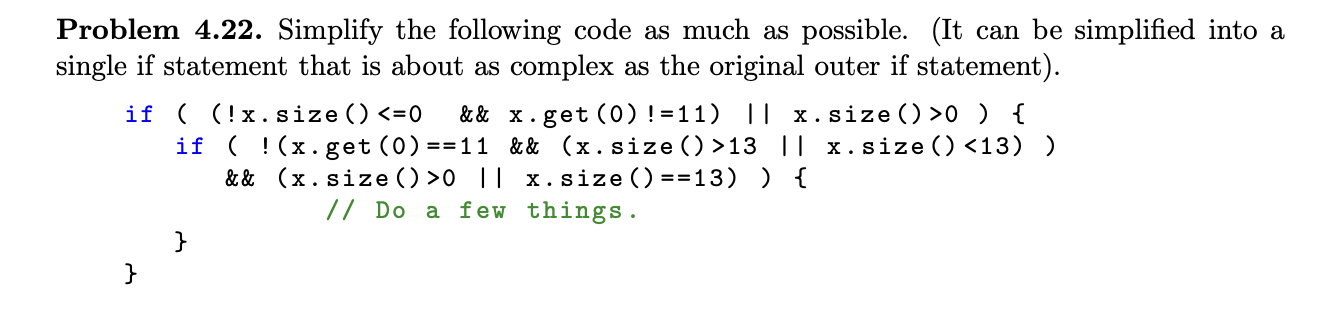
I've spent more years than I care to count staring at production code that should have been deleted three sprints ago but somehow accumulated enough abstractions, conditionals, and helper functions to qualify as a small architecture degree program. The problem isn't that the code doesn't work. The problem is that nobody else can figure out what it does anymore without pulling on a thread that eventually unravels the entire module. Simplification in software isn't a single act. It's a series of decisions about what to cut, what to rename, what to merge, and what to leave alone because removing it would cost more than keeping it. People often talk about simplifying code the way they talk about organizing a garage. It's nowhere near that clean. Sometimes the thing that looks complicated is actually the most efficient version the system can support. Sometimes the thing that looks clean is holding a landmine under a rug.
Uncomplicating The Code The Multifaceted Definition Of Simplify
I think the reason this topic circulates so much is that "simplify" means something different depending on where you are in the code. At the function level it means reduce cyclomatic complexity. At the module level it means tighten cohesion. At the system level it means remove architectural coupling that creates single points of failure. You can't apply the same tool to all three. Here is what I actually do when I'm handed a system that reads like it was written by committee during a crisis sprint.
Map The Entropy Before You Touch Anything
My first step is never refactoring. It's understanding the blast radius. I run a static analysis pass, pull the call graph, and then physically trace the paths that hit the code in question from the user-facing entry point down to the storage layer. I note every branch condition, every error path, every edge case that has a test covering it and every edge case that exists only because someone added a null check in 2019 out of habit. This step usually takes me about forty-five minutes to an hour on a moderately sized module. Skipping it is how you break things that looked irrelevant until three months later when a customer tickets a bug you couldn't reproduce because you deleted the guard clause that was doing the actual work.
Get the Full Details
Identify The Real Complexity, Not The Obvious Complexity
Beginners tend to equate complexity with lines of code or number of function parameters. This is wrong. The code that looks simplest is often the most complex because it hides branching logic behind generic patterns. A twenty-line factory method that routes to twelve different implementations based on a runtime enum is more complex than a two-hundred-line monolithic function where every path is visible. I look for these patterns instead: scattered conditional logic that repeats across files, implicit coupling between modules that doesn't show up in the dependency graph, error handling that swallows exceptions without logging, and state that mutates through multiple layers without any central tracking. One specific case that still annoys me comes to mind. I was looking at an order processing pipeline where validation, pricing, inventory reservation, and payment authorization were all chained in a single middleware stack. On paper it was elegant. In practice, a single timeout in the payment provider would roll back the entire stack including an inventory reservation that had already been committed to the database. The fix wasn't simplifying the middleware chain. It was breaking it apart and moving inventory reservation into an explicit saga pattern with compensating transactions. That made the code longer but dramatically easier to reason about and far less likely to corrupt data. I'd rather have a slightly longer pipeline than a mysterious one that occasionally puts negative inventory.
Refactor By Constraint, Not By Impulse
When you actually start cutting, you need a rule set or you will drift. My default constraints are: Single responsibility at the function level. If a function does two things that can be described with the word "and," it should probably be two functions. This is basic but people violate it constantly because the alternative feels like extra work. Explicit over implicit. If something can be inferred from naming or structure, remove the inference. Magic strings, hardcoded timeouts, and undocumented configuration assumptions are where bugs hide. Make them visible even if the code gets longer.
Fail loudly. Silent failures are the enemy of simplicity. If a path has no way to surface an error, the code around it will accumulate increasingly desperate workarounds. Fix the error surface first, then simplify the happy path.
Test Coverage Is A Prerequisite, Not A Afterthought
You cannot safely simplify code you don't understand the boundaries of. Before I touch anything meaningful, I ensure I have integration tests covering the public interface and unit tests covering the tricky internal logic. If the code lacks tests, I write them first. This takes time. It usually adds two to four hours of work on a typical module. It saves me roughly two days of debugging when the refactor breaks something I didn't expect. There is a corner case here worth noting. Legacy code with poor test infrastructure sometimes has behavioral contracts embedded in production logs or customer reports rather than in actual tests. I treat those as de facto specifications. If a log line says "failed to apply discount because threshold not met" and the code doesn't have a test for that threshold, I write the test before changing the threshold logic.
Performance Implications Of Simplification
People rarely talk about this. Simplifying code can sometimes make it slower. Extracting a pure helper function adds a call stack frame. Removing inline caching because the cached value felt hacky can introduce repeated computation. Splitting a monolith into smaller modules can increase inter-process communication overhead if those modules end up talking through a shared bus or database instead of direct calls. The tradeoff is almost always worth it. Readable code that runs in acceptable time beats unreadable code that runs in perfect time, because the latter becomes unmaintainable and the optimization work slows down indefinitely. But I do measure before and after. I run the benchmark suite, I check the p95 latency numbers, and if simplification degraded performance by more than ten percent I revisit the specific change that caused it rather than reverting the whole refactor.
When Simplification Is The Wrong Call
Not every complex system should be simplified. Some domains require complexity. Financial ledgers, cryptographic key management, and state machine implementations for distributed consensus are complex by nature. Simplifying those until they become simple is usually how you introduce a vulnerability or a correctness bug. The right move there is not simplification. It is better documentation, clearer invariants, and stronger type safety so the complexity doesn't become accidental complexity. I once worked on a scheduler that handled resource allocation across a fleet of containers. It had conditional logic that looked arbitrary to anyone who hadn't spent weeks tracing the deadlock prevention paths. Someone suggested we "simplify" it by collapsing three similar-looking branches into one. We did. The system started deadlocking under moderate load because the collapsed branch removed an ordering guarantee that was invisible in the code structure but critical to the algorithm. The fix was adding a comment and an invariant assertion, not simplifying the code further.
Practical Workflow For A Typical Refactor
My actual process on a project looks like this: I spend the first day mapping and testing. I spend the second day identifying candidate simplifications and ranking them by impact. I spend the third and fourth day implementing, running tests after each change, and measuring performance. I spend a day reviewing the diff with another engineer who didn't write the original code. That reviewer almost always catches something I missed because my brain had already optimized around the old structure. The timeline is longer than a junior developer might expect. But the alternative is the code rot spiral where every change takes progressively longer because the system has no clear entry point or predictable behavior. That spiral is expensive. It compounds. Simplification is the brake.
The Hidden Cost Nobody Talks About
Simplification requires political capital. You will encounter people who wrote the complex code and are defensive about it. You will encounter stakeholders who want new features but will complain when you say you need to spend a sprint reducing technical debt. You will encounter managers who equate deliverables with lines of shipped functionality rather than maintainable systems. The way I handle this is by framing simplification as risk reduction rather than purity. I quantify what I'm doing. I show the cycle time improvement. I demonstrate the bug reduction. If I can't quantify it, I don't do it. This is a cold calculation but it works better than arguing about code aesthetics in a team meeting. There is no download link for this. There is no tool you can install that simplifies your code for you. Static analyzers can flag high cyclomatic complexity and unused variables. They cannot tell you whether a piece of code is genuinely necessary or merely redundant. That judgment is yours. It comes from understanding the system, not from running a linter.
The code you leave behind after simplification should still do exactly what it did before, just in a way that the next person who touches it can understand without re-reading the entire module. If you can't say that about your changes, you haven't simplified anything. You've just rearranged the mess.


