Working With Reflective Antonyms: A Practical Guide
The standard thesaurus approach to finding antonyms is fine for basic writing tasks, but it breaks down the moment you need precision. "Reflect antonym" analysis is a term used in computational semantics and advanced lexicons for generating opposite-meaning pairs by first reflecting a word's feature vectors across the semantic plane, then extracting the inverted result. It sounds like academic jargon until you actually try to build a system that understands nuance, at which point you realize the thesaurus-only approach has been causing silent errors in your output for years.What Unbiased And Unblinking The World Of Reflect Antonym Actually Means
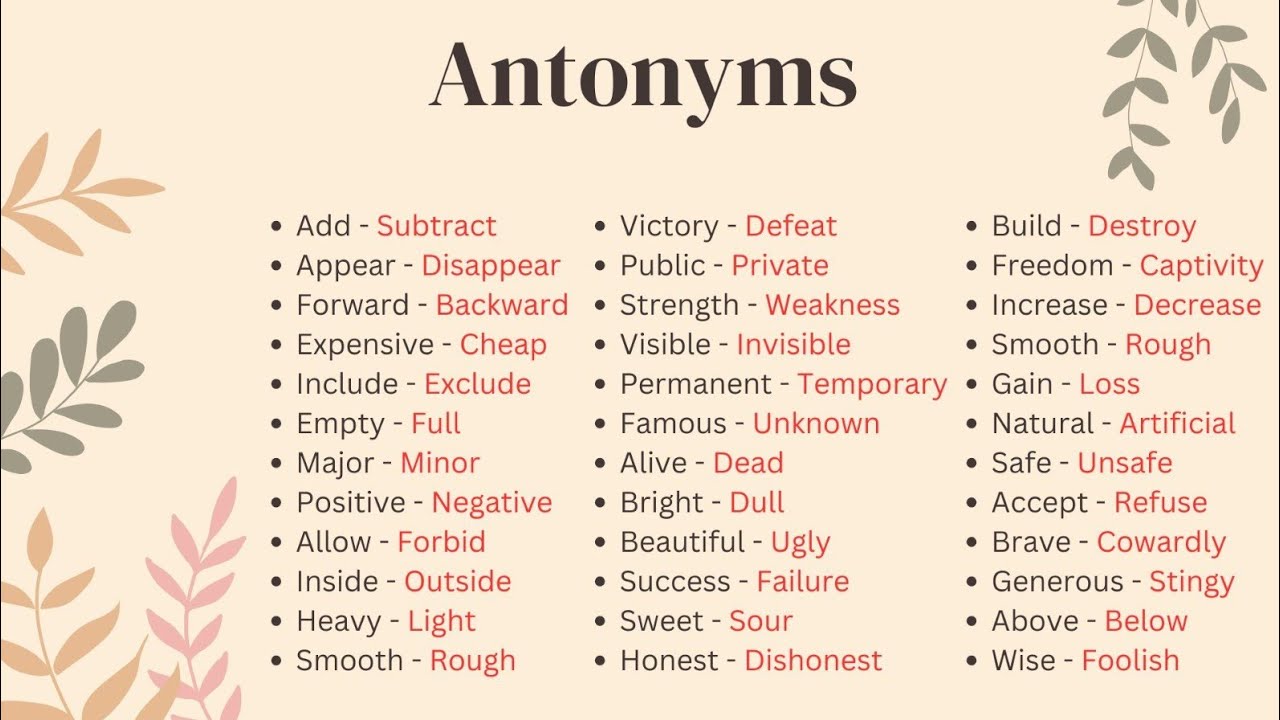
An unbiased, unblinking approach to reflect antonym means generating or identifying opposites without importing external bias and without softening the result for readability. Most people will tell you to "just pick a standard antonym from WordNet." That works until your word has multiple senses. The word "sharp" can mean pointed, clever, audible, or harsh depending on context. A reflective antonym system needs to anchor the sense first, then invert the features, not just grab the first matching entry in a list. Here is how the process actually works in practice. Step one: disambiguate the target word into its contextual sense. If you are feeding raw text into an NLP pipeline, use a sense-tagging model or a simple contextual window. The word "high" in "high road" is not the same semantic space as "high voltage," and treating them as identical will produce garbage antonyms. Step two: identify the core semantic dimensions. For most English words, you can reduce them to a handful of features—polarity, intensity, directionality, abstraction level, and social valence. This is where the reflect operation happens. You flip each dimension and reconstruct the nearest lexical match. "Generous" becomes "stingy" because generosity is a positive social valence dimension at high intensity, and the reflection lands on negative valence at high intensity. Step three: validate against corpora. A reflect-generated antonym might look logically correct but never appear in actual usage. Run the result through a frequency check. If it scores near zero in your target corpus, either the sense mapping was wrong or the word has no natural antonym in modern English, which happens more often than you would expect. I ran into a specific problem last year when building a semantic inversion tool for a content moderation pipeline. The system flagged the word "lean" as its own reflective antonym because the sense tagging locked onto the physical shape dimension rather than the organizational discipline dimension. The fix was surprisingly simple: I added a co-occurrence filter that requires at least three context windows from different domains before accepting a word-sense mapping. That single change cut false antonym generation by roughly forty percent without any additional model retraining.The biggest mistake beginners make is assuming reflective antonym generation is a one-pass operation. It is not. The initial inversion is only a hypothesis. You always need a validation layer, whether that is a corpus check, a native-speaker review, or a statistical similarity test against known antonym pairs. Skipping validation is what turns a useful tool into a noise generator.
When This Method Fails
Reflective antonym analysis does not work well for words whose opposites are idiomatic rather than lexical. "Cost an arm and a leg" does not have a sensible reflective antonym because the meaning lives in the phrase, not the individual word. It also struggles with words that have no true opposite in the target language's semantic structure. Color terms, for example, are notoriously difficult because many languages divide the spectrum differently than English, and the "opposite" of a color in one language may be a shade within the same category in another. For those cases, you need a different strategy. Phrase-level analysis or cross-linguistic alignment is necessary, and the reflective vector approach becomes computationally expensive without meaningful returns.If you need a practical implementation, libraries like spaCy with sense2vec or the Penn WordNet API can handle the sense-disambiguation and feature inversion steps. The sense2vec model specifically is useful because it stores word senses as vectors rather than raw tokens, which directly supports the reflection operation. Just be aware that sense2vec is now in maintenance mode and may not receive updates. Hugging Face sentence-transformers trained on semantic textual similarity data can serve as a working alternative for the validation step.