Filler Words Aren't Noise — They're Data
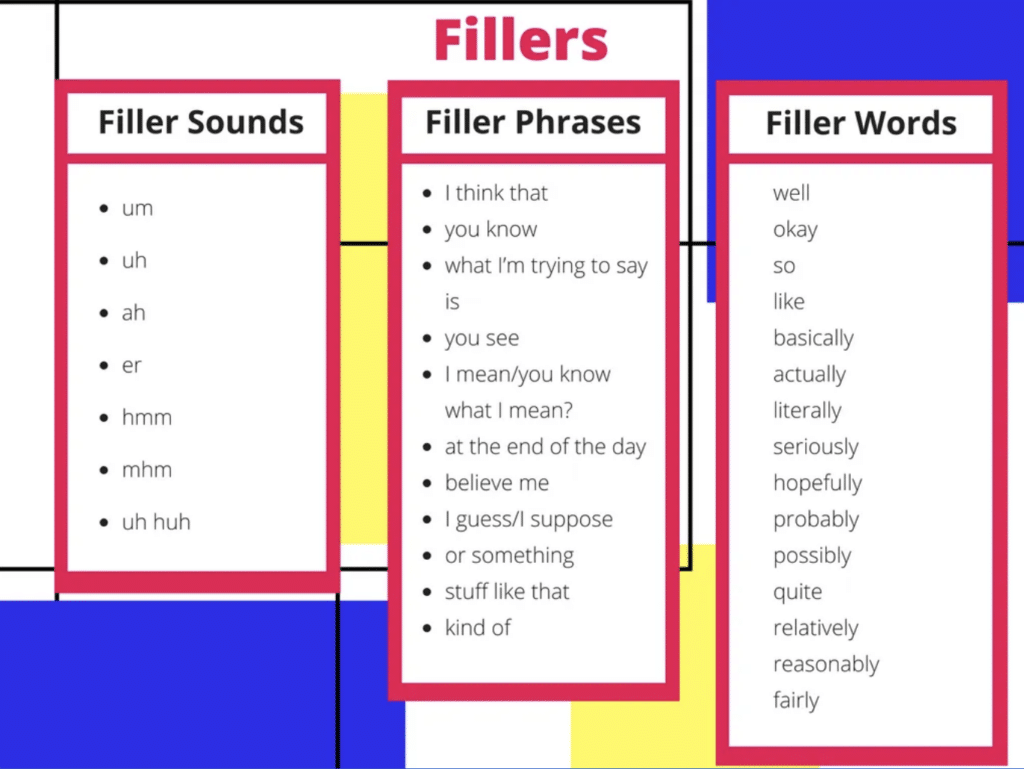
I spent about three years transcribing casual speech for a sociolinguistics project, mostly from coffee shops and family gatherings. At some point I stopped seeing "um" and "uh" as mistakes and started noticing patterns. The thing that surprised me wasn't that people use filler words — it's how predictably they use them, and what the timing reveals about cognitive load. For decades, filler words like "um," "uh," "like," and "you know" were treated as speech disfluencies — the verbal equivalent of static on a radio line. You filtered them out. In linguistic work, we were taught to ignore them because they didn't carry semantic content. That assumption started cracking in the late 2000s, and has been getting louder since. The shift isn't that linguists suddenly discovered people say filler words. It's that we learned to treat them as structurally significant rather than accidental. Here's what I actually saw in my transcripts. Speakers don't use "um" randomly. The distribution is tightly coupled to syntactic planning complexity. When someone's about to produce a coordinate structure — "I went to the store and then..." — "um" tends to appear before the conjunction, not after. When they're switching topics or embedding a relative clause, the pause lengthens and the frequency of filler increases. This isn't vague intuition. Multiple labs have measured it with millisecond precision, and the effect sizes are substantial enough that you can predict structural boundaries in real time.
The counter-intuitive part is that more fluent speakers often use more fillers, not fewer. People who process language under high cognitive load — non-native speakers, people with certain aphasias, even highly articulate speakers tackling unfamiliar topics — tend to reduce filler use and replace it with longer silent pauses. The silence feels more awkward to listeners, but the data shows that fillers actually serve a facilitative function. They hold the floor. They signal "I'm still producing." They prevent conversational overlap in a way that pure silence doesn't. I remember a specific edge case that broke my assumptions. I was analyzing a participant who used almost no fillers during a narrative task. On the surface, this looked like high fluency. But when I compared pause durations and turn-taking patterns, the picture was different. The participant was producing unusually long silent pauses between clauses — pauses that consistently exceeded 800 milliseconds. Native speakers in the same dataset used "um" in those positions and kept pauses under 400 milliseconds. The non-filler strategy wasn't more fluent; it was cognitively more expensive and produced a very different interactional rhythm. Listeners rated that speaker as "hesitant" even though they technically had fewer disfluencies. That's the kind of thing that makes you reconsider what you're actually measuring. There's also the register dimension that beginners miss. "Like" functions differently depending on whether you're analyzing teenager peer conversation or academic panel discussion. In casual speech, "like" can mark quoted speech or approximate similarity. In formal contexts, speakers suppress it almost entirely. But even suppression is informative. A speaker who normally uses "like" eight times per minute and then drops to zero during a particular topic — that's a data point about pragmatic awareness and audience design, not just a style choice.
The tools for studying this have gotten dramatically cheaper and faster. What used to require a dedicated lab and months of transcription can now be done with open-source pipelines like ELAN combined with forced alignment tools. I've run basic filler detection on an hour of casual speech in about 45 minutes using automated whisper-based alignment, and the results are accurate enough for pattern discovery even if they're not perfect at the phoneme level. For anyone getting into this, start simple. Transcribe ten minutes of natural speech. Count every "um" and "uh" with their timestamp. Plot them against clause boundaries. You'll see the structure without needing fancy software. The limitations are worth stating plainly. Filler analysis is not a diagnostic tool for speech pathology in isolation. Dysfluency patterns overlap across conditions — developmental language disorder, aphasia, autism, anxiety — and the same surface behavior can have different underlying mechanisms. A clinician looking at filler frequency without context will misdiagnose. The research literature is also uneven. Some corpora are heavily skewed toward educated, middle-class, native-speaker norms. Cross-dialect and cross-language work is growing but still fragmented. If you're comparing filler rates across groups, you need to control for speech rate, topic familiarity, and interlocutor relationship, or the results will confound social variables with cognitive ones. Another bottleneck is the transcription itself. Forced alignment is fast but error-prone on filled pauses because the acoustic realization of "um" varies widely across speakers and contexts. I've seen alignments that split a single "um" into two tokens or merge adjacent disfluencies into one. Manual verification of the first few thousand entries is usually necessary before you trust the automated counts. It's not a full-day job, but it's not invisible either.
Get the Full Details

If you're interested in the core research, the works by Schiffrin, Herring, and more recently Byrd and Taylor have shaped this field significantly. The journal Discourse Processes and Language in Society publish the most relevant empirical work. For practical tools, the CHAT format for transcription combined with CLAN analysis commands remains the standard in many labs, though Python-based pipelines using Praat scripts are gaining ground. The bottom line is that filler words are not debris in spoken language. They're timed, structured, and functionally motivated. The linguists who are "listening up" are the ones who stopped treating them as errors and started treating them as evidence.