Setting Up Gradescope for Automated Grading at UIUC
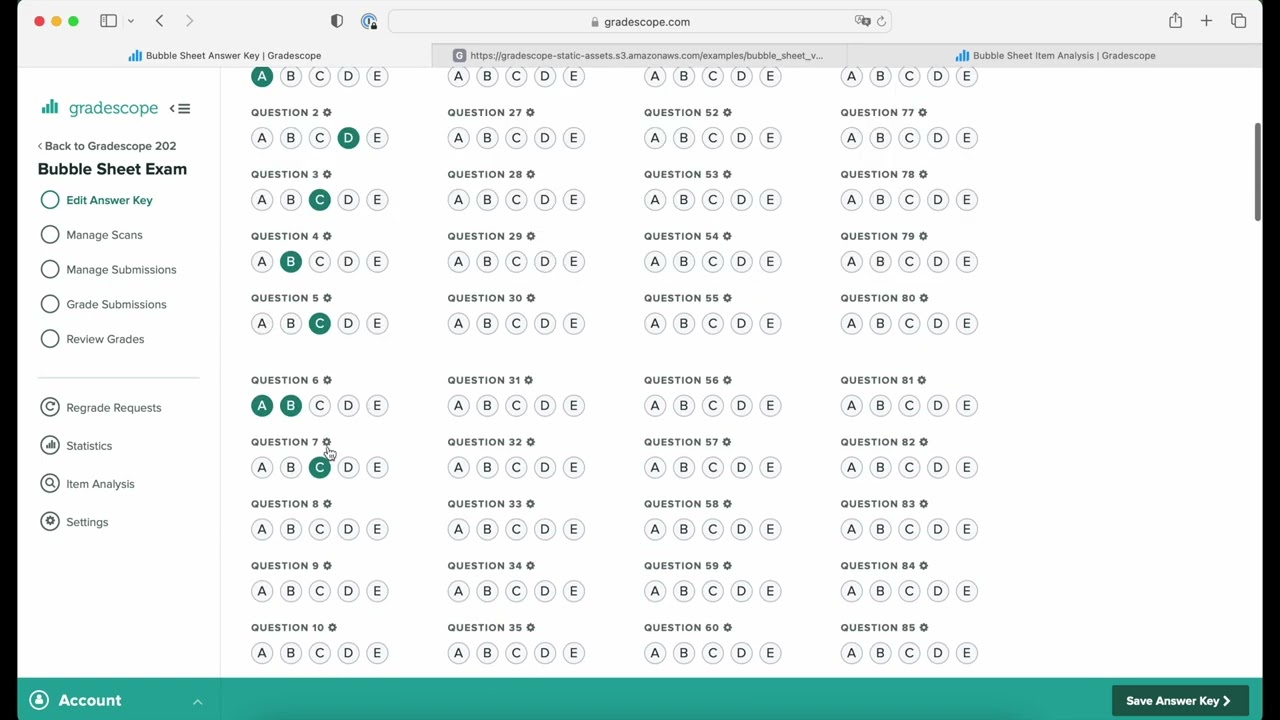
I spent way too many semesters manually grading introductory Python assignments before I figured out how to make Gradescope actually do the work for me. The official documentation assumes you already know half the things you need to figure out yourself. Here is what I learned the hard way. Gradescope is a platform UIUC adopted across multiple colleges, but "adopted" doesn't mean it works out of the box for any particular course. The automation piece is where most TAs hit a wall. You upload a PDF of handwritten exams, run an autograder against Python submissions, and expect the system to match everything up correctly. That last part is where it falls apart if you haven't configured the right settings. The first thing you need is a properly structured repository. I used to throw random script files into the repo root and wonder why Gradescope couldn't find them. Put everything under a submissions/ directory, keep your autograder entry point clean, and version the config separately from the code. This matters more than people admit because when you have 300 students submitting and one student's file path has a space in it, Gradescope will silently fail without telling you why.
Practical autograder structure: Most courses I've seen use a pattern like this. The main autograder file lives at the root, usually named autograder.py or run_tests.py. It imports test modules from a tests/ subdirectory. Each test module uses pytest or unittest and asserts on output, return values, or file contents. Gradescope executes this against each submission and maps the test results back to the student. The critical setting you need to toggle is the "Allowed Files" configuration under Course Settings > Submissions. If you don't restrict this, students can include external libraries or helper scripts that your autograder wasn't designed to handle. I once had a whole section of students submit solutions that imported numpy when the assignment explicitly said no external libraries. Their code passed locally because they had numpy installed, but Gradescope's environment didn't. I caught it because I ran a parallel grading pass with stricter file restrictions before releasing scores.
The Hidden Complexity of Multi-Part PDF Grading
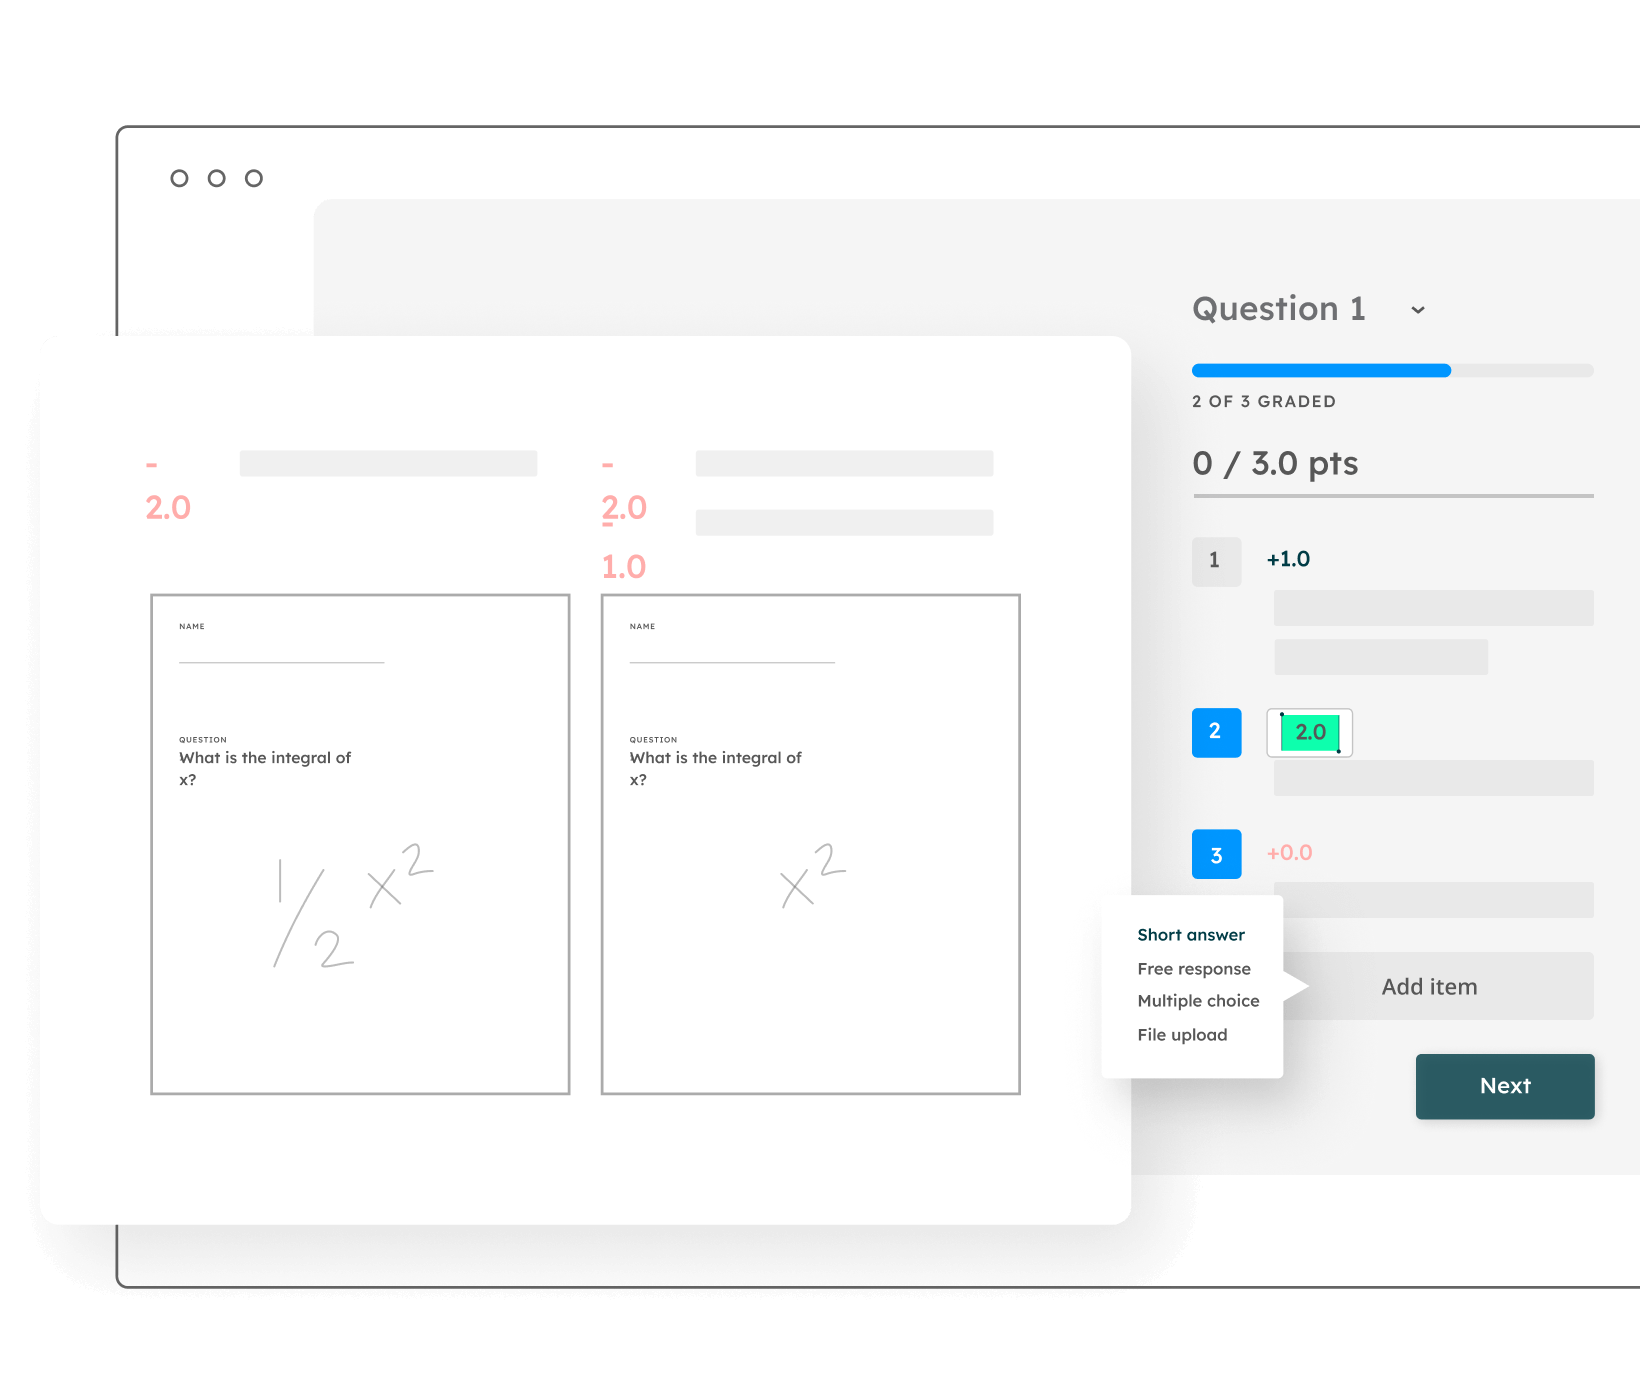
Let me tell you about the edge case that nearly cost me my sanity last fall. We had a midterm with 25 problems across 8 pages, and about a third of the questions required multi-step derivations where partial credit mattered. The standard Gradescope setup assigns each question to a bounding box and scores it independently. This works fine until a student writes their answer to problem 7 across two columns because they ran out of space on the right side. Gradescope's OCR would capture both columns but assign them to different question scopes depending on where the bounding boxes were drawn. One column might score high on method while the other scored zero because the grading rubric expected a single coherent response. I spent three days manually re-scoring because the auto-grader had split answers arbitrarily. The workaround I ended up using was drawing very generous bounding boxes that covered entire page regions instead of individual answer areas, then writing a custom rubric in the "Partial Credit" section that rewarded structure even when the spatial mapping was imperfect. It isn't perfect, but it reduced the manual regrading from 40% of the exam down to about 10%. You still need to verify the weird cases yourself, but you aren't starting from zero.
Get the Full Details
Python Autograding: Environment Consistency Is Everything
When you configure an autograder for Python assignments, the first decision is whether to use Docker or the default sandbox. The default sandbox is faster to set up but notoriously inconsistent between runs. I switched to Docker after a student submitted a solution that happened to work on Python 3.9 but not 3.11, and the grading environment rotated versions between semesters without updating the course config. Docker autograder setup steps: Create a Dockerfile in your repo root that installs Python, pytest, and any dependencies. Keep it minimal because Gradescope pulls and rebuilds this image for every submission batch. A large base image means slow grading turnaround. Use a python:3.11-slim base and install requirements through pip in a single layer.
Then create a run_autograder.sh script that Gradescope calls. This script should set PYTHONPATH, execute pytest with JSON output, and exit with the appropriate code. The JSON output is critical because Gradescope parses it to display individual test results to students. Without it, students see a single pass/fail without any feedback about which tests failed. I also learned the hard way that Gradescope's Docker execution has a timeout. If your autograder takes longer than a certain threshold, the submission gets marked as an error, not a fail. This happened to me when I wrote a test suite that included performance benchmarks for algorithmic efficiency. The benchmarks took 45 seconds per test, and with 20 tests, the total runtime exceeded the timeout. I replaced the benchmarks with simple correctness checks and moved performance validation to a separate optional assignment. The students who wanted extra credit could still prove efficiency, but the core grading didn't timeout anymore.
Rubric Design for Code Assignments
The way you structure your rubric determines whether automated grading saves time or creates more work. A flat rubric with 20 individual criteria sounds thorough until you realize you need to define partial credit for every single one. A tiered rubric with broader categories is faster to build and easier for students to understand. I recommend organizing code rubrics into three tiers: correctness, style, and robustness. Correctness is binary. The code either passes the hidden test cases or it doesn't. Style covers naming conventions, documentation, and code organization. Robustness handles edge cases, input validation, and error handling. This structure maps cleanly onto Gradescope's question group feature. Here is a concrete example from a data structures course I taught. The assignment asked students to implement a balanced binary search tree. The correctness tier had 12 test cases ranging from basic insertions to complex rebalancing scenarios. The style tier checked for method documentation and naming consistency using a lightweight linter. The robustness tier included tests with invalid inputs and empty trees. Students received immediate feedback on all three tiers, and the distribution of scores revealed patterns I wouldn't have noticed grading manually. Most students nailed correctness but ignored robustness. A handful focused so heavily on style that their implementation became unnecessarily complex.
Common Pitfalls That Waste Hours
I wish someone had told me these before I discovered them myself. First, always test your autograder with a known-bad submission before the semester starts. I once deployed a grading pipeline that appeared to work perfectly, only to realize during the first submission window that the test runner was ignoring assertion errors and marking everything as pass. The bug was in my pytest configuration, not in Gradescope itself. A single sanity check with a deliberately broken submission would have caught this in five minutes instead of three hours of confused debugging. Second, be careful about the "Anonymous Grading" setting. When enabled, Gradescope strips student names from submissions, which is great for fairness but terrible if you need to manually review flagged cases. I've had to turn off anonymous grading mid-semester after the auto-rubric caught something suspicious that required identifying the student. The compromise I settled on is enabling anonymous grading for the initial pass and running a second non-anonymous pass on submissions with unusual score distributions.
Third, remember that Gradescope caches uploaded files. If you correct a bug in your autograder after some students have already submitted, those early submissions are graded against the old version unless you re-grade them manually. I learned this when a student emailed me saying their score seemed wrong, and I discovered their submission had been graded before I pushed a fix for a path-handling bug. The fix was simple, but the damage was done for 47 early submissions.
Integration With Canvas and UIUC's Infrastructure
UIUC runs Canvas as its primary LMS, and Gradescope integrates through LTI. The integration works smoothly for grade synchronization, but there are timing issues you need to be aware of. When you publish scores in Gradescope, they don't appear in Canvas immediately. There is a delay that varies from minutes to an hour depending on server load. If you have a hard deadline tied to student visibility, schedule your grade publishing at least two hours before the cutoff. Another quirk specific to UIUC's instance is the authentication flow. Students use their NetID to log in, but some graduate students and external researchers may not have the proper Gradescope permissions. I've had cases where a teaching assistant's account worked fine but a student's account showed a permissions error when trying to view feedback. The fix usually involves the course administrator adding the student to the correct roster, but the roster sync from Canvas to Gradescope isn't always instantaneous.
When Manual Grading Still Makes Sense
Automated grading is powerful, but it fails spectacularly for certain assignment types. Open-ended design questions, creative coding projects, and proofs that rely on non-standard approaches don't map well to automated evaluation. I stopped trying to automate these entirely and instead used Gradescope for the portions I could grade automatically, reserving manual grading for the subjective parts. For a software engineering course, I automated the unit test grading for the implementation phase but manually reviewed the design documentation and architecture decisions. The split meant I spent about 30% of the time I would have spent on fully manual grading while still providing detailed feedback on the parts that actually required human judgment. The students appreciated this because they got fast feedback on their code and thoughtful comments on their design choices. The bottom line is that Gradescope at UIUC works well when you understand its limitations and configure it properly. The platform handles the mundane scoring tasks reliably, but the configuration decisions around file restrictions, rubric structure, and environment setup require deliberate attention. Skip those steps and you will spend more time fixing broken auto-graders than you would have spent grading by hand.