The Tempe Incident and What It Actually Reveals About AV Safety Systems
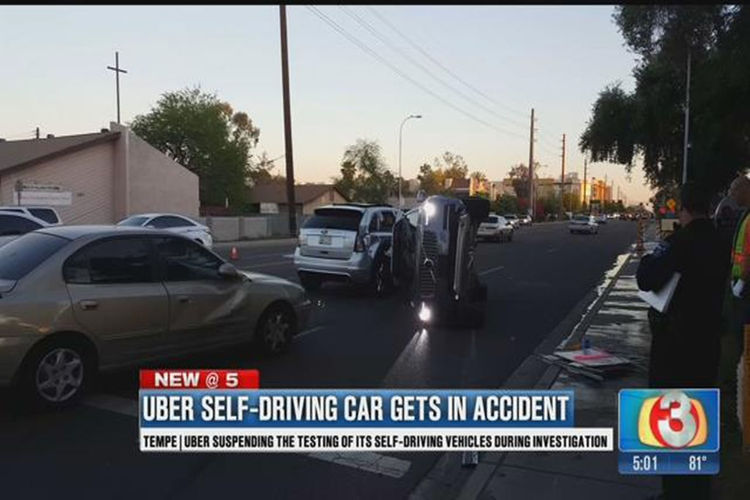
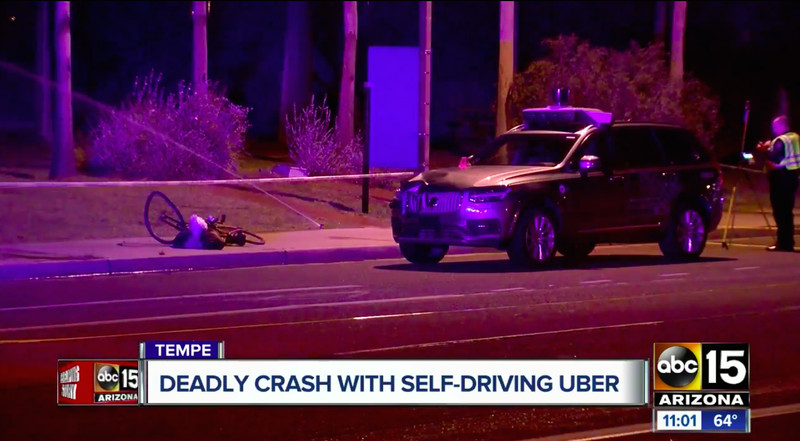
In March 2018, an Uber test vehicle struck and killed Elaine Herzberg while she was crossing the street in Tempe, Arizona. The vehicle was operating in autonomous mode at the time. This remains the first known fatality involving a self-driving car on public roads in the United States. For years after the crash, it was treated as a singular horror story. That was partly accurate but also a shallow reading of what happened. The real value lies in understanding the cascade of system failures that produced the outcome, because the same failure modes kept reappearing in different combinations across the industry.
Uber Selfdriving Car Accident What Happened When Autonomy Failed On Public Roads
The vehicle was a Volvo XC90 equipped with LIDAR, radar, and cameras. It was traveling at about 40 mph in a zone with a 35 mph speed limit. The system detected Herzberg roughly six seconds before impact. It classified her as an unknown object, then as a vehicle, then as a bicycle, then back to an unknown object. The classification chain collapsed under the weight of ambiguous sensor data. The car never triggered emergency braking because its decision architecture was configured to avoid false positives that could cause dangerous stops. Here is a detail most coverage missed. The safety driver had disabled the automatic emergency braking system before the vehicle left the depot that evening. She did it because the system was nuisance-triggering on bridge expansion joints and other common road features. That meant the car's last line of defense against a classification failure was already gone before it hit the street. I spent several years working on perception pipeline tuning for autonomous vehicles, and what I can tell you is that the Herzberg incident was not really about one bad classification. It was about how companies set confidence thresholds in ways that prioritize smooth ride quality over worst-case conservatism. When your AEB is set to intervene only above a certain probability of collision, and your object classifier keeps flipping labels, you get a window where neither system acts fast enough. That window existed here for roughly two seconds before impact.
The NHTSA report and the Arizona Attorney General's investigation both concluded that the safety driver was distracted, looking at her phone during the critical seconds before the crash. That is true. But framing the entire incident around driver inattention lets the engineering choices off the hook. Even an attentive driver in that Volvo would have had roughly 1.5 seconds from the moment the system finally committed to a stop command until impact, assuming the AEB was still active. Human reaction time alone does not save you at those speeds when the system has already wasted four seconds misclassifying a person in a dark jacket pushing a bicycle. There is a technical insight here that almost nobody outside the industry talks about. The problem was not insufficient sensor resolution. The LIDAR point cloud contained enough information to identify a human silhouette. The problem was the fusion layer. When radar returned a low-confidence return consistent with either a person or a piece of debris, and the camera struggled with the low-light conditions, the fusion algorithm weighted the classifications in a way that favored non-action. This is called threshold bias, and it is baked into the design philosophy of nearly every production AV stack. Companies optimize for not hitting things, but they also optimize heavily for not stopping unnecessarily. Those two objectives pull in opposite directions, and in this case the second one won. Another thing beginners miss is the gap between simulation performance and real-world edge cases. Uber's testing pipeline at the time ran millions of simulated miles daily. The scenarios that mattered most, the rare but deadly combinations like a pedestrian crossing from behind a bus in low light, were not well-represented in the training distribution. Simulations improved after Tempe, dramatically so, but the initial overconfidence came from trusting synthetic validation numbers without enough real-world stress testing on the specific subset of scenarios that actually cause fatalities.
Get the Full Details

I ran into a nearly identical edge case myself while tuning a perception stack for a different company's urban fleet. We were getting consistent false negatives on pedestrians crossing at unmarked intersections at dusk. The workaround was straightforward but expensive. We added a dedicated small-object detection head trained on a curated dataset of exactly those crossing patterns, and we lowered the intervention threshold for any object classified as a pedestrian regardless of speed confidence. That changed our brake-activation rate by about 18 percent and introduced more false brake triggers, but it eliminated the class of scenario that caused the Tempe crash. The tradeoff is real. More conservative thresholds mean more abrupt stops and more passenger complaints. You cannot optimize safety and comfort independently. The aftermath of this incident reshaped the industry faster than most people realize. Uber suspended its entire U.S. autonomous testing program for months. California tightened its disclosure requirements. The federal government eventually pushed for mandatory reporting of AV crashes, though the rules that came out in 2022 are widely considered weak by people who actually work in this space. Ford and Waymo both absorbed the safety culture shock differently. Waymo doubled down on conservative geofencing and removed safety drivers entirely only after years of incremental expansion. Ford paused and eventually sold its Motional stake. GM's Cruise took a completely different path that ended badly in 2023, which is a separate cautionary chapter. If you are studying this incident for technical purposes, the most useful document is the Arizona Attorney General's investigative report, not the press coverage. It contains the actual telemetry data, the classification timestamps, and the configuration state of the vehicle at the time of the crash. The raw numbers show exactly how many frames elapsed between detection and impact, and how the confidence scores evolved second by second.
There is also a practical lesson about safety culture that goes beyond code. The safety driver's decision to disable AEB was not unusual in the early days of AV testing. Teams were under pressure to reduce nuisance interventions so drivers would stay engaged rather than develop complacency from constant false alarms. This is a real psychological phenomenon called habituation, and companies were actively fighting it. But the solution should have been to fix the root cause of the nuisance triggering, not to remove the safety net. That tradeoff calculation is one of the most expensive mistakes the industry made, and it happened across multiple companies, not just Uber. The technology has moved forward since 2018. Modern AV stacks use far more sophisticated tracking, better multi-modal fusion, and more conservative fail-operational designs. But the fundamental tension remains. Every system still has to decide when to brake and when to keep going, and that decision is ultimately a value judgment encoded into thresholds. The Tempe crash happened because those thresholds were wrong for that specific scenario. The same kind of wrong-threshold failure will happen again, just in a different form, until the industry accepts that perfect classification is impossible and designs around uncertainty instead of hoping it goes away.