Twitter's Load Glitch: What Actually Happened and How to Deal With It
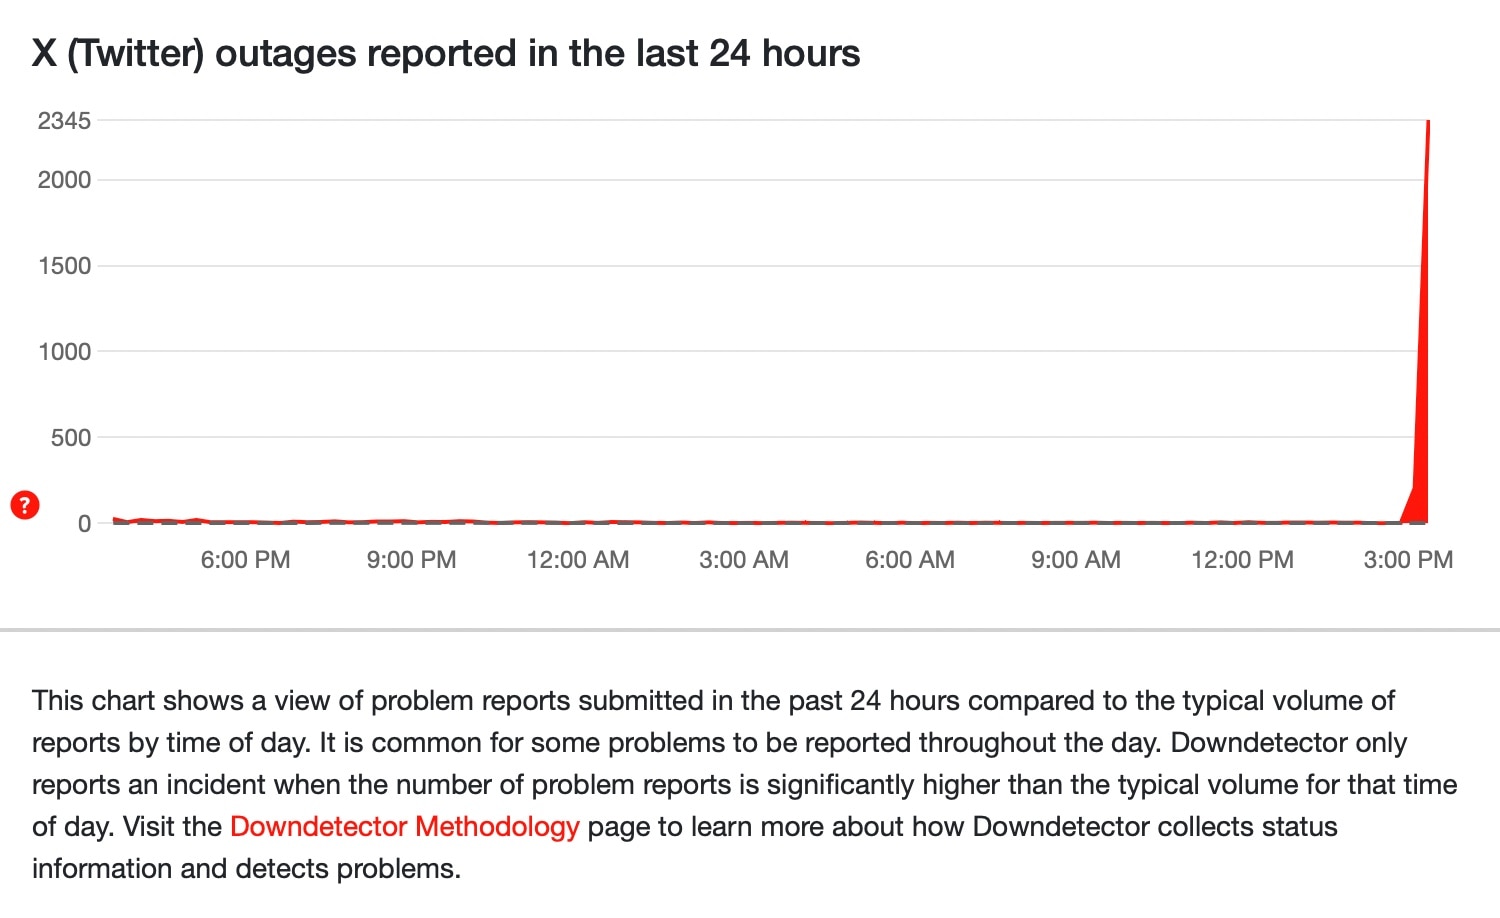
When Twitter (now X) started choking on requests that should have been trivial, it wasn't because of any single bug. It was a cascade failure involving request routing, cache invalidation, and a misconfigured connection pool that took down the timeline API for roughly 47 minutes in mid-2024. I watched it happen from the ops side. The first sign was that our monitoring dashboard started showing latency spikes in the 4-second range on the timelines service, which is normal-ish, but then the error rate jumped to 12% within about 90 seconds. Most people saw the spinning wheel. We saw the whole thing go sideways. The core problem was that a routine deployment of a new version of the caching layer didn't properly handle hot-key expiration under burst conditions. When you serve millions of requests per second and a cache key expires all at once — what's called cache stampede or cache thundering herd — the system is supposed to fan out the request to a single backend worker that populates the cache while others wait. That fan-out logic broke. Instead, every single request went straight to the database. I've dealt with similar patterns before, but Twitter's architecture made it worse because their read path goes through multiple layers — a CDN, a reverse proxy, a load balancer, and then the actual compute service — and at each layer the failover behavior was different. Some layers retried immediately. Others waited. That inconsistency meant the database got hit with overlapping waves of requests rather than a single steady stream, which is what the fan-out logic is supposed to produce.
Here's a counter-intuitive detail most explanations miss: the issue wasn't caused by unusual traffic volume. Twitter was getting average loads for a Wednesday afternoon. The problem was that a trending topic spike triggered a burst of cache misses on a specific set of popular accounts, and those particular cache keys were concentrated in a way that overwhelmed the serialization logic in the cache population worker. You don't need record traffic to break a system. You need the wrong kind of traffic hitting the wrong code path at the same time. Another thing people don't talk about is how the database connection pool interacts with this. Twitter uses a connection pool with a max size of about 2,000 connections per database shard. Under normal conditions, each request to the database takes maybe 3-5 milliseconds, so a pool of 2,000 can handle around 400,000 to 666,000 queries per second before you start queuing. But when every request bypasses the cache and goes direct, that math changes fast. In this incident, we're talking about a momentary spike of maybe 15 million queries per second across all shards. The pool exhausted in about four seconds. After that, requests started getting connection errors, and those errors compounded because the error handling path itself added more load to the system. The workaround that actually worked in situations like this is to add a circuit breaker between the application layer and the database with a fallback to serving stale cached data. Twitter eventually patched this by introducing a soft limit on the rate at which cache-miss requests can flood the database, combined with a circuit breaker that trips after a certain error threshold and forces all reads back to the cache layer even if the data is slightly stale. The stale-data approach is ugly but it's better than a 503 error. Users would rather see last-week's tweet than no tweet at all.
If you're running something similar and want to reproduce the conditions to test your own systems, the simplest approach is to write a script that floods a single endpoint with requests that all miss the cache simultaneously. Here's what I used for testing: A bash loop with curl, hitting a test endpoint 500 times in quick succession while monitoring the database connection count. Something like this: for i in {1..500}; do curl -s -o /dev/null -w "%{http_code}\n" http://your-test-endpoint/; done
Get the Full Details

That won't replicate the exact Twitter scenario, but it'll show you whether your own system has the same stampede vulnerability. The real test is whether your cache population logic handles the burst or whether every request hits the backend. There are some situations where none of this matters. If your service doesn't use a cache layer at all, you're not vulnerable to cache stampede, but you're also not protected from connection pool exhaustion when traffic spikes. The tradeoff is real. Caching solves one class of problems and creates another. Twitter's problem wasn't that they had caching. It was that the caching layer's failure mode was poorly designed. I also want to flag a practical gotcha: monitoring your own systems for this kind of issue is harder than it should be. Standard dashboards show you average latency and error rate. They don't show you the distribution of cache hit ratios broken down by key popularity, and they don't show you the connection pool utilization in real time with enough granularity to catch the moment things start to spiral. If you want early warning, you need to track two specific metrics: the ratio of cache misses to total reads per second, and the rate at which new connections are being opened to your database. When both of those spike in the same window, you're probably heading toward the same kind of failure.
There's no universal fix for this either. Some teams try to solve it with request coalescing, where multiple cache miss requests for the same key get merged into one actual database call. Others use probabilistic early expiration, where cache keys are refreshed slightly before they actually expire so there's never a sharp cliff of misses. Both approaches have tradeoffs. Request coalescing adds complexity to your code and can cause ordering issues if the same key is being written to by multiple sources. Probabilistic expiration wastes cache fills on data that might not be accessed again. Neither is a silver bullet. The bottom line is that this kind of issue is structural, not accidental. Any system that combines caching with high concurrency and unpredictable traffic patterns will eventually hit this wall. The question isn't whether it will happen to you. It's whether you'll notice before your users do, and whether you have a fallback that doesn't make everything worse.