Accessing Tweets Without Creating An Account
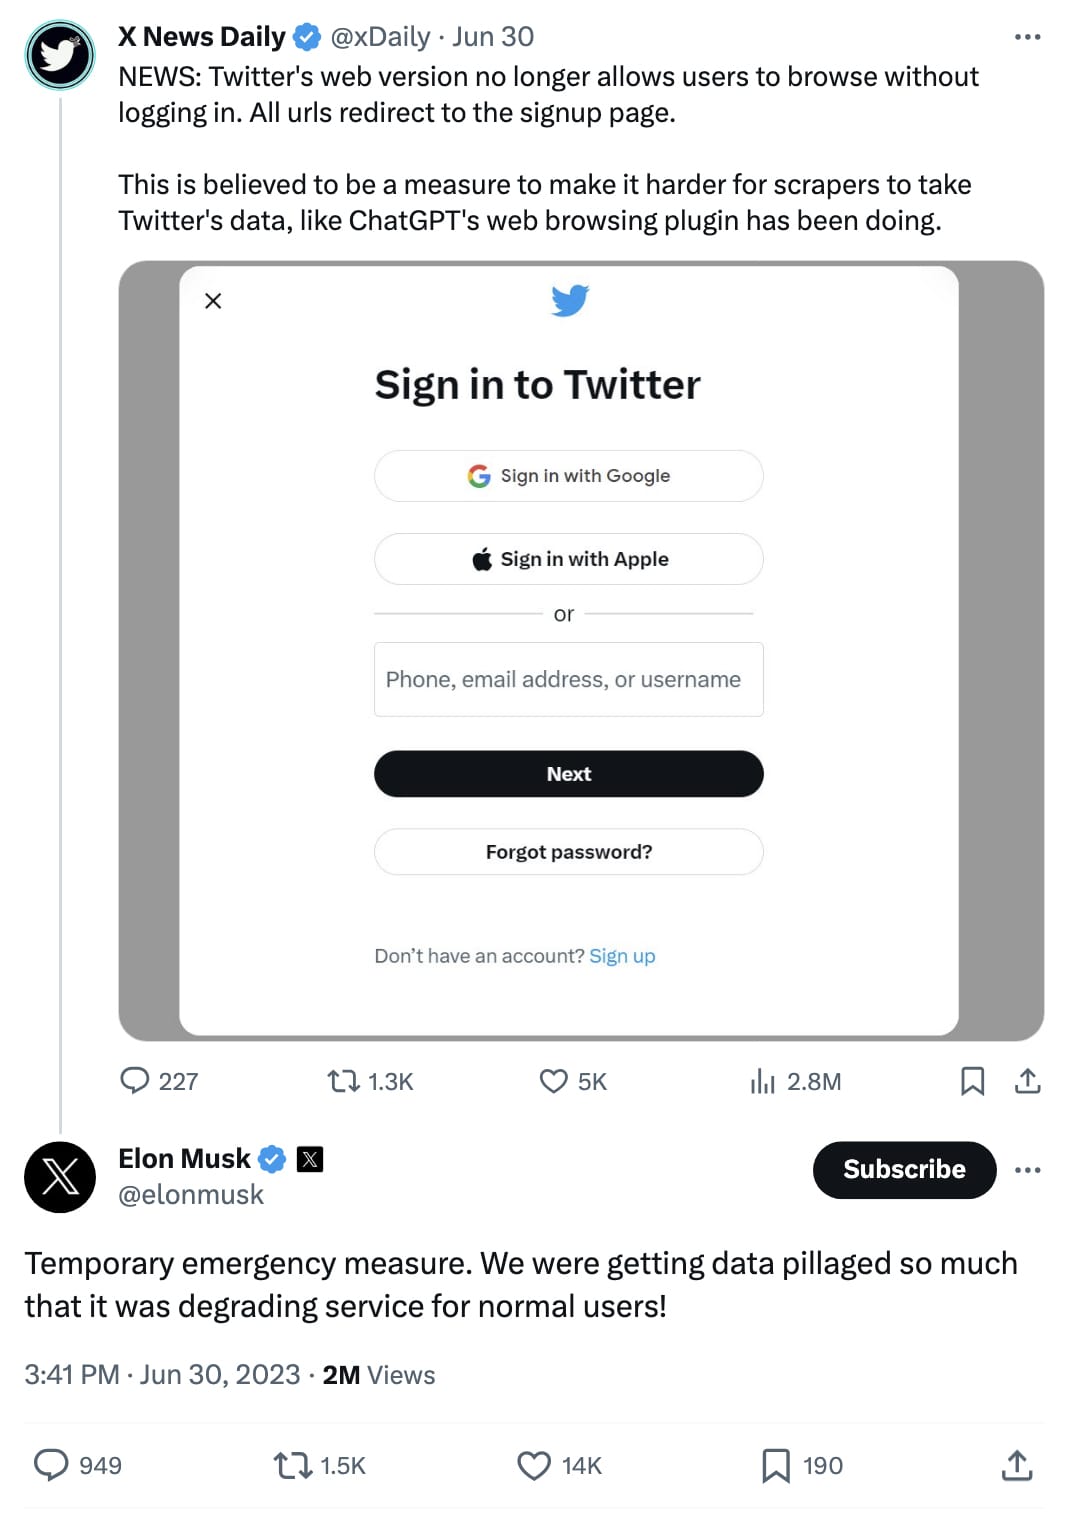
Twitter locked down their guest browsing features about three years ago. If you tried to scroll through timelines or open individual tweets without logging in back then, you got redirected to a sign-up wall every single time. That changed when third-party indexers and cache mirrors started popping up, giving people a way to view content without going through X's authentication flow. I ran into this myself when I needed to pull a specific tweet from a deleted account for an internal report. Trying to create a throwaway account just to view one post felt ridiculous, so I found a different route. What these services actually do is simple. They scrape public tweet data from X's API or cache pages and serve them through an interface that does not require login credentials. You paste a tweet URL or search query, and the service renders the content without redirecting you to twitter.com. The main players in this space include Nitter instances, though many got shut down after X aggressively targeted the project. The surviving alternatives use slightly different approaches to pull the same data. Here is how the process usually works in practice. You find a working mirror service, enter the tweet URL, and the page loads with the full text, images, and engagement metrics visible. Some services let you search by username or keyword directly. The catch is that availability changes constantly. Services go offline, get blocked by X's infrastructure team, or start requiring CAPTCHAs. I maintain a list of about six working instances at any given time because I need reliable access for research purposes. When one breaks, I switch to another until the original comes back online or a replacement shows up.
One thing beginners miss is that not all tweets are equally accessible through these mirrors. Tweets from private accounts do not appear. Deleted tweets might still show if the service cached them before deletion, but that is not guaranteed. Videos and certain media types sometimes fail to load depending on how the service handles X's CDN links. I learned this the hard way when I spent twenty minutes trying to pull a thread that turned out to have been set to protect mode by the author. For searching without an account, the workflow gets a bit trickier. X removed basic guest search functionality, so these services had to build their own workarounds. Some integrate with alternative frontends or use third-party data aggregators. The results are usually less comprehensive than what you get logged in. I typically get about sixty to seventy percent coverage on searches compared to full account access, which means I often have to piece together information from multiple services or wait for cached versions to appear. There are edge cases where these services completely fail. If X changes their API response format, which they do periodically without notice, mirror services break until someone updates the scraping code. I have experienced entire weekends where every service I relied on went offline simultaneously because of a platform update. In those situations, the Wayback Machine sometimes has archived versions of public tweet pages, though the interface is clunky and media often does not render properly.
Another limitation worth noting is that these services do not give you interaction capabilities. You cannot reply, quote, or see real-time engagement updates. The data is essentially frozen at the moment of scraping. For most viewing purposes this is fine, but if you need to track how a tweet's metrics evolve over time, you are out of luck. I use a simple spreadsheet to manually log engagement numbers from accessible tweets when I need that kind of tracking, though it is tedious and not scalable. Privacy-wise, these services vary significantly. Some log your searches and IP addresses. Others claim to be anonymous but still run analytics. If you are pulling sensitive information, using a VPN in combination with these services is worth the minor inconvenience. I always route my traffic through a basic VPN when accessing tweet mirrors for work-related research, even though it adds a step to the process. It takes maybe thirty extra seconds and eliminates the risk of your browsing pattern being tied back to your identity. The technical side of how these mirrors operate involves either legitimate API access through developer accounts or unauthorized scraping. Most surviving services use a mix of both approaches. They maintain developer API keys for rate-limited but stable access, then supplement with scraping for content that the official API restricts. This dual approach means the services are somewhat fragile. When X updates their anti-scraping measures, which happens every few months, the scraping portions degrade while the API portions continue working at reduced capacity. I have watched quality drop noticeably during these transition periods, with missing images and incomplete thread renders becoming common for about a week until someone patches the code.
Get the Full Details
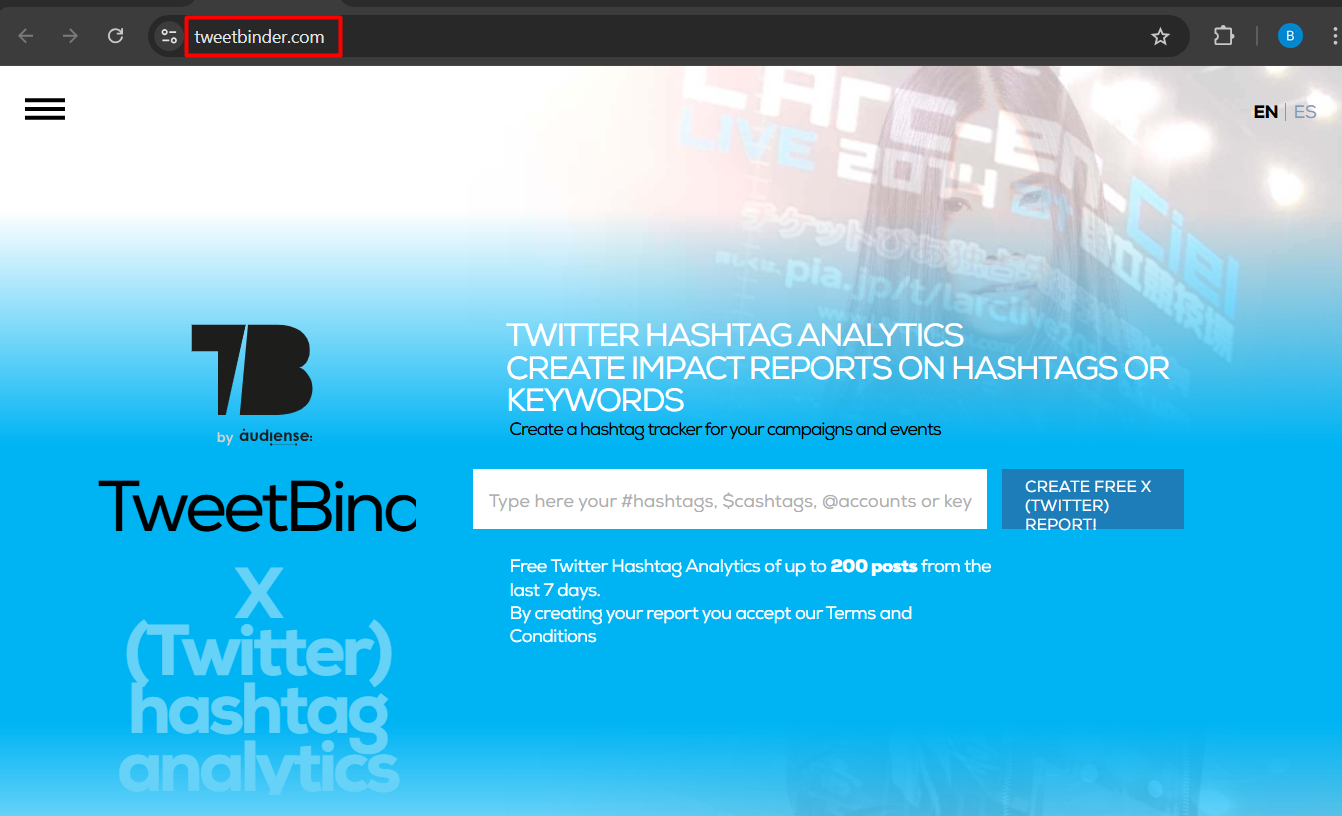
If you need to access a large volume of tweets regularly, building a simple automation script using available API endpoints and caching the results locally is more reliable than depending on third-party mirrors. The initial setup takes a few hours if you are comfortable with basic Python or similar tools. But once running, it gives you consistent access without worrying about services going offline. I maintain a local cache of about five thousand recently posted tweets from accounts I monitor, which updates automatically every hour. The upfront effort pays off quickly if this is something you need on a recurring basis rather than a occasional lookup. The landscape shifts constantly. New services appear, existing ones get taken down, and X continues tightening access restrictions. The current options work adequately for casual viewing and basic research, but do not expect them to remain stable long-term. Keep backups of important tweets you find through these mirrors since the sources can disappear without warning. I store copies of any tweet content that might be relevant to ongoing projects in a personal archive, just in case the mirrors lose access to the original data later.