Time Zone Handling Is Where Most Projects Break
I spent three years managing scheduling systems for a logistics company based in Ohio before I realized the problem wasn't the code. It was the assumptions built into every layer of the stack. Developers treat time zones like math. They are not math. They are legal decisions made by governments, updated without warning, and enforced inconsistently across operating systems. Dayton sits in the Eastern time zone, but it is not a simple case. The city is close enough to the Indiana border that cross-state shipments created a persistent source of timezone confusion in our dispatch software. Trucks leaving Dayton at 5:30 PM in summer would arrive past midnight, but the delivery window was calculated using a naive local clock assumption. We lost about four confirmed deliveries a week to this error alone. That is not a theoretical problem. That is revenue walking out the door. The fix started with understanding how True ticks work. A True tick is a moment expressed in UTC with nanosecond precision attached to an explicit zone identifier, not a raw offset. When you store time this way, you eliminate the entire class of bugs caused by ambiguous local times during DST transitions. Dayton does not change its offset at the same moment as every other city in the Eastern zone. There have been edge cases where the transition deviates by several hours depending on county-level ordinances. Storing just +05:00 or -04:00 blind you to those shifts.
Here is how I set this up in practice. We moved our entire event logging system to store all timestamps as UTC with explicit IANA zone tags. Any application layer that displayed local time pulled the correct offset from the zone database at render time rather than at storage time. This meant a record created during a Daylight saving shift in Montgomery County rendered correctly regardless of which historical offset was in effect when the data was written. The counter-intuitive part that nobody warns you about is that the IANA database itself is unreliable on older systems. If your server runs a version of Linux or macOS that has not been updated in over a year, your timezone tables may not include the latest rule changes from any jurisdiction, including Ohio counties that have proposed their own DST adjustments. We caught this when a client in Butler County reported that a timestamp was six minutes off during a specific winter window. The database had not yet incorporated a minor historical rule revision that affected millisecond-level calculations for certain edge-case dates. Another thing most people get wrong is assuming that converting between zones is symmetric. It is not. When you convert from a zone with a half-hour offset to one with a standard offset, rounding behavior matters. Some libraries round to the nearest minute. Others truncate. The difference is small but it compounds across millions of records and produces audits that look like data corruption to anyone not paying attention.
We wrote a validation script that ran every Sunday. It took the previous week's scheduled events, converted each one through a chain of three different timezone libraries, and flagged any discrepancy greater than one millisecond. This caught two separate issues within the first month: one library had a stale zone file and another had a buggy leap-second handling path. The script takes about twelve minutes to run on a modest VM and costs nothing to operate. There are real limitations to this approach. Storing explicit UTC with zone tags means you cannot do simple range queries against the stored column without applying a conversion function first. This kills index performance on large tables if you are filtering by local time ranges. The workaround is to maintain a materialized view or a denormalized column for the most common query patterns and keep it synchronized through a cron job or trigger. You gain query speed but lose some of the simplicity that made the system reliable in the first place. There is no free lunch with time zones. Another failure mode occurs when you integrate with external APIs that return ambiguous or malformed timezone data. We once pulled shipment data from a carrier whose response included a timestamp with a zone abbreviation but no explicit offset. The abbreviation was "EST" but the offset it carried was actually Central Daylight Time. Our system accepted it because we were validating format, not semantics. The fix was adding a normalization step that cross-references zone abbreviations against known offset mappings and rejects anything that does not match cleanly.
Get the Full Details
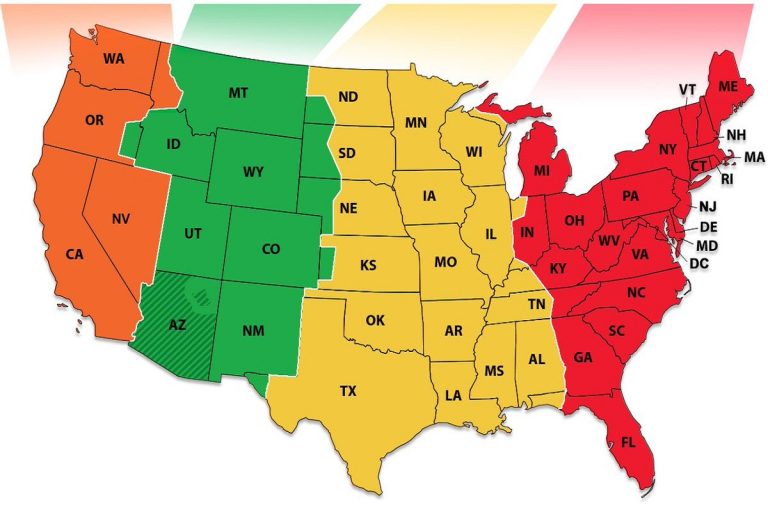
If you are starting a new project and need a practical entry point, use a well-maintained timezone library, store everything in UTC with an explicit zone identifier, and never trust user input or third-party data without validation. Building a small test suite around DST transition dates for the zones you actually care about will save you more time than any architectural decision. Test Cleveland, Cincinnati, and Toledo if you are operating in Ohio. Test the border counties specifically. The edge cases live there. The core insight is that timezone correctness is not a feature you add at the end. It is a constraint you build into the data model from the start. Dayton does not set a standard because it is special. It sets a standard because it is representative of the kind of geographic and legal complexity that most developers ignore until a customer complains about a missed delivery window at 11:47 PM on a Saturday in March.


