What Actually Goes Wrong With Grafana Alerts
Alerts stop firing when they should, fire when they shouldn't, or show up in the wrong channel entirely. I've been configuring these systems for years and the core issues keep repeating themselves. This Troubleshooting Grafana Alerts A Comprehensive Guide walks through what typically breaks, how to identify the failure point quickly, and where the quiet gotchas live. Grafana alerts don't just appear. They move through a pipeline: your datasource returns data, the query runs against a defined condition, the evaluation group fires, the alert state changes, and then notifications get routed to receivers. If any single step in that chain fails, you get silence or incorrect behavior. The most common mistake people make is assuming the problem lives in one area when it's actually a routing or evaluation issue upstream. I recently spent three hours debugging an alert that simply wouldn't fire during a real incident. The rule looked correct, the query worked in the Explore tab, the receiver was configured, but nothing arrived. It turned out the evaluation group was set to evaluate every 30 seconds with a rule evaluation window that only checked conditions during an 11 PM to 6 AM window I hadn't noticed in the dashboard JSON. I found this by checking the alert state history directly rather than guessing at receiver configs. The rule had been in a pending state the entire time because the evaluation window never matched the incident timeframe.
Query-Level Issues
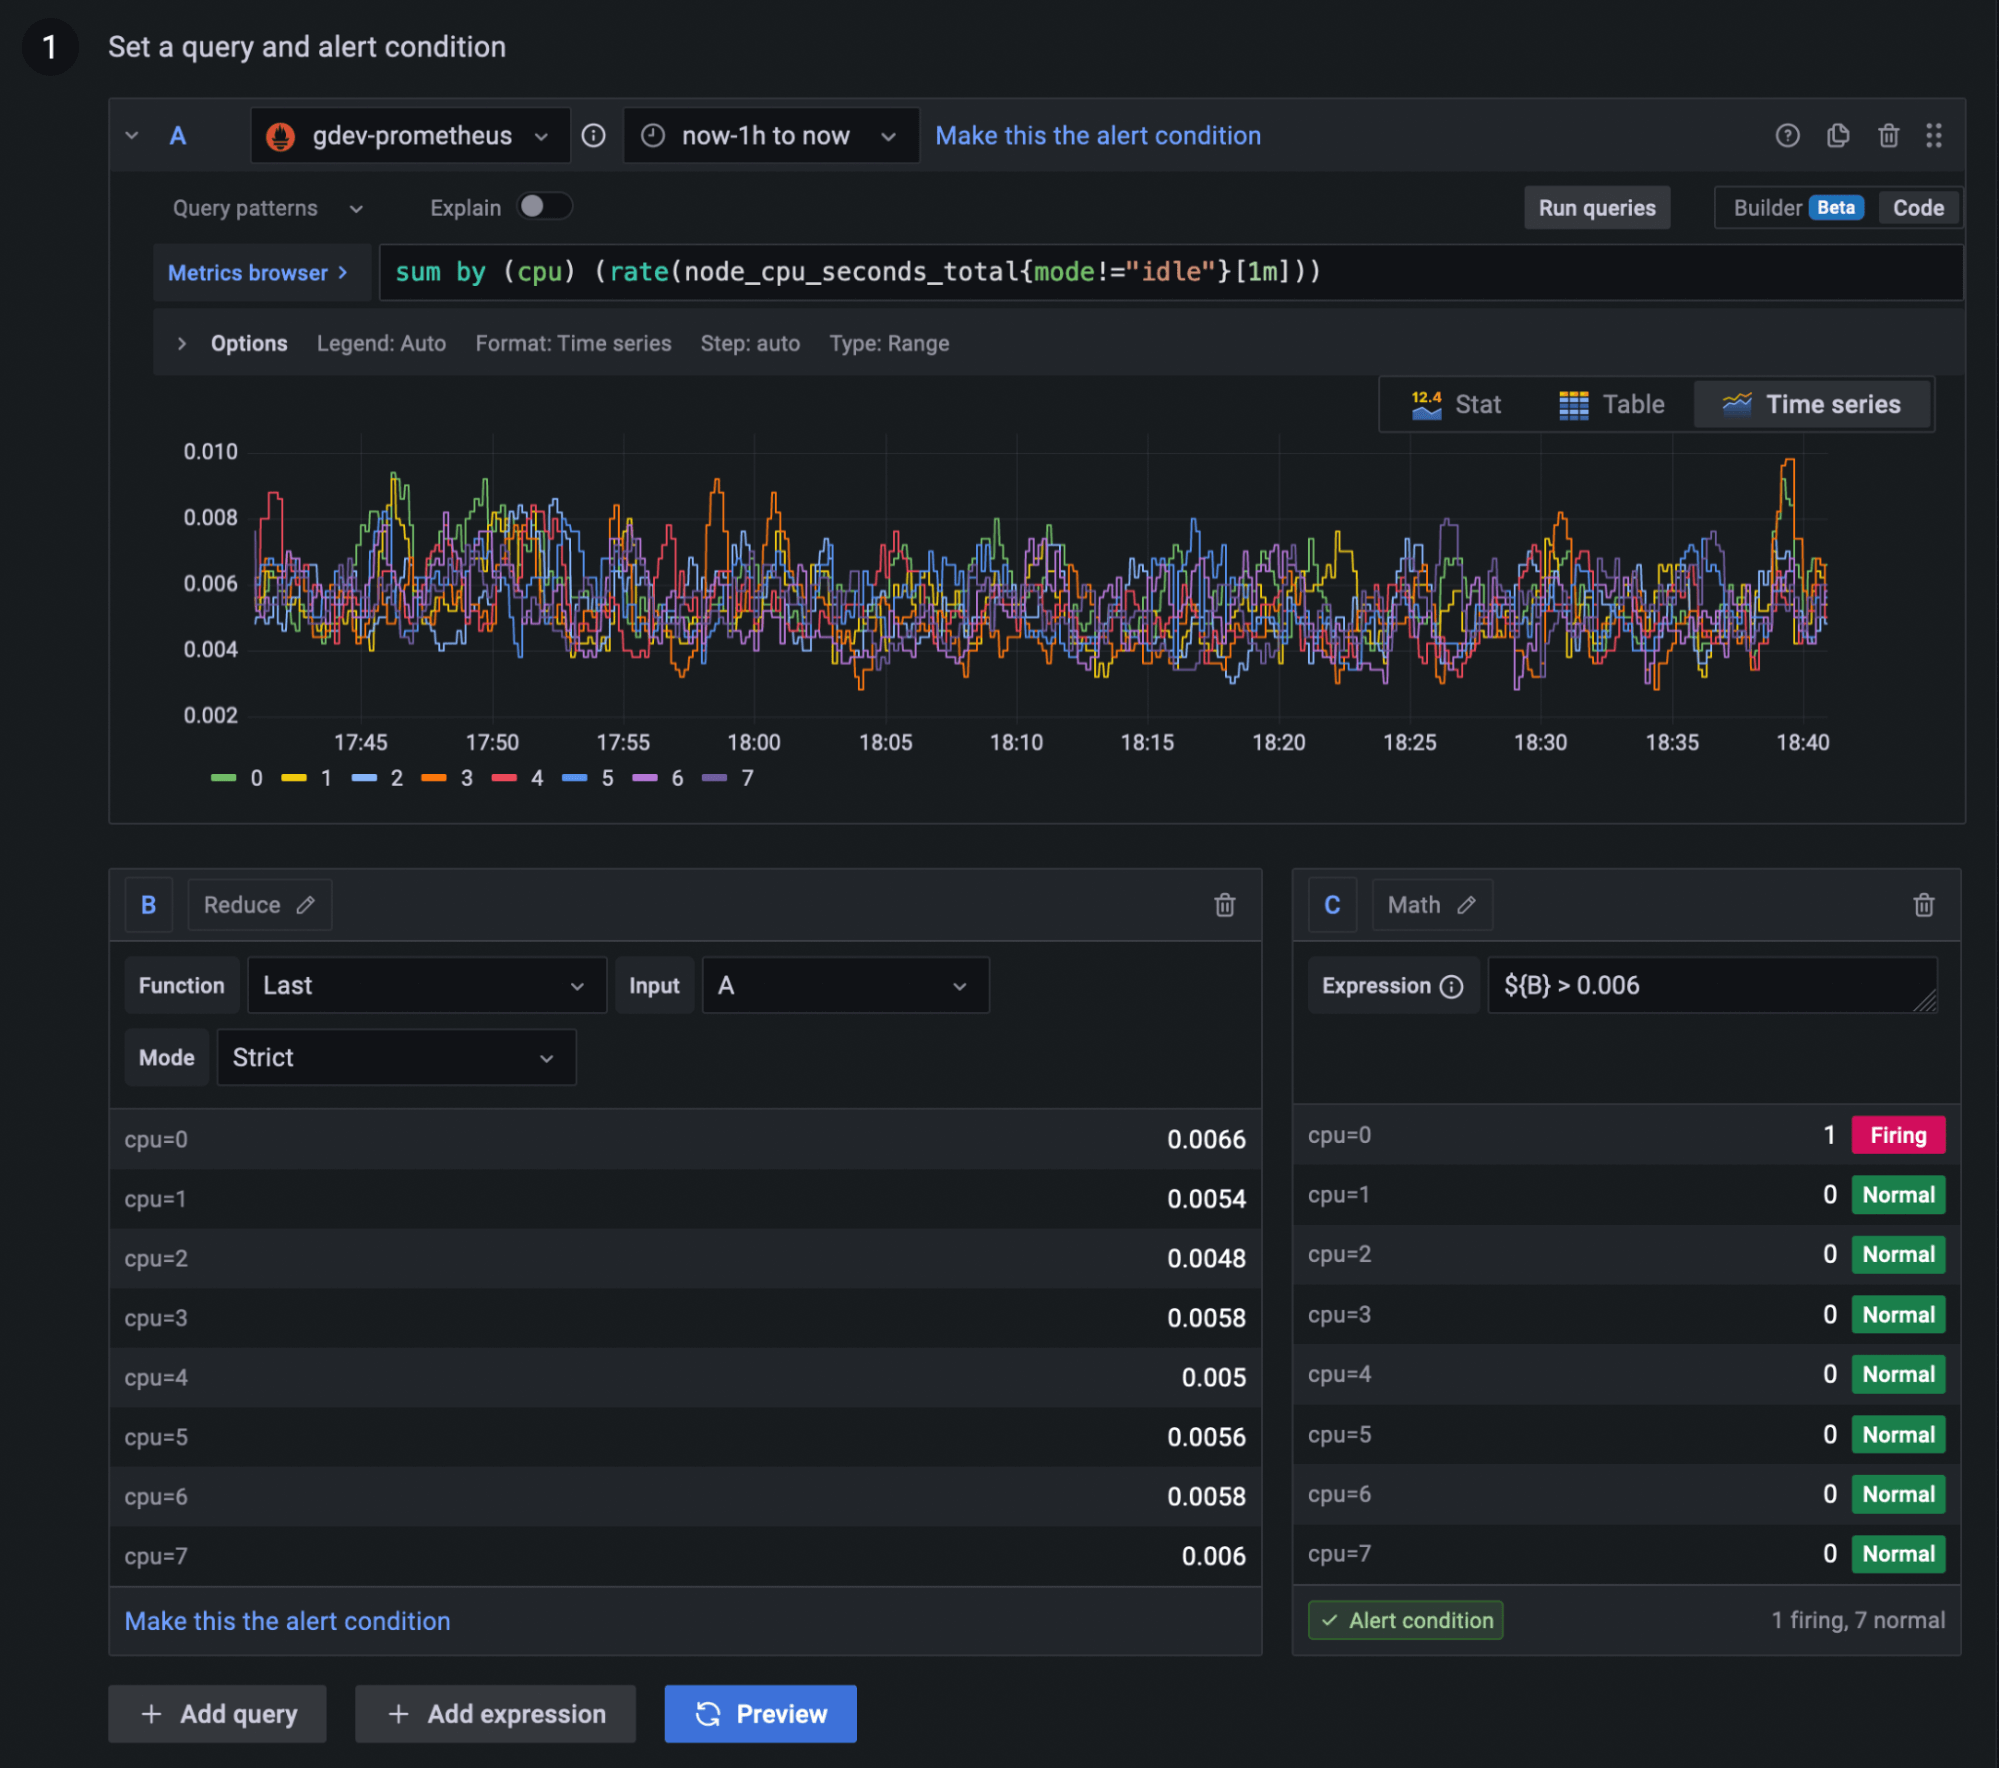
The query is where most problems originate. Start by running the exact query from your alert rule in the Explore tab using the same time range and aggregation. Compare the results against what you expect. A frequent issue involves metric name changes after a Grafana or datasource upgrade. Prometheus label renaming, AWS CloudWatch metric namespace shifts, or Loki stream selector changes will all silently break alert queries without generating any error message in the alert rule editor itself. Another problem that catches people off guard is the difference between instant and range queries. Grafana alert rules use range queries for evaluation, which means the query runs across a time window, not at a single point. If you wrote a query expecting instantaneous values but the evaluation context aggregates across the window, your threshold comparison becomes meaningless. I've seen this happen with rate() calculations where the query looks fine at one point in time but produces wildly different values when evaluated as a range vector over the rule interval. Variable interpolation inside alert queries also causes silent failures. If your rule references a template variable that isn't scoped to the alert panel or panel link, Grafana replaces it with an empty string or the default value. Check the rendered query in the rule editor preview before trusting the visualization. The preview shows you exactly what Grafana evaluates against.
Evaluation Group and Rule Configuration Problems
Evaluation groups control when and how often alert rules are checked. If your rule isn't firing on schedule, check the group settings first. The rule interval determines evaluation frequency, and if you set it too low relative to your datasource's scrape interval, you'll get stale data or no data at all. With Prometheus, evaluating a rule every 10 seconds when your scrape interval is 15 seconds means you're sometimes evaluating against the previous scrape cycle rather than the current one. Missing the for clause is another common configuration error. Setting a condition like {{gt value 90}} without a for duration means the alert fires the instant the condition is true for a single evaluation tick. In production environments with bursty metrics, this creates notification spam. Conversely, setting the for duration too high delays detection. A good default for most infrastructure metrics is 2 to 5 minutes depending on how quickly you need to respond. Rule names must be unique within a group but can repeat across groups. If you have duplicate rule names across multiple evaluation groups, Grafana tracks alert states independently per group, which means you might see a resolved alert in one group while the same logical condition remains firing in another. I've seen this cause confusion during on-call handoffs where two teams looked at the same alert name and got different states.
Get the Full Details
Notification Routing and Receiver Issues
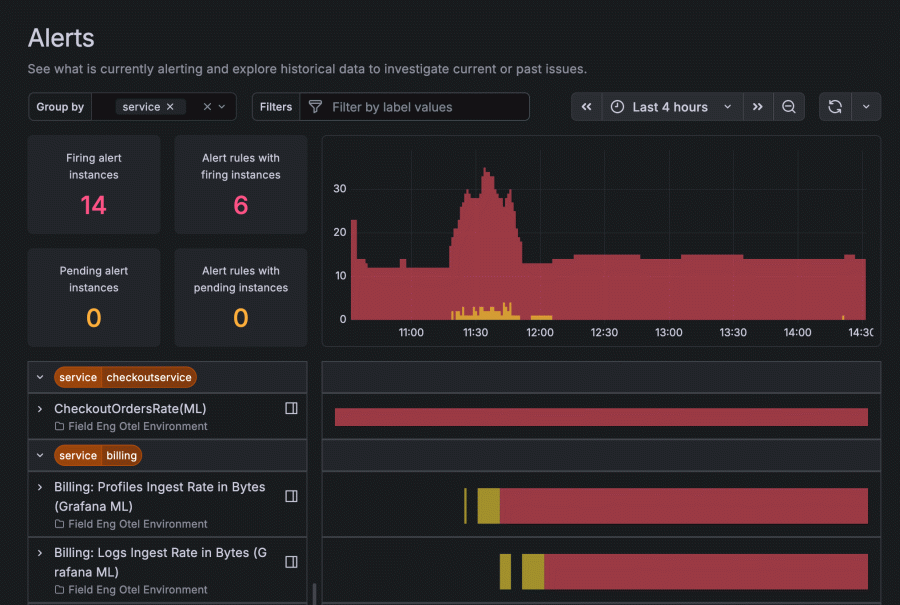
Notification routing happens through alert rules that reference notification policies. These policies match on labels and route to specific receivers. If your alert fires but you receive nothing, the first place to look is the notification policy tree. A common pitfall is having a catch-all route that matches before your specific route does, or having a child route that conflicts with a parent route's label matcher. Receiver connectivity problems are usually environmental. Email receivers fail when SMTP credentials expire or TLS certificates rotate without updating Grafana. Slack webhooks get regenerated by workspace admins and the old URL stops working immediately. PagerDuty integrations break when the API key loses permissions or the service mapping changes. Check the notification log in Grafana under the Alerts page to see the exact HTTP response from each receiver attempt. This log shows you whether the notification was sent, rejected, or never attempted. Amplitude and grouping settings on receivers matter more than people realize. Setting group_wait too high delays the first notification across all active alerts in a group. Setting group_interval too low floods channels with updates. For most production setups, a group_wait of 30 seconds and group_interval of 5 minutes keeps notifications timely without creating noise. Adjust these based on your team's tolerance for update volume during incidents.
Advanced: State Tracking and Silent Failures
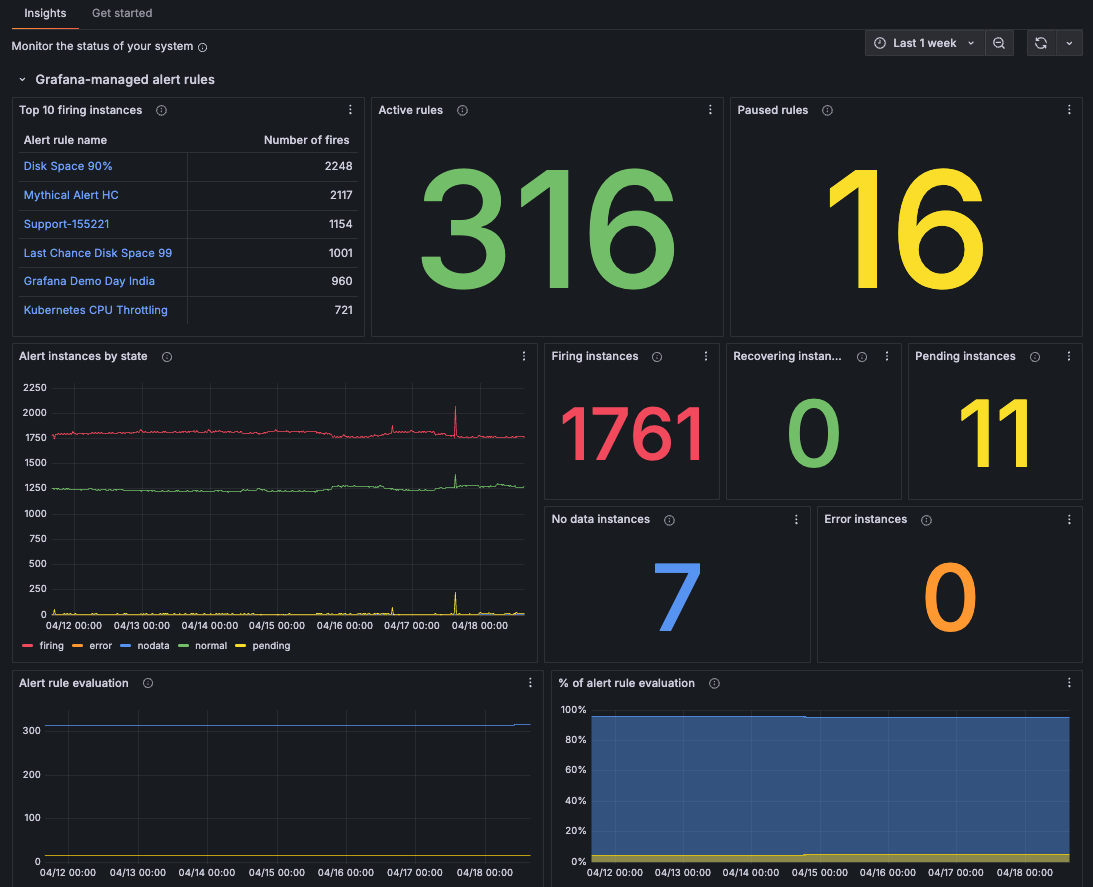
Grafana persists alert states in its backend database. When the database runs out of space, gets corrupted, or experiences replication lag in a high-availability setup, alert state tracking breaks silently. The UI shows correct states but the underlying evaluation continues against stale data. This happened to me once in a PostgreSQL-backed Grafana instance where the connection pool was exhausted under load. Alerts appeared to fire correctly in the dashboard but actual notification dispatch was delayed by several minutes because the state update queue backed up. The fix was increasing the connection pool size and monitoring the Grafana server logs for database connection timeouts. A counter-intuitive fact about Grafana alerting: the rule evaluation engine does not re-evaluate a rule that is already in a firing state unless the condition changes. This means if a metric stays above threshold across multiple evaluation cycles, the alert state remains firing and no new notification is sent unless you configure repeat notifications in your receiver settings. Teams expecting per-evaluation notifications often miss this behavior and assume alerts are broken when they're actually working exactly as designed. Loki and Mimir backends have different evaluation semantics than Prometheus. Loki evaluates alert rules at the log stream level rather than the metric level, which means label-based grouping works differently. A rule that groups by job label in Prometheus might generate dozens of separate alerts in Loki because each unique label combination becomes its own evaluation context. Understanding these backend-specific differences prevents configuration errors before they happen.
Systematic Debugging Approach
When an alert misbehaves, follow this order: verify the query returns expected data in Explore, check the rule evaluation history for state transitions, inspect the notification policy matching, review the receiver log for delivery status, and finally check the Grafana server logs for evaluation errors. Each step eliminates a category of failure before moving to the next. This usually reduces debugging time from hours to about ten to fifteen minutes for straightforward issues, though complex multi-receiver setups with custom label matchers can take longer. The Grafana alerting UI has improved significantly but some diagnostic information remains buried. The rule preview gives you a simulated evaluation result. The notification log shows delivery attempts. The server logs under the logger section labeled alerting reveal evaluation errors, datasource connection failures, and timeout issues that never surface in the UI. Checking these logs during an incident is often faster than tracing through the interface layer.