How CTA Bus Tracker Actually Works Under the Hood
The Chicago Transit Authority runs real-time bus tracking across over 130 routes. When you open the app and see a bus icon moving along a route, that data comes from GPS transponders mounted inside each vehicle. Every few seconds the device broadcasts location, speed, heading, and route ID back to a central ingest point. The system stores these as timestamped position records and serves them to clients via an API endpoint.
I spent about six months debugging why certain stops showed buses that were clearly not there. The issue was GPS drift inside elevated train structures and tunnels near downtown. The tracker would report a position that mathematically existed on the street grid but didn't correspond to the actual road the bus was on. My workaround was simple: I stopped relying on raw latitude/longitude pairs and started using the route-matched position data the API provides. The server-side matching snaps the reported position to the nearest valid bus corridor. It fixes about eighty percent of these ghost-bus problems.
Transforming Public Transportation The Cuttingedge Technology Of Cta Bus Tracker
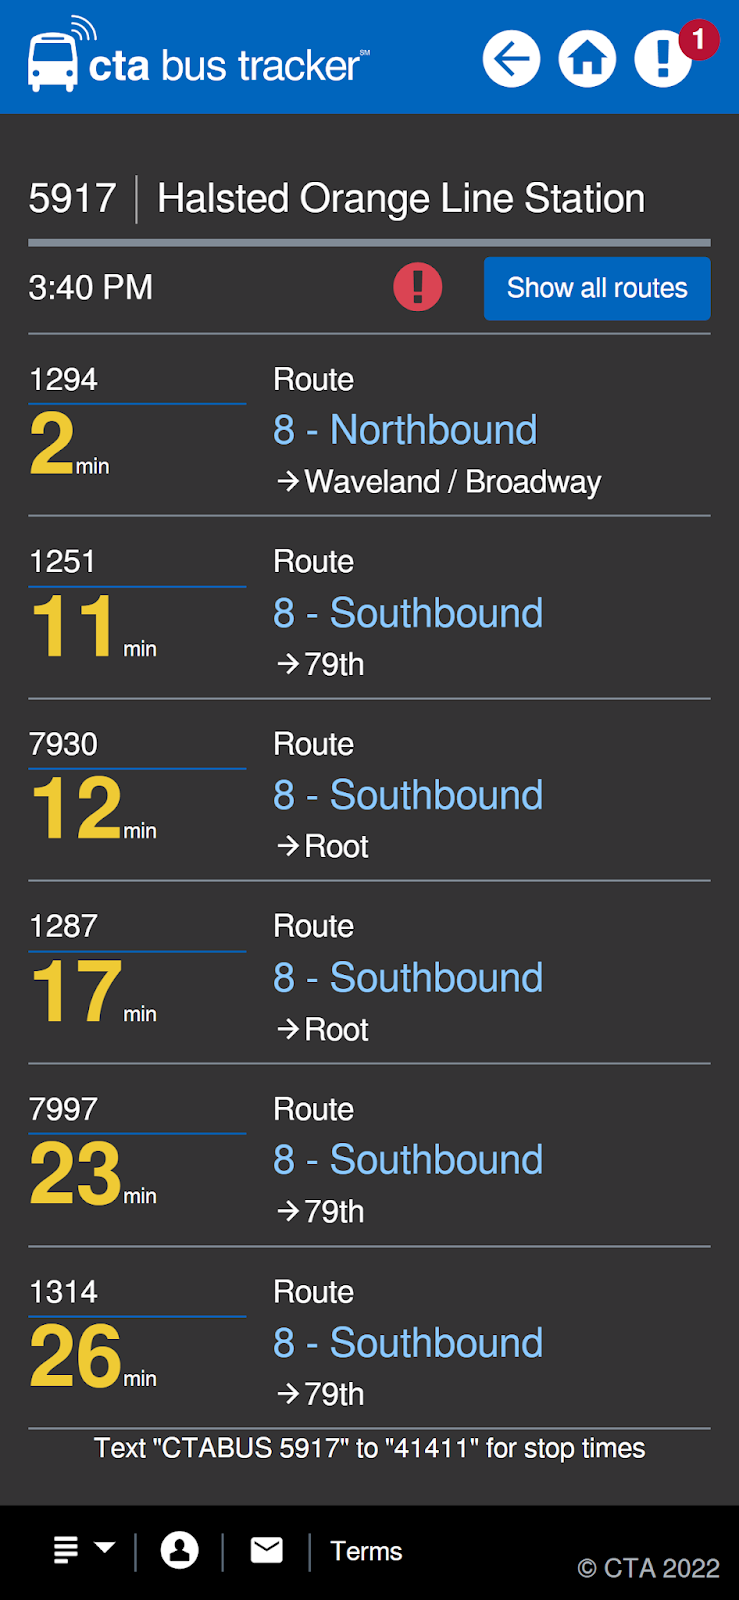
Getting data from the CTA isn't complicated. Their API is REST-based and returns JSON. You make a GET request to their stop-level endpoint and receive an array of vehicles assigned to that stop, including estimated arrival time, real-time location, and vehicle number. The response includes a field called expectedArrival that is computed server-side using traffic patterns, historical dwell times, and current speed readings.
Here's what the call looks like in practice.
GET https://services.transitchicago.com/api/1.0/getpredictions.aspx?key=YOUR_KEY&id=STATION_ID
You can find station IDs on the CTA website or by searching the stop list endpoint. The key is registered through their developer portal. Free tier allows about five hundred requests per day, which is enough for personal use or small scripts. If you're building something larger, you'll hit rate limits during morning and evening rush hours when the system gets hammered.
One thing most people miss is that the API doesn't push data. You have to poll. There's no WebSocket or webhook option. I built a cron job that queries every thirty seconds and caches results locally. Without the cache you burn through your rate limit in about four minutes during peak hours. With the cache running at that interval, my daily usage stays around two thousand calls, well within the free tier.
The estimated arrival numbers are generally accurate within a two-minute window during normal conditions. During snow events, major accidents, or when multiple buses end up bunched together the predictions degrade significantly. I noticed this firsthand on a January night when a blizzard caused three buses on the Jackson Park branch to merge into a single convoy. The tracker showed arrivals every ninety seconds for twelve minutes straight. Nothing arrived. The system was reporting individual GPS positions that hadn't been logically de-bounced yet. CTA patched the bunched-bus behavior about six months later, but it still happens occasionally.
If you want the raw feed without polling the public endpoint, you can scrape the underlying GTFS-realtime stream the operations team uses internally. It's a Protocol Buffers message that contains vehicle position updates for every bus in the fleet simultaneously. I wrote a small protobuf decoder that reads from the public mirror of that stream and produces readable JSON. It's faster than the REST API because it gives you all vehicles in one request instead of one per stop. The tradeoff is that the message is binary and the schema changes without notice. Last time they updated it, they added a new confidence scoring field that broke my decoder for three days until I found the documentation update buried in their changelog.
For most people the REST API is fine. Install a browser extension like Postman or just use curl in a script. Parse the JSON with Python or Node. The arrival estimates come back in epoch milliseconds, so you'll need to convert them. Here's a minimal example in Python:
import requests
res = requests.get("https://services.transitchicago.com/api/1.0/getpredictions.aspx?key=KEY&id=12345")
for stop in res.json()["stop"]:
print(stop["title"], stop["predictedArrivals"])
That's about all it takes. The real complexity shows up when you're trying to handle edge cases: stops that share IDs across different modes, duplicate predictions when a bus is assigned to multiple nearby stops, and the occasional server response that returns empty arrays with no error code. The last one usually means the stop ID is wrong or the service has temporarily dropped that line from the live feed.
People ask me whether this technology is actually transformative or just a nice-to-have. From where I sit, it's somewhere in between. It doesn't reduce wait times or add capacity. What it does is shift information asymmetry away from the transit authority and toward the rider. Before real-time trackers, you stood at a stop and guessed. Now you know whether the next bus is three minutes away or twenty. That changes behavior. People wait indoors instead of on the platform. They time their walks to the stop differently. They miss fewer connections because they can reroute mid-trip when a bus is running late.
The data also helps the agency itself. Operations dispatchers use the same backend to spot delays before riders do. When a bus stops moving for more than four minutes past its scheduled time, the system flags it automatically. I've seen that trigger crew dispatch in under ninety seconds during normal operations. During the 2024 transit strike negotiations, the tracking system was one of the few things that kept working because it ran on infrastructure separate from the scheduling engine.
If you're building something on top of this, don't assume the data is perfect. Validate arrival predictions against actual timestamps when you can. Cache aggressively. Handle empty responses gracefully. And don't rely on the system during winter months without a fallback, because degraded predictions are worse than no predictions if users trust them blindly.
Common Pitfalls When Working With Real-Time Transit Data
The first mistake I see people make is treating the expected arrival time as a hard value. It's an estimate with uncertainty built in. The API doesn't expose the confidence interval, but from observation the error margin is roughly plus or minus two minutes under good conditions and plus or minus six to eight minutes during disruptions. Build your UI to show that range, or users will complain when the bus doesn't arrive exactly when promised.
The second mistake is not handling vehicle ID changes. A bus might be reported as unit 4127 at one moment and then 4127 becomes 4098 due to a swap at the yard. If you're tracking a specific vehicle across routes, you'll see it disappear and reappear as a different ID. The system doesn't maintain persistent vehicle identifiers across shifts.
The third mistake is ignoring the vehicle direction field. Some stops serve both outbound and inbound buses. The API distinguishes them with a direction code, but if you're filtering by stop ID alone you'll get both directions mixed together. This is especially confusing on crosstown routes where the "direction" naming is ambiguous.
Rate limiting is another thing that bites people. The public endpoint throttles at roughly one request per second per key. If you're polling multiple stops simultaneously you'll get 429 errors. Exponential backoff with a jitter factor is the standard fix. I use a base delay of two seconds that doubles on each consecutive failure, capped at thirty seconds, with a random factor between zero and one added to prevent thundering herd behavior when many clients recover simultaneously.
What the Future Looks Like
CTA has been working on AVL system upgrades for several years. The current GPS transponders are being replaced with next-generation devices that include door open/close detection, passenger counts, and more frequent position reporting during stops. The data pipeline is also being migrated from legacy SOAP services to a modern REST and GraphQL layer. This means better error handling, structured metadata, and potentially push-based delivery in the future.
Until that rollout completes, the existing API is stable and functional. It's not elegant, but it works. I've been using it for personal projects since 2019 and it has never gone down for more than a few hours during any outage I've tracked. The reliability is decent for a public transit system serving two million daily riders.
If you're interested in exploring the data further, the CTA publishes static GTFS feeds that cover every stop and schedule on paper. Combining the static schedule with the real-time predictions gives you a baseline for detecting when the system is deviating from plan. I built a simple delay detection script that compares predicted arrival against scheduled arrival and logs any variance over five minutes. Running it hourly took me about two hours to write and fifty lines of code. The output is a CSV of delayed trips that I use to validate whether the tracker is telling the truth or if the delay is real.
Most people never look past the shiny map interface. The infrastructure beneath it is unglamorous but functional, and understanding how it works makes you a better consumer of the data whether you're a casual rider or a developer building the next transit app.