The Actual Process Behind Converting Video to Audio
Most people think extracting audio from video is just pressing a button. It is not, and if you skip understanding what happens under the hood, you will end up with files that are either too small in bitrate or completely out of sync. When you feed a video into a converter, the software reads the container first — MP4, MOV, MKV, whatever it is — then locates the audio stream inside it. That audio stream might be AAC, MP3, FLAC, or something less common like AC3 or Opus. The converter's next job is either to copy that stream directly without re-encoding, or to decode and re-encode it into whatever format you requested. Copying is instant and preserves quality. Re-encoding takes time and introduces generation loss, even with modern codecs like Opus or AAC at high bitrates.
Transform Video To Audio The Fastest Way To Convert Visual Content Into Speech A Stepbystep Guide
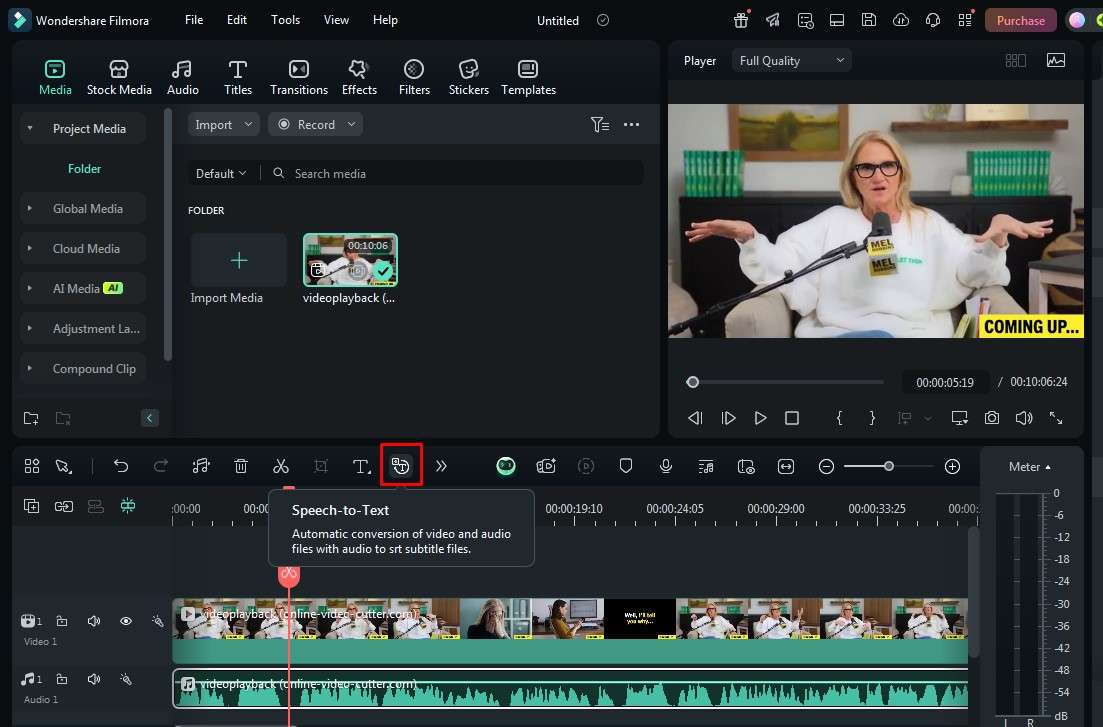
Here is how I actually do it in practice, not the version people copy-paste from somewhere else. The first step is isolating the source file on a fast drive. There is a reason for this. If your video is sitting on a slow HDD or a network share, the converter spends more time reading than processing. Move it to an SSD first. It takes ten seconds and saves you minutes later. Open your conversion tool and load the video. Do not start by hitting convert. Check the stream info panel. In FFmpeg-based tools you would use something like ffprobe -i video.mp4 to see exactly what is in there. I spent an hour once trying to convert a 4K drone video and kept getting audio that was two seconds out of sync. The problem turned out to be a custom muxing order — the audio track was placed after the video track in the container, and the tool assumed default ordering. The workaround was forcing the tool to read streams by index number rather than by name, which took about thirty seconds to fix.
Once you know what you are working with, select your output format. For speech content — voiceovers, podcasts, audiobooks — mono AAC at 128 kbps or mono Opus at 96 kbps is more than sufficient and produces significantly smaller files than stereo at higher bitrates. Stereo adds nothing to speech and just wastes space. I learned this the hard way when a client complained about slow upload times for their podcast episodes before I realized they were encoding mono narration as stereo WAV exports at 320 kbps. Cutting the bitrate in half while removing the empty second channel made no audible difference and halved the file size. Set your output folder, press convert, and wait. For a typical two-hour video with standard H.264 video and AAC audio, stream copying takes roughly three to five minutes on a modern machine. Re-encoding the audio only might take eight to fifteen minutes depending on codec and CPU load. If it is taking longer than that, something is wrong with your settings or your hardware is struggling. After conversion, always do a quick sanity check. Play the first thirty seconds and the last thirty seconds. Listen for clicks, pops, dropout, or misalignment. The middle of the file can sometimes behave differently than the edges due to how certain encoders handle keyframes and buffer states.
Get the Full Details

I also recommend converting in batches when you have multiple files. Queue them up and let the tool run through sequentially. This keeps your CPU and RAM usage steady instead of spiking every time you open a new instance. I used to open a separate window for each video and wonder why my system slowed to a crawl after the third one. One more thing that nobody mentions enough: file naming. Set your output filename pattern before you start. Automatic names like output_001.mp3 become a nightmare when you have twenty files and need to find one. Use a consistent pattern like projectname_timestamp_format.mp3 and save yourself the headache later. Not every tool handles every case. If you are working with live-action footage that has overlapping dialogue and ambient noise mixed together, simple extraction will give you exactly that mix with no separation. There is no way around that unless you start using stems or multitrack projects. Some professional workflows involve rendering separate audio stems from the original recording session, but that is a different process entirely and requires access to the source project file.
For most people dealing with standard video files, the stream-copy method through FFmpeg-based tools or dedicated converters like HandBrake, Shutter Encoder, or even built-in OS utilities is the fastest and most reliable path. Anything more complicated usually means the source file has issues that need solving before conversion anyway.