Okta + TeamHealth stack actually works until it doesn't
I spent three days last fall untangling a provisioning loop between our Okta environment and a legacy claims system that TeamHealth was integrating with. The issue wasn't the framework itself. It was a misconfigured attribute map that fed a truncated employee ID into a system that expected a padded format, causing every sync to fail silently. The fix was switching from a standard SCIM transform to a custom JavaScript rule that zero-padded the ID before the payload hit the outbound call. Took twenty minutes once I found the right place in the dashboard. Most people would have wasted weeks staring at the logs.The framework itself is straightforward when you treat it as what it is: a mapping engine wrapped around Okta's identity infrastructure, using TeamHealth's healthcare-specific extensions for compliance and data handling. It handles SSO, JIT provisioning, role-based access, and audit trails out of the box. That's the selling point. The reality is that the defaults are generic enough that half the configuration still has to be written by someone who understands how your specific applications handle authentication tokens. Start with the connector you're working with. Okta has a library of pre-built integrations, but the healthcare vertical ones — especially anything touching Patient Access Services or claims adjudication — need custom attribute profiles. Don't skip the attribute mapping step. I've seen teams push straight into activation and then spend hours debugging auth failures that came down to a missing email suffix transform or a case-sensitivity mismatch on group membership fields. Build your schema definition first. Write down every field that needs to flow between IdP and each application. Group them by type: core identity, security attributes, role assignments, tenant-specific metadata. Okta's profile editor will let you define these, but if you don't have a documented list going in, you'll be adding fields retroactively, which triggers re-syncs and often drops users from active groups in the process.
Set up your provisioning policies before you turn anything on. This is where the scalable part of the framework actually matters. Okta's batch provisioning can handle thousands of users in a single run, but if your filters are too broad, you'll be de-provisioning contractors or test accounts that should never have been in scope. Use explicit inclusion filters. I had a client who almost removed forty disabled service accounts from their production directory because the policy was set to "all users matching a department code" instead of "active employees in specific OUs." It corrected itself within a minute of catching it, but the audit trail looked like a mass layoff of ghost accounts. The health checks are worth paying attention to. Okta's diagnostics page will show you token refresh rates, sync success percentages, and any stalled assignments. When the sync success rate dips below ninety-seven percent over a twelve-hour window, something is breaking upstream. Check your source system first — HRIS exports, LDAP directory syncs, whatever feeds Okta. Most failures here aren't Okta's fault. Group-to-role assignment happens through Okta's assignment policies. Map your internal group names to application roles, not individual user accounts. This makes rotation and offboarding automatic instead of manual. TeamHealth's extensions add a layer for compliance role definitions — things like HIPAA-aware role segmentation that most teams don't bother configuring because they don't see the immediate need. You will when an auditor asks for it.
Testing should run parallel to your live environment, not after. Spin up a sandbox Okta tenant, mirror your critical applications, and run your provisioning workflows against it. The framework supports duplicate tenant configurations at no extra license cost, and you'll catch more issues in a weekend of sandbox testing than in two months of hoping production stays clean. One thing people miss: the audit log retention settings. By default, Okta keeps logs for a configurable period, but if you're in a regulated environment and need to push those logs to a SIEM, you need to configure the integration separately. The logs don't ship anywhere automatically just because you turned on audit tracking. We set up a Splunk forwarder for ours, and the initial configuration took longer than the rest of the deployment combined. Once it was running, though, we had clean visibility into every authentication event, provisioning action, and policy change going back eighteen months. The main limitation of this whole setup is that it assumes your source systems are well-maintained. If your HRIS is pushing stale or inconsistent data, Okta will just distribute that stale data faster. Garbage in, garbage scaled. I've worked with organizations where half their identity issues traced back to manual data entry in the source system — contractors added without manager approval, terminated employees whose records sat in limbo, duplicated accounts from merged departments. No framework fixes that at the source. You have to clean the upstream data or build validation rules that reject malformed entries before they enter Okta at all.
Get the Full Details
.png)
Another pain point is the custom scripting side. The JavaScript rules for transforms are powerful, but they're not typed. A missing semicolon or an incorrect property reference won't give you a compile error — it'll just cause a provisioning failure for whatever user happens to be in the queue when the rule runs. Keep your scripts small, test them individually, and don't chain more than three or four custom transforms together without writing a separate handler for each one. Readability matters when you're coming back to a rule six months later and can't remember why you nested that conditional three levels deep. If you're starting from scratch and don't have an existing Okta tenant, the free developer edition lets you build and test the full framework before committing to a paid plan. It won't handle enterprise-scale provisioning, but for mapping out your schema and validating your attribute flows, it's more than enough. The documentation is adequate. Not great, but adequate. The real knowledge is in the community forums and the support tickets you'll inevitably open.
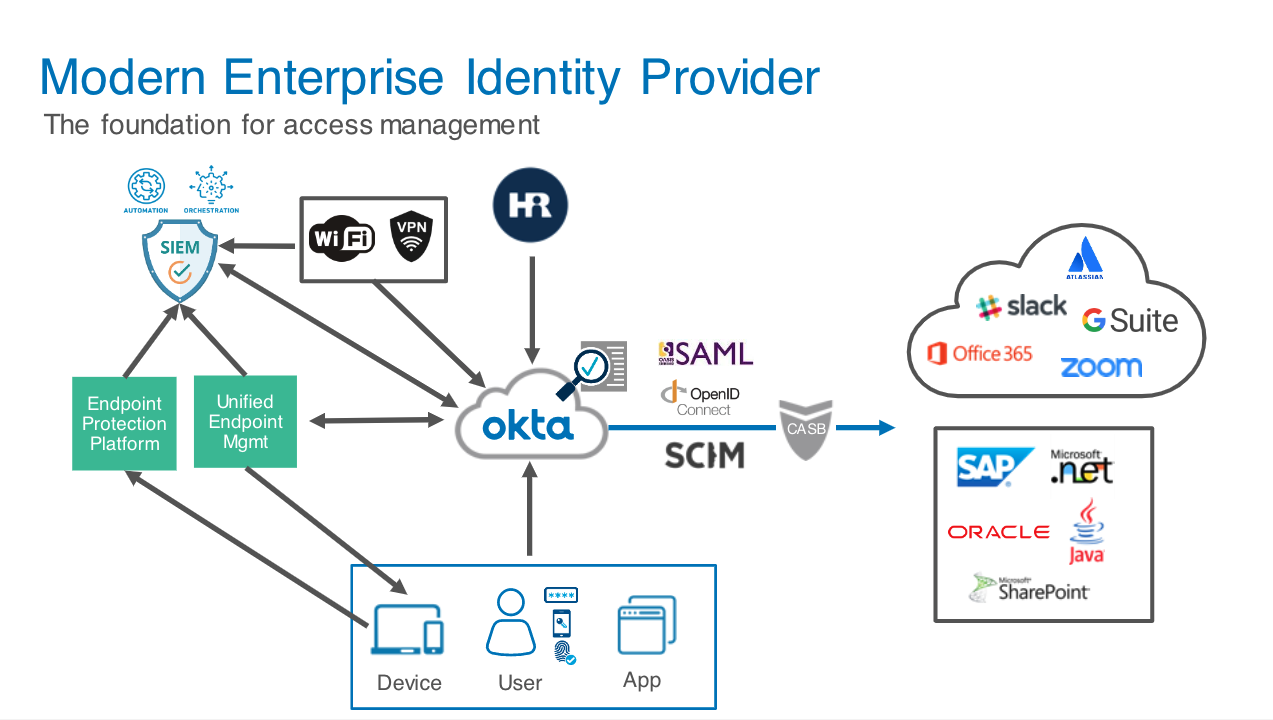
 Complete Getting Started Guide – Architecture, Configuration & Real-World Implementation.png "What is Okta? Complete Guide to Identity & Access Management (2026 ...")