Google Translate Has Gone Through A Major Shift
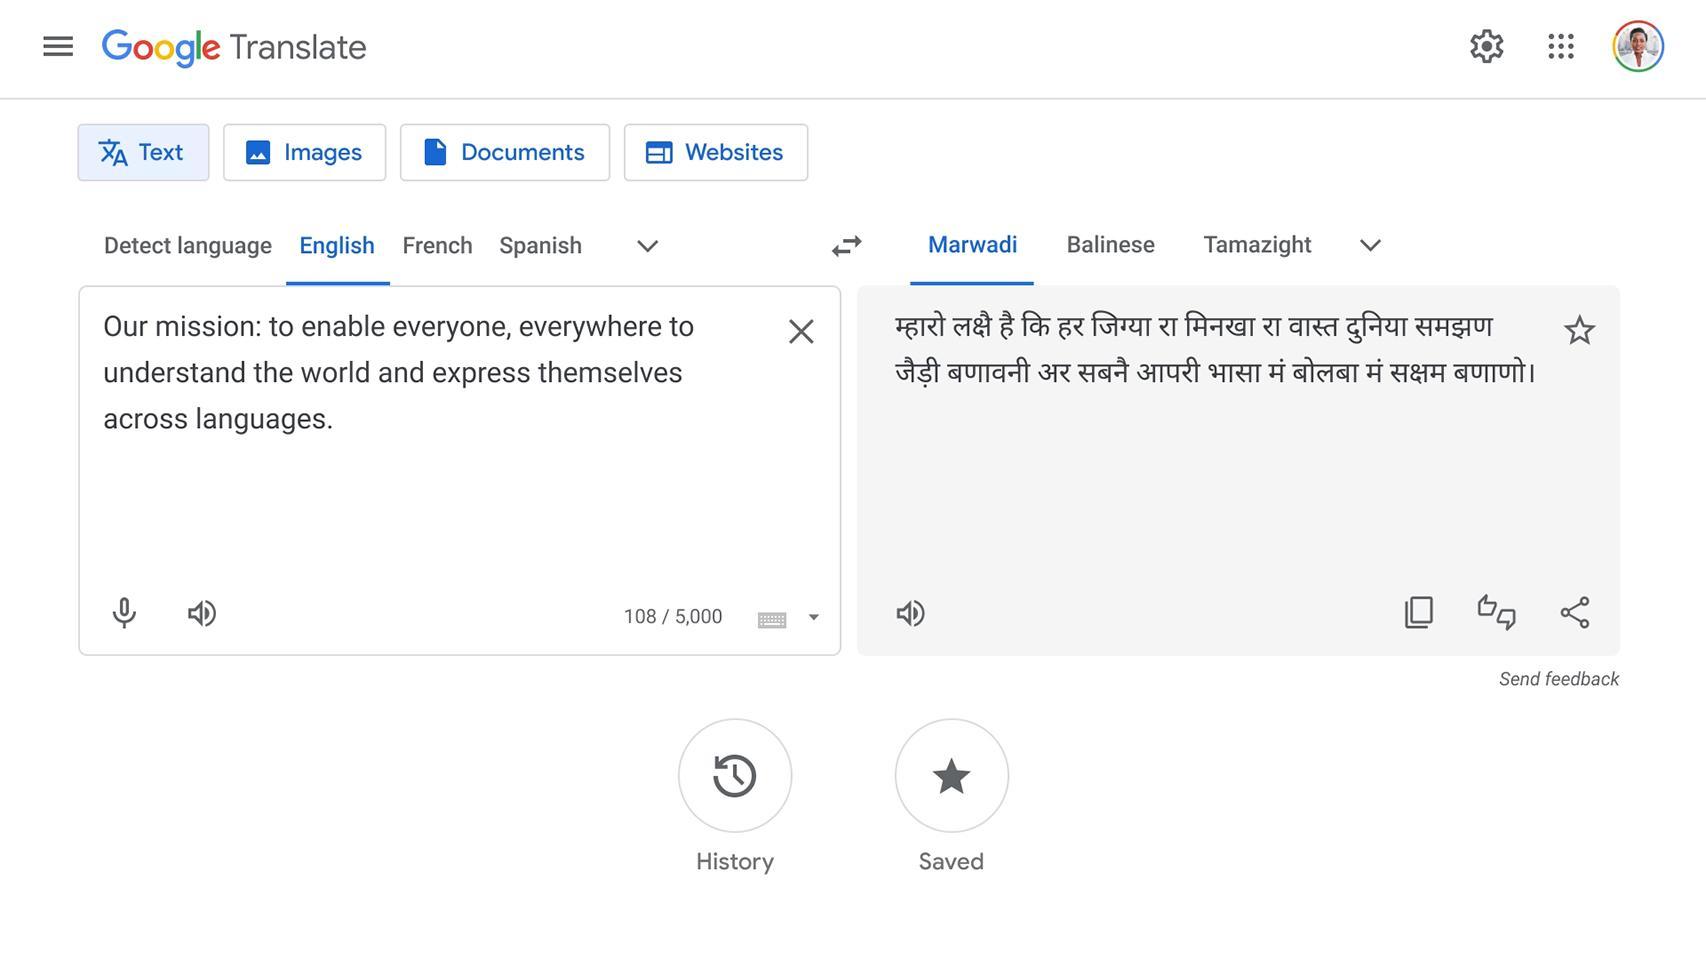
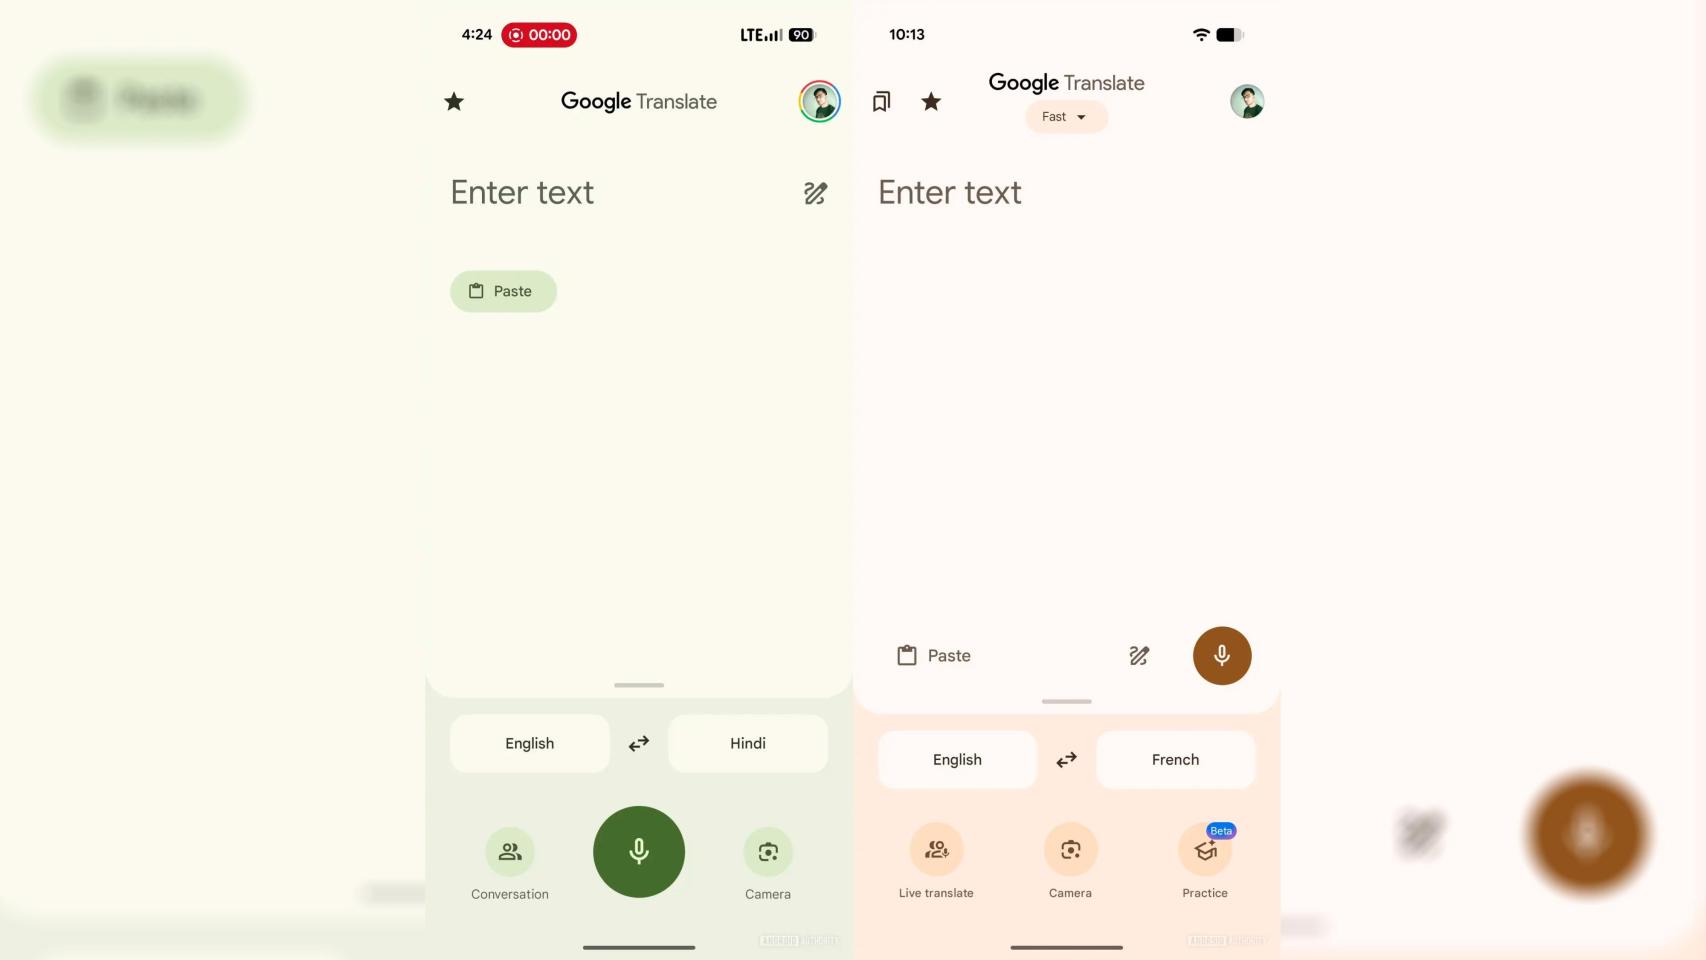
The last time I checked the Google Translate interface, it had completely overhauled how it handles long-form translation. No more waiting five seconds on a page while it churns through sentences. Now it streams results back almost instantly as you type, and the quality jumps noticeably when you stop feeding it fragments and start giving it full paragraphs. The model underneath changed to something closer to their Neural Machine Translation 3.0 stack, which means it actually understands context across sentences rather than translating each one in isolation. Most people don't realize that Google Translate now supports over 200 languages, including some lower-resource ones that used to get terrible output. I'm talking about things like Luganda, Kinyarwanda, and several indigenous American languages. The shift happened slowly but it accelerated hard around 2023-2024. What's actually changed is the way they handle zero-shot translation, which is when you try to translate between two languages that the model hasn't been explicitly trained on together. Instead of returning garbage, it now routes through a high-resource intermediary language like English or Spanish and produces usable results. Here's how I actually use it day to day. I work with technical documentation that comes in French and Portuguese, and I need to get it into English quickly before my team reviews it. I used to spend maybe twenty minutes per document running it through DeepL and then fixing the awkward phrasing. Now I paste directly into Google Translate, hit the mobile app for audio playback to catch tones and registers, and usually spend only five or six minutes cleaning up the output. The difference isn't marginal. It's the difference between doing quick translations on a tight deadline and just skipping them entirely because they take too long.
One edge case that bit me pretty hard was translating medical consent forms from Spanish to English. Google Translate got the general meaning across but completely botched the legal terminology around liability clauses. It translated "responsabilidad civil" as "civil responsibility" instead of the standard "liability" used in US legal documents. I ended up going back to the source text sentence by sentence, comparing it against the translation, and correcting every instance where the phrasing drifted from legal convention. The workaround for that was using the Google Translate API with a custom glossary file so it would lock down specific terms across the entire document. If you're working in a regulated field, don't trust the default output for anything that needs to hold up in a legal context without a human review pass.
What Actually Changed Under The Hood
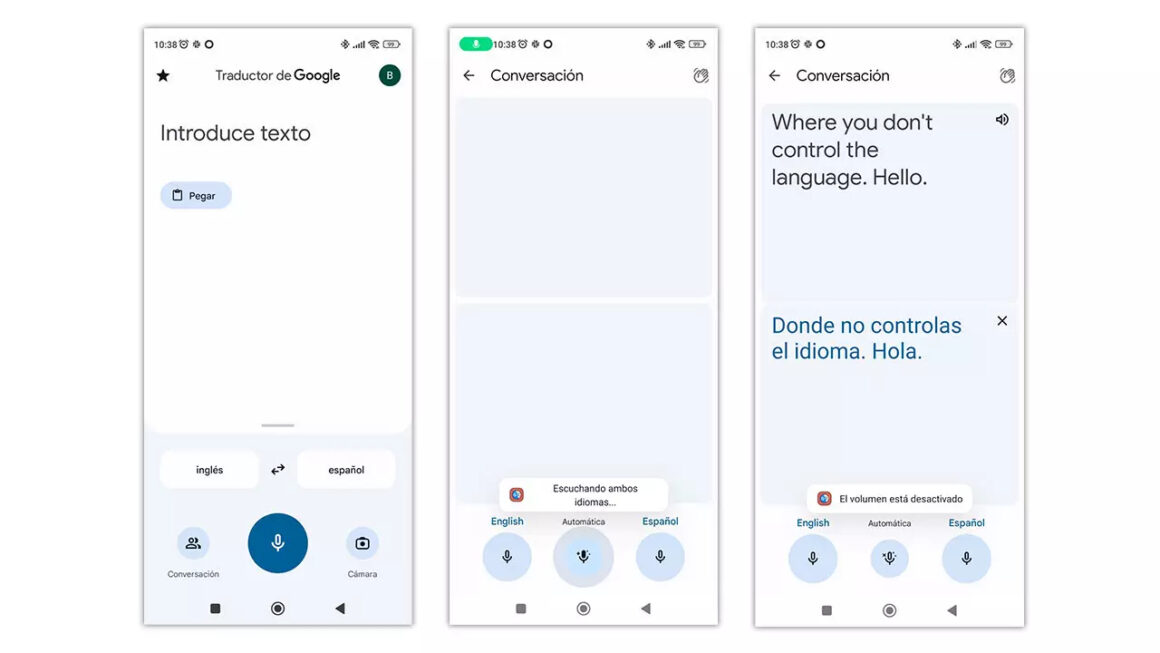
Google moved to a transformer-based architecture that pays attention to the entire input sequence rather than processing chunks independently. This means when a sentence refers back to something mentioned three sentences earlier, the model can now connect the dots. The improvement is most noticeable in languages with different word orders, like Arabic to English or Japanese to English, where the old phrase-based systems would completely scramble the structure. There's also the conversation mode, which works well for bilingual dialogue but struggles when more than two people are talking simultaneously. I tried using it in a multilingual team meeting once and the back-and-forth switching made it misattribute who said what about half the time. It kept assigning turns to the wrong speakers and the translation flow fell apart within three minutes. For one-on-one conversations it's fine, but anything group-based needs a human moderator. The offline mode on mobile deserves mention since it's useful when you're traveling and don't have reliable data. You download a language pack and it runs a quantized version of the model locally. The quality drops slightly compared to online translation because of the compression, but it's still serviceable for basic communication. I've used it at airports and in rural areas where roaming data costs are ridiculous and it gets the job done.
Get the Full Details
Pitfalls That Nobody Talks About
Google Translate tends to overconfidently produce fluent-sounding output even when it's wrong. This is called fluency bias and it's a real problem because readers tend to trust translations that read smoothly. I caught this happening with a German to English translation of a technical manual where the system rendered "druckfest" as "pressure resistant" when the actual meaning in context was "print-resistant." The sentence read perfectly fine either way but the distinction matters when you're dealing with material specifications. Another issue is dialect variation. The model defaults to a generic form of each language, which means regional variations often get flattened. Catalan gets routed through Spanish, Scottish Gaelic loses its grammatical distinctions when translated to English, and even things like Brazilian Portuguese versus European Portuguese get standardized into a midpoint that satisfies nobody. If you need precise regional adaptation, you'll need post-processing by someone who actually lives in that region. The pricing changed recently for heavy API users. The free tier gives you two million characters per month, which sounds like a lot until you're translating hundreds of pages per week. After that it's a per-character charge that adds up fast. I calculated that translating a 300-page book at average length costs around twelve dollars in API credits. For occasional use it's negligible. For volume work it eats into budgets faster than you'd expect.
How To Get Better Results Consistently
Pre-processing the source text makes a meaningful difference. Splitting run-on sentences, fixing obvious typos, and standardizing formatting before you paste anything into the translator will improve the output noticeably. I make it a habit to at least scan through my documents once before translation because cleaning up bad input takes less time than cleaning up bad output. Use the glossary feature in the API version if you're doing repeated work in a specific domain. Setting up a term database with your preferred translations for key vocabulary stops the model from guessing differently each time. It took me about an hour to set up my first glossary for legal documents but it's saved probably fifty hours since then by eliminating inconsistency across documents. For casual everyday translation, the web interface and mobile app are genuinely useful tools now. They're not perfect and they'll still trip over idioms and humor, but for practical communication tasks they've become reliable enough that I reach for them before anything else. The world is shifting toward these kinds of tools and the quality gap keeps narrowing every few months. Just keep your expectations realistic and don't let the convenience make you careless about verifying important content.