Understanding the Transfer Process
A Wu Transfer generally refers to moving assets from one account or system to another while maintaining full tracking and compliance. Asset relocation isn't just about pushing data or money — it's about making sure nothing gets lost in transit, every step is documented, and both the origin and destination systems agree on what happened. Most people gloss over the documentation part and then spend three weeks untangling mismatches. I've done enough of these to know that the difference between a clean transfer and a messy one usually comes down to preparation on day one. Not the tools. Not the speed. The prep work.
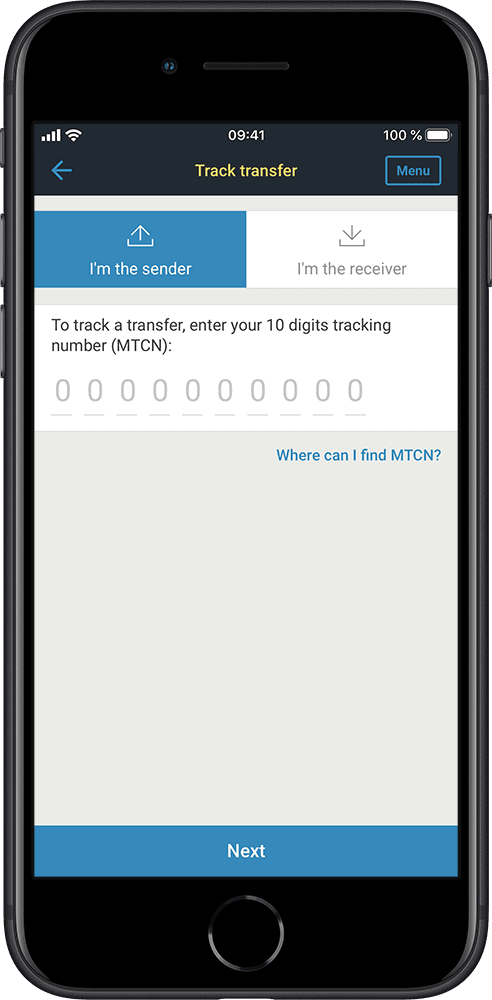
Track A Wu Transfer The Ultimate Guide To Seamless Asset Relocation
The word "seamless" gets thrown around a lot in this space, but realistically you're looking at a process that goes like this: First, you inventory everything. Every asset — whether it's financial instruments, intellectual property holdings, data records, or physical equipment with assigned values — needs to be catalogued with source identifiers before you initiate anything. I once saw a company try to relocate server infrastructure across jurisdictions without properly logging which drives were encrypted under which compliance keys. The destination side accepted the transfer, but they couldn't decrypt 40% of the data because the key metadata didn't travel with it. We spent six days rebuilding the encryption mapping from scratch. Don't skip the inventory. Next, you establish the tracking mechanism. This is where most transfers fail silently. You need a unique identifier assigned to each asset at the moment of transfer initiation, and that identifier must persist through every handoff. API logs won't cut it if you're relying solely on automated reconciliation — APIs fail, endpoints change, and audit trails get truncated. I keep a manual ledger alongside whatever digital tracking system I'm using. If the two disagree, I trust the ledger until I can prove otherwise. This has saved me twice in three years.
Setting Up the Transfer
Here's the practical breakdown of how to actually execute a Wu-style asset transfer without losing your mind: 1. Define the scope. Know exactly what you're moving and why. "All assets" is never a useful definition. Narrow it down to specific categories, values, and jurisdictions. 2. Verify compliance requirements on both ends. This sounds obvious but I've watched people initiate multi-million-dollar transfers only to find out midway that the destination jurisdiction requires a different classification for certain asset types. Re-classification mid-transfer can freeze assets for weeks depending on the system.
Get the Full Details

3. Run a test transfer with non-critical assets first. Even a small-scale test will surface format mismatches, naming convention conflicts, or permission errors that you'd otherwise discover during the actual transfer when time pressure is high. 4. Execute in waves, not all at once. Moving everything simultaneously increases the chance that a single failure cascades across the entire batch. Wave one gets tracked. Wave two gets tracked. Each wave has its own reconciliation checkpoint.
Tracking Through the Move
The tracking portion is where the Wu methodology differentiates itself from standard transfer approaches. The core principle is continuous state validation — you're not checking whether the asset arrived, you're checking whether the asset is still what you sent it as at every point in the chain. Each checkpoint requires three data points: the asset's unique identifier, its current state (in transit, held, received, reconciled), and a hash or fingerprint of the asset itself. If any of these three don't match between the sender's record and the receiver's record at any checkpoint, the transfer is flagged immediately rather than discovered after completion. I use a simple but effective trick here: instead of relying on a single tracking system, I maintain parallel records across two independent platforms. One might be your primary transfer management tool, the other a basic spreadsheet with timestamps and checksums. When they diverge, you've found a problem. When they align, you have confidence. This dual-record approach adds maybe ten minutes per asset but prevents entire batches from going undetected for days.
Common Pitfalls and How to Avoid Them
Asset transfers have a short list of recurring failure modes. The important ones: Naming convention drift. Source systems and destination systems often use different field names for identical data. A field called "owner_id" on the source might map to "custodian_reference" on the destination. Map these explicitly before initiating. Auto-mapping tools will get about 70% of this right and silently mislabel the rest. Value timestamping. For financial or valuation-sensitive assets, the moment of transfer matters. An asset's value at 11:59 PM on the source date might be materially different from its value at 12:01 AM on the destination date if markets are moving. Lock the valuation timestamp at the moment of handoff and document it.

Permissions decay. Assets often carry access permissions, licenses, or restrictions that don't automatically transfer. I learned this the hard way when transferring a portfolio of digital assets where the destination system defaulted all incoming items to public access. We had to manually reapply restricted permissions to 200+ individual records after the fact. Build permission mapping into your pre-transfer checklist. Reconciliation lag. Most tracking systems update in near-real-time, but reconciliation — the process of confirming that what was sent equals what was received — often runs on a delay. During that delay window, false positives appear. An asset might show as "missing" when it's actually just pending verification. Build a hold period into your reconciliation process before raising alerts.
When This Approach Doesn't Work
I should be straight about the limitations. A Wu-style tracked transfer is resource-intensive. The dual-tracking, wave-based execution, and checkpoint validation add roughly 30-40% overhead compared to a straightforward push-transfer. For small-scale moves with low-risk assets, that overhead may not be justified. A simple scripted transfer with post-move reconciliation will serve you fine in those cases. The method also breaks down when dealing with assets that don't have stable identifiers. Things like dynamically generated data, streaming content, or assets whose identity changes based on external factors are nearly impossible to track meaningfully through a transfer. You'll spend more time building tracking infrastructure than you'll save in error prevention. For those cases, consider a simpler audit-and-reconcile approach instead. Verify the output after transfer rather than trying to track the asset through every hop. It's less elegant but more practical when the assets themselves resist stable identification.
Final Notes
The most important thing I can tell you about asset relocation is that patience during setup pays exponential dividends during execution. The people who rush the inventory, skip the test transfer, or rely on auto-mapping are the same people who end up working weekends fixing mismatches. The people who take the time to do it methodically usually finish ahead of schedule because they don't have to backtrack. Track your identifiers. Validate at every checkpoint. Keep a secondary record. And for God's sake, run a test transfer first.