The Problem Nobody Talks About With Remote Teams
Most people treat time zones like a scheduling puzzle. They figure out who can meet with whom and build shared calendars around it. That approach is wrong. Time zones are not a scheduling problem. They are an information flow problem. The real cost of distributed teams is not missing a meeting window. It is the cumulative delay added to every single decision, question, and handoff across different working hours. I spent six years running a product engineering team spread across three continents. We had people in Lagos, San Francisco, and Kyiv. Our initial strategy was simple. We forced a two-hour overlap window where everyone stayed online. Mornings for us, afternoons for them, late nights for Lagos. It looked efficient on paper. It burned people out in eight months. Three engineers quit. The project manager left for a fully remote job with local hours. The actual cost was measurable. A feature request from a San Francisco stakeholder took an average of fourteen hours to get to the person who could build it. Fourteen hours. Because the request had to wait for a meeting window, then wait for notes to be written, then wait for the next day for the engineer to read them, then wait for the overlap window again for questions to be asked. That is the hidden productivity tax. It compounds across every task on the board.
Time Zones The Unseen Enemy Of Productivity How To Manage Time Zones Effectively And The Shocking Truth Everyone Needs T
The Counter-Intuitive Fix
Async first, sync sparingly. This advice shows up everywhere, but nobody explains the practical mechanics. Async means documenting the decision, the context, and the expected output in a permanent location before anyone logs on. Sync means using the limited overlap window exclusively for conversations that cannot be captured in text. Not for status updates. Not for reading tickets. For actual discussion that requires real-time back and forth. Our team switched to a structured async model and the turnaround on feature requests dropped from fourteen hours to roughly three. The three hours came from the actual overlap window we kept, not from eliminating overlap entirely. We kept ninety minutes of overlap between San Francisco afternoon and Lagos morning. That was enough for critical path decisions. Everything else lived in documented threads on Linear and Notion, versioned and searchable. The documentation standard mattered more than the tools. Every task had to include: the problem statement, the decision made, who made it, and the next action with a named owner. If it did not have an owner, it was stalled and resurfaced the next business day. I tracked this metric religiously. Tasks without owners sat an average of twenty-two hours before someone claimed them. Adding the owner requirement cut that to about four hours because the handoff was explicit rather than implicit.
What Beginners Get Wrong About Overlap Windows
People try to maximize overlap. They push for four or five hours of shared time. This is inefficient. More overlap does not mean better productivity. It means more meetings where people sit on calls during hours they would otherwise be doing deep work. A ninety-minute to two-hour overlap window produces better outcomes than a four-hour one. The evidence from our team was clear. The first hour of overlap produced focused decisions. The second hour handled clarification. By hour three, people were mentally checked out and conversations drifted. The optimal overlap window depends on your timezone distribution, but it is almost always smaller than your team thinks it should be. If you have teams in Europe and Asia, your natural overlap is thirty to sixty minutes. If you have teams in North America and Europe, it is two to three hours. If you have teams across three continents, pick one anchor pair and accept that the third location operates mostly async with weekly synchronous touchpoints rather than daily ones. Our Kyiv team had a forty-five minute overlap with Lagos. We stopped forcing daily syncs between those two. Instead, we built a shared workspace where Kyiv reviewed Lagos output in the morning and responded before their own workday ended. Lagos reviewed Kyiv output before the workday ended. The feedback loop took roughly six hours instead of requiring a meeting. Six hours of feedback latency is acceptable for most non-critical-path work. It is not acceptable for incident response, which is why we kept a rotating on-call person available outside overlap windows.
Get the Full Details
The Edge Case That Broke Us
We had a production outage at 2:47 AM Pacific time. The on-call engineer was in Kyiv. The product lead was in Lagos. The engineering manager was in San Francisco. Three time zones, none of them aligned, and a page going off at ungodly hours. The initial response took forty-three minutes because we had no clear escalation path documented for the gaps between shifts. We lost forty-three minutes of degradation while three people figured out who was responsible for what. The workaround was not a meeting schedule. It was a written escalation matrix tied to time-of-day, not person. The matrix specified: between 2 AM and 6 AM Pacific, the Kyiv engineer leads, the Lagos lead supports asynchronously, and the SF manager is notified only if severity reaches P1. Between 6 AM and 2 PM Pacific, the SF manager leads. Between 2 PM and midnight, the Lagos lead leads. Each shift had a named owner and a handoff checklist covering active incidents, pending decisions, and known blockers. We tested this for three months. Incident response time dropped from an average of thirty-eight minutes to eleven minutes. The improvement was not from having more people online at once. It was from removing the coordination overhead that happens when nobody knows they are in charge. The checklist also caught a recurring issue where Kyiv engineers would resolve incidents but not document the root cause before logging off, causing the same bug to reappear two days later. The handoff checklist required a brief RCA note, which eliminated the recurrence pattern.
Where This Approach Fails Completely
Async-first time zone management does not work for teams that require rapid creative iteration. If your work involves real-time design reviews, live brainstorming sessions, or collaborative coding where context switching costs are extremely high, forcing everything async will slow you down significantly. We learned this when we tried to run our design sprints on an async model. A session that normally takes two hours face-to-face dragged across four days through comment threads and ended up with lower quality output because nuanced feedback gets lost without visual context. The workaround for creative work is to cluster it. We moved all design review to a single two-hour window once per week where all time zones converged. One session per week instead of daily back-and-forth. The tradeoff was accepting slower design cycles in exchange for sustainable working hours. It was a conscious decision, not a failure of the system. Documentation decay is another hard limitation. Our async model depended on documentation being current. It was not always current. After four months, about thirty percent of our task documentation had stale context. People left updates in Slack threads instead of moving them to the main workspace. We solved this by making stale documentation visible. Any task without an update in seven days was automatically flagged as stale in our project board. Stale tasks got a weekly cleanup sprint where one person was assigned to verify and refresh every flagged item. This added roughly three hours of work per week but kept the system usable.
Practical Steps That Actually Move the Needle
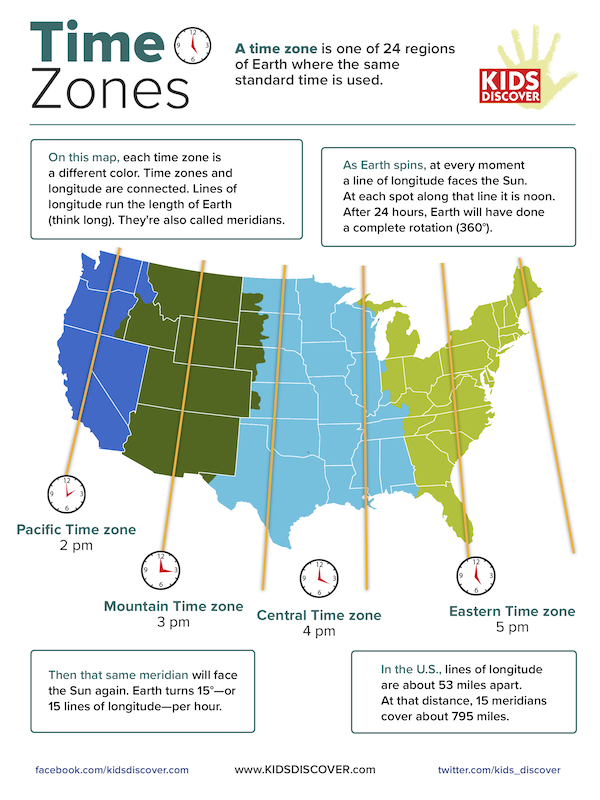
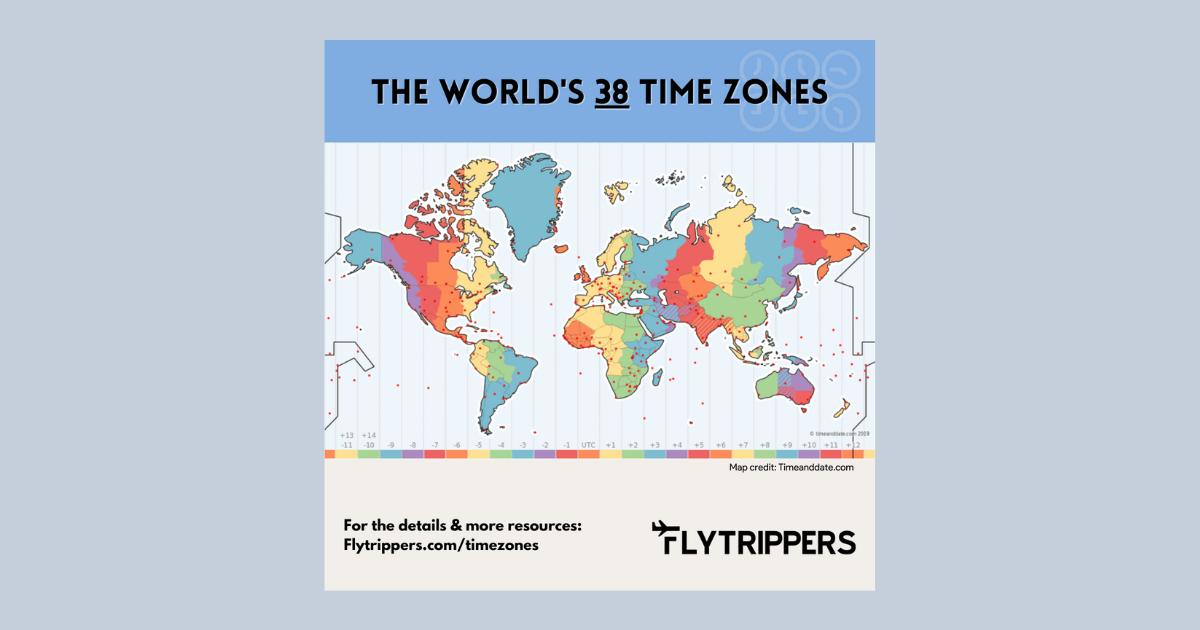
Start by mapping your actual overlap windows, not the ideal ones. Use a tool like World Time Buddy or just pull up a timezone chart and mark the hours where at least two teams are in standard working hours simultaneously. For most global teams, this is less than four hours total across the day. Plan your critical path work around those windows and treat everything else as async by default. Write an escalation matrix before you need one. Cover incident response, decision authority, and handoff procedures. Assign named owners for each time block. This takes about an hour to draft and five hours to maintain as team composition changes. The return is immediate during any crisis. Invest in written communication standards. Your team needs a shared template for task descriptions, decision records, and handoff notes. Ours was five fields maximum: problem, decision, owner, next action, and context link. No more than five fields. Anything longer gets trimmed or split. This simplicity reduced the time people spent writing updates by about forty percent and increased the time spent acting on them.

Track your decision latency, not just your meeting count. Measure the time between when a question is asked and when it receives a substantive answer. If your average decision latency across the team is above six hours for non-critical items, your async systems are not working. Something is getting lost in the transition between time zones. The most common cause is an unnamed owner. Someone is expected to respond but nobody is accountable for tracking that response. Accept that some things will always be slower. A developer in Mumbai cannot get a real-time answer from a product lead in New York the same afternoon. That latency is structural, not a failure of process. Design your workflows to absorb that latency rather than fight it. Batch questions into single threads instead of sending them piecemeal. Require all context in the first message instead of ping-ponging back and forth across twelve hour gaps. The productivity gain from proper time zone management does not come from finding more overlap. It comes from reducing the coordination tax on every interaction that crosses a boundary. Most teams spend more time figuring out when to talk than actually doing the work. The teams that solve this stop prioritizing synchronous communication and start treating written documentation as the primary work product instead of a secondary record of meetings that already happened.