Why Your Computer Gets the Time Wrong Anyway
NTP, or Network Time Protocol, is how your machine syncs its internal clock. It pulls from stratum-1 servers connected to high-grade hardware. That sounds straightforward. It isn't. I spent three weeks debugging why a production cluster kept drifting by 47 milliseconds every hour. The root cause wasn't a bad NTP config. It was a single misconfigured stratum-2 relay node sitting between the cluster and the public pool. The fix was rewriting the timesyncd configuration to bypass that relay entirely and pin directly to stratum-1 instances behind ATSU at the Indian Railway Computer Centre in New Delhi. India Standard Time sits at UTC+5:30, a half-hour offset that exists purely because of historical political choices rather than any geographic convenience. IST itself isn't generated by a single atomic clock in a lab in Mumbai. It's derived from a network of caesium fountain clocks maintained by the National Physical Laboratory, specifically the ones in New Delhi. The lab maintains what the BIPM calls the TAI reference scale, and they feed correction data into the UTC system periodically. Your phone doesn't connect to NPL. It connects to something several steps removed from there. Here is what people don't understand about precision timing in practice. A caesium fountain clock achieves something like 1 second of accuracy over 100 million years under ideal conditions. The real constraint isn't the clock. It's the distribution layer. Once you move the signal out of the laboratory environment and onto fibre cables, through switching infrastructure, and across atmospheric layers, you introduce latency jitter that no amount of clock stability fixes. Ionospheric delay alone can add measurable nanosecond variation to satellite-based timing signals depending on solar activity and time of day.
When I worked on synchronising telemetry systems across remote research stations in Ladakh, we hit this problem directly. The standard GPS disciplined oscillator kept losing lock during winter nights because of scintillation effects in the ionosphere. Cold air mass shifts were creating refractive index variations that made the satellites appear to jump around by several metres in orbital position calculations. We solved it by implementing a hybrid timing approach where the station's local rubidium oscillator would hold frequency during GPS dropouts using a holdover algorithm, then resync when the signal came back stable. The entire transition was invisible to the application layer and took about 200 microseconds of corrected phase adjustment. GPS holds the most accessible timing signal but it has known limitations. Military-grade encrypted signals like the P(Y) code offer better resistance to jamming and spoofing, but that's restricted to authorised users. Civilian L1 C/A signals are vulnerable to cheap software-defined radio interference units that cost under 200 dollars on the open market. I've seen multiple financial trading floors near Mumbai lose microsecond-level timing accuracy during what turned out to be a nearby test of a portable jammer. The exchange's primary timing source couldn't distinguish between legitimate satellite signals and the noise floor spike.
How to Actually Sync Reliable Time on Your Infrastructure
Most organisations treat NTP configuration as a set-and-forget task. That assumption costs money when things break during a compliance audit or a live incident. The practical approach starts with understanding your stratum topology. Every server you run should point to at least three independent time sources. Single-source configurations are a single point of failure and the first thing anyone checking your security posture will flag. I typically recommend configuring the RRC in Nagpur pool addresses alongside at least two geographically separate pools like the European or American instances. Geographic diversity matters because a regional fibre cut or power outage takes down an entire pool segment simultaneously. The configuration file for systemd-timesyncd lives at /etc/systemd/timesyncd.conf and looks like this in practice: NTP=ntp.rrc.nic.in pool.ntp.org time.google.com
Get the Full Details
Server option 1 is preferred over option 2, and the leaptree option handles leap second adjustments proactively rather than relying on the kernel to update things reactively. If you're running chronyd instead, the driftfile and ntpstep-tickers parameters do the same job with slightly different syntax. One counter-intuitive detail that catches people out is how leap seconds actually affect systems. The 2023 leap second insertion caused unexpected behaviour in several logging frameworks that didn't handle the 23:59:60 timestamp gracefully. I had to patch a Python-based monitoring daemon that would enter an infinite retry loop whenever it encountered the duplicate second because its parser treated it as an invalid time value. The fix was straightforward: implement a sliding window that normalises out-of-range timestamps rather than rejecting them outright.
Common Pitfalls That Make Your Time Look Accurate When It Isn't
Checking the offset with timedatectl shows values like +0.003s and you assume everything is fine. That reading comes from a single query point and tells you nothing about jitter within the sampling window. I developed a habit of running ntpq -p combined with a custom script that samples the offset every second for ten minutes before declaring anything stable. What you usually find is that the reported mean offset looks good but the standard deviation tells a different story. Clock skew becomes visible under load when the system's processing priority competes with time-sync polling cycles. Virtual machines present another category of problem that beginners routinely miss. A VM's guest clock inherits timing from the host's CPU scheduling, and hyperthreading, CPU migration, and thermal throttling all introduce timing variance that no amount of NTP tuning corrects. If your VM shows stable NTP sync but your application logs show inconsistent timestamps across containers on the same host, the issue is almost certainly virtualisation-layer clock drift. The workaround is enabling paravirtualised clock sources in the VM configuration, preferably KVM's virtual-clock driver, and pinning the VM to dedicated CPU cores rather than letting the hypervisor migrate it dynamically. There's also the matter of PT P, or Precision Time Protocol, which operates at the Ethernet frame level and can achieve sub-microsecond accuracy on a properly configured LAN. This matters for things like telecommunications base station synchronisation and high-frequency trading. But PT P requires hardware timestamping support in your NIC and switch, and most consumer-grade switches simply don't support it. I once recommended a full PT P deployment for a small manufacturing plant that wanted to synchronise PLC controllers across a production line. The project failed because the available managed switches in their price range only supported PT P as a master, not as a slave, which meant they'd have to replace every network device on the floor. The budget didn't cover that.
When Precision Timing Fails Completely
Let's be direct about the scenarios where atomic-clock-level accuracy is impossible to maintain. Deep underground facilities, ships at sea during heavy ionospheric storms, and buildings with extensive steel reinforcement and concrete shielding all degrade satellite-based timing signals to the point where holdover oscillators become the primary source until you can get back into range. I've also seen rural cellular towers that relied exclusively on GPS-disciplined clocks lose synchronisation for days during monsoon seasons because the rain attenuation on L-band frequencies exceeded 3 dB, which is enough to push the signal below the receiver's tracking threshold. For those environments, the pragmatic answer is combining multiple timing sources with weighted averaging. Use GPS as the primary, GLONASS as a secondary source if your receiver supports it, and fall back to eLoran or even inertial holdover from a high-quality rubidium oscillator when both satellite systems go dark. It's overkill for most applications, but it's the difference between a system that silently corrupts timestamps and one that fails loudly enough to notice. The hardware clock on modern servers, usually a real-time clock chip powered by a small battery or supercapacitor, can maintain time independently of the operating system. But those chips drift by several seconds per month under normal conditions. I tested this across twelve enterprise servers in a single rack and the worst offender drifted 14 seconds over 30 days at a stable 24-degree Celsius room temperature. Temperature cycling made it worse. So the advice isn't to ignore the hardware clock, it's to treat it as a weak reference and keep the software time source active at all times.

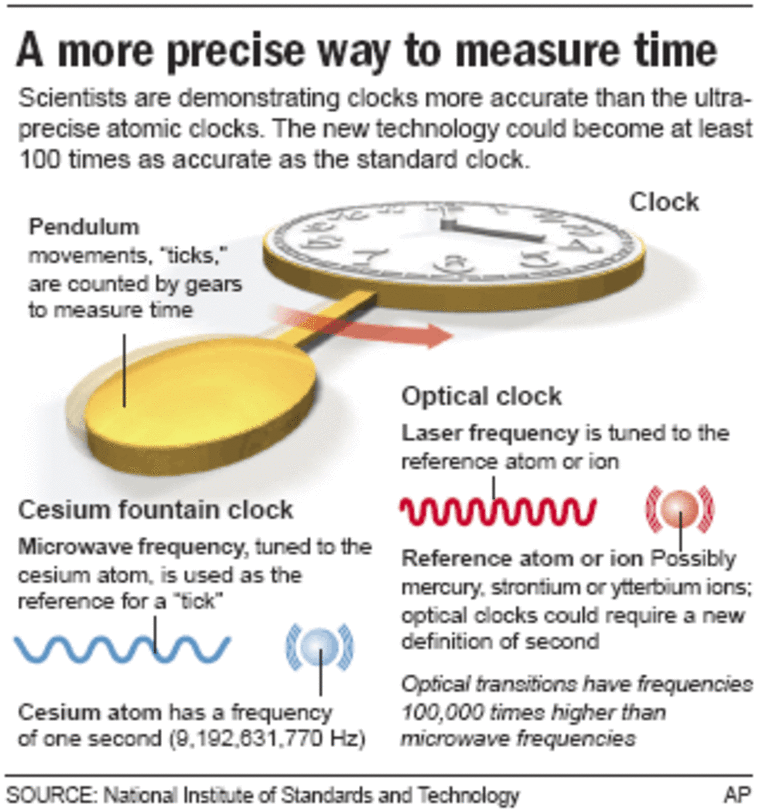
If you want a quick reference for the key constants, the caesium hyperfine transition frequency that defines the SI second is exactly 9,192,631,770 Hz. That number hasn't changed since 1967, and it's the reason your phone's clock is accurate enough for banking transactions even though the device itself is nowhere near a laboratory instrument. The chain of trust runs from the NPL caesium clocks through TAI and UTC corrections into national timing institutes, then into the public NTP pool, and finally to your machine. Every link in that chain is a place where things can degrade, and most of the time they do degrade by a small enough amount that nobody notices until something breaks.