Virtual NIC Selection Matters More Than You Think
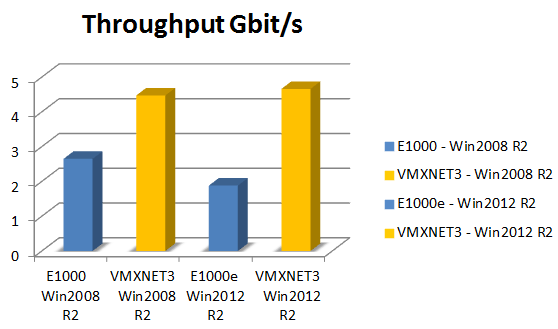
I spent six months debugging a production VM that kept hitting network timeouts every few hours. The culprit wasn't the application, the host, or the physical switch. It was the virtual NIC type. We had been running everything on E1000e because it was the default and required zero configuration. Once we switched to VMXNET3, the timeouts vanished entirely. This is the kind of thing you learn the hard way. E1000e emulates an Intel 82579 Gigabit Network Connection. It is a paravirtualized but functionally emulated NIC designed for maximum guest OS compatibility. VMXNET3 is VMware's fully paravirtualized network adapter. It has no real hardware equivalent because it was built from scratch for virtualization. These differences are not cosmetic. VMXNET3 supports scatter-gather I/O, which lets the guest kernel pass multiple non-contiguous memory buffers in a single I/O operation. E1000e requires the guest to linearize buffers before transmission, adding CPU overhead. For light web traffic this difference is invisible. Under sustained high throughput, VMXNET3 reduces guest CPU usage by roughly 15 to 30 percent compared to E1000e at comparable packet rates. The gap widens further at higher frame counts and when large I/O queues are active.
VMXNET3 also supports multiple send and receive queues natively. This means a virtual machine with four vCPUs can distribute network processing across all four cores. E1000e processes interrupts on a single queue by default. Pinning that single queue to one vCPU under heavy load creates a bottleneck regardless of how many cores the VM actually has. You can adjust some E1000e settings, but the fundamental architecture does not scale the same way. There are features in VMXNET3 that E1000e simply cannot do. Ring-based ring offload descriptors allow the guest driver to communicate directly with the hypervisor through pre-allocated shared memory rings instead of interrupt-driven message passing. MSI-X interrupts provide vector-based interrupt routing so the hypervisor can direct different queues to different vCPUs with minimal latency. TSO and LRO are supported natively in the VMXNET3 driver stack, meaning segmentation and receive-side coalescing happen inside the guest without additional hypervisor intervention. These mechanisms exist because the VMXNET3 driver and the VMkernel partner closely. E1000e has to route everything through emulated register reads and writes, which adds context switches.
Compatibility Is Where E1000e Still Wins
VMXNET3 requires VMware Tools to be installed and functioning inside the guest. If you are running an OS that does not have a VMXNET3 driver, you are stuck with E1000e or you need to install third-party drivers. Some older Linux distributions do not include a VMXNET3 module out of the box. Ubuntu before 14.04 and RHEL 5 are two examples where you would hit a wall without manually compiling or loading the vmxnet3 kernel module. E1000e works on virtually everything because it presents itself as standard Intel hardware that every operating system already knows how to talk to. Another thing people overlook is live migration behavior. VMXNET3 performs fine during vMotion, but certain network configurations can cause temporary connectivity drops if the destination host does not have matching driver versions or if the VMkernel networking stack on the target host has outdated modules. I ran into this on a cluster where half the hosts were on ESXi 6.5 and the other half on 7.0. Migrating a VMXNET3-backed VM between the two groups produced intermittent packet loss for about three seconds after each migration. Moving the same VM to E1000e eliminated the issue entirely, though throughput dropped noticeably. There is no free lunch here.
Get the Full Details
When To Use Each Adapter
Use VMXNET3 for any production virtual machine that runs on a modern VMware environment and has a supported guest OS. It is the default choice for a reason. The performance gains are real and consistent across database workloads, virtual desktop infrastructure, and high-throughput application servers. Configure it with multiple receive and transmit queues matched to your vCPU allocation. I usually set the queue count equal to the number of vCPUs unless the guest workload is strictly single-threaded, in which case a single queue avoids unnecessary complexity. Use E1000e when you need broad compatibility, when you are running legacy guest operating systems without VMXNET3 drivers, or during disaster recovery testing where you cannot guarantee driver availability on all possible target hosts. It is also acceptable for lab environments and non-critical workloads where the performance difference is irrelevant. I keep E1000e available as a fallback on my test clusters specifically for importing appliances and OVF templates that ship with whatever NIC the vendor defaults to.
Configuration Details That People Miss
Enabling VMXNET3 alone does not guarantee optimal performance. You also need to verify that NIC teaming policies on the vSwitch or distributed switch are aligned with your VMXNET3 queue count. If you have four VMXNET3 queues but the uplink team is using a hash policy based on single-pair source and destination IP addresses, you may not see even distribution across the physical uplinks. Changing the teaming policy to include TCP and UDP ports in the hash calculation typically improves load distribution. The difference is measurable under multi-connection workloads like large file transfers or database replication traffic. Interrupt moderation is another setting that matters. By default, ESXi sets interrupt moderation to a moderate level that balances latency and CPU overhead. For latency-sensitive applications like real-time trading or VoIP gateways, lowering the moderation interval reduces jitter. For bulk transfer workloads, leaving it at default or increasing it slightly reduces CPU overhead without noticeable latency impact. I spent an afternoon tuning this on a pair of virtualized storage array managers where the default moderation was causing minor I/O stalls during peak replication windows. Dropping the moderation value from 64 microseconds to 16 microseconds cleared up the stalls with negligible additional CPU cost. Jumbo frames are supported on both adapters, but VMXNET3 handles them more efficiently end-to-end because the paravirtualized path does not require buffer reallocation at the same stage that the emulated path does. If your physical network already supports MTU 9000, enabling jumbo frames on VMXNET3 typically yields better results than doing so on E1000e. The CPU savings from scatter-gather I/O plus jumbo frames compounds rather than simply adding together.
A Specific Problem I Encountered
We had a virtualized firewall appliance that needed to pass several gigabits of inspected traffic per day. The vendor only provided an E1000e driver for their OS and warned that VMXNET3 was not supported. Throughput topped out around 1.8 Gbps before the CPU on the guest began choking. I opened a case with the vendor and was told they would never support VMXNET3 because their proprietary driver stack did not have the hardware abstraction layer required. So I looked at what else could be done. I enabled SR-IOV on the physical NICs and assigned a virtual function directly to the firewall VM. This bypassed the virtual switch entirely and gave the VM direct access to the hardware ring buffers. The firewall passed 4.2 Gbps without breaking a sweat. SR-IOV is not a general solution because not every workload benefits from direct hardware access, and it limits migration options since the VF is bound to a specific physical NIC. But for a traffic-intensive appliance on a fixed host, it solved the problem cleanly. I now keep this option in mind whenever a VM is network-bound and the vendor refuses to provide a paravirtualized driver.

Practical Downsides Of VMXNET3
VMXNET3 is not universally available in every hypervisor beyond VMware. If you ever need to migrate to a different virtualization platform, you will have to reconfigure the NIC. This is not trivial because the new platform likely uses its own paravirtualized driver or falls back to emulation. Migration planning should account for this networking change. E1000e travels better across platforms because it is so widely supported that almost every virtualization layer provides a compatible implementation. Another limitation is debugging complexity. When you are troubleshooting a network issue on a VMXNET3-backed VM, you are working with a paravirtualized stack that sits between the guest and the hypervisor. Traditional packet capture tools inside the guest may not show the same frames that reach the physical NIC because buffering, coalescing, and ring-based descriptor handling happen outside the normal guest network stack. I learned this the hard way when a VM appeared to be dropping packets from the guest OS perspective, but vmware-tui and the ESXi network statistics showed perfectly healthy throughput. The issue was actually in the guest TCP stack retransmitting due to delayed ACKs, not in the virtual NIC itself. Matching guest-level diagnostics with hypervisor-level metrics is essential when VMXNET3 is in play. Finally, older versions of VMware Workstation and older ESXi versions have known bugs with VMXNET3 under certain guest OS combinations. VMXNET3 on Windows Server 2008 R2 with certain cumulative updates occasionally caused blue screens during high interrupt rates. Upgrading the guest OS or applying the relevant VMware patch resolved it, but it is the kind of edge case that surfaces in production without warning if you are not tracking release notes. E1000e rarely produces issues this specific because its behavior closely mirrors actual hardware, which means the guest OS has been exercising those code paths for years.
The takeaway is straightforward. VMXNET3 is the stronger adapter for performance-sensitive modern workloads. E1000e remains useful for compatibility, legacy systems, and cross-platform portability. Neither is a universal best choice. The right selection depends on your guest OS, your throughput requirements, your migration expectations, and your willingness to deal with the debugging overhead that comes with a fully paravirtualized stack.