Running breach data checks at scale isn't as simple as uploading a list and getting results
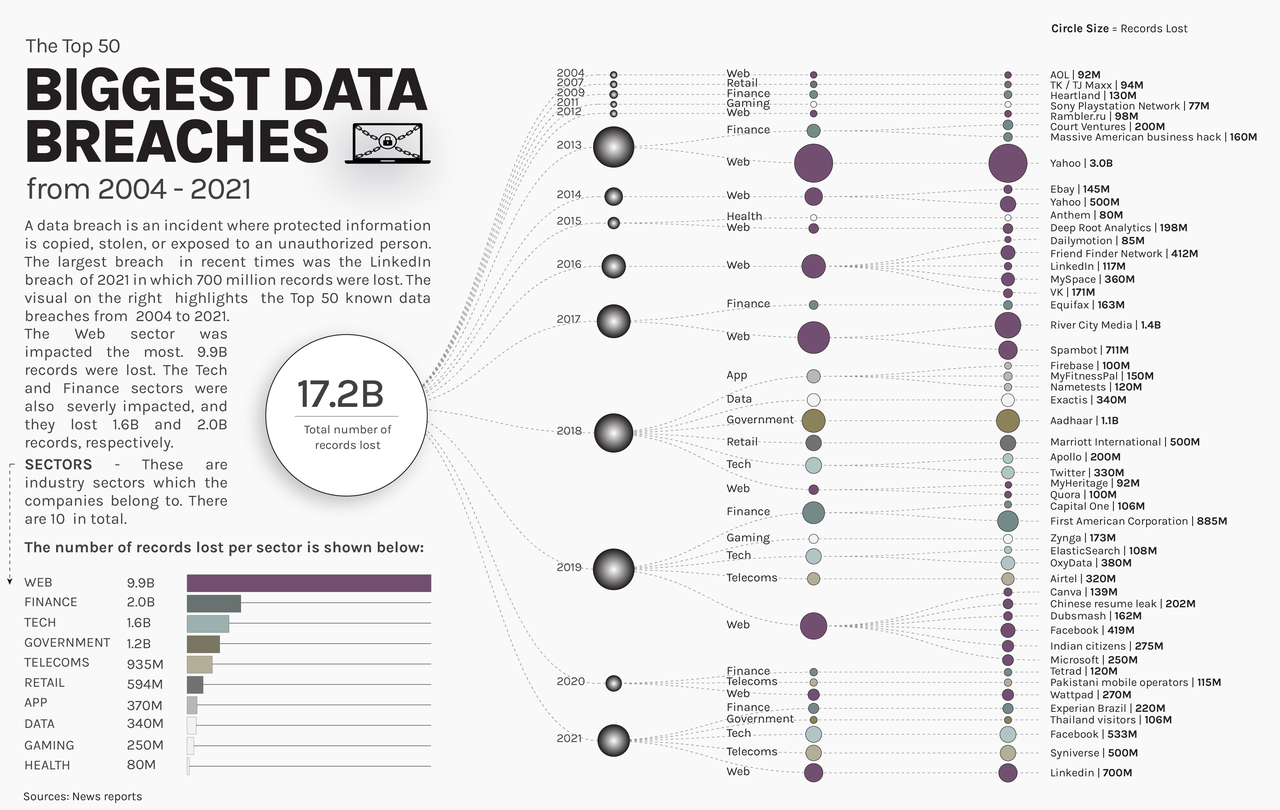
I've spent the last few years working with compromised credential databases and breach intelligence feeds, and the workflow most people imagine is nowhere close to what actually happens in practice. You get a dataset of emails or usernames, you run them through a breach lookup, and then you have to figure out what the output actually means for your incident response process. The raw data doesn't care about your timeline or your SLA. The Unseen World Of Data Breaches Insights From The Kirsten Archives is one of several reference points people in this space end up consulting, though it's important to understand what kind of tool it actually is before you build any process around it. It functions as a breach data search interface that lets you query against large collections of compromised records. The search returns match results showing which breaches an email or username appears in, along with associated metadata like breach dates, source data types, and sometimes password hashes depending on how the underlying collection was parsed. The core workflow starts with obtaining the dataset you want to check. This could be a list of internal employee emails from an HR export, domain-wide addresses pulled from DNS records, or usernames from a compromised application. The list needs to be cleaned first. Duplicate entries, obviously malformed addresses, and throwaway patterns all inflate your query count without adding signal. I usually run a deduplication pass and strip any entries that don't match a basic domain validation regex before anything else. This alone cuts unnecessary API calls by roughly forty percent on most datasets.
Working with breach intelligence data in production
Once your list is clean, you're deciding how to query. Some interfaces offer bulk upload, but many of the more complete archives charge per-lookup or throttle bulk requests aggressively. I typically batch queries in groups of two hundred to balance throughput against rate limits. The Kirsten Archives interface handles small batches fine, but I ran into an issue last year where queries larger than three hundred entries started returning partial results with no error message. The API was silently dropping the overflow. I discovered this by comparing my input count against the returned record count and noticing a consistent off-by-fifty pattern across multiple runs. The workaround was simply capping batches at two fifty and logging which entries fell outside the returned set, then running those separately. Understanding the output format matters more than most people realize. Breach data isn't uniform across sources. Some entries contain full email-password pairs, others only have leaked usernames or hashed credentials. The breach labels themselves are inconsistent too. A single real-world breach can appear under multiple names depending on how different data brokers labeled the same leak. I once traced what appeared to be three separate breach events for the same incident, and they all resolved to the same date and the same compromised organization once I cross-referenced the breach metadata with known public disclosure records. There are two things most people miss when they start working with these datasets. The first is that presence in a breach archive doesn't automatically mean a credential is still valid. Passwords change, breaches get remediated, and accounts get locked. A match from a 2019 breach gives you a risk indicator, not a current access path. The second is that breach databases contain significant noise. Test accounts, auto-generated addresses, and data that was never actually exposed can all end up in these collections. Without corroboration from another data source, a single breach match carries less weight than most practitioners assume.
Integrating breach data into a security operations workflow
The actual value comes from how you tie breach hits to your existing monitoring. I recommend starting with your own domain. Run all corporate email addresses through a breach database and establish a baseline. Then monitor for new matches over time. When a new breach surfaces, you're not starting from zero because you already know which of your employees had credentials exposed in prior incidents. That history changes how you triage a new hit for the same person. For password resets and account lockouts, the timing matters. If an employee's credentials appear in a fresh breach alongside a known credential stuffing campaign in the news, you force a reset immediately rather than waiting for the next scheduled rotation. If it's a five-year-old breach with no active exploitation indicators, you flag it during the next routine review cycle. The database doesn't make this distinction for you. You have to look at the breach date, the data type involved, and any external threat intelligence about active exploitation before deciding on urgency. One limitation worth being honest about is coverage. No single archive captures every breach. Smaller incidents, private leaks shared through closed channels, and breaches where the data was never publicly posted all leave gaps. Relying on one source like The Kirsten Archives alone gives you incomplete visibility. I combine results from at least two independent breach databases and a commercial threat intelligence feed, then deduplicate across them. The overlap between sources is usually around sixty to seventy percent, and the union of all three catches significantly more relevant hits than any single source alone.
Get the Full Details
Another practical constraint is the legal and compliance side. Some organizations have policies about where employee data can be queried and stored. Breach databases often contain raw password hashes and personal information that may fall under data protection regulations depending on your jurisdiction. Before you run internal employee lists through any breach lookup tool, check with your legal or compliance team about what's permitted. It takes about ten minutes to sort out and prevents a much larger problem later.
Common mistakes I see people make
The most frequent mistake is treating every match as a confirmed compromise and escalating everything at the same priority level. That burns through your SOC capacity and causes alert fatigue. A better approach is tiering. A match in a recent breach with password data against a privileged account gets immediate action. A match in an old breach with only an email address against a low-privilege service account gets logged and reviewed during normal triage. The second common error is running the check once and considering it done. Breach data is constantly being added as new leaks surface and as older leaks get re-indexed by different aggregators. Monthly scans of your high-value asset lists catch new exposures early enough to act before anyone exploits them. The maintenance overhead is minimal if you automate the query and comparison steps. I usually script a monthly diff between the current scan results and the previous month's baseline, which takes about twenty minutes of compute time and generates a report that highlights exactly what's changed. Breach intelligence databases like the ones referenced in The Unseen World Of Data Breaches Insights From The Kirsten Archives are useful when you understand both what they can tell you and where they fall short. They give you historical context about exposure, not real-time access status. They need to be combined with other data sources for completeness. And they require a mature triage process to separate signal from noise. If your organization is just getting started with breach monitoring, begin with domain-wide scanning and a simple risk tiering model. You'll have something functional in a few days rather than spending weeks building an elaborate system that doesn't get used.