Automated Security Testing Feels Right Until It Is Completely Wrong
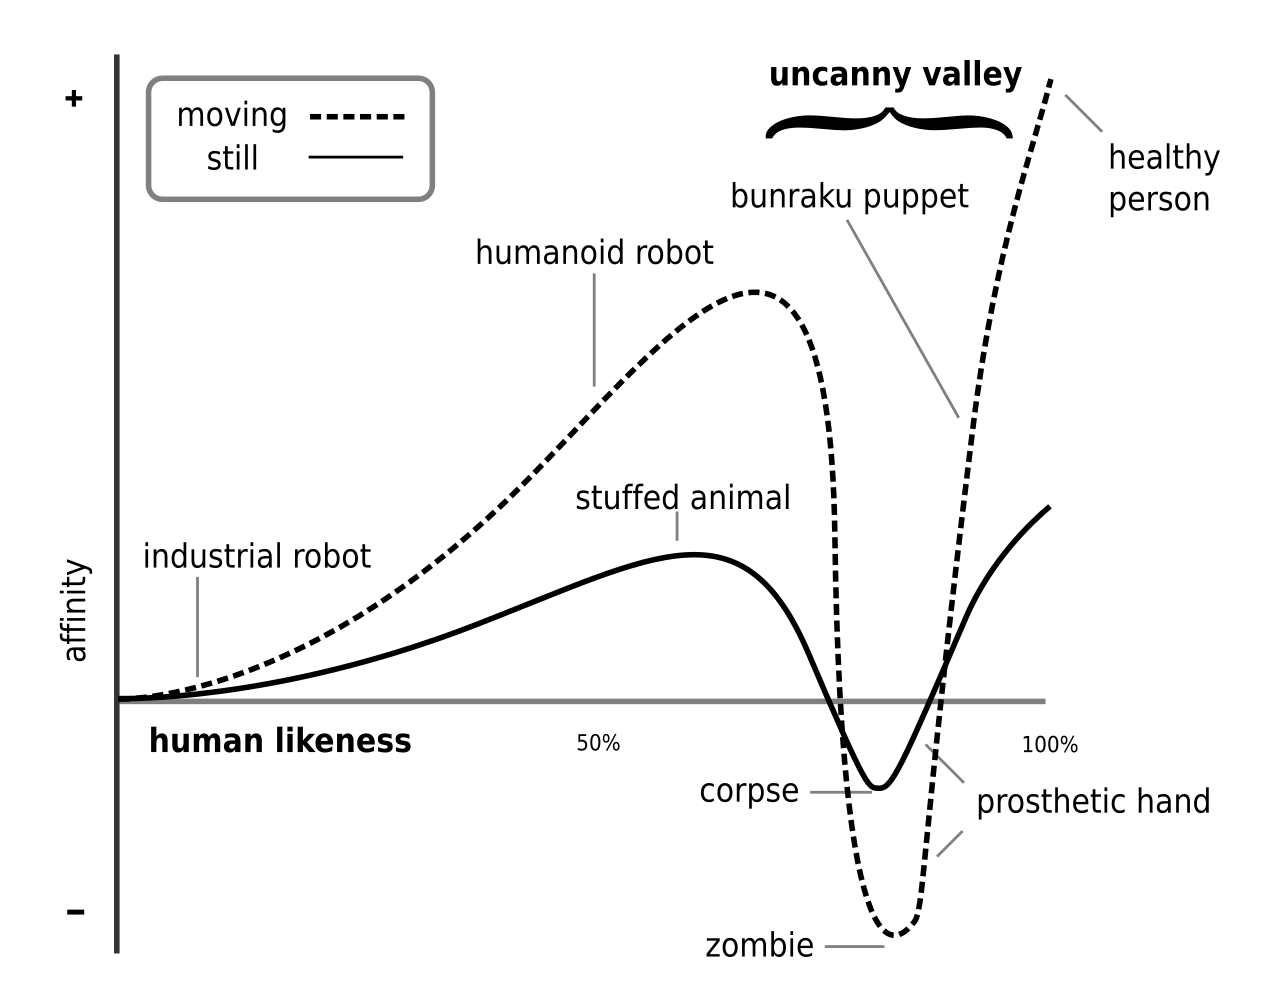
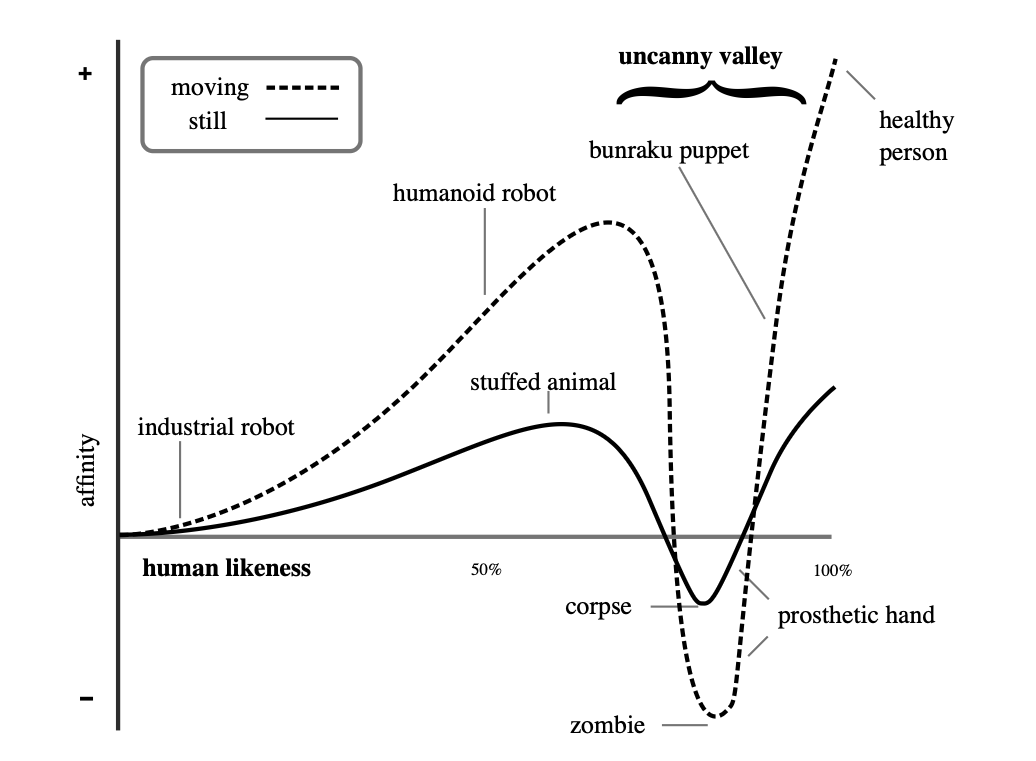
I spent three days reviewing a penetration test report for a mid-sized fintech company last year. The report looked immaculate — formatted like an OSCP submission, complete with exploit chains, proof-of-concept screenshots, and risk scores for every finding. Two months later, a researcher disclosed a direct database exfiltration path that the entire engagement had somehow missed. The tools ran green across the board. The report passed QA. The vulnerability sat there the whole time, hiding behind a parameterized API endpoint that every scanner treated as a non-issue. This is what I mean by the uncanny valley of cybersecurity assessment. It is not about bad tools. It is about tools that are good enough to produce results that look trustworthy while leaving systematic gaps. Organizations adopt these workflows because the outputs feel professional. They stop looking closely enough.
The Uncanny Valley Of Cybersecurity Exploring Oscpse And Tsesc In Industries And Websites
Let us talk about what is actually happening under the hood. OSCPSE, which I use to refer to the expanded operational methodology that builds out from the baseline OSCP framework — things like sustained post-exploitation persistence tracking, lateral movement chain documentation, and custom exploitation beyond the typical lab scenarios — sits in that valley. It produces work that looks thorough by any surface-level rubric. TSESC, the threat-simulated evaluation and security certification process I have seen teams use internally, takes a different angle. It attempts to model attacker behavior at the infrastructure level before an actual breach occurs, running red-team style engagements against live or near-live environments. Both approaches share the same structural weakness. They optimize for completeness of output rather than completeness of coverage. A well-executed OSCPSE-style engagement will thoroughly document everything it finds within its chosen scope. It will not necessarily look outside that scope. A TSESC-style evaluation simulates specific threat vectors based on predefined scenarios. If the scenario list does not include a particular attack path, that path does not get tested. The report still looks comprehensive. It is not. I ran into this explicitly with a healthcare client who used an automated TSESC pipeline for their quarterly assessments. The pipeline checked every box on their compliance matrix. During a routine follow-up, I found that the orchestration layer behind their patient records API had an unpatched serialization flaw. It was not in any of the standard vulnerability feeds the pipeline pulled from. It was not covered by their threat model because no one had modeled an deserialization attack against that specific component in over a year. The engagement had flagged forty-seven findings, all accurate. The one that mattered was completely absent.
How The Gap Actually Forms In Practice
Automation creates the illusion of coverage through velocity. Scanners move fast. They generate PDFs with executive summaries and appendices full of CVE references. The visual weight of that output functions as proof of rigor. Most security teams accept it as such without stress-testing the methodology behind it. Here is a concrete example. A SaaS provider runs a weekly OSCPSE-style scan against their web application. The tool suite includes Burp Suite Professional, Nmap, and a custom Python-based enumeration script. It discovers SQL injection on a login endpoint, chains it to authentication bypass, and documents the full attack path. The finding gets a critical severity rating. The team remediates it within forty-eight hours. The next week, the same scan runs again. It returns clean. Two weeks later, the application moves to a new subdomain behind a WAF rule that blocks the original injection vector. The scanner never checks the new subdomain because it was not in the target list. It also never reports on the new WAF rule as a potential misconfiguration because that falls outside the scan's defined methodology. The application now has a publicly accessible admin panel with no authentication. The scan output has not changed in structure or appearance. It just does not reflect the current state of the environment. The second issue is more insidious. It appears in reporting rather than in the testing itself. Tools produce findings at consistent severity levels. A business logic vulnerability gets the same visual treatment as a remote code execution flaw. Readers absorb the formatting and assume equivalent risk. In reality, the logical flaw might allow mass account enumeration while the RCE is contained behind a network segmentation boundary that the tool did not verify. The report does not distinguish between these cases in any meaningful way unless the tester manually adds context that most automated workflows do not capture.
Get the Full Details
What Actually Works When You Need To Bridge The Gap
I do not recommend abandoning automated assessment entirely. That is impractical for most organizations at scale. What I recommend is treating automation as a baseline layer and building manual validation on top of it. Here is the structure I use. First, separate your scope definition from your scope validation. Define the target list explicitly before any tool runs. Then, after the initial scan completes, spend time mapping the discovered attack surface against what you know should exist. If a client has a payment processing microservice and the scan returns zero results from the domain hosting it, that is not a clean result. That is a missing data point. Verify the domain resolves. Check DNS records. Walk the application manually. Run the scanner against it one more time with an expanded parameter set. This step usually takes between two and four hours per engagement and catches the subset of findings that automation quietly drops. Second, do not rely on severity ratings alone. Add a coverage matrix to every report. List each tested category — authentication, authorization, input validation, cryptographic implementation, session management, infrastructure exposure — and mark which ones were actively tested, which were skipped with justification, and which produced no results. This forces honest reporting and makes it obvious when a category was never actually evaluated. I started doing this after a client pointed out that their most expensive OSCPSE contractor had marked fourteen categories as "cleared" when six of them had only been tested via automated heuristics with zero manual verification.
Third, treat TSESC threat models as living documents. I have seen teams finalize a threat model, run an evaluation against it, and then file it away for six months. During that gap, the application architecture changes, new dependencies are added, third-party integrations shift. The threat model no longer matches the environment. Revisit it before every evaluation cycle. Update the adversary personas. Adjust the attack trees. If your last TSESC run did not include container escape as a vector and the production environment now runs workloads in Kubernetes, the evaluation is already behind. Fourth, maintain an independent challenge track alongside your automated assessments. Pick one finding from each scan cycle and attempt to reproduce or extend it manually using techniques that fall outside the tool's methodology. This does not have to be exhaustive. Five to ten hours per quarter dedicated to manual challenge work is enough to catch systematic blind spots. In my experience, this approach reveals issues roughly once per quarter that would otherwise go unreported for six to twelve months.
Where These Methods Fail Completely
There are scenarios where neither OSCPSE-style engagement nor TSESC evaluation will give you reliable results, and it helps to know them upfront. Supply chain compromises are the primary example. If an attacker injects malicious code into a dependency that your scanners do not inspect at the source-code level, neither methodology surfaces it. You need SBOM analysis, software composition analysis, and runtime behavior monitoring for that category. Automated vulnerability scanning will show you an outdated library version and call it a finding. It will not show you that the library has been poisoned with a backdoor. Zero-day targeting by determined actors is the second example. TSESC evaluates against known or modeled threat patterns. An actor using an undisclosed vulnerability in a component you did not flag in your threat model operates outside the evaluation frame. The assessment will come back clean while the exploit runs in production. This is why continuous monitoring and bug bounty programs exist alongside periodic assessments, not as replacements but as necessary complements. A third failure mode is environment drift. I have seen engagements where the testing environment was provisioned freshly for the assessment. The production environment diverged six months earlier due to configuration changes, deprecated service migrations, or undocumented patching. The assessment results were technically accurate for the tested environment and practically useless for the one that handled real traffic. Always verify that the assessment target matches production configuration. Diff the settings. Check the deployment manifests. This takes approximately twenty minutes and prevents an entire class of false-negative results.

A Practical Workflow That Does Not Waste Time
If you are running assessments in-house or managing an external team, here is the sequence I find functional without turning evaluation into a three-month project. Begin with reconnaissance and scope finalization. Document every domain, subdomain, IP range, and API endpoint. Record the current deployment version and any recent changes. This phase takes one to two hours for a standard web application environment. Run the automated scan. Capture all output. Do not adjust parameters mid-scan to chase better-looking results. Record what you actually tested and what the tool returned. Most full scans against a medium-complexity application complete within four to eight hours depending on network latency and endpoint count.
Map findings to your coverage matrix. Identify categories with no results or results that rely solely on heuristic detection. Flag them for manual follow-up. Execute manual validation on flagged areas. Use Burp Suite for deeper application-layer testing. Write small scripts for edge cases the scanner cannot handle. Expect this to take four to twelve hours depending on scope complexity. Conduct a challenge run. Pick two or three findings and attempt to extend or reproduce them using non-standard techniques. Document what works and what does not. This usually requires three to five hours.
Compile the final report with the coverage matrix included. Exclude any category from the "cleared" section if it lacks manual verification. Provide remediation guidance ranked by actual exploitation likelihood, not just CVSS score. This reporting step typically takes two to four hours. The total engagement for a standard web application comes to roughly twenty-five to thirty-five hours of focused work. It is longer than a fully automated scan but significantly shorter than a traditional manual penetration test that runs for weeks. More importantly, the findings it produces tend to hold up under scrutiny because they survived both automated detection and manual verification. The uncanny valley exists because the output looks right without being right. The remedy is not to stop producing professional-looking reports. It is to make the reports honest about what was actually tested and what was assumed. Once you start marking the gaps explicitly, the gap stops functioning as a hidden risk and starts functioning as a known limitation that you can plan around. That shift changes how security teams allocate their budget and how leadership interprets assessment results. It is not dramatic. It just makes the work slightly more accurate than it was before.