How to Make Mr Incredible Transformation Memes
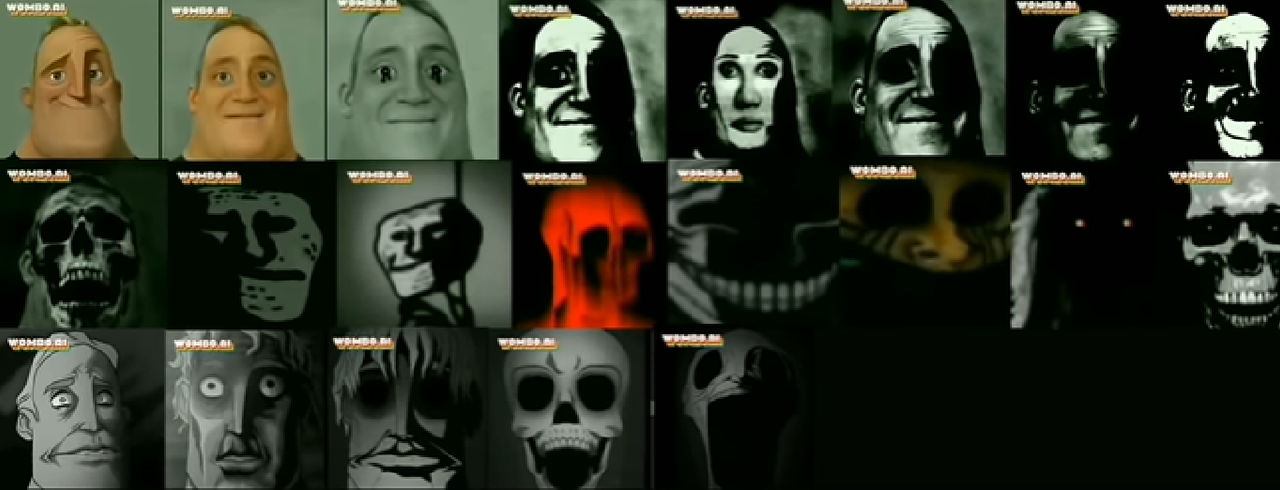
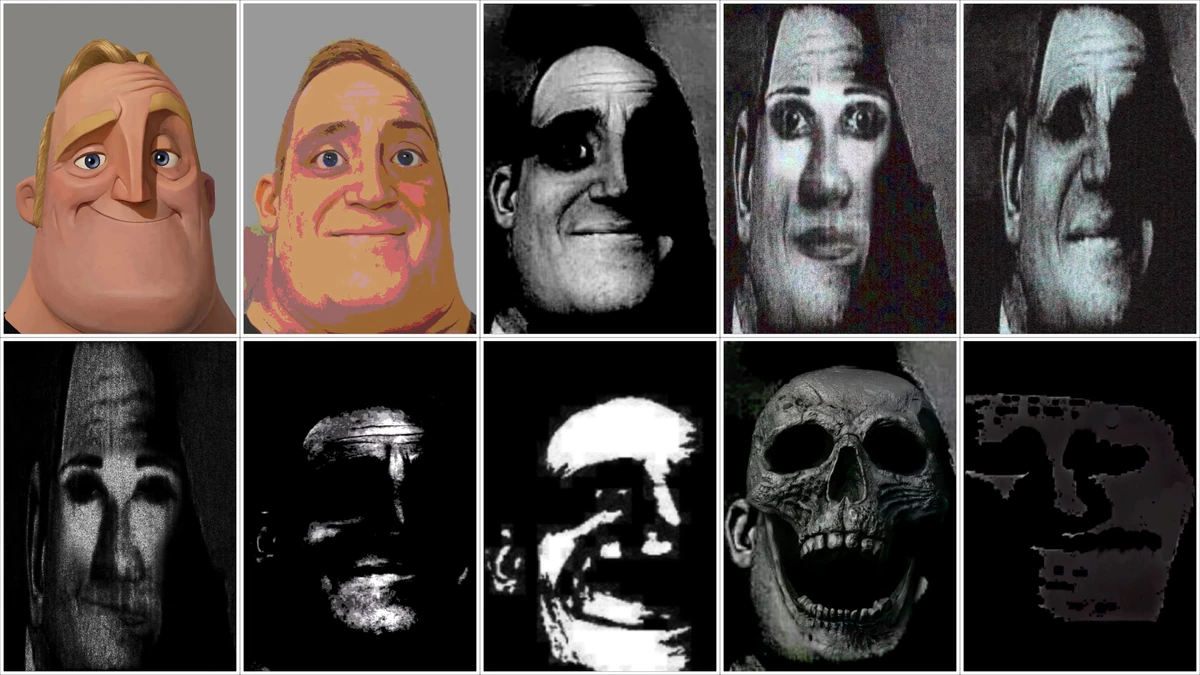
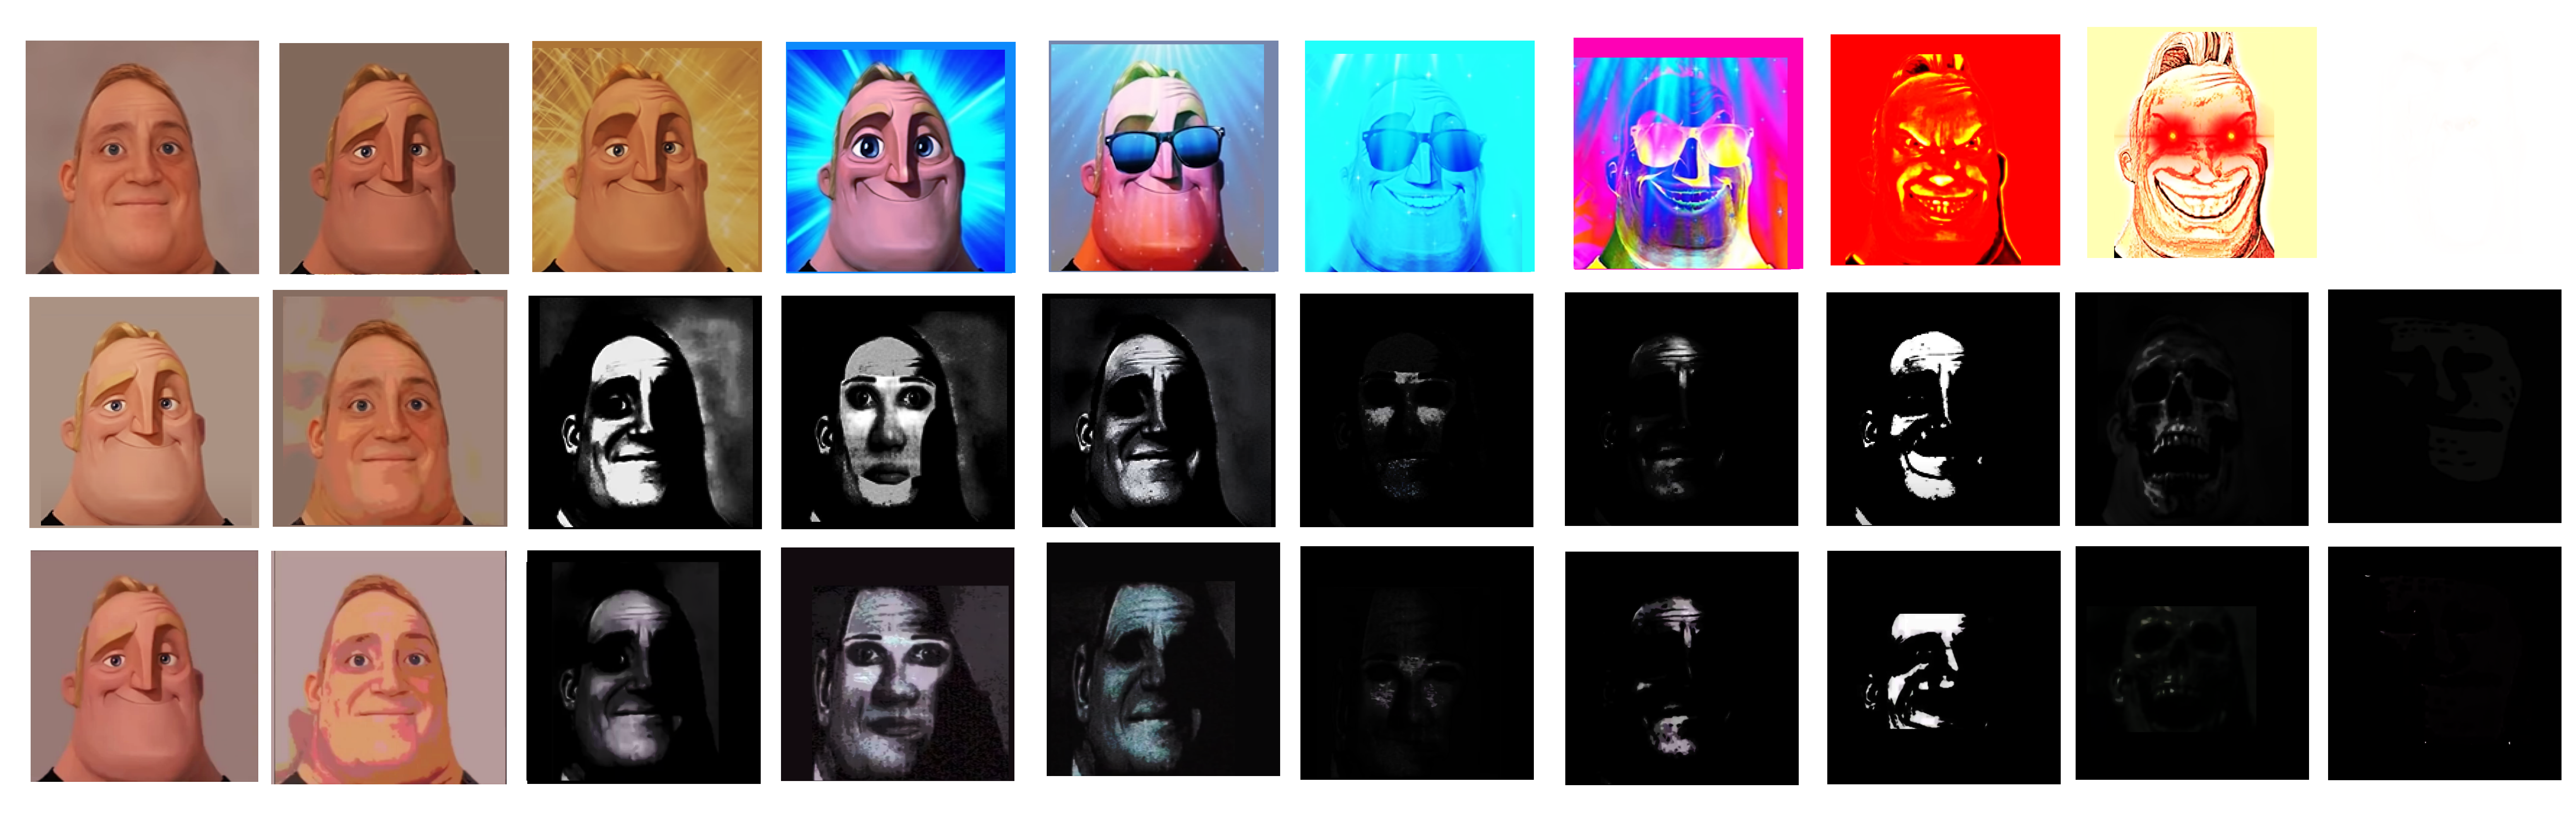
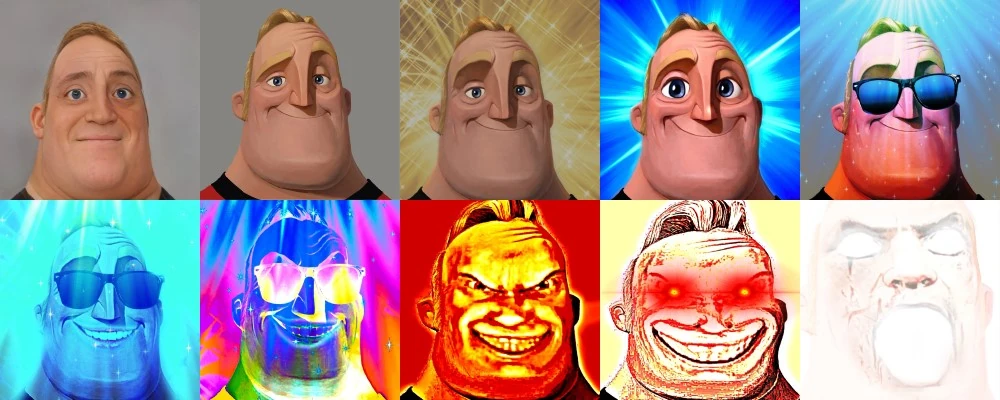
The template goes like this: you start with the normal cartoon Mr Incredible from The Incredibles movie, then each step in the sequence makes him look slightly more wrong. Not just more realistic necessarily, but subtly off. His face gets too smooth, or his proportions shift, or the lighting becomes unnatural. By the final panel, he looks either terrifying or dead, depending on which version of the meme you're making. I've made dozens of these over the years for friends and random forum requests. Here's how the actual work flows when you're not relying on one-click generators.
The Uncanny Transformation Of Mr Incredible From Superhero To Internet Sensation
Most people jump straight into Midjourney or DALL-E and type something like "Mr Incredible becoming more realistic." That gives you something, but it's rarely on-model. You end up with a blurry blob that vaguely resembles a man in a red suit. The trick is being specific about the pipeline. Start with a base image. Find the cleanest, most recognizable frame of Mr Incredible from the 2004 Pixar film. A shot where he's facing forward with clear lighting works best. I use a screencap from the opening bank-robbery scene because the lighting is flat and even, which makes inpainting far more consistent across iterations. From there, you have two real paths. The first is using Stable Diffusion with an img2img pipeline. This is the method that actually gives you control. I run SDXL with the RealVisXL checkpoint loaded. Your base image goes in as the starting point at a denoising strength between 0.4 and 0.55 depending on how much you want to shift the image. If you crank denoising above 0.6, the whole thing falls apart and you just get random textures.
Your prompt needs to anchor the generation. Something like "Mr Incredible, Pixar style, red suit, muscular, confident pose, clean lighting, high detail" helps the model stay close to the source. Then each subsequent step, you adjust the prompt slightly to push toward uncanny territory. I add things like "hyperrealistic, uncanny valley, slightly distorted face, cinematic lighting, photorealistic skin texture" across successive generations. Each iteration takes the output of the previous one as its new input at a slightly higher denoising value. The second path is Midjourney with the base64 image parameter. You upload your screencap, set the stylize value around 100 to keep it grounded, and feed it prompts that gradually shift the aesthetic. The problem with Midjourney is consistency. Every generation is somewhat independent. You'll get four variations each time and picking the right one adds friction. Over six to eight steps, the drift compounds and you lose the character entirely. Here's where I ran into a specific problem last year that nobody really talks about. I was building a 12-step sequence and by step seven, Mr Incredible's suit color had drifted from red to maroon, then to an orange-red that looked wrong against his yellow belt. The face was also slowly morphing into a generic CGI male face. I couldn't tell which control net or reference parameter was responsible without running test generations.
Get the Full Details
My workaround was simple but time-consuming. I added a reference image parameter in Midjourney (--cref) pointing back to the original screencap at every single step. In Stable Diffusion, I kept the original image as a secondary control net at low weight. This locked the color palette and basic proportions while still allowing the facial uncanny shift I wanted. It added maybe 30 seconds per generation but saved me from having to rebuild the whole sequence from scratch. There are free alternatives if you don't want to spend money on API credits or subscriptions. You can run Stable Diffusion locally through Automatic1111 or ComfyUI at zero cost after the initial setup. The catch is you need a decent GPU. An RTX 3060 with 12GB VRAM handles SDXL comfortably. Anything less and you're waiting five minutes per generation, which gets old fast when you're iterating through twelve steps. If local hardware isn't an option, Clipdrop by Stability AI offers a decent img2img tool with a free tier. It's slower and more limited than running locally but avoids the consistency problems you get from pure text-to-image approaches. Another option I've used is Leonardo AI, which has a built-in canvas editor for in-painting. It's more expensive per image than local SD but cheaper than Midjourney if you're doing heavy iteration.
One counter-intuitive thing about these transformations: less is usually more. The moment you try to make each step dramatically different, the sequence loses its power. The humor and creepiness comes from the slow creep, the tiny accumulation of wrongness. A good sequence has twelve steps where you can barely tell each individual change from the last, but by the end you're looking at something genuinely disturbing. If someone can point at step three and say "that's different," you've pushed too hard too fast. Another pitfall beginners miss is ignoring aspect ratio consistency. If your base image is 16:9 and each generation defaults to square, the character gets cropped differently each time. The composition shifts and your final sequence looks like twelve unrelated images rather than one continuous transformation. Set your output dimensions once and stick with them across every generation. The downsides are real and worth stating plainly. AI-generated meme sequences are fragile. A model update on any platform can break your workflow overnight. I've lost entire projects when Midjourney changed how it handles reference images in an update. Local Stable Diffusion has its own fragility — drivers update, checkpoints get deprecated, and you spend more time debugging installations than making memes.
There's also the question of originality that some creators overlook. These templates spread because they're easy to replicate. The field is saturated with generic versions. If you want something that actually stands out, you need to inject a specific concept into the transformation rather than just running "more realistic" eight times. I've seen people make sequences where Mr Incredible transitions from hero to corrupted government agent to cosmic horror entity. Those get shared. The generic ones just get scrolled past. When the sequence is done, you stitch the panels together. Most people use simple image editing software or even PowerPoint. Arrange them in a grid, add a caption row underneath if needed, export as PNG. The file size stays manageable. A 12-panel sequence at typical meme dimensions comes in around two megabytes, which loads fine on Reddit, Discord, and Twitter without compression ruining the details. I stop here because there's not really a conclusion to draw. The process is what it is. Generate, refine, drift, stitch. The tools change but the underlying method stays the same.