Understanding VMware vCloud Hybrid Service Central
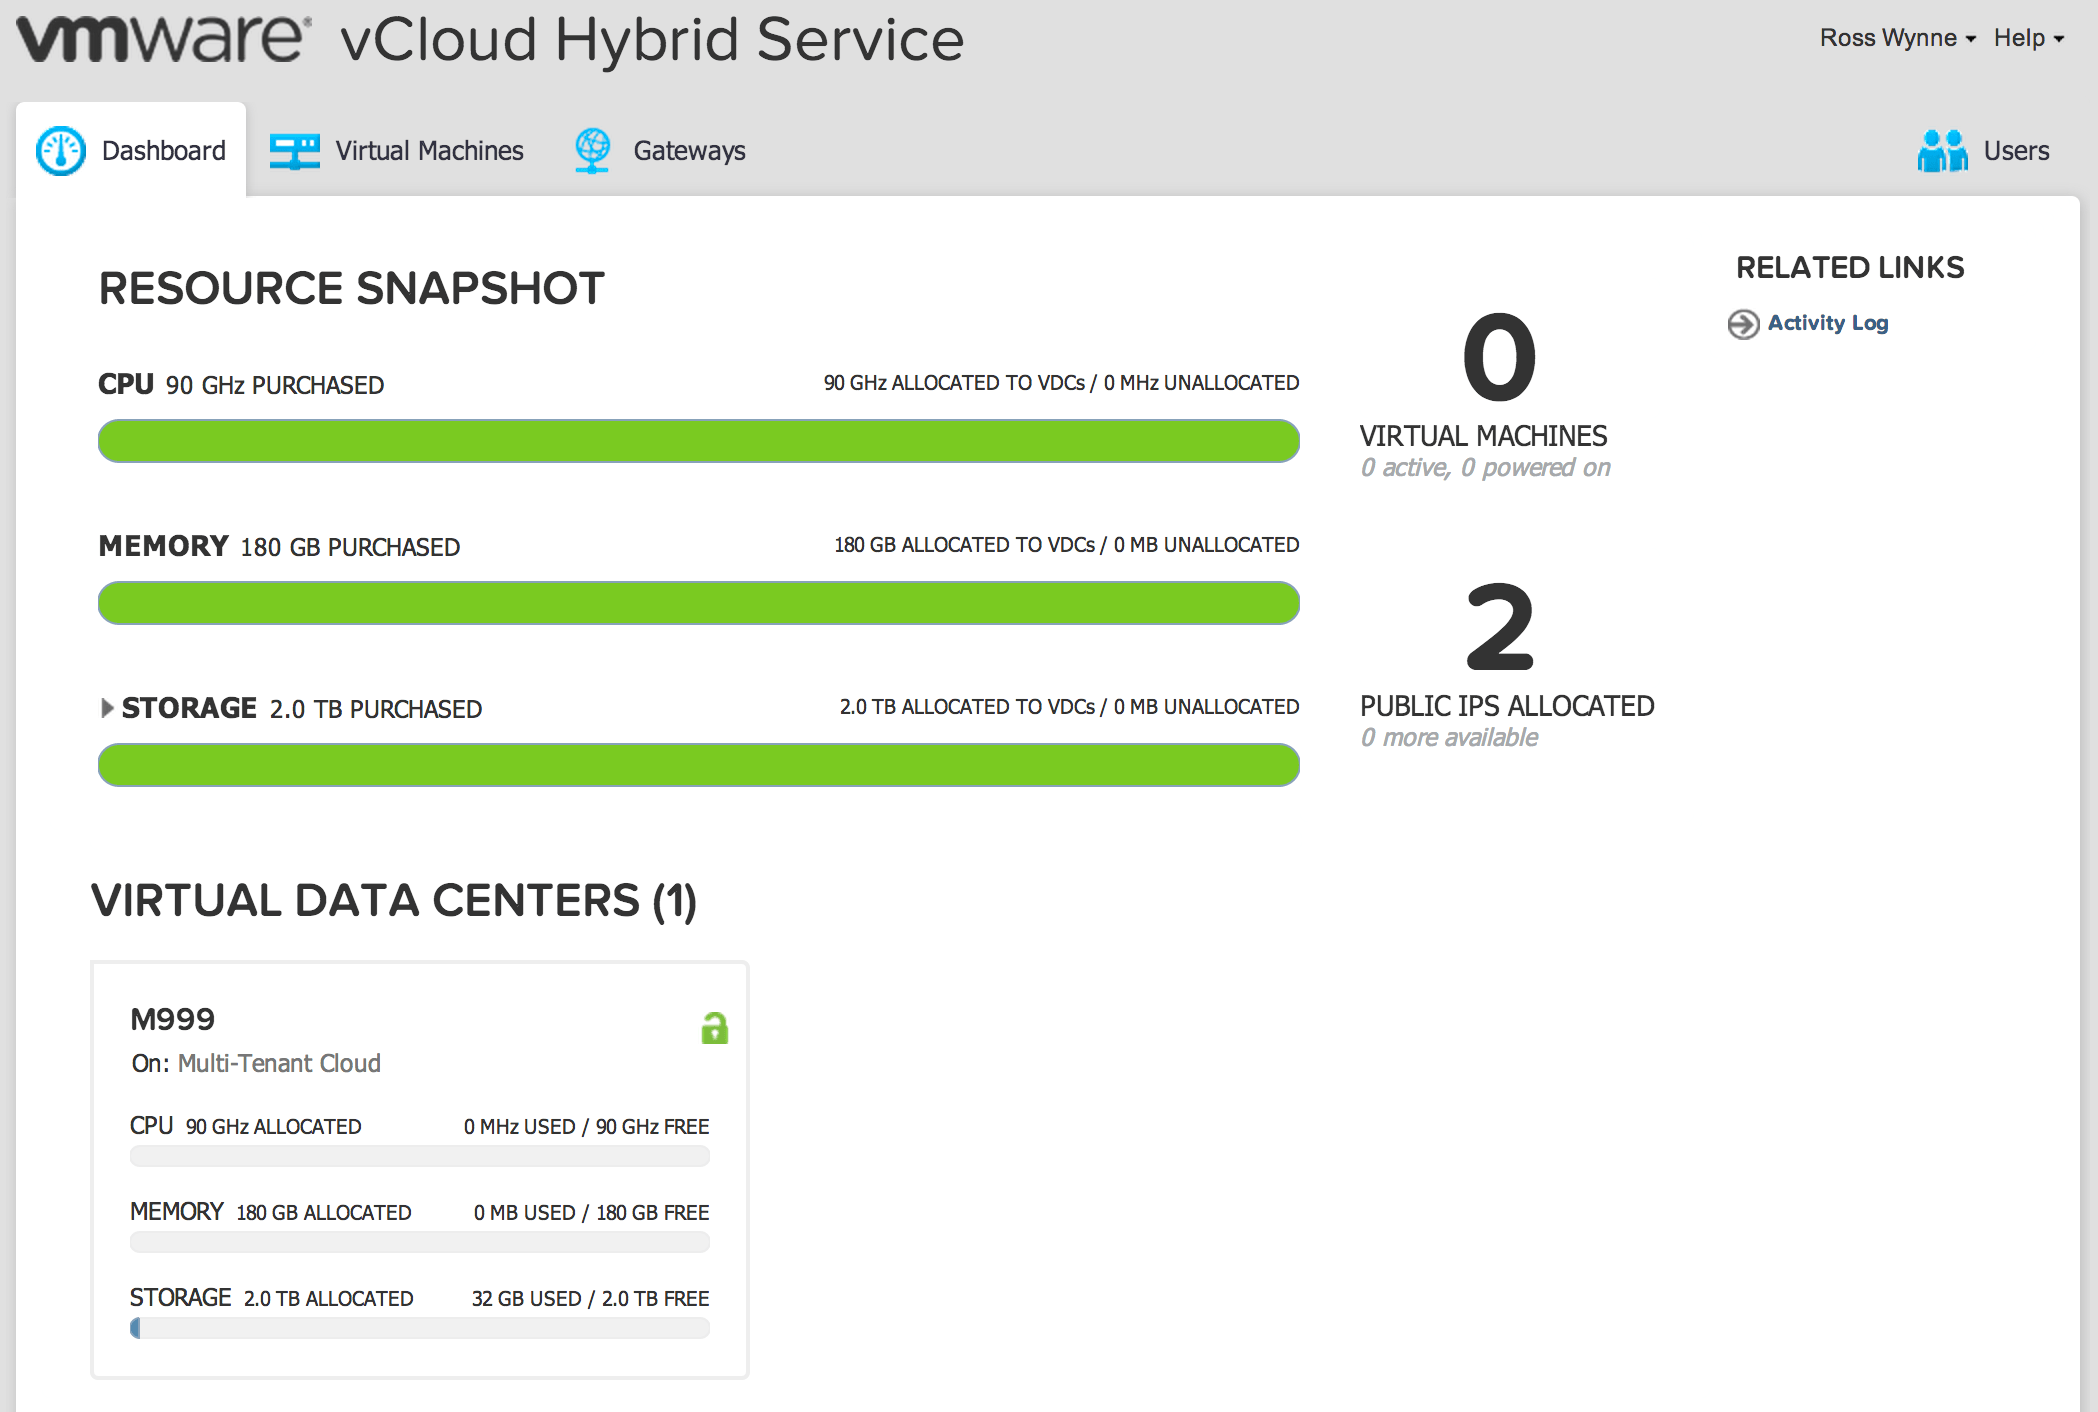
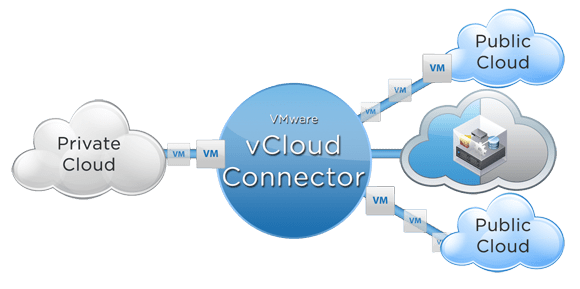
vCloud Hybrid Service Central was VMware's control plane for managing hybrid cloud environments. It let you extend vSphere infrastructure into public cloud providers like AWS and Azure while keeping a single management interface. I spent several years working with this platform across enterprise migrations, and it had some genuinely useful capabilities alongside frustrating limitations. The core idea was straightforward: deploy virtual machines in VMware-managed data centers or partner cloud infrastructure, manage them through the same vCenter workflow you already used on-premises, and handle networking between your private and cloud environments. The platform promised that if you could run VMware on-premises, you could run it in the cloud without re-architecting applications.
The Ultimate Guide To Vmware Vcloud Hybrid Service Vchs Central Unlocking New Heights In Cloud Computing
Here is how the platform actually worked when you were not reading marketing materials. You started by configuring connectivity between your on-premises vCenter and the VCHS environment. This involved setting up IPsec tunnels or leveraging VMware's partner cloud providers who had pre-built connections. The networking piece was where most people hit walls, particularly around bandwidth limitations and latency considerations for cross-datacenter traffic. Resource pools in VCHS operated differently than standard vSphere resource pools. Instead of CPU and memory reservations, you worked with quota-based allocations tied to specific cloud locations. I learned this the hard way during a migration project where we assumed standard vSphere resource reservation semantics applied. A workload that performed perfectly in our on-premises data center showed severe I/O throttling in the cloud because VCHS enforced different IOPS limits per tenant at the hypervisor level.
Setting Up the Hybrid Connection
The initial configuration required coordinating with your chosen cloud provider, which was typically one of VMware's partners like NTT, SoftLayer, or AWS through VMware Cloud on AWS (the later iteration). You needed valid VMware licenses for the vSphere components, and licensing was per-CPU-core, which changed cost calculations significantly compared to traditional on-premises deployments. Network connectivity used either site-to-site VPN with your own IPSec gateway or VMware's managed connections depending on the provider. The managed option was simpler but meant you surrendered some network visibility. I preferred the self-managed VPN approach because it gave us direct access to routing logs and made troubleshooting packet loss considerably easier when applications started showing intermittent connectivity issues. After establishing connectivity, you configured vCenter integration. This involved registering your existing vCenter Server with VCHS Central or using VCHS to manage a separate vCenter instance that controlled the cloud-deployed hosts. The two approaches had different failure modes. Self-managed vCenter instances gave you more control but required ongoing maintenance. VCHS-managed vCenter reduced operational burden but limited your ability to apply custom configurations or third-party plugins.
Get the Full Details

Deploying and Managing Virtual Machines
VM deployment through VCHS used templates stored in a shared content library. These templates were essentially golden images you prepared on-premises and published to the VCHS repository. The template format had to match the target cloud provider's requirements, which created compatibility headaches when moving workloads between different providers. I encountered a specific issue with disk provisioning during a multi-provider deployment. VCHS used thick-provisioned disks by default for production workloads, but certain AWS regions had storage costs that made this economically unviable. The workaround involved creating custom OVF properties that forced thin provisioning while maintaining performance through strategic I/O scheduling. This required modifying the template configuration and updating the provisioning policy through the VCHS API, which was not documented in the standard administration guides. Scaling operations worked through VCHS Central's orchestration capabilities. You could define virtual machine groups with auto-scaling policies based on CPU, memory, or custom metrics collected through vROps agents. The monitoring agent deployment was straightforward, but the metric collection intervals had significant overhead. I typically configured 30-second collection intervals for critical production systems and 5-minute intervals for dev/test environments to balance monitoring granularity against management plane performance.
Cost Management and Billing
VCHS billing operated on a consumption model that tracked compute hours, storage usage, and network egress separately. The pricing structure varied by provider and region, making cost comparisons across environments complicated. I maintained a spreadsheet tracking actual versus projected costs for every deployment, which revealed significant variance between quoted and actual pricing due to network egress charges that many organizations underestimated. Storage costs deserved particular attention. VCHS billed based on provisioned storage, not actual usage, which meant empty virtual disks still incurred charges. During one engagement, we identified that approximately 15 percent of our cloud storage costs came from discarded snapshot files that had not been properly cleaned up after migrations. Implementing automated snapshot policies and enforcing regular cleanup reduced that waste significantly. Network egress represented another cost trap. Data leaving the cloud environment for on-premises destinations or internet endpoints carried per-GB charges that compounded quickly during large data transfers. I implemented compressed data pipelines and scheduled bulk transfers during off-peak windows when some providers offered reduced rates, though these discounts were inconsistently applied across the VMware partner ecosystem.
Limitations and Known Issues
VCHS Central had genuine shortcomings that prospective users should understand before committing. The platform supported only VMware ESXi hosts, which eliminated options for organizations running heterogeneous hypervisor environments. Migration tools existed for converting Hyper-V and Physical-to-Virtual deployments, but the process added time and complexity that sometimes exceeded the benefit of using VCHS in the first place. Performance variability remained a persistent concern. Because VCHS shared physical infrastructure across multiple tenants, baseline performance could fluctuate based on neighboring workload patterns. I experienced situations where database query response times degraded by 40 percent during peak hours without any configuration changes on our side. VMware offered dedicated instance options at higher cost, but these were not always available in all regions. The platform's integration with third-party tools was limited compared to native cloud offerings. Automation workflows required vRO, and complex orchestration scenarios often needed custom script development. I spent considerable time building PowerShell modules that wrapped VCHS API calls for CI/CD pipeline integration, but VMware did not provide official SDKs that matched the quality of what AWS and Azure offered their native tooling.

Support responsiveness varied significantly depending on your contract tier and the specific cloud provider involved. Critical production issues sometimes required escalation through multiple organizational layers before reaching engineers with actual platform expertise. This was particularly problematic during outages when rapid resolution was essential but communication lag delayed remediation efforts.
Migration Considerations
Moving workloads to VCHS required careful assessment of application dependencies and performance requirements. Network latency between your on-premises environment and cloud-deployed instances could break applications that assumed direct connectivity or low-latency communication. I implemented load testing protocols that simulated cross-datacenter latency before authorizing any production migrations. Data migration strategies depended heavily on workload size and acceptable downtime windows. Large database migrations often required replication-based approaches with cutover planning, while smaller application workloads could use VMware vMotion or Storage vMotion equivalents provided through the VCHS interface. The vMotion capability worked well for warm migrations but had strict size limitations on virtual disks, typically capping at 2TB per disk in most provider configurations. Testing after migration required validation of both functional correctness and performance characteristics. I developed checklists covering application startup sequences, database connectivity, external service integrations, and performance benchmarks compared against on-premises baselines. Missing any of these validation steps led to post-migration surprises that damaged stakeholder confidence in the hybrid cloud approach.
Current State and Alternatives
VMware has since evolved its cloud strategy significantly. VCHS Central has been superseded by VMware Cloud on AWS as the primary managed service offering, with additional integrations through Tanzu and other product lines. The fundamental hybrid cloud concept remains relevant, but the implementation details and available features have changed considerably since VCHS's peak popularity. Organizations currently evaluating hybrid cloud options should compare VMware's current portfolio against native cloud solutions and other managed service providers. The trade-offs involve different factors than they did during the VCHS era, particularly around Kubernetes integration, edge computing capabilities, and multi-cloud management features. Cost analysis should account for platform lock-in risks and the potential need for future architectural changes as cloud provider capabilities continue evolving. The lessons from the VCHS experience remain applicable regardless of which platform you ultimately choose. Network architecture deserves careful planning, cost models require detailed understanding beyond headline pricing, and testing protocols must account for the specific limitations of your chosen infrastructure provider. These principles translate across technologies even as the tooling changes.