Why Your ETL Pipeline Keeps Breaking on Wednesday Nights
I spent about four years working on data integration for retail companies, and the ones that survived the transition from legacy systems to modern cloud warehouses had one thing in common: they stopped treating ETL like it was something you built once and never touched again. You build it, it breaks, you fix it, it breaks again when the source system changes. That's just how it is. The reality most people don't tell you is that the average enterprise ETL job runs 30 to 40% slower than it should because nobody audits the pipeline for actual bottlenecks. They just let it run, hope it finishes, and move on. This guide is about stopping that pattern and getting your integration work doing what it's supposed to instead of eating into your entire team's week.
The Ultimate Guide To Target Etl Pay Unlocking Data Integration Efficiency
Target ETL Pay refers to the practice of optimizing extract, transform, and load processes specifically for data integration workflows where efficiency gains translate directly into operational savings and faster reporting cycles. It's not a single tool or a product you can buy. It's an approach to how you design, monitor, and maintain your pipelines so they don't fall apart under real workload conditions. Here's what that looks like in practice. First, you stop writing ETL jobs that pull every single row from every table and process them in a single pass. That approach worked fine when your data volume was in the thousands. Now you're dealing with millions per job, and the difference between pulling incrementally versus pulling fully can mean the difference between a pipeline that finishes in two hours and one that takes all night and still doesn't finish. The second thing you do is identify your actual transformation bottlenecks before you optimize anything else. Most teams skip this step. They tune the query and assume that's the problem. It's rarely the problem. The problem is usually one of three things: your merge logic is doing full table joins on staging tables that haven't been partitioned, your data types are mismatched between source and target causing implicit conversions on every row, or your parallelism settings are configured so poorly that you're actually creating more contention than you're solving.
I ran into this exact situation at a mid-size retailer. We had a nightly payroll integration job that processed employee compensation data across twelve different source systems. The job was scheduled to finish at 4 AM so finance could run reports by 8 AM. It took five hours. Every single night. The root cause wasn't the data volume — it was the transformation step. Each source system had its own date format and its own currency code, and the ETL was converting and mapping everything in a single sequential pass with no parallelism. I rewrote the mapping layer to handle the transformations in four parallel branches, one per geographic region, with local date and currency rules applied within each branch instead of globally. The job went from five hours to forty-two minutes. Not because we added more servers. Because we stopped making the database do useless work. Here's another counter-intuitive thing nobody mentions: sometimes the best optimization is removing data, not processing it faster. I've seen teams spend weeks trying to speed up a pipeline that was doing unnecessary transformations on data that nobody actually used in their reports. Audit what the downstream consumers are actually querying. If half your transformed columns aren't referenced in any dashboard or report, you're spending compute resources moving dead weight around the warehouse. Remove them. You can always add them back if someone complains. Monitoring is where most teams fail. They set up alerts that trigger when a job fails. That's too late. You need alerts that trigger when a job is taking longer than its historical average, even if it hasn't failed yet. A job that normally runs for ninety minutes and suddenly takes two hours and ten minutes has already eaten part of your morning. By the time it fails, you've lost the whole day. I configure my monitoring to track duration trends with a simple moving average, and alert when any single run exceeds two standard deviations from the baseline. That gives me time to intervene before the failure window becomes a crisis.
Get the Full Details

Let's talk about incremental loads, because this is where the biggest efficiency gains live. A full refresh of a ten-million-row table every night is almost always the wrong answer. Incremental loads pull only the rows that changed since the last successful run. The implementation varies depending on your platform, but the concept is universal: you need a reliable change tracking mechanism. Timestamps on updated rows work for most operational systems. Change data capture works better if your source system supports it natively. Triggers are a trap — they sound elegant in theory and they degrade write performance on the source system in practice. There is a legitimate scenario where incremental loading fails completely, and that's when your source system doesn't maintain a history of changes. Some legacy ERPs only store the current state of a record. There's no timestamp you can rely on. There's no audit trail. In those cases, your only option is to do a full comparison between source and target, which means reading the entire source table every time anyway. You haven't saved anything. The only way around this is to work with your source system administrators to enable audit logging, or to build a small shadow table that captures changes at the application layer. Neither is trivial, but both are cheaper than maintaining a nightly full load that's going to cost you in compute and latency. Data quality checks belong inside the pipeline, not after it. I see too many teams validate their data in a separate step that runs after the ETL completes, which means every time a quality issue is found, the whole pipeline has to rerun. Put the validation inside the transform stage. Reject bad rows into a quarantine table, log the reason, and continue processing the good ones. Your downstream reports get delivered on time with known data gaps instead of being delayed because a single malformed row broke the entire batch.
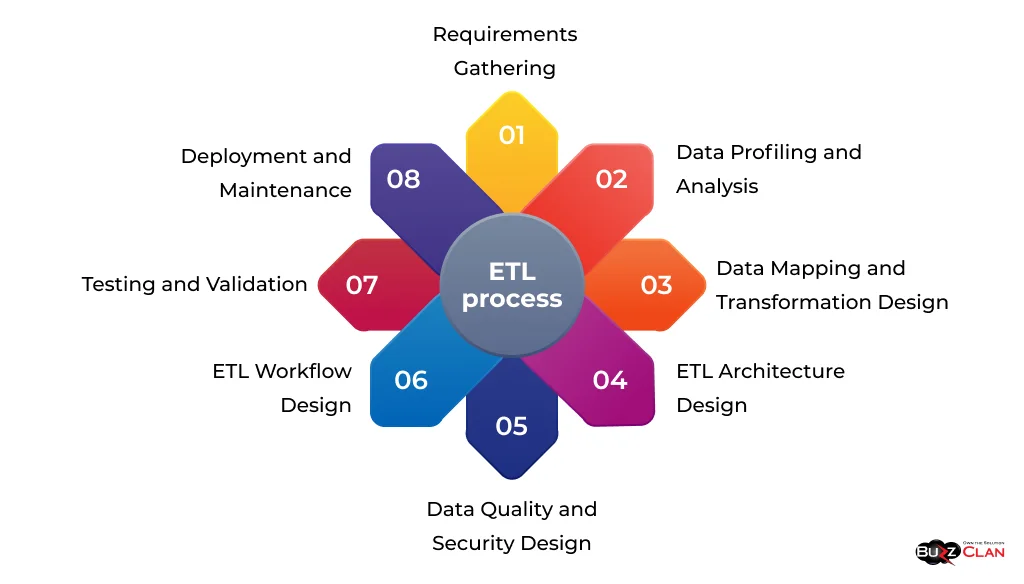
Parameterization matters more than people think. Hardcoded values in your ETL jobs — file paths, connection strings, date thresholds — are the kind of thing that creates silent failures. The job runs successfully but against the wrong environment or stale parameters. Store everything in a configuration layer that you version control. A well-maintained parameter table is worth more than any fancy orchestration tool because it makes your pipelines transparent and debuggable. If you're starting from scratch or rebuilding an existing pipeline, here's the order I'd recommend working through: map your data sources and confirm exactly what fields each one provides and how often they update, define your target schema and identify which columns downstream consumers actually need, choose your load strategy based on whether the source supports change tracking, write the pipeline with parallelism enabled for independent transformations, add inline quality checks at every major stage, set up duration trend monitoring before you go live, and run a parallel execution alongside your existing pipeline for at least one full cycle before decommissioning the old one. Do not skip that last step. You will always find something in the old pipeline that wasn't documented. The cost analysis is straightforward. A typical enterprise ETL environment with six to eight major pipelines running nightly will spend between four and eight engineer-hours per week on pipeline maintenance, debugging, and reruns. After a proper optimization cycle — and I'm talking about a focused two to three week effort, not an ongoing initiative — that number usually drops to under two hours. The initial investment is real. But the compounding return is what makes it worth doing right instead of doing fast.