Why Alphabetical State Lists Are Tricker Than They Look
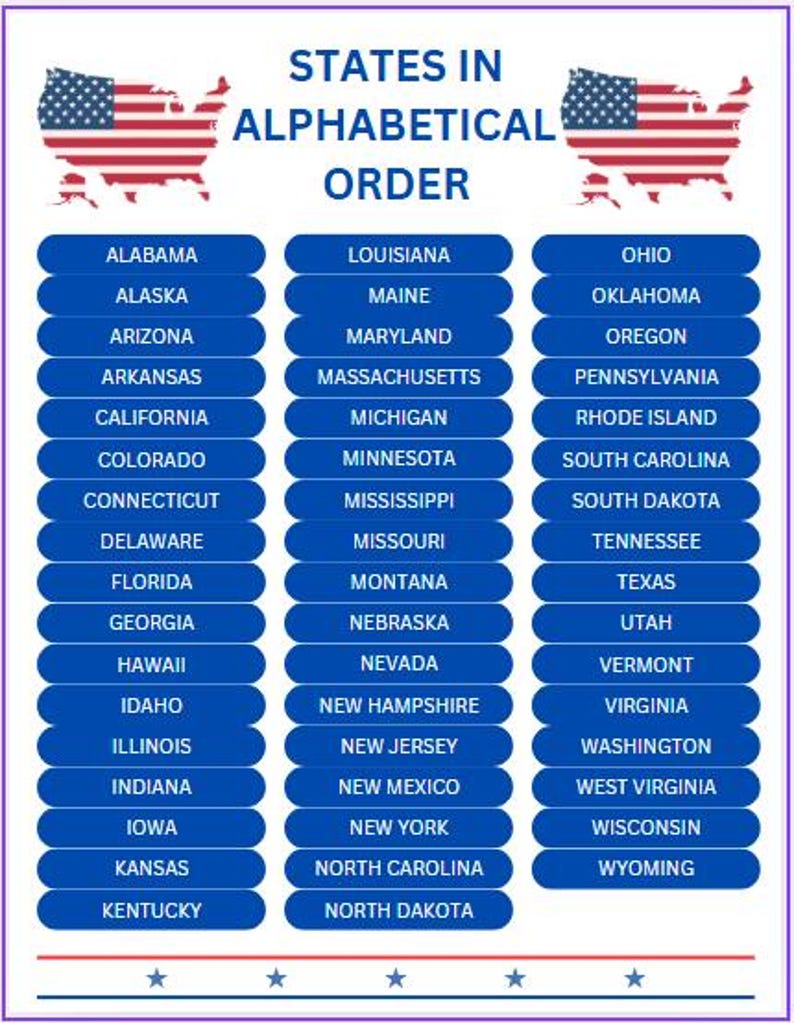
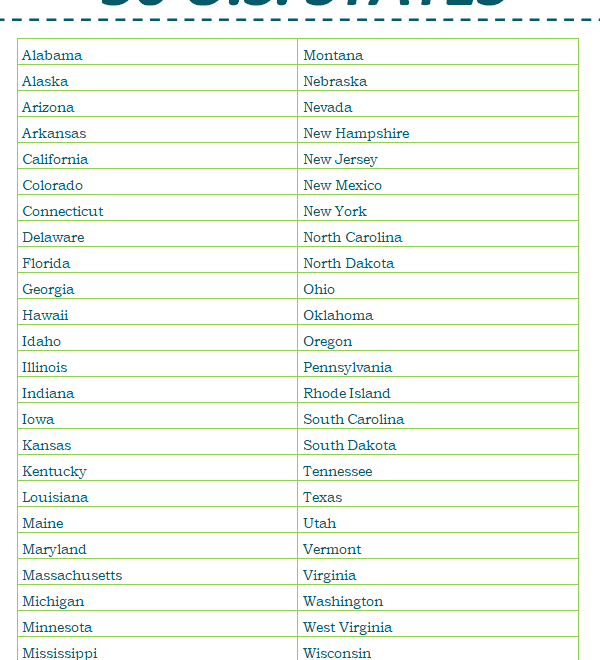
Most people assume sorting fifty US states alphabetically is something you could do blindfolded. It isn't. I spent three hours last month fixing a municipal zoning database where the state abbreviations had been manually entered across two dozen spreadsheets, and half the alphabetical sort failures came from inconsistent abbreviation formats — some fields used "Calif." while others used "CA." The actual alphabetical sequence of the states themselves is straightforward, but the data entry layer underneath usually introduces enough noise that any automated sort produces garbage unless you clean the source material first. The core list, in plain alphabetical order by full state name, runs like this: Alabama, Alaska, Arizona, Arkansas, California, Colorado, Connecticut, Delaware, Florida, Georgia, Hawaii, Idaho, Illinois, Indiana, Iowa, Kansas, Kentucky, Louisiana, Maine, Maryland, Massachusetts, Michigan, Minnesota, Mississippi, Missouri, Montana, Nebraska, Nevada, New Hampshire, New Jersey, New Mexico, New York, North Carolina, North Dakota, Ohio, Oklahoma, Oregon, Pennsylvania, Rhode Island, South Carolina, South Dakota, Tennessee, Texas, Utah, Vermont, Virginia, Washington, West Virginia, Wisconsin, Wyoming. That looks simple until you actually need to produce it for official use. Several states create edge cases that trip up naive sorting algorithms. Connecticut and Delaware have very short names, which messes with fixed-width formatting in older legacy systems. District of Columbia is not a state but frequently appears in these lists, and its proper placement alphabetically is between Delaware and Florida — or outside the list entirely depending on whether the requirement specifies "states only." I learned this the hard way when a grant application portal rejected my submission because I'd appended D.C. at the end instead of inserting it in its correct alphabetical position.
Here is what most people miss. The alphabetical order changes depending on whether you sort by full name or by postal abbreviation. The USPS two-letter codes were assigned in roughly 1963 and do not follow alphabetical order at all. For example, "PA" comes before "RI" visually, but Pennsylvania (PA) is alphabetically after Rhode Island (RI). If your system sorts by abbreviation and displays the full name alongside it, you will get a list that looks wrong to anyone who knows the actual alphabetical state order. I encountered this exact problem when building a dropdown menu for a voter registration form — the developer used the postal code field as the sort key, which produced a list that had Vermont appearing after Texas and Wyoming appearing before Virginia.
How To Build A Clean, Sort-Correct State List
Start with the raw data. The US Census Bureau publishes an official list of states and territories with their corresponding FIPS codes and postal abbreviations. This is the authoritative source, and it should be your starting point rather than pulling from a random blog post or Wikipedia table. The Census list gives you each state's legal name, abbreviation, numeric code, and region assignment, which you then process through a sort routine keyed on the full name field, not the abbreviation field. If you are generating this list programmatically, use a case-sensitive sort and normalize all entries to title case first. Raw data from government databases sometimes arrives with unexpected capitalization — "new york" in lowercase can slip through validation, and a simple case-insensitive sort will place it after "North Dakota" instead of in its correct position after "New Mexico." I once inherited a dataset where the lower-state names had been bulk-imported in lowercase, and the alphabetical output was completely wrong for any entry beginning with "New" or "South." For the postal abbreviation reference, here is the complete set ordered by full state name, which is the useful dual view most people actually need:
Get the Full Details

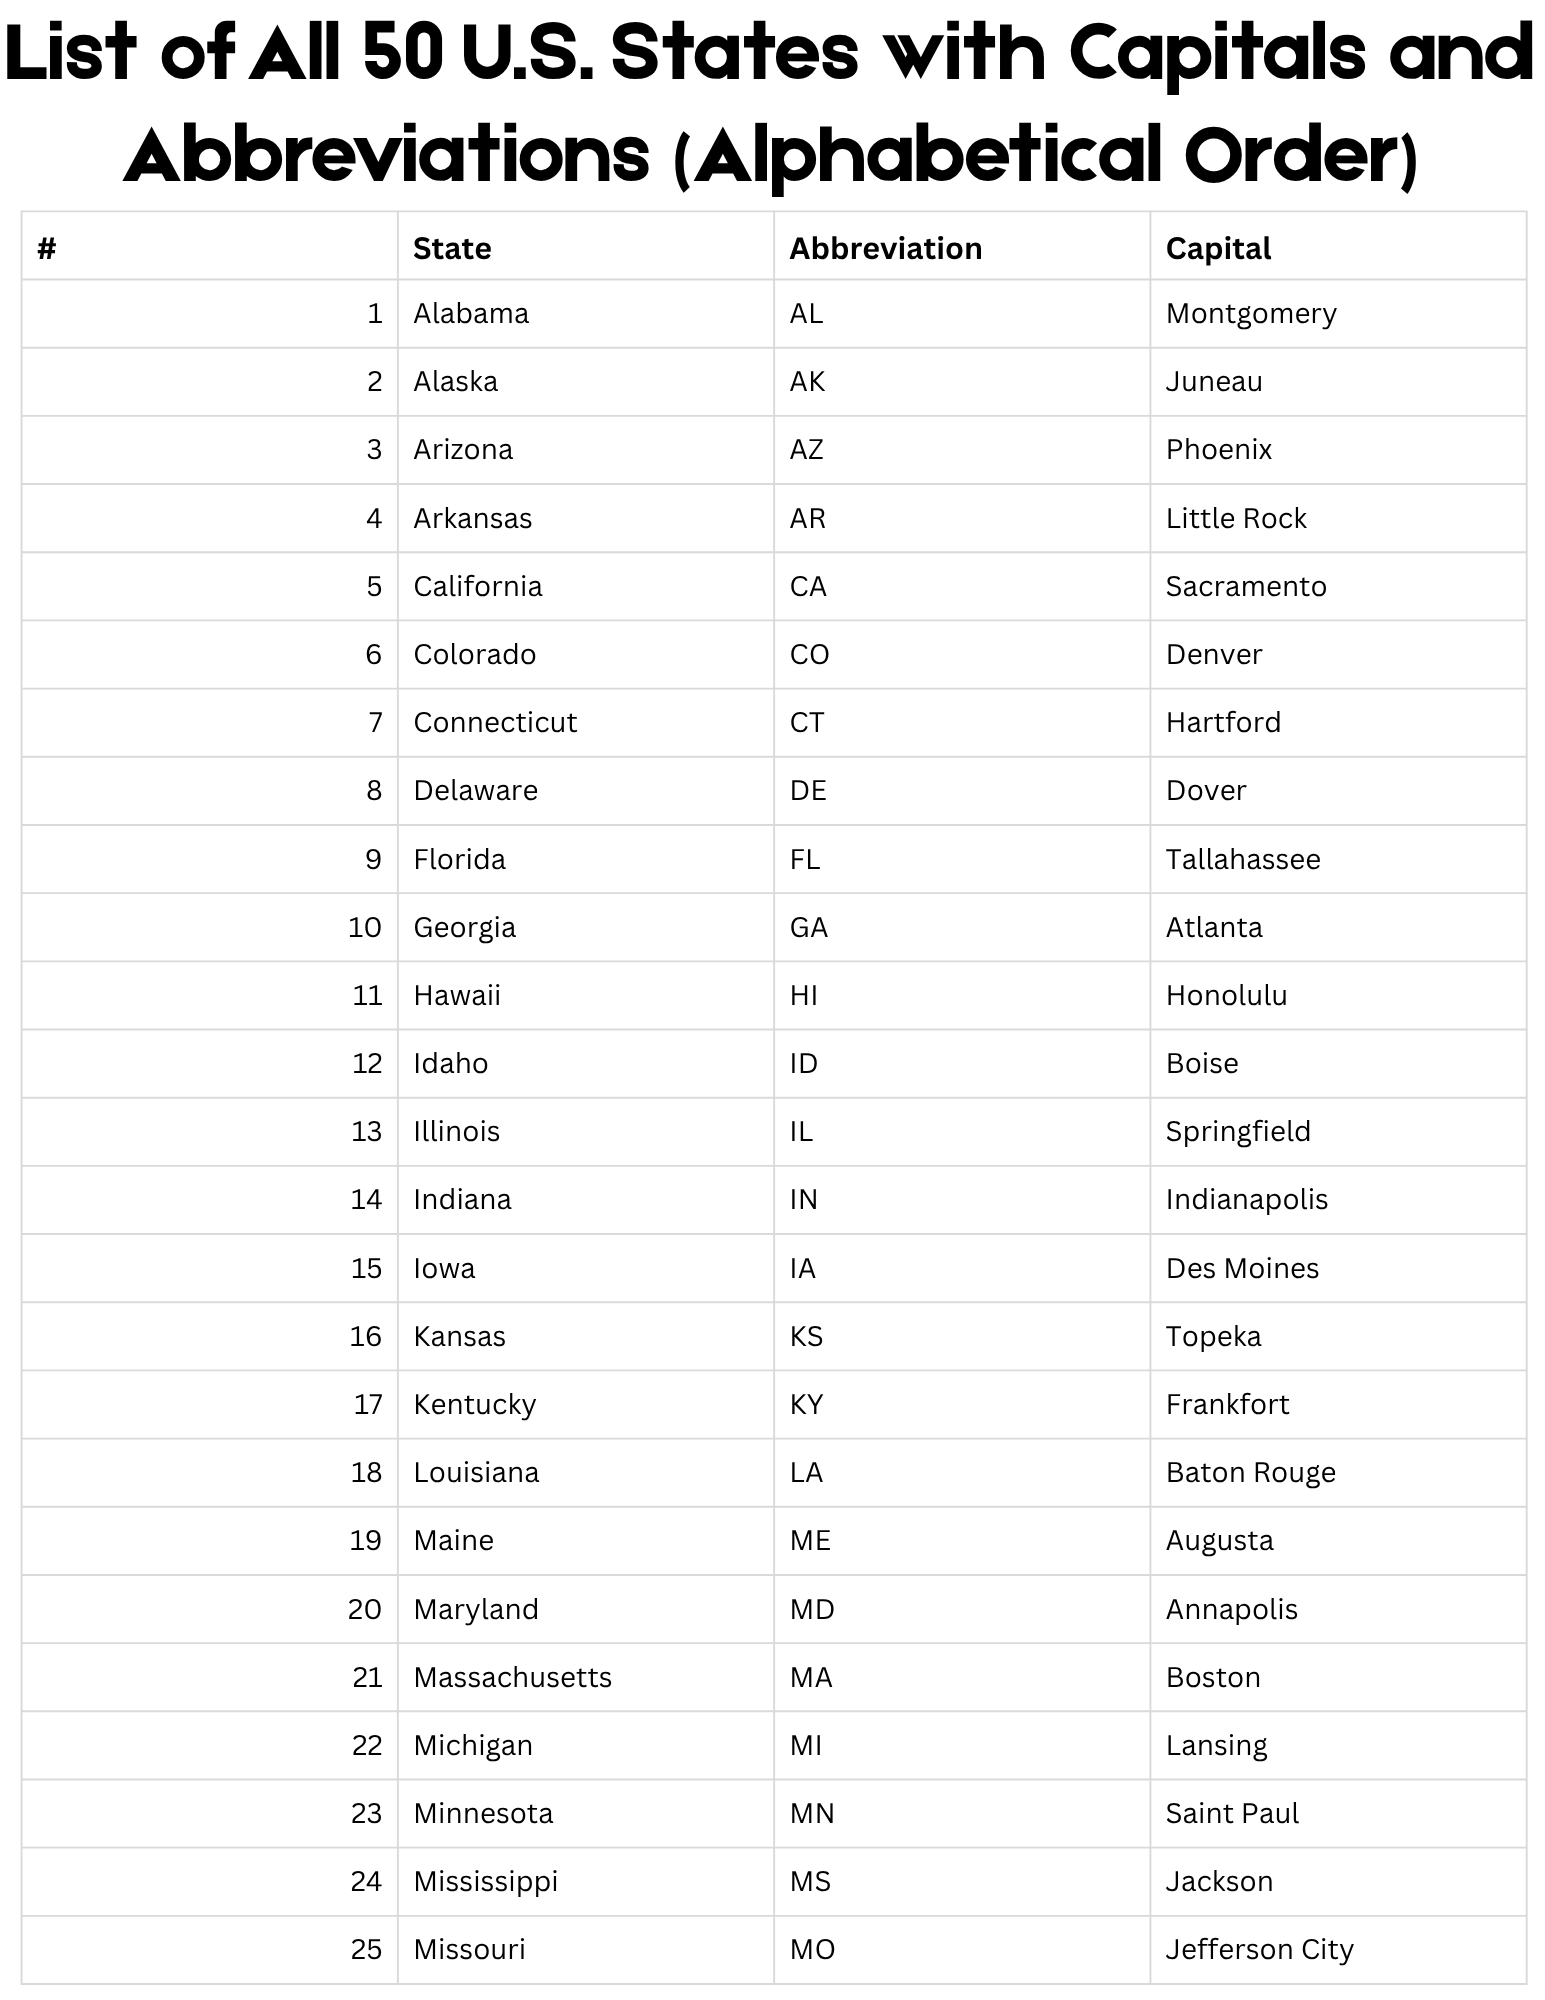
Alabama (AL), Alaska (AK), Arizona (AZ), Arkansas (AR), California (CA), Colorado (CO), Connecticut (CT), Delaware (DE), Florida (FL), Georgia (GA), Hawaii (HI), Idaho (ID), Illinois (IL), Indiana (IN), Iowa (IA), Kansas (KS), Kentucky (KY), Louisiana (LA), Maine (ME), Maryland (MD), Massachusetts (MA), Michigan (MI), Minnesota (MN), Mississippi (MS), Missouri (MO), Montana (MT), Nebraska (NE), Nevada (NV), New Hampshire (NH), New Jersey (NJ), New Mexico (NM), New York (NY), North Carolina (NC), North Dakota (ND), Ohio (OH), Oklahoma (OK), Oregon (OR), Pennsylvania (PA), Rhode Island (RI), South Carolina (SC), South Dakota (SD), Tennessee (TN), Texas (TX), Utah (UT), Vermont (VT), Virginia (VA), Washington (WA), West Virginia (WV), Wisconsin (WI), Wyoming (WY).
Common Pitfalls When Working With State Lists
The biggest practical problem I see is the omission of territories and independent nations. Puerto Rico, Guam, American Samoa, the US Virgin Islands, and the Northern Mariana Islands frequently appear in address verification systems but are not states. They have their own postal abbreviations — PR, GU, AS, VI, MP — and they sort differently than states. If your list is intended for general mailing purposes, you need a separate section for these. If it is strictly for state-level reporting, they must be excluded, and the distinction matters because regulatory forms sometimes require all federally recognized US territories to be listed separately. Another pitfall is date-referenced lists. Maine split from Massachusetts in 1820. Vermont was an independent republic before joining the Union. Kentucky was part of Virginia. These historical facts do not change the current alphabetical list, but they do matter when you are working with historical documents, land records, or genealogical databases where "state" had a different meaning at the time of record creation. I worked on a digitization project for county clerk records from the 1780s where the concept of "state" was still being defined, and applying modern alphabetical state sorting to that data produced nonsensical results because the territorial boundaries were completely different. There is also the problem of duplicate or variant spellings. "Massachuset" appears in some historical records missing the final "s." "Carolina" without the "North" or "South" qualifier creates ambiguity. Legacy database systems from the 1990s sometimes stored state names with truncation — "Washingto" instead of "Washington" — which breaks alphabetical sorting because the truncated version would sort after "Virginia" rather than in its correct position.
When Standard Sorting Fails
Some datasets require sorting by region rather than alphabetically. The Census Bureau divides states into four regions: Northeast, Midwest, South, and West. Within each region, states are often listed alphabetically. A "comprehensive review" of state lists that ignores regional grouping is incomplete for any application involving demographic analysis, emergency management, or federal funding distribution. The regional sort order is a completely different sequence from pure alphabetical order, and I have seen multiple projects fail compliance reviews because they presented states alphabetically when the reporting standard required regional grouping. Population-based ordering is yet another alternative that occasionally gets confused with alphabetical ordering. Texas, California, Florida, and New York lead by population but appear at opposite ends of the alphabetical list. This is mostly relevant for business directories or market research, but the confusion between these two sorting methods has caused real errors in published reports. Electronic data interchange formats like ANSI X12 and EDIFACT use state codes that differ from USPS abbreviations in some implementations. Healthcare and logistics organizations sometimes maintain parallel state lists — one for mail delivery, one for transaction processing — and keeping them synchronized is more work than most people anticipate. The USPS updated its abbreviation standards in recent years, retiring certain legacy codes, which means any system built on older abbreviation tables may have become partially outdated.
At this point the basic alphabetical list should be clear, the sorting methodology established, and the common failure modes identified. The practical takeaway is that producing a correct state list is simple in theory and messy in practice, and the messiness usually comes from the data layer rather than the sorting logic itself.