Stop Rerunning Everything Because You Never Cleaned Up State
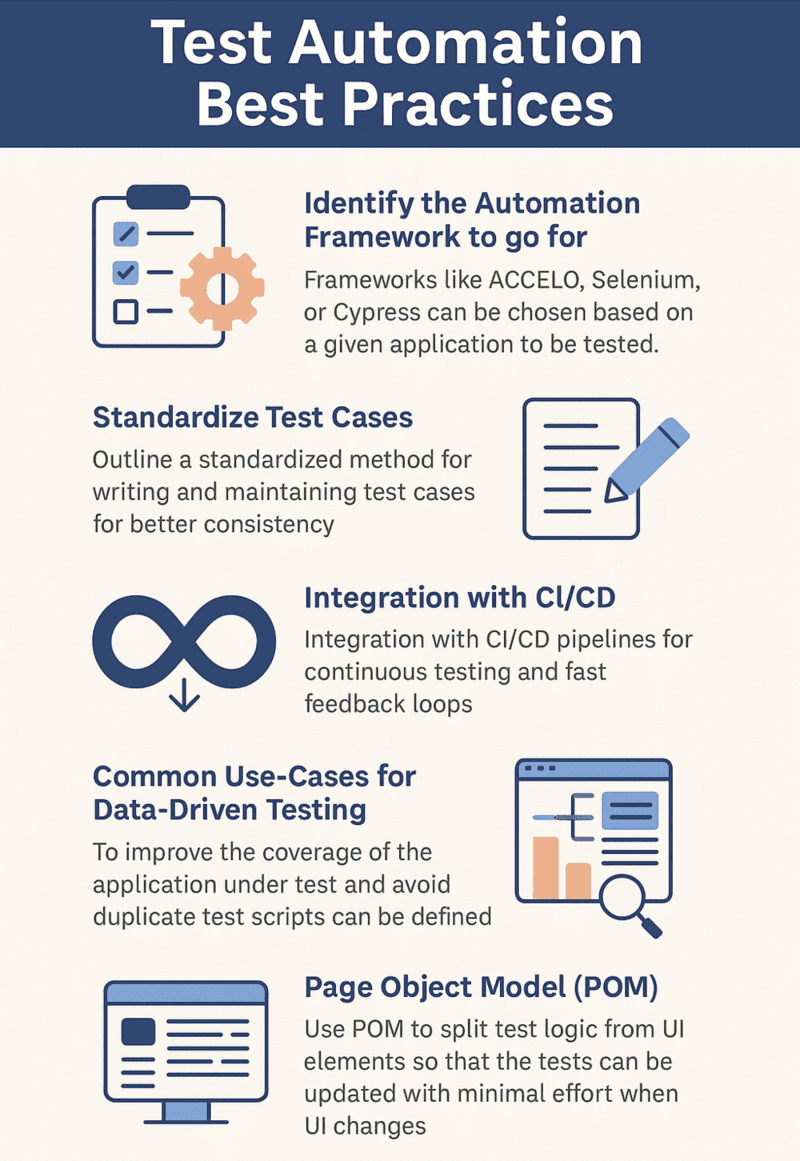
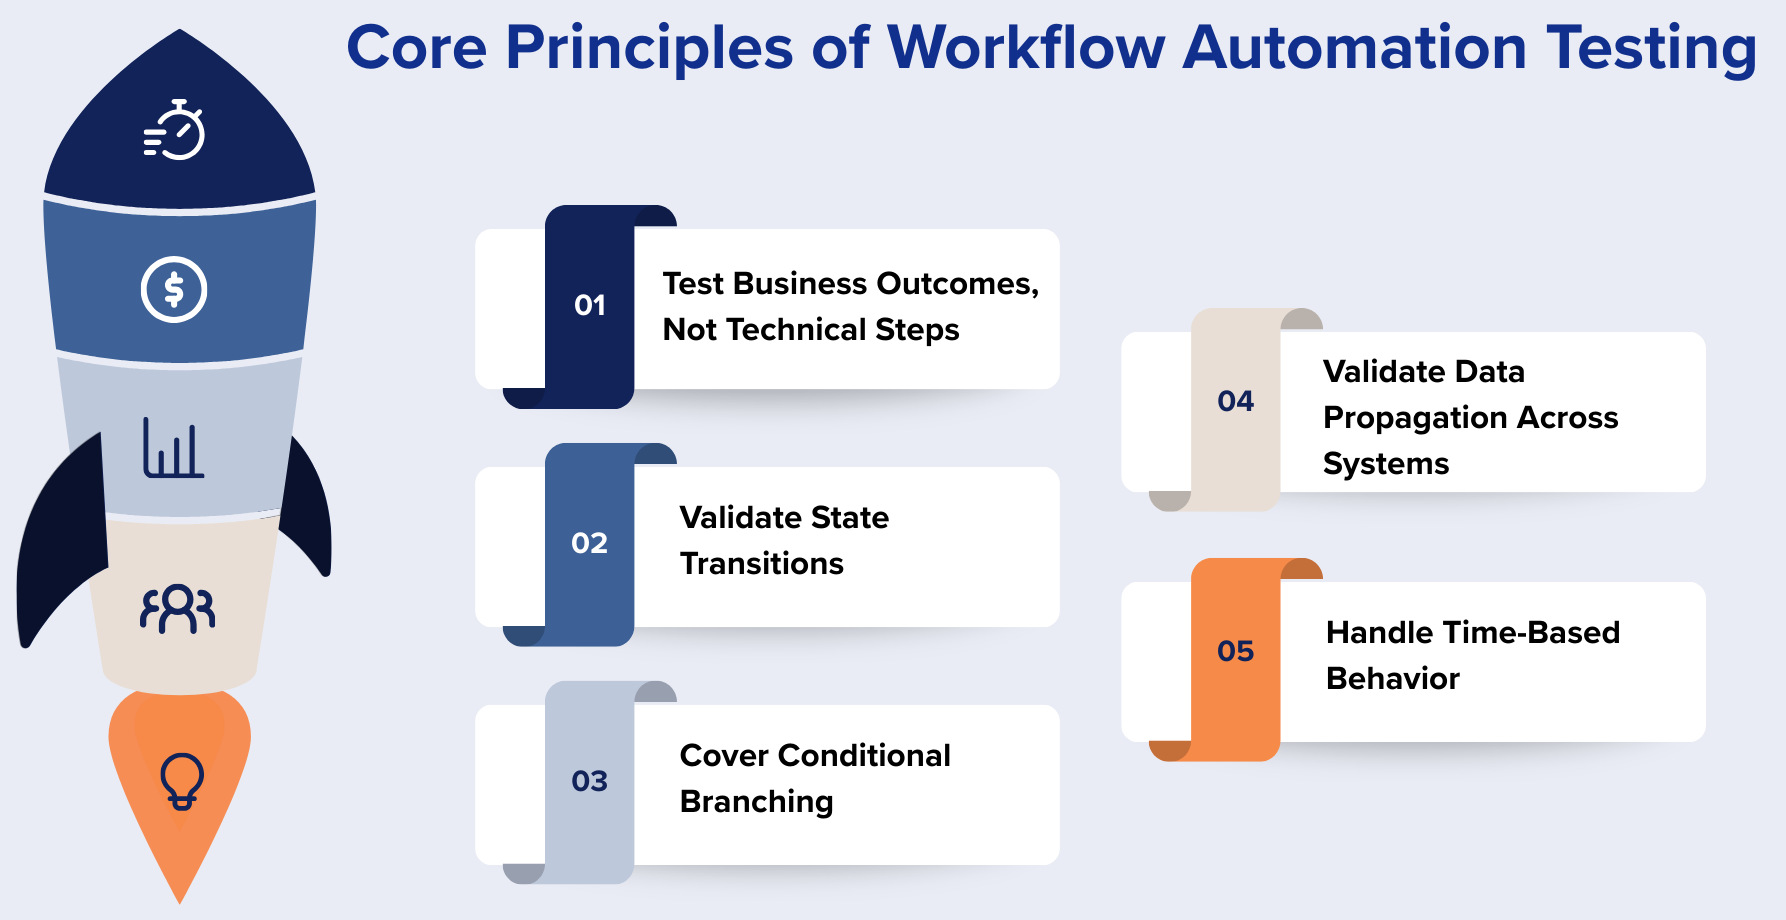
I spent three days last month debugging a test suite that kept failing intermittently across different workers. The actual bug was a singleton in the service layer that held database connections from a previous test run. Eighteen tests failed. The code under test had never changed. This kind of thing happens constantly when your workflow assumes each test is isolated by default. It isn't. Optimizing your testing workflow isn't about running tests faster. It's about making the feedback loop actually useful. Fast tests that give you false confidence are worse than slow tests you trust. I've seen teams cut their suite runtime from 45 minutes to six by sharding, only to discover they'd also eliminated meaningful integration points in the process. Now they ship things that break in staging every Thursday and nobody knows why until the alert fires. The first practical step is mapping what you actually have. Most teams I talk to think they have a "test suite" but really they have three different kinds of tests running through the same command. Unit tests, integration tests, and end-to-end tests all live in the same directory, share the same CI pipeline, and all get blocked behind the same gate. When something fails, you have no idea which category it belongs to without manually inspecting each one. This alone accounts for most of the wasted time in any workflow I've audited.
Separate them at the pipeline level. In my own setup, I use different test markers and route them to separate pipeline stages. The unit tests run first with no external dependencies. They should complete in under two minutes for a medium-sized codebase. If yours takes longer than that, you're probably doing I/O or instantiating objects you shouldn't be. I've seen developers import entire application contexts just to call a single function. That's not a unit test at that point, it's an integration test wearing a costume.
Structural Flaws Most People Miss
Here's something nobody likes to admit: your test suite's growth rate is probably exponential, not linear. Every new feature adds not just its own tests but also setup complexity, fixture dependencies, and coupling to existing test infrastructure. I watched a project where the test count went from 400 to 1200 over eighteen months, but the meaningful coverage stayed flat around 62 percent. The other 800 tests were either redundant assertions, flaky integration checks, or regression tests for bugs that had already been fixed and then rewritten without anyone updating the original test. The workaround I ended up using was aggressive test pruning combined with a coverage threshold that actually mattered. I set a requirement that any new code must have associated tests, and I ran a quarterly audit where I killed anything that wasn't directly preventing a known failure mode. Coverage dropped from 62 percent to 54 percent over two quarters and we caught more production bugs than we had in the previous year. The tests that remained were sharper because they had a clear purpose. The ones I removed were noise that was burning CI minutes and making real failures harder to spot. Another structural issue is how you handle test data. I used a fixtures-based approach for years. Load a JSON file, seed the database, run the test, tear it down. Then I moved to transactional test isolation where each test runs inside its own database transaction that gets rolled back on completion. This cut our flakiness significantly because you're no longer dealing with lingering state between tests. But it introduced a new problem: any test that needs to query outside its own transaction, like checking a message queue or a secondary read replica, breaks immediately. You end up writing adapter layers just to make those tests work, and now you're maintaining test infrastructure that's more complex than the production code.
Get the Full Details
Parallelization And Sharding
Running tests in parallel is the most common optimization people reach for, and it's also the most poorly understood. Sharding your test suite across multiple workers works well until your tests share mutable state. I had a pipeline where shard two consistently took 40 percent longer than the others. The problem was a cluster of tests that all depended on loading a large seed dataset into memory. They weren't actually slower per test. They were slower because they were competing for the same resource allocation on the same worker container. The fix was grouping related tests so they ran sequentially within a single shard while keeping unrelated shards parallel. This is called affinity-based grouping and it's something most CI platforms don't expose directly. You have to specify it manually through test ordering or annotation. In my case I used test markers to tag which tests shared expensive setup, then configured the pipeline to route those markers to the same worker instance. Another parallelization mistake is assuming more workers equals faster results. After a certain point, you hit diminishing returns because your CI infrastructure becomes the bottleneck rather than the tests themselves. I found this out the hard way when adding workers from four to twelve reduced our total runtime by maybe 15 percent instead of the expected 66 percent. The remaining time was dominated by container spin-up, dependency installation, and test result aggregation. At that point, optimizing the pipeline configuration gave us more gains than throwing hardware at the problem.
Flaky Tests Are A Workflow Problem, Not A Code Problem
Flaky tests will destroy your workflow faster than anything else. A single flaky test causes engineers to skip reruns because they've learned the pipeline lies. Then the real failures hide behind the noise until something breaks in production. I once spent an afternoon tracking down a test that failed randomly. It turned out to be using the system clock to generate unique IDs. When two tests ran simultaneously on different workers, they produced the same ID and collided. The fix was replacing the clock-based ID generator with a UUID in the test setup. The root cause was architecture, but the symptom was a flaky test, and fixing the symptom without addressing the cause meant it would come back. The practical approach to flakiness is treating it as a workflow priority, not a code quality issue. When a test flakes, you don't just rerun it and move on. You document it, isolate it, and either fix the underlying race condition or quarantine it behind a retry annotation with a deadline. I use a policy where any flaky test gets marked with a retry mechanism but also tagged with a Jira ticket that expires in fourteen days. If the root cause isn't resolved by then, the test gets removed from the main suite and moved to a nightly-only run. This keeps the pipeline green for daily development while still preserving coverage for things that can't be made deterministic.
Local Development vs CI Divergence
This is the single biggest waste of time I see in testing workflows. Your tests pass locally but fail in CI. The reasons are almost always environmental: different Node versions, missing environment variables, locale differences affecting string comparison, or cached dependencies that don't exist in the container. I spent two weeks debugging a test that failed only in CI because the production Docker image was using an older version of a library than what was installed globally on my machine. The API had changed subtly between versions. The test passed everywhere except the pipeline because the pipeline was the only place running the old version. The solution I settled on was using a Docker-based local development environment that mirrors the CI container exactly. Not a perfect mirror, but close enough that the dependency tree matches. I also pin all versions in a lockfile and refuse to accept PRs that update dependencies without running the full test suite in the container. This added about thirty seconds to my local test runs but eliminated the entire class of "works on my machine" failures. Thirty seconds is nothing compared to the hour someone else spends debugging why the pipeline broke.
What This Workflow Doesn't Solve
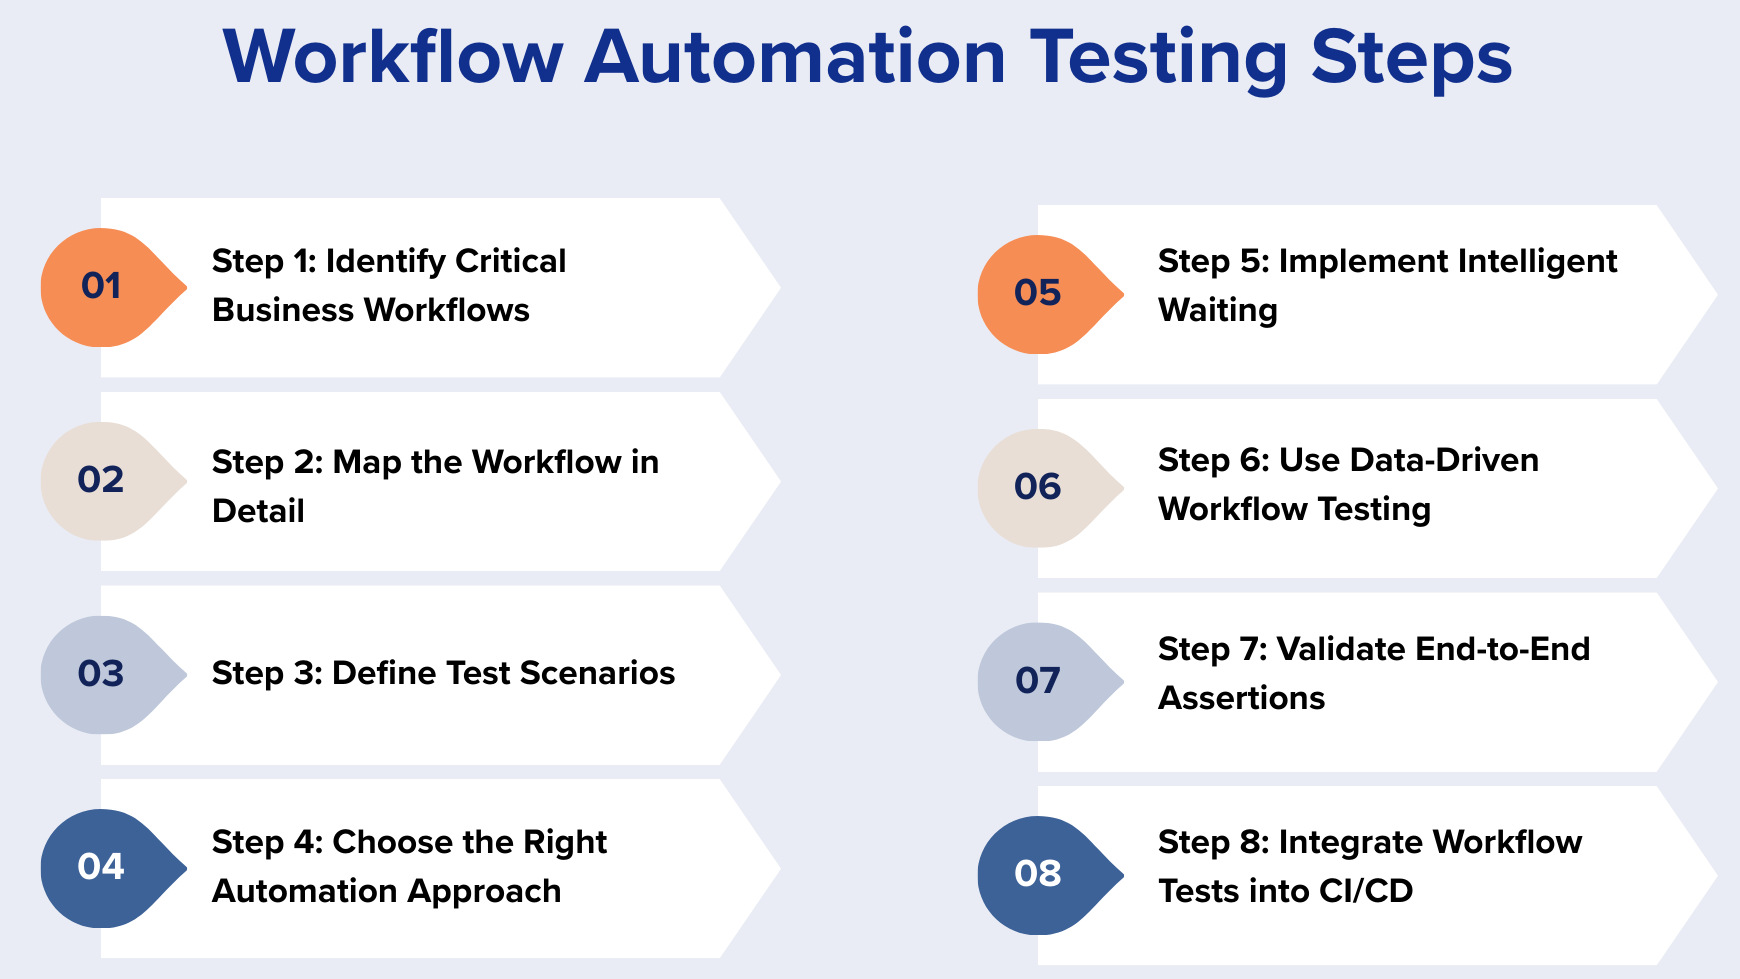
I should be clear about what optimizing your testing workflow won't fix. If your application has fundamental architectural problems, like tight coupling between modules or implicit dependencies scattered across the codebase, no amount of testing pipeline optimization will make your tests reliable. You'll get faster feedback on bad code, but you'll still get bad feedback. I've seen teams spend six months refining their test infrastructure only to realize the tests they'd optimized were covering a layer of the system nobody actually used anymore. Another hard limit: testing workflows can't compensate for poor feature design. When a feature has twenty different code paths that all need separate test cases, the problem isn't your test runner. It's that the feature should have been simpler. I learned this after spending three weeks building elaborate test fixtures for a notification system that had grown into a five-state finite automaton. We eventually refactored it down to three states and the test suite shrank by 60 percent naturally. The workflow optimization was irrelevant once the code got better. The practical takeaway is that testing workflow optimization is a multiplier, not a foundation. It amplifies whatever quality of testing you already have. Good tests become faster and more reliable. Bad tests become faster and still wrong, which is somehow worse because you have less time to notice the problem. Start with test quality, then optimize the workflow around it. I've tried it the other direction and it never works.