Embeddings Come First, Everyone Else Goes Second
The way most people approach natural language processing is backwards. They train a classifier before they understand their data distribution. I spent two years learning this the hard way on a legal document classification task where we built a BERT fine-tune that achieved 94% accuracy on validation but failed catastrophically in production because the training set had zero examples of contracts from three specific jurisdictions. The model wasn't just wrong, it was confidently wrong. That cost us about six weeks of rework and a lot of credibility with the product team. Here is the practical order that actually works: first, build a small tokenizer script and inspect your token distributions across your actual input data. Second, compute basic statistics on token lengths, vocabulary coverage, and the percentage of OOV words your base vocabulary encounters. Third, run a tiny baseline like logistic regression on TF-IDF features just to establish what "easy" looks like. Fourth, choose your transformer or whatever architecture based on whether the baseline already captures 80% of the signal. If TF-IDF gets you there, you don't need BERT and you'll save three days of training time.
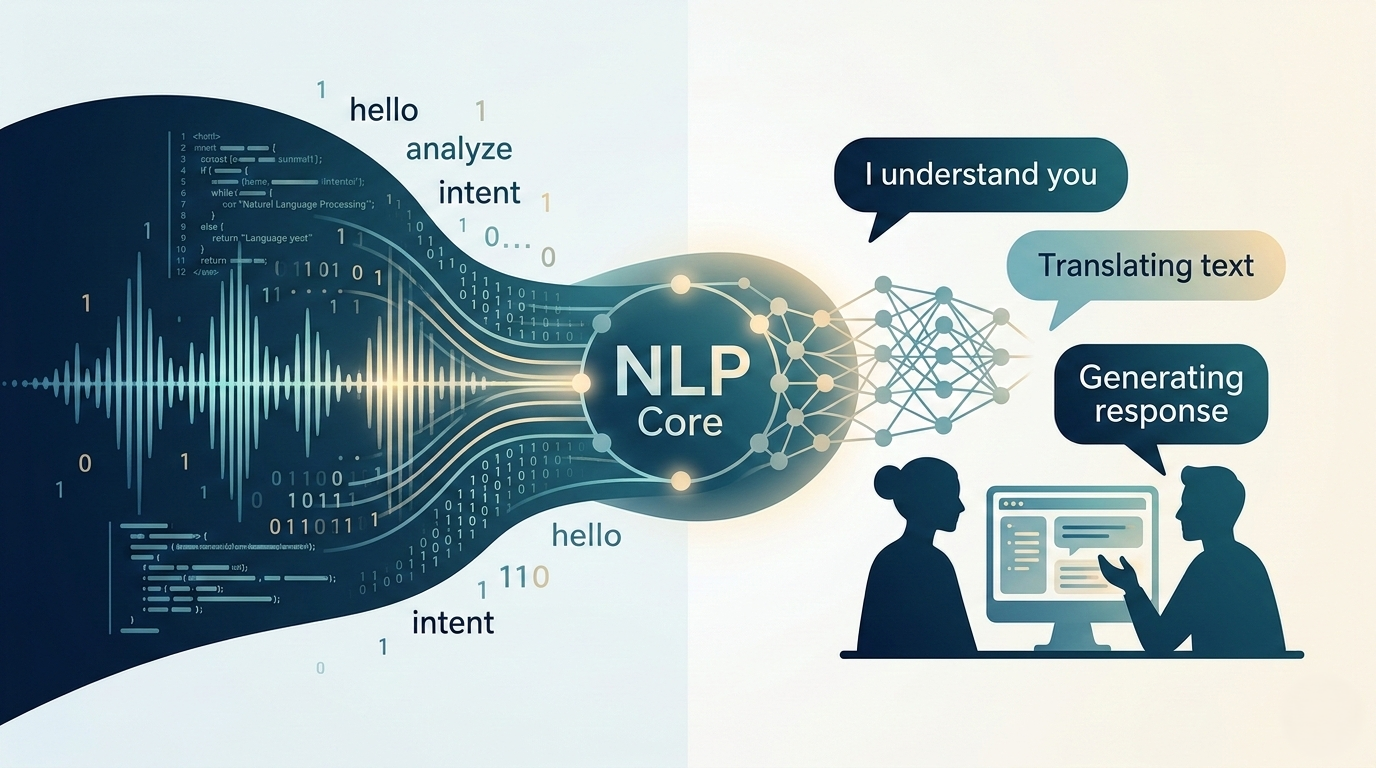
The Ultimate Guide To Natural Language Processing How AI Is Revolutionizing The Way We Communicate
There is a reason this field has moved so fast in the last five years. Before transformers, you were fighting positional encoding limitations with LSTMs and attention was this expensive luxury that only worked on short sequences. The shift to self-attention meant you could process entire paragraphs in parallel instead of sequentially, and that opened up a whole layer of applications that were previously too computationally expensive to attempt. Real-time sentiment analysis on live chat streams, document-level summarization on the fly, these aren't hacks anymore, they're standard pipelines. But the revolution is uneven. Consumer-facing tools got the glossy treatment. Most actual industrial NLP work still looks like someone writing a lot of data cleaning scripts and then calling a pre-trained model from Hugging Face. I've reviewed codebases where the NLP "system" was essentially a regex filter upstream of a spaCy pipeline upstream of a frozen DeBERTa checkpoint. It worked, mostly. The regexes handled 60% of the edge cases and the model handled the rest.
Tokenization Is Where Things Break
I want to talk about a specific problem I ran into last year with a multilingual support ticket classification system. We were using a multilingual XLM-RoBERTa model and everything looked fine until we started seeing terrible performance on tickets that mixed English with code-switched Hindi-English. The model's wordpiece tokenizer was fragmenting Hinglish terms like "server crash ho gaya" into garbage subwords. One tokenization of "kya" produced the tokens ["k", "##ya"]. This destroyed the semantic representation for entire classes of queries. The workaround wasn't elegant. I wrote a preprocessing function that detected code-switched segments using a simple language identification step, then ran those segments through a Hindi-specific tokenizer before merging them back into the main pipeline. You can do this with langdetect and the Hindi tokenizer from transformers. The result was a 12% lift in F1 score on the mixed-language test set. Not transformative, but real. And it took about four hours to implement. Another thing nobody warns you about: tokenization choices affect your memory footprint more than you think. A model that uses byte-level BPE will produce different sequence lengths than one using WordPiece, even on the same text. If you're running inference at scale and your GPU is memory-bound, switching from a WordPiece tokenizer to a SentencePiece BPE tokenizer can actually reduce your batch size requirements because the token count drops. I saw this on a production deployment where the switch let us squeeze two extra samples into each batch without hitting OOM errors.
Get the Full Details
Fine-Tuning Without Wrecking What Worked Before
Transfer learning in NLP means something very specific: you take a model that was trained on something massive and mostly unrelated, and you adjust its weights for your narrower task. The standard approach is full fine-tuning, which means you update all the parameters. That is the naive approach and it is often the wrong one. When you fine-tune a 340 million parameter model on a dataset of a few thousand labeled examples, you risk catastrophic forgetting, where the model loses its general language understanding and becomes specialized to the point of brittleness. LoRA and similar parameter-efficient methods changed the game here. You freeze the base model and inject small trainable matrices into the attention layers. A typical LoRA setup might add less than 1% new parameters. The model retains its pretrained knowledge and learns only the task-specific adaptations. I switched our team to LoRA about two years ago and we've been able to fine-tune models on datasets ten times smaller than what full fine-tuning requires. The tradeoff is that you need to tune the rank and alpha hyperparameters, and if your task requires deep semantic restructuring rather than surface-level adaptation, LoRA can hit a ceiling. We found that for text classification and NER, it's usually sufficient. For abstractive summarization or machine translation, full fine-tuning or at least_adapter_ tuning still tends to win. One counter-intuitive detail: lower learning rates matter more than people realize when doing parameter-efficient fine-tuning. A lot of tutorials suggest using the same learning rates you'd use for full fine-tuning, which is around 2e-5 for BERT models. But when you're only updating a small subset of parameters, that rate can be too aggressive. We started seeing loss spikes and validation curves going horizontal after the first epoch. Dropping the learning rate to 5e-5 for the adapter layers and keeping the base model at something like 1e-5 or even freezing it entirely made a noticeable difference. I know that sounds backwards, lower learning rate on the base, but the pretrained weights are already good, they don't need much adjustment.
Evaluation That Doesn't Lie
Accuracy is almost never the right metric for NLP tasks. If you have an imbalanced dataset, which nearly all real-world ones are, accuracy will look good while your model learns nothing useful. I once saw a spam filter report 99.2% accuracy when it was just classifying everything as "not spam" because only 0.8% of the training data was spam. The model was worthless and everyone celebrating the score. For classification, report macro-F1, not just F1. Macro-F1 treats all classes equally regardless of support, which catches imbalanced dataset problems. For sequence labeling like NER, use span-based F1 rather than token-level F1, because token-level metrics penalize boundary errors unfairly. If your model predicts a person's name from index 3 to 11 and the gold label is 3 to 12, token-level metrics say almost nothing correct, but span-based F1 acknowledges that the model got the identity right and only messed up the length by one token. Error analysis is where the actual work happens. I recommend writing a script that randomly samples 200 misclassified examples from your development set and manually reviews them. In my experience, you'll find that 40 to 60% of errors fall into three or four recurring patterns. Once you identify those patterns, you can either add targeted training data, write preprocessing rules, or adjust your model architecture. This process usually takes one or two days and it consistently produces bigger improvements than hyperparameter tuning on its own.
What This Stuff Actually Can't Do
I need to be clear about the limitations because the marketing around NLP doesn't mention them. NLP models are pattern matchers at scale. They don't understand anything in the way humans do. They learn statistical associations between sequences of tokens. This means they will always struggle with compositional generalization, reasoning about combinations of concepts they haven't seen together before. A model trained on "the cat sat on the mat" and "the dog lay on the rug" doesn't necessarily know what to do with "the cat chased the dog across the mat" because the relational structure is novel. NLP models also inherit and amplify biases from their training data. This isn't a bug you can fix with a better architecture, it's a fundamental property of training on web-scale text. If your downstream application makes decisions about people, you need a bias audit in your pipeline, not just a trained model and a prayer. We implemented a simple demographic parity check on our hiring document screening tool and found that the model was down-weighting resumes from certain university names. We couldn't fully fix it, we could only reduce reliance on the model's output and require human review for borderline cases. The biggest practical bottleneck right now isn't model quality, it's data quality and labeling consistency. You can have the best architecture in the world and it will underperform a mediocre architecture on clean, well-labeled data. We switched from using internal staff to label our training data to using a specialized annotation platform with inter-annotator agreement checks, and our model performance improved by about 5 percentage points across the board. The labeling platform cost us more money per annotation but the data quality difference was enormous.
Where To Start If You Have To Build Something
Don't start by building a custom pipeline. Start with an off-the-shelf model and a well-defined task. Pick something like sentiment classification on your own data, or named entity recognition on documents you already have. Use a Hugging Face Transformers model, fine-tune it with the Trainer API, and evaluate it properly using the metrics I described above. Once you have a working baseline, you can iterate from there. Most teams that I see fail are the ones that try to customize everything before they've proven the basic approach works on their data. If you need to handle long documents, look into sliding window approaches with overlap or models designed for long sequences like Longformer or BigBird. These trade off some accuracy for the ability to process thousands of tokens at once, which is necessary if your use case involves full legal contracts or technical manuals. We use a sliding window approach with a mean pooling aggregation step on top of a standard BERT model for our contract review pipeline. It's not state-of-the-art but it handles our document length requirements and it's fast enough for daily batch processing. Deployment is another area where people dramatically overthink things. A fine-tuned model wrapped in a FastAPI endpoint with a simple request-validation layer will serve most production needs. You don't need Kubernetes orchestration on day one. You need monitoring, and that means logging predictions alongside the inputs so you can detect drift. We set up a simple pipeline that saves every prediction and the corresponding input to a database, and we run a weekly comparison of input distributions against the training set. When the divergence crosses a threshold, we know it's time to retrain or collect fresh labeled data.
The field moves fast but the fundamentals don't change much. Understand your data, pick the simplest model that could work, evaluate honestly, and iterate. The hype around generative NLP models is real but it's also noisy. The systems that actually ship and provide value are usually the ones built by people who understand when not to use the newest tool.