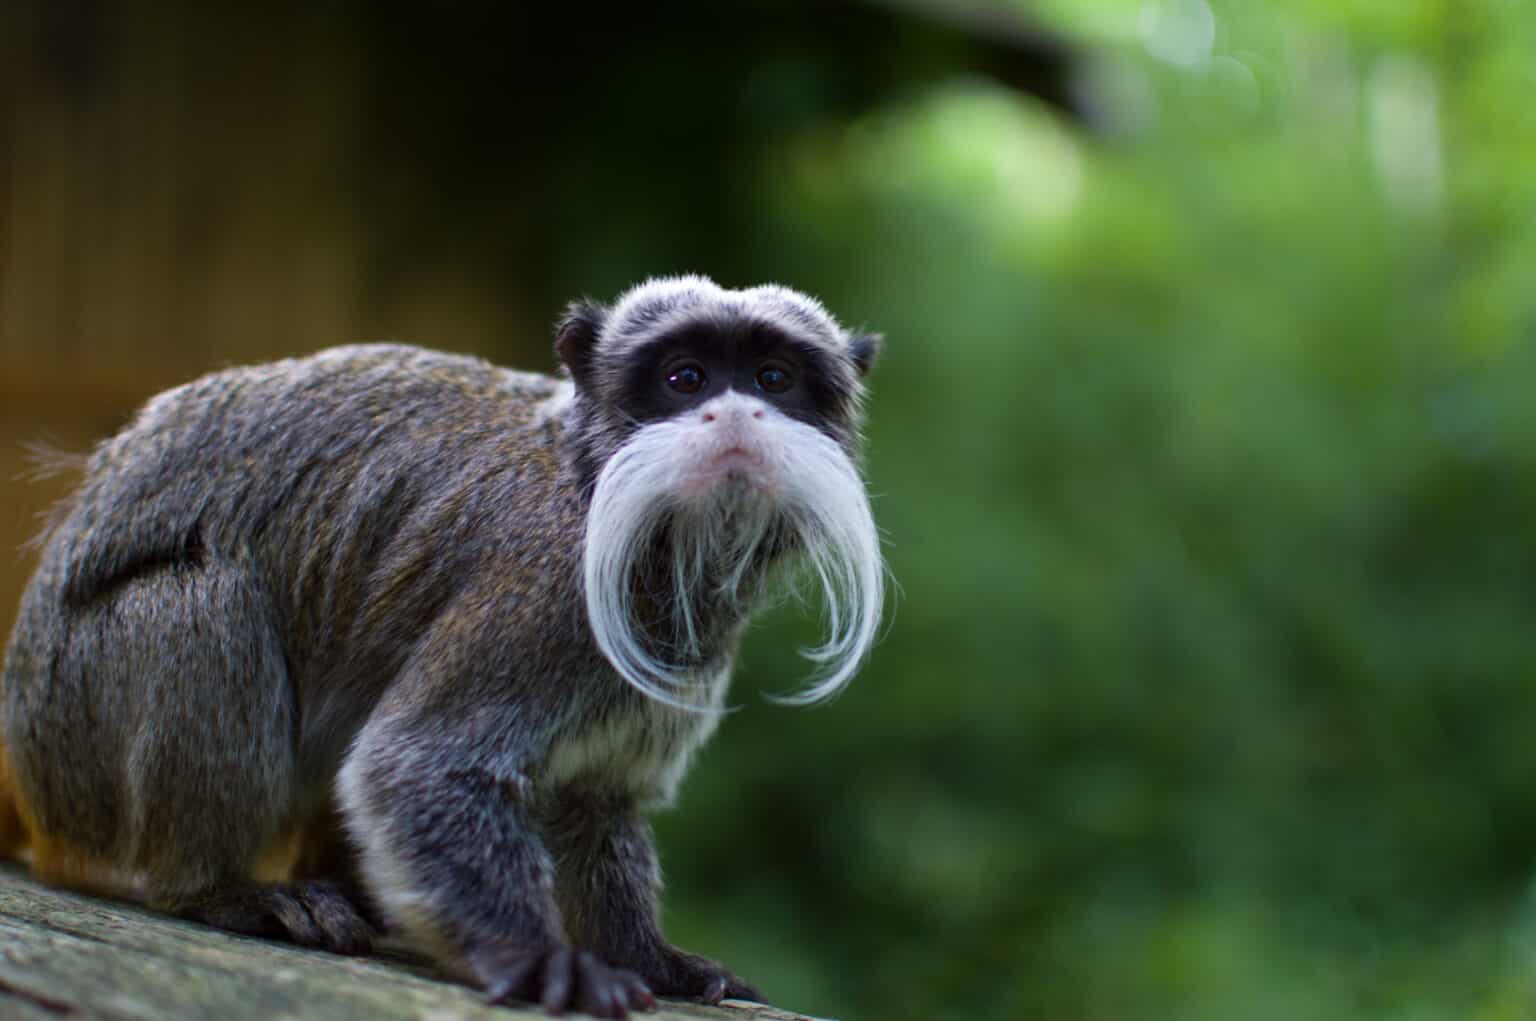
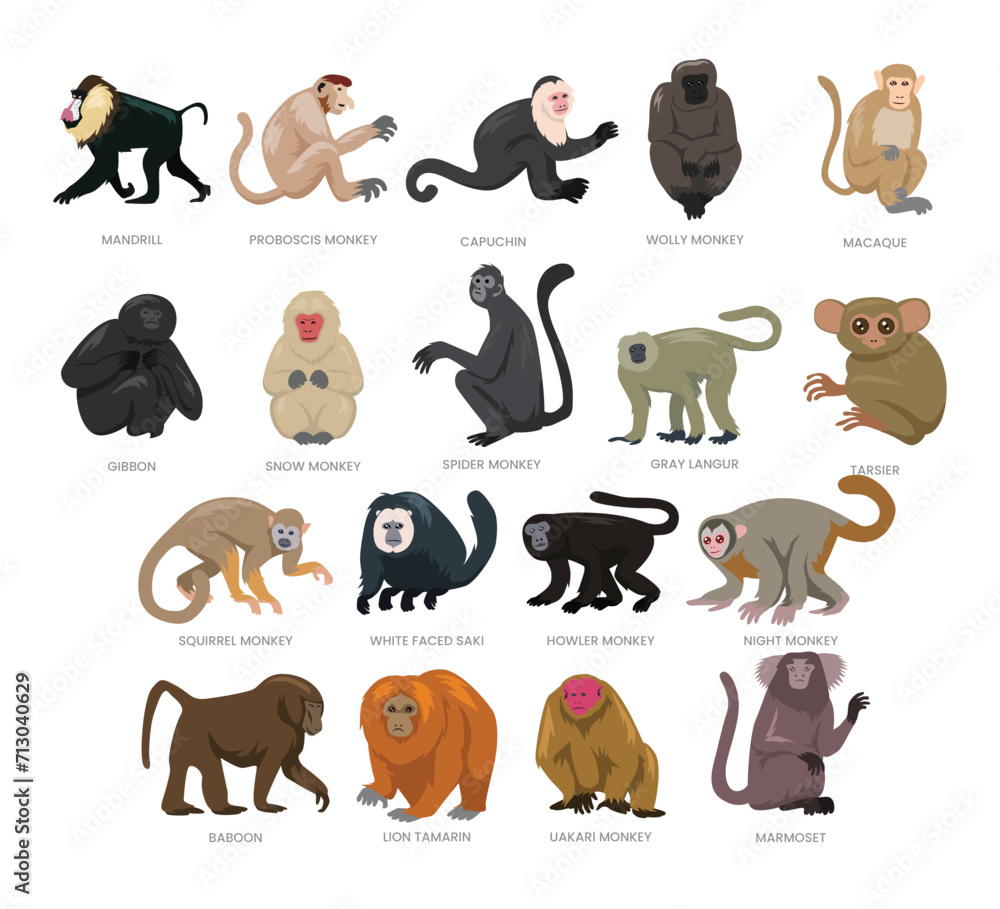
Species Trait Assessment: Where It Actually Works and Where It Falls Apart
Most people approaching monkey conservation don't realize how fragmented the available data actually is. You want to assess species traits for a paper, a grant application, or a habitat management plan, and you open up the IUCN Red List only to find that several genera have fewer than three field studies supporting their trait databases. This isn't a problem you solve by reading more. You solve it by knowing where the gaps are before you start writing. I spent about four years cross-referencing primate trait data across Southeast Asian lowland forests. The first thing you learn is that no single database covers everything. The Global Mammal Assessment gives you distribution ranges. The Primate Info Net gives you behavioral notes. The IUCN gives you threat classifications. None of them give you reproductive timing, home range size per habitat type, and diet composition in the same place. When I was compiling a trait matrix for a conservation zoning project in Kalimantan, I had to pull from seven different sources just to get reasonable coverage for two out of twelve species I was studying. One source that saved me from wasting weeks was the published trait database compiled by Scharlemann and colleagues at the University of Birmingham, which standardized over 400 mammal species but still left several macaque species with thin data. My workaround was reaching out directly to zoo curators who had handled those specific species for collection management purposes. They kept records that never made it into peer-reviewed literature.
The Ultimate Guide To Monkey Breeds Understanding Species Traits And Conservation
There is no single document that covers everything you need. What exists are overlapping frameworks, and the skill is in knowing which one to prioritize depending on your goal. If you are doing threat classification work, the IUCN criteria framework is the standard. If you are modeling habitat requirements, the ecopath and niche modeling databases are more useful. If you are building a captive breeding program, the SSP and EAZA studbook records are where you actually need to look. Let me walk through how this works in practice. Say you are trying to determine whether a particular lemur species qualifies for upgraded protection status. You start with the IUCN population trend data, which for many lemurs is estimated from habitat loss rates rather than direct census counts. That alone is insufficient. You then layer in life history traits: age at sexual maturity, litter size, interbirth interval. These traits determine how quickly a population can recover from decline. Species with long interbirth intervals and late sexual maturity, like the greater spot-nosed monkey, are structurally more vulnerable to hunting pressure than species with shorter reproductive cycles, regardless of current population numbers. This is a counter-intuitive point that most initial assessments miss. People look at the headline population figure and stop there. The trait data tells you what that figure actually means for survival trajectory. Another thing that trips people up is the assumption that range maps are stable. They are not. Range maps are updated infrequently, often decades apart, and they reflect historical knowledge more than current occupancy. I once pulled a range map for a colobus species that showed continuous forest cover across an area that had been converted to oil palm plantation ten years prior. The map hadn't been revised. Using outdated range data for a conservation priority assessment would have sent that species the wrong kind of attention entirely. The workaround is to check the most recent primary literature for range updates before relying on any static map.
When you are working with Old World monkeys specifically, there is a taxonomy problem that makes trait comparison harder than it should be. Several genera have been reclassified in the last fifteen years based on genetic analysis. The old classifications are still used in older databases, so a species might appear under a different genus name depending on which source you consult. The black-and-white colobus, for example, has undergone several taxonomic revisions that split and lumped populations in ways that don't always align between the IUCN and the academic literature. If you are building a dataset and your species count doesn't match between sources, this is usually why. Check the scientific name version date on each entry. For New World monkeys, the trait data tends to be even thinner for the smaller, less charismatic species. Marmosets and tamarins make up a large portion of Neotropical diversity, but most of the published behavioral and ecological data concentrates on a handful of well-studied species. The rest are largely extrapolated from related genera. This is acceptable for broad regional assessments but becomes a liability if you are making species-specific management recommendations. In my experience, the error rate on extrapolated trait values for unstudied marmoset species runs around twenty to thirty percent when validated against later field studies. That margin matters when you are designing a reintroduction protocol. Conservation planning that relies on trait data alone without field validation tends to overestimate resilience in specialist species and underestimate it in generalists. Specialist frugivores with narrow home ranges look vulnerable on paper, which they are, but generalist omnivores that can persist in fragmented habitats often get overlooked because their current population numbers appear stable. Both scenarios happen regularly. The fix is to combine trait-based risk modeling with actual sightrate surveys in the target area. One gives you the structural vulnerability profile. The other tells you whether the species is actually declining in that specific landscape.
Get the Full Details

If you are starting from scratch and need a comprehensive baseline, the most reliable open resource I have found is the combination of the IUCN Red List API, the PanTHERIA database for mammalian life history traits, and the published literature from International Journal of Primatology and Primates. Cross-referencing those three will cover roughly eighty percent of what you need for most conservation assessments. The remaining twenty percent usually requires direct contact with field researchers or zoo collection managers, which is slower but often necessary for species with limited publication histories. The hard limit of this approach is that trait databases are only as good as the underlying observations. There is a geographic bias toward South American and African species with heavy investment in primate research institutions. Southeast Asian and Indonesian species remain significantly underrepresented. If your work focuses on those regions, plan for extra time spent locating primary source material rather than relying on compiled databases. It will cost you approximately two to three weeks per poorly documented species to build a trait profile that matches the quality of better-studied regions. That is the reality of the current data landscape, not something you can work around without accepting a higher uncertainty margin in your final assessment.