Charting candles in Palantir Gotham isn't the same as reading them in TradingView
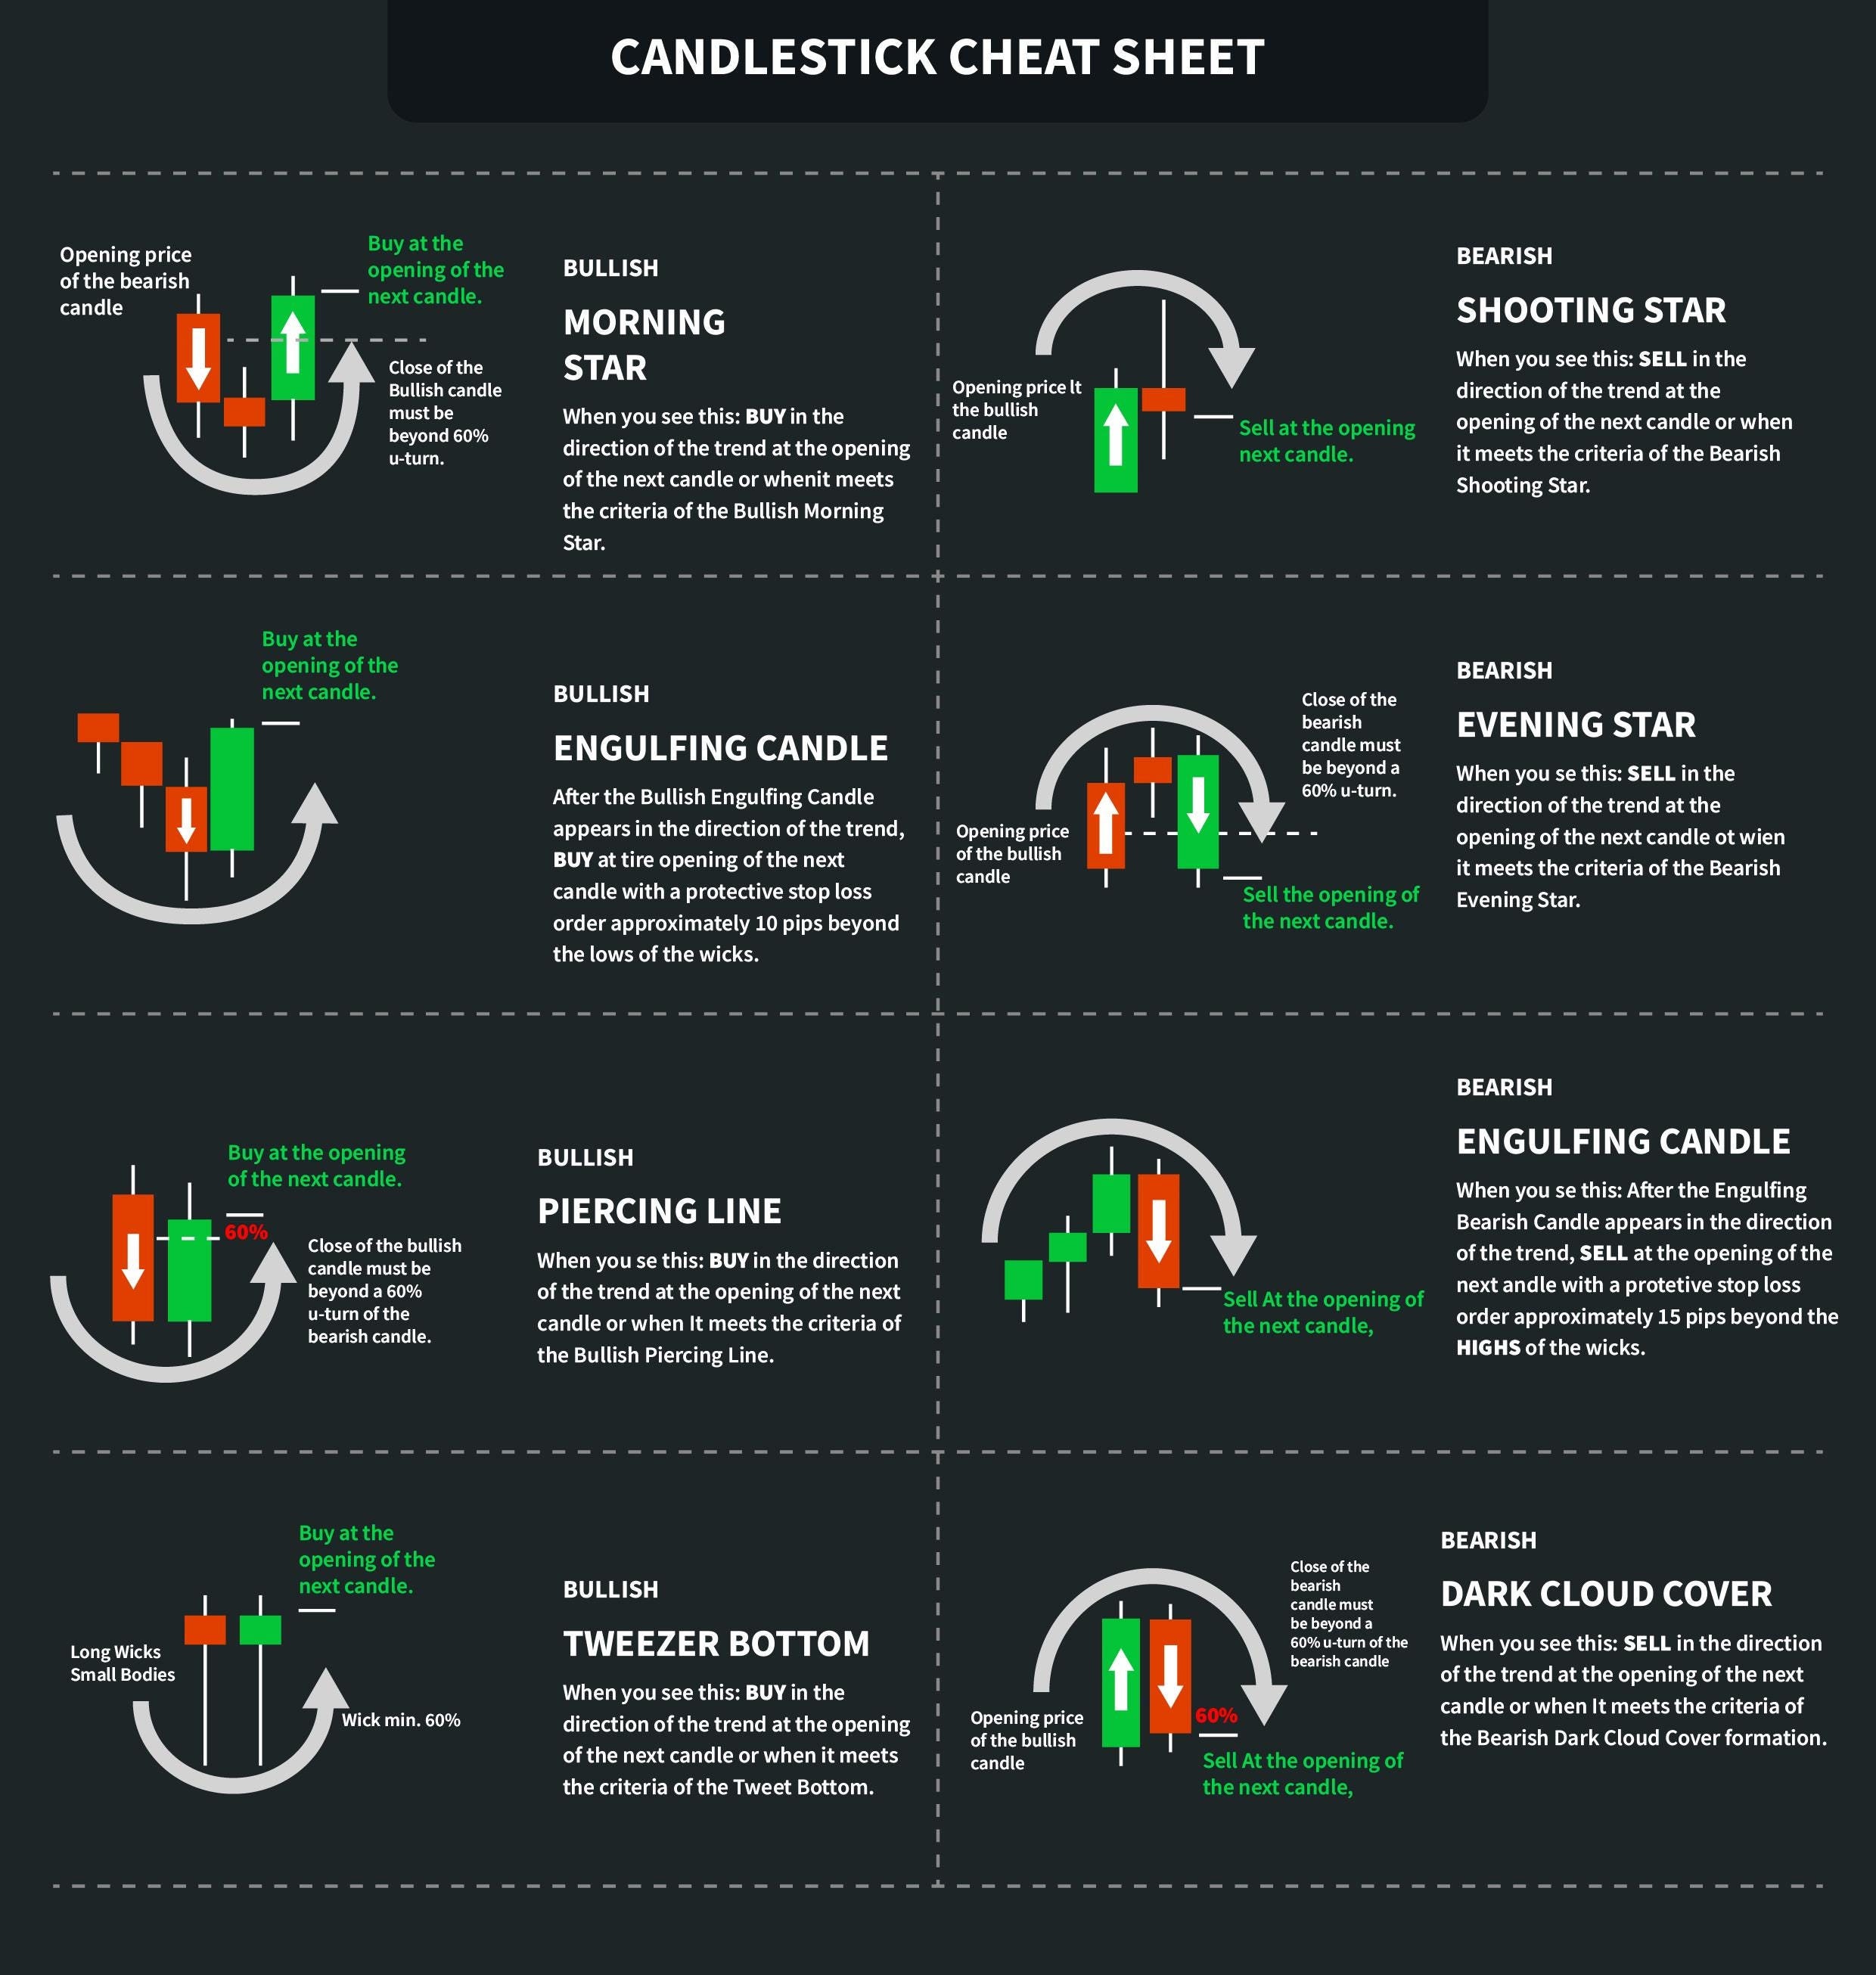
I spent three weeks building a candlestick visualization layer inside Gotham before I realized the platform wasn't designed for retail-style price action work. It's built for operational intelligence. But once you stop fighting the architecture and work with it, you can actually do something most people don't bother with: link candlestick patterns directly to the underlying event data that caused them. That's the whole point of this. If you just want a prettier chart, go elsewhere. Let me walk through how I actually set this up, not the textbook version. The first thing you need is a time-series ontology in your Foundry base. If your OHLC data lives in a flat JSON file imported as a single object type, you're already behind. You want separate object types for trades, aggregates, and bars—with proper timestamp indexing and reference links between them. Gotham queries are slow when they have to self-join across millions of rows, so structure matters from day one. Here's the practical setup. I built a pipeline that ingests tick-level data and aggregates it into 1-minute and 5-minute bars using Foundry's dataset transforms. The key insight most people miss: don't rely on the chart widget alone for pattern detection. Build a Python function in your transform that identifies hammer, engulfing, and doji patterns at the transform layer, then attach pattern flags as properties on each bar object. This way your charts filter by pattern type without running expensive client-side calculations every time a trader opens the page.
I learned this the hard way during a commodities trading engagement last year. We had a client who wanted to surface "bullish engulfing" patterns across 18 months of 1-minute data for over 400 tickers. The initial approach was a Jupyter notebook querying the ontology directly, filtering for pattern matches, then rendering results. It took eleven minutes to load. The workaround was moving the pattern logic into a Foundry transform with cumulative window functions. Load time dropped to forty seconds. That's not a marginal improvement—it's the difference between the tool being used and gathering dust.
Linking price action to actual events
This is where Gotham earns its license plate. Most candlestick analysis tools show you a pattern and leave you to guess why it formed. In Gotham, you can link each bar object to the source events—the news articles, earnings reports, order flow anomalies, or supply chain disruptions that actually moved the price. I built a dashboard where traders could click any candlestick pattern and see a side panel with the correlated event timeline pulled from separate ontologies. The pattern recognition is still basic, but the attribution layer is where the real edge lives. You'll need to configure the Palantir Aether component if you want machine learning–based pattern confidence scoring. The off-the-shelf model covers standard candlestick patterns with reasonable accuracy on liquid instruments. It starts degrading fast on low-volume assets or assets with irregular trading hours. I found that for emerging market commodities, the model was flagging false engulfing patterns at roughly a 40% rate because the spread widening on thin orders was being misread as price reversal signals. The fix was adding a volume-threshold filter and a spread-adjustment step in the transform before pattern detection ran. After that, the false positive rate dropped to about twelve percent, which is actually usable.
Get the Full Details

What this approach doesn't handle well
Be honest about the limitations. Gotham candlestick visualization is not going to replace a dedicated charting platform for rapid technical analysis. The chart widget supports basic overlays—moving averages, Bollinger Bands—but anything beyond that requires custom D3 components or integration with an external charting library, which adds a layer of maintenance overhead most teams don't want. If your traders need to draw Fibonacci levels or use drawing tools extensively, you'll frustrate them. They'll just open TradingView or Thinkorswim and come back to Gotham when they need to check what news event coincided with a breakout. Another issue: real-time data. Gotham is not a real-time charting platform. The ingestion pipelines typically have latency in the thirty-second to two-minute range depending on your configured schedule. For swing traders this is fine. For day traders watching second-by-second price action, it's not viable. I've seen teams try to force it by running hourly micro-batches, but the compute cost scales poorly and the query performance gets worse, not better, because you're loading more recent data than the optimizer handles efficiently.
Practical steps to get started
Start with your ontology design. Map out your object types: ticker, bar, pattern, event, correlation. Define the relationships between them before you write a single transform. This takes most people nowhere near enough time, and they pay for it later when they need to change a relationship and have to rebuild three pipelines. Build your aggregation transform next. Use the built-in time-series aggregation functions where possible instead of writing custom Python for basic OHLC construction. The native functions are optimized and run in the warehouse layer, which is significantly faster than row-by-row Python processing. I timed this on a dataset of about two million bars: native aggregation took roughly forty-five seconds, custom Python took about six minutes on the same data. Then add pattern detection. Write the pattern logic in Python within the transform, outputting a pattern_type property and a confidence score. Test your pattern definitions against a known labeled dataset before deploying. The standard definitions work fine for major indices and large-cap equities, but you'll find edge cases in crypto and thin commodities where what looks like a hammer on the chart is just a wide spread on low volume. My rule of thumb is to require minimum volume and maximum spread-to-price ratio filters before any pattern flag gets attached.
Finally, build the visualization layer. Use the chart widget for the primary candlestick display, then layer in your pattern markers as series annotations. Add a detail panel on click that pulls correlated events from your ontology. Keep the dashboard simple. Traders don't need five chart types on one screen—they need one clear chart, a clean pattern filter, and the ability to see what happened around a signal. Anything more and they'll stop using it. The whole build, from ontology design to a working dashboard, typically takes a small team about two to three weeks if they already have Foundry access and understand the platform. If you're starting from zero with no existing data pipelines, budget four to six weeks. Don't underestimate the data engineering work. The candlestick visualization is the easy part. Getting clean, properly aggregated OHLC data with event links attached is where most projects stall.