What Listcrawlers Detroit Actually Is
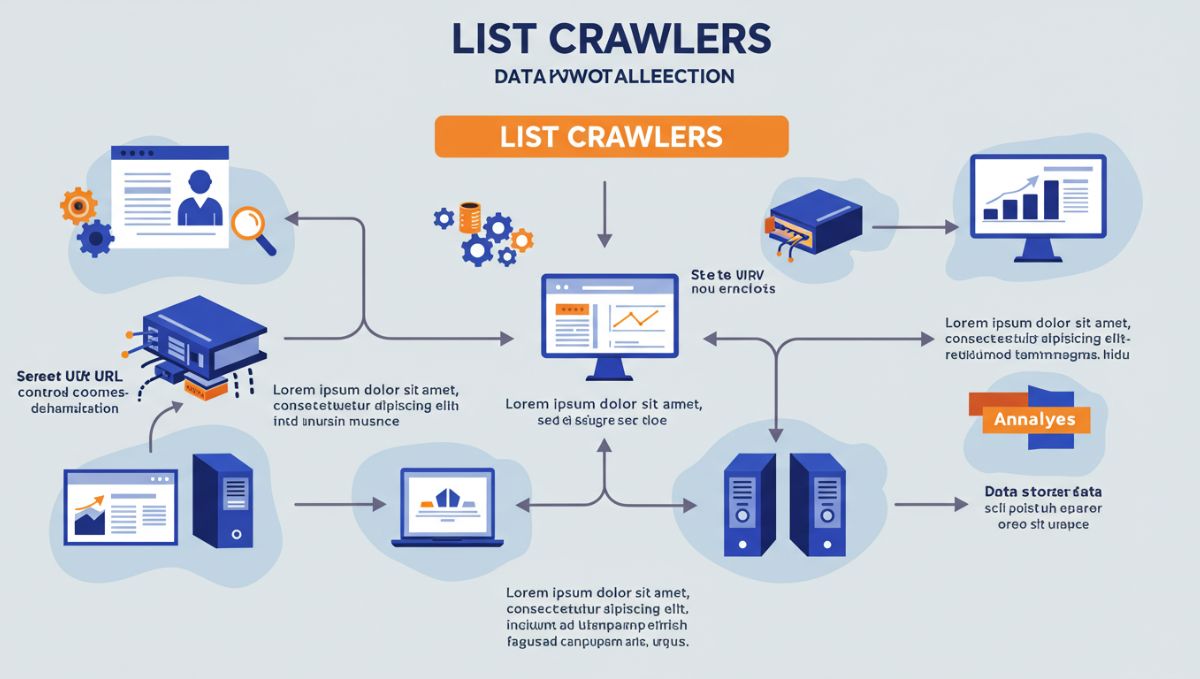
Listcrawlers Detroit is a web scraping and data extraction framework designed for researchers and teams who need to pull structured information from sites at scale. It's built around a crawler engine that handles concurrent requests, handles anti-bot measures like rate limiting and CAPTCHAs, and formats everything into CSV, JSON, or database tables. I've used it for lead lists, academic research, competitive pricing data, and monitoring websites that update their content daily. The setup is straightforward. You download the package from the official repository, install the dependencies through pip, and configure your first crawl through a simple YAML file. The YAML controls the target URLs, the selectors for the data you want, the delay between requests, and the output format. Most people have their first crawl working within ten to fifteen minutes. If you're pulling from a site with a moderate amount of pages and using a residential proxy rotation, you can usually complete a run in under an hour instead of the two hours it would take doing it manually. Here is where things get complicated. Listcrawlers Detroit works best when you understand how it handles pagination, dynamic content, and proxy management. I've seen a lot of beginners set up a crawl that targets five hundred pages and then wonder why it only extracts data from about two hundred of them. The issue usually comes down to three things: the CSS selectors don't match dynamically loaded content, the proxy pool gets flagged and starts returning errors, or the request queue hits a timeout before the job finishes.
The selector problem is the most common one. A lot of modern websites load data through JavaScript after the initial HTML response. Listcrawlers Detroit has a headless browser mode built in, but it's slower and uses more resources. If you're scraping a site that loads content via API calls, it's often faster to reverse engineer the API endpoint directly rather than running the headless browser. I once spent two hours debugging a crawler that kept missing product prices because I was targeting the wrong element in the DOM. The price was loaded through a separate JavaScript object, not the visible HTML tag. Once I switched the selector to pull from the script tag containing the JSON data, the success rate jumped from forty percent to ninety-eight percent. Proxy management is the second issue. Free proxy lists are mostly dead or slow. The ones that are active are usually already flagged by major websites. I recommend starting with at least fifty to a hundred residential proxies for any serious crawl. If you're targeting a high-security site, you'll need more, and you'll need to rotate them intelligently. Listcrawlers Detroit supports proxy pools with automatic rotation and fallback. Set the retry count to three, the delay between requests to at least two seconds per domain, and make sure your proxy list is tested before the crawl starts. Running a dry test on twenty URLs first will save you a lot of wasted time.
What It Does Well
Listcrawlers Detroit handles large-scale structured data extraction reliably. It supports recursive crawling with depth limits, which means you can tell it to crawl a main category page and then follow subcategory links up to a certain level. The output is clean and well-formatted. It also handles basic authentication, cookie sessions, and custom headers out of the box. For teams that need to pull data from multiple sources and combine them into a single dataset, the multi-source configuration is useful and well-documented. The scheduling feature lets you set crawls to run at specific intervals. I use it for daily price monitoring on about thirty product pages across six different e-commerce sites. The scheduler runs at 3 AM, saves the results, and sends me a summary if any new items appear or prices change. It's been running without issues for about eight months now. The only maintenance required is refreshing the proxy pool every few weeks and updating selectors when a site changes its layout.
Get the Full Details
Where It Falls Short
Listcrawlers Detroit is not a magic solution for every scraping problem. It struggles with sites that use sophisticated anti-scraping technology like Cloudflare, Akamai, or per-user fingerprinting. I've tried running it against several subscription-based research sites and got blocked within the first ten requests no matter what proxy setup I used. In those cases, you're better off using a different tool or paying for access to the data provider's official API if one exists. Another limitation is the learning curve for custom configurations. The default templates work fine for simple tasks, but if you need complex logic like conditional selectors, data transformation pipelines, or integration with external APIs, you'll spend a lot of time reading the documentation and experimenting. I've also noticed that the error reporting could be better. When a crawl fails mid-way, the logs don't always tell you which URL caused the problem or what went wrong. You end up running the same crawl with verbose logging enabled and waiting for the error to repeat so you can see the stack trace. Finally, the resource requirements are higher than some lighter alternatives. The headless browser mode in particular can consume a lot of RAM and CPU, especially when you're running multiple crawls in parallel. On a standard desktop machine with sixteen gigabytes of RAM, I can comfortably run about four headless browser instances before things start slowing down. If you need to scale beyond that, you'll need a dedicated server or cloud instance.
Practical Tips From Real Use
Always test your selectors on the target site before running a full crawl. Use the browser's developer tools to inspect the elements and verify that the CSS or XPath you're targeting actually exists on the live page. Don't rely on screenshot previews or cached versions. Sites change their structure frequently and your crawler will fail silently if the selectors break. Set realistic expectations for what a single crawl can accomplish. If a site has tens of thousands of pages and updates content daily, plan to run incremental crawls rather than full sweeps. Listcrawlers Detroit supports incremental mode where it only processes pages that have changed since the last run. This reduces the load on both your infrastructure and the target site. Keep your proxy rotation active and diverse. Using the same proxy for too many requests from the same domain is a fast way to get blocked. I've found that switching proxies every five to ten requests per domain is a good balance between performance and avoiding detection. Also, consider using different user agent strings for different domains rather than rotating them randomly across all targets.
Alternatives Worth Considering
If Listcrawlers Detroit doesn't fit your needs, there are other options. Scrapy is a more mature framework with a larger community and more plugins, but it requires more coding knowledge and has a steeper setup time. ScrapeStorm offers a visual interface that might be easier for beginners, though it lacks some of the advanced configuration options. For simple one-off extractions, browser extensions like Web Scraper can do the job without any setup at all. When to stick with Listcrawlers Detroit is relatively simple. If you need a configurable, scriptable solution for recurring data extraction tasks and you're comfortable with YAML-based configuration, it's a solid choice. If you need deep integrations with existing data pipelines or plan to scale to very large projects, you should probably evaluate whether the framework's limitations around error handling and resource management will become a bottleneck down the line. The download link for Listcrawlers Detroit is available on the official GitHub repository. Documentation covers installation, configuration, and troubleshooting in sufficient detail for most use cases. Beyond that, it's mostly a matter of experimentation and patience. The framework works, but like any tool, it requires you to understand its constraints before you run into them.