
Comparing PDFs is a pain and the tools keep breaking on you
I spent three weeks last quarter trying to diff two versions of a legal contract that someone had re-uploaded through a third-party portal. The original was a cleanly typed Word export. The new one was a scanned multipage form with OCR garbage hiding in the margins. Every tool I tried — Adobe Compare Files, DocuDiff, even a Python script using pdfminer.six — spat out false positives from the scan noise. The only thing that worked was exporting both to plain text with a careful layout-preserving converter and then running a strict unified diff on the cleaned strings. So here is what I have learned from doing this more times than I would like to admit.
The Ultimate Guide To Compare PDF Documents Tools Methods And Best Practices For Precision
Before you pick a method, you need to know what kind of PDF you are looking at. That matters more than which tool you install. A PDF generated from LaTeX or Word will compare very differently from a scanned image with an invisible OCR layer. The structure inside the file tells you whether byte-level comparison makes sense or whether you need to extract text first and accept some lossiness. PDFs are not documents in the way a Word file is. They are drawing instructions with optional text layers. When you open two versions and ask a tool to compare them, the tool has to decide what counts as a change. Did the font shift by two points? Did the text reflow because the margin changed by a quarter inch? Did someone move a signature block six pixels to the right? I encountered this exact problem when comparing two building-code PDFs where the only real difference was a table that had been shifted down half an inch because the header paragraph was one word longer. The visual diff highlighted the entire page as changed. What I actually needed was semantic comparison focused on the code references, not the layout. I solved it by running both through a text extraction step with whitespace normalization and then using a custom script to diff only lines containing the target keywords. It took about twenty minutes to set up and saved me from marking an entire chapter as modified when nothing in the code language had changed.
Methods that actually work
Visual pixel-based comparison
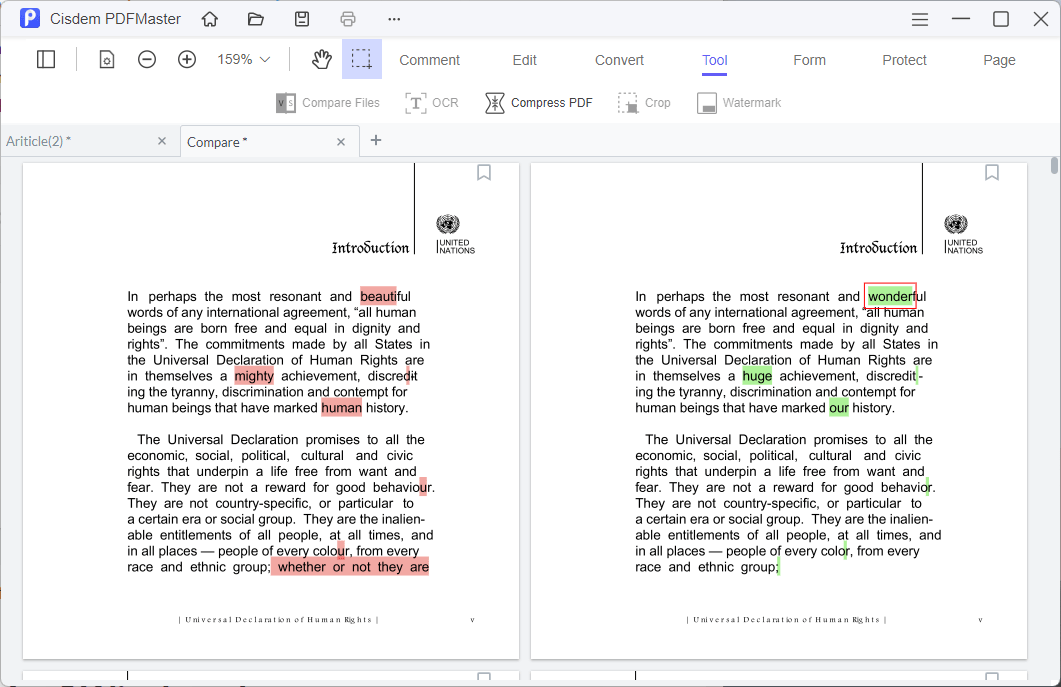
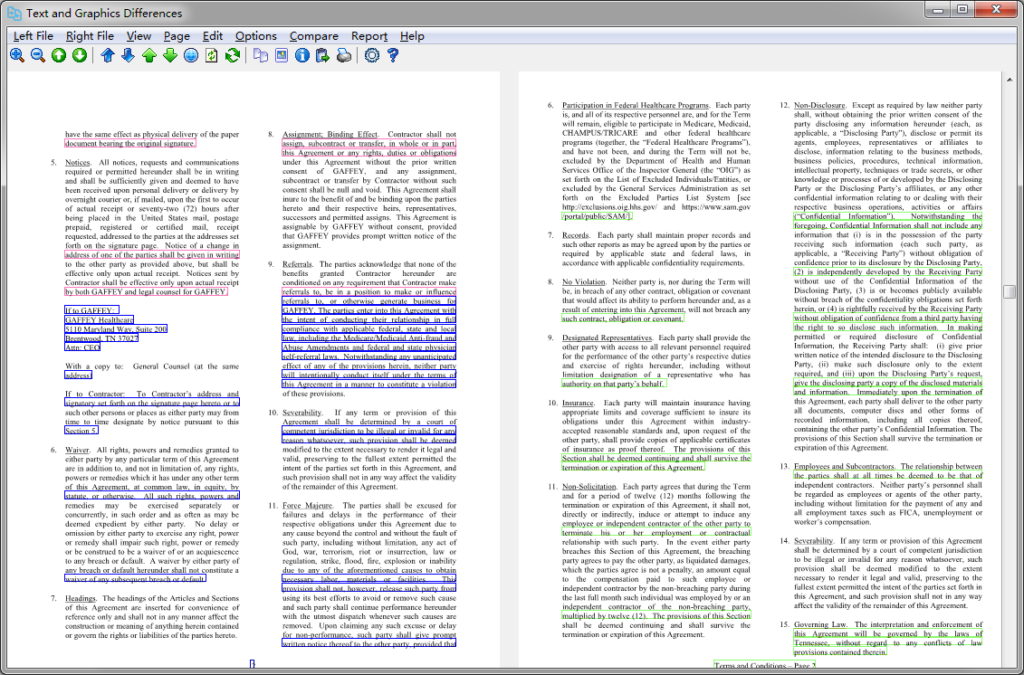
This is what most people reach for first. You open two PDFs side by side and look for differences. Tools like Adobe Acrobat Pro's Compare Files feature do this under the hood. It renders both documents and highlights regions that differ beyond a configurable tolerance. The problem is that pixel comparison is fragile. A reflowed page, a different PDF producer, or an embedded font with slightly different hinting can make the entire page light up red. It also misses changes that do not affect rendering, like metadata updates or hidden structural edits. I use this method only when I need to prove visually that two versions differ for a non-technical audience. For actual precision work, it is too noisy.
Get the Full Details
Text extraction and lexical diff
This is the method I use most often now. You extract the text content from both PDFs, normalize whitespace, and run a standard diff tool. The output is a clean list of additions, deletions, and modifications. The challenge is text extraction quality. Some PDFs store text in unpredictable orders, especially multi-column layouts or documents with complex tagging. You can get jumbled output that looks like changes when nothing changed. I learned this the hard way with a technical manual that used a two-column layout for definitions and examples. The default extractor interleaved the columns in a way that made every paragraph look reordered. The workaround was to use pdfplumber instead of pdfminer, which respects the column structure better for most layouts. After extraction, I strip out common boilerplate using regex patterns for things like page numbers, footers, and document control numbers. Then I normalize whitespace by collapsing runs of spaces and trimming each line. The diff step itself is trivial with any standard tool — diff, UnifiedDiff, even a Python difflib call. This usually cuts the process down from two hours of manual review to about fifteen minutes of scripted output, depending on document size and complexity.
Structural comparison via PDF internals
For power users who need to catch hidden changes, you can compare the PDF structure directly. This means looking at the object stream, the cross-reference table, and the page resources. Tools like pdftk, qpdf, or specialized diff tools can show you when objects are added, removed, or modified at the low level. This method catches things that text extraction misses. Someone could change a hyperlink destination without touching the visible text. A form field could have its required flag flipped. A digital signature reference could be swapped out. I used this approach when investigating a suspicious invoice PDF where the text looked identical but the payment details had been altered in a way the visual comparison did not reveal. The downside is that structural comparison produces extremely verbose output. A well-formatted PDF might have thousands of objects, and most of them will be unchanged boilerplate. You need good filtering to make sense of the result. I typically pipe the structural diff through a filter that highlights only changes in specific key areas like annotations, form fields, and page content streams.
Hash-based comparison
If you just need to know whether two PDFs are identical, compute a hash of each. SHA-256 is fine for this purpose. If the hashes match, the files are byte-for-byte identical. If they differ, something changed but you do not get details. This is useful in pipeline automation where you are checking whether a newly received PDF is a duplicate of one you already processed. It is not useful for finding what changed. I recommend combining hash checking with text extraction: compute the hash first, and if it differs, run the text comparison pipeline automatically. This saves time by skipping the expensive extraction step for identical files.

Tool recommendations
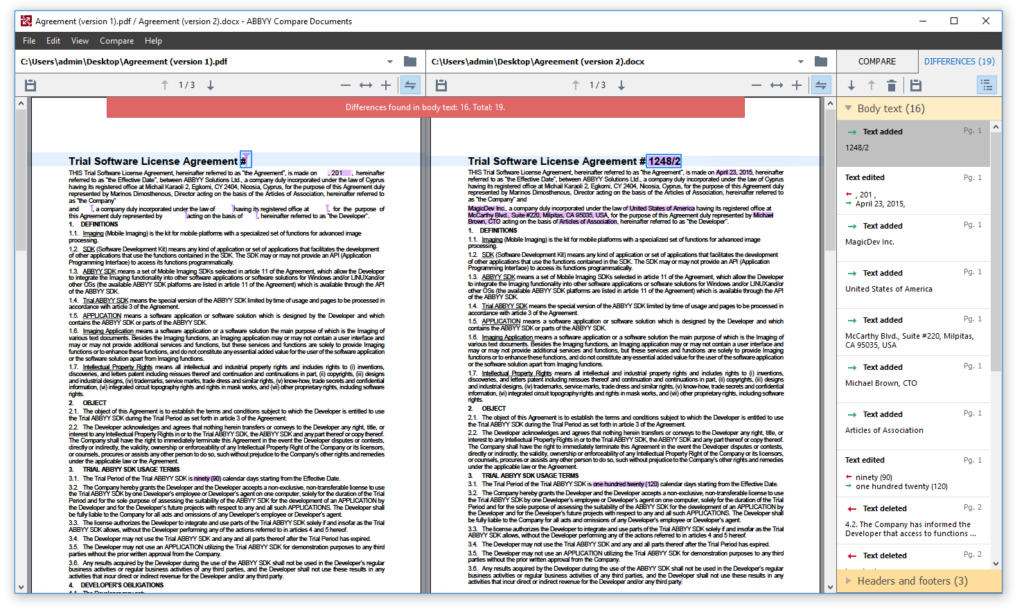
There is no single perfect tool for this job. The best approach depends on your threat model, your document types, and how much precision you need. For legal and compliance work where audit trails matter, Adobe Acrobat Pro's Compare Files feature is the industry standard. It is expensive and sometimes produces noisy output, but it generates a formal report that holds up in procedural contexts. I use it when the deliverable needs to be shown to a third party who does not trust custom scripts. For internal precision work, a combination of pdfplumber for extraction and a proper diff engine gives you the best signal-to-noise ratio. The open-source path costs nothing and runs on any system with Python installed. The tradeoff is that you need to maintain your own extraction and filtering logic, which can drift when document formats evolve.
For high-volume automated comparison, consider a dedicated service like Diffchecker's PDF comparison or commercial solutions like Kofax Capture's diff module. These are engineered for throughput and handle edge cases you will not think to test for until a production incident forces you to. For forensic analysis where hidden structural changes matter, qpdf combined with a custom extraction pipeline gives you the deepest visibility. I keep a small wrapper script around qpdf that outputs object-level diffs in a human-readable format. It is not pretty but it works reliably for the cases where standard tools fail.
Common pitfalls
The first mistake people make is assuming two visually similar PDFs are the same. They are not. A PDF can look identical on screen while containing completely different embedded fonts, metadata, or form field structures. The second mistake is trusting text extraction without verification. I once compared two versions of a software license agreement where the extracted text showed no meaningful changes. A subsequent structural comparison revealed that a critical liability clause had been replaced with a functionally equivalent but legally distinct clause in a different font. The text matched because the words were the same but the legal meaning shifted due to a carefully worded modification. This happened because I stopped at the text layer without digging into the page content streams. The third mistake is ignoring the extraction ordering problem. Multi-column documents, tables, and complex layouts will produce jumbled text if you do not account for reading order. Always inspect the raw extraction output before running a diff. A quick visual scan of the first few hundred lines will tell you whether the extractor preserved the logical flow.
Best practices I follow
I start every comparison task by classifying the PDF type. Is it text-native, scanned with OCR, or a hybrid? Is it a form, a report, or a legal document? The classification determines which method I use first. Text-native documents go straight to extraction and diff. Scanned documents require OCR comparison or structural inspection since the text layer may be incomplete or inaccurate. Second, I always run a hash check before investing time in deep comparison. If the files match at the byte level, I document the hash and move on. This simple step eliminates a large percentage of comparison tasks that turn out to be duplicates. Third, I normalize extraction output before diffing. This means stripping whitespace variation, removing common boilerplate headers and footers, and handling known encoding quirks. The normalization step is where most precision comes from. A poorly normalized comparison will highlight differences that do not matter and miss differences that do.
Fourth, I verify critical findings by spot-checking at least three random differences against the original PDFs. Automated tools make mistakes, especially with complex layouts or unusual character encodings. Spot-checking catches extraction artifacts and false positives before they propagate into a report. Fifth, I document the comparison methodology. The tools, parameters, and normalization steps you used matter for reproducibility. If you need to rerun the comparison later or defend the results to someone else, having a written record of your process is essential. I keep a small markdown file next to each comparison output that records the tool version, the extraction settings, and any manual interventions.
When to use what
Quick duplicate check: hash comparison. Takes seconds and tells you everything you need to know about identity. Legal document review: structured extraction plus diff with boilerplate filtering. Add visual spot-checking for the final report. This combination caught a material clause change in a vendor contract last year that a purely visual review missed because the change was buried in a footnote reference. Forensic analysis: structural comparison with qpdf or equivalent, plus extraction and diff for the text layer. Use this when you suspect deliberate tampering or when the visual appearance might be misleading.
High-volume batch processing: automated pipeline with hash prefilter, text extraction, normalization, and diff. Monitor false positive rates and adjust your filters based on the document population you are processing.
Edge cases that break standard approaches
Encrypted PDFs are the first category. If a document is password-protected, most comparison tools cannot access the content. You need the password or a legal right to bypass the restriction. I have seen cases where the comparison was impossible because the PDF was encrypted with an unknown password and the document owner was unavailable. PDFs with embedded fonts that substitute glyphs differently across renderers are another category. The text content is identical but the visual appearance differs because the renderer chose a fallback font. This is common with complex mathematical notation or specialized symbol sets. Pixel-based comparison will flag these as differences even though the semantic content is unchanged. Portable document format versions matter too. A PDF-1.7 document and a PDF-2.0 document with identical content may produce different object structures and thus trigger false positives in structural comparison. I learned this when comparing two versions of a standards document where one was saved in an older PDF format and the other in the latest revision. The content was the same but the internal representation differed enough to confuse several tools.
Digital signatures complicate comparison significantly. A signed PDF may appear unchanged while the signature value itself changed because of a timestamp refresh or a certificate update. Or the document content may have been altered after signing, which should invalidate the signature but some tools do not check for this automatically. Always verify signature validity alongside content comparison when dealing with signed documents.
Final thoughts
PDF comparison is a balancing act between precision and practicality. No method catches everything. No tool handles all document types cleanly. The best approach combines multiple methods and validates the output with human inspection on the critical sections. I recommend starting with hash comparison to eliminate duplicates, then moving to text extraction and diff for the bulk analysis, and finally applying structural comparison for documents where hidden changes matter. The total time investment depends on your document population and the precision requirement, but a well-tuned pipeline can reduce what used to take hours of manual review to minutes of automated processing with a manageable verification overhead. The tools available today are good but not perfect. They require configuration, validation, and sometimes creative workarounds for edge cases. If you are doing this professionally, invest in building your own pipeline rather than relying solely on commercial tools. The maintenance burden is real but the precision payoff is worth it when the stakes are high.
