What You Actually Need When You Build A Node.js Backend
I spent three years debugging production issues that came from skipping the basic architecture decisions most tutorials gloss over. The difference between a backend that survives its first month and one that collapses under real traffic usually has nothing to do with whether you picked Express or Fastify. It comes down to how you handle errors, structure your modules, and manage async operations without accidentally blocking the event loop. Most people start by scaffolding an Express project and immediately write route handlers that mix database calls, business logic, and response formatting in the same function. This works fine until you have twelve routes and someone asks you to add authentication to half of them. Then you realize you never separated concerns and you are refactoring at 2 AM on a Tuesday.
The Ultimate Guide To Building A Robust Nodejs Backend Starts With Structure
Before you write a single route, decide on your directory layout. Here is a structure that actually holds up past the prototype stage: src/controllers handles incoming requests and returns responses. src/services contains your business logic. src/models defines your data schemas. src/middleware contains reusable request processors. src/routes wires controllers to paths. src/utils holds pure helper functions that do not depend on any framework. Keep controllers thin. They should validate input, call a service, and return a response. If a controller needs more than three lines of actual logic, that logic probably belongs in a service. I learned this the hard way when I had a payment processing route that was nearly two hundred lines because I kept adding validation, webhook handling, logging, and error recovery directly into the handler. Moving the payment flow into its own service cut the controller down to fourteen lines and made unit testing trivial.
Error Handling That Does Not Break Your App
Unhandled promise rejections will kill your Node process in production. This is not a theoretical risk. If a database query fails and nobody catches it, the entire process exits. You need a global unhandled rejection handler as a safety net, but more importantly you need to handle errors at the point where they actually occur. Use an async wrapper pattern for your routes instead of trying to catch errors inside each handler. Here is what that looks like in practice: Wrap every route handler with a function that catches errors and passes them to your centralized error handler. This avoids the repetitive try-catch boilerplate that clutters every single route file. A common pattern is something like:
Get the Full Details

const asyncHandler = fn => (req, res, next) => Promise.resolve(fn(req, res, next)).catch(next); Then define error classes for different failure types. ValidationError, AuthenticationError, NotFoundError. Each one carries a status code. Your central error handler inspects the error type and returns the appropriate response. This way you never accidentally leak stack traces to clients or return generic 500s for expected failures. One thing people consistently get wrong is treating all errors the same. A missing user is not the same problem as a database connection timeout. One returns 404, the other might need a retry or a circuit breaker. If you lump them together your API responses become useless to anyone consuming your service.
The Event Loop Is Not Magic, It Is a Constraint
Node.js runs on a single thread. The event loop processes one thing at a time. Anything that blocks that loop blocks everything else. CPU-intensive operations, large file reads, and synchronous database calls are the usual suspects. I once had an API that started returning 30-second timeouts during peak hours. The issue was a report generation feature that read a CSV file with twenty thousand rows using fs.readFileSync inside a route handler. Synchronous file operations block the entire event loop. Other requests sat in queue and timed out. Replacing it with fs.promises.readFile and streaming the data reduced the average response time from four seconds to under two hundred milliseconds. Use streams for large data sets. Use the built-in worker_threads module for CPU-bound tasks. Never import a heavy package at the top level if you can avoid it. Node.js loads all required modules eagerly, so a single unnecessary dependency can add measurable startup latency to your server.
Configuration Management
Hardcoding values is the fastest way to make your app fragile. Use environment variables for secrets and deployment-specific settings. A library like dotenv works fine for local development, but in production you should inject configuration through environment variables set by your deployment platform. Validate your configuration at startup. If a required environment variable is missing, fail fast with a clear error message rather than letting the app crash hours later when it tries to connect to a database that was never configured. I have a utility that loads all required env vars and throws a descriptive error listing every missing variable. It saves a lot of time compared to debugging connection failures in production.
Testing Strategy
Unit test your services. Integration test your routes against a real or mocked database. Do not test your controllers in isolation from the database because that misses the most common failure mode: data consistency issues. A service method might work perfectly in a unit test but fail when the actual database returns a constraint violation. Use a test database that you reset between test runs. Docker makes this straightforward. Spin up a Postgres or MongoDB container for your test suite and tear it down after. This gives you realistic conditions without risking your development data. Mock external services like payment gateways and email providers in your integration tests. You do not want your test suite hitting a real Stripe account every time you run your tests. I use nock for HTTP mocking and it has saved me from accidental charges multiple times.
Logging And Monitoring
Silent failures are worse than loud ones. If an error happens in production and nobody knows about it, you are already behind. Set up structured logging with a library like pino or winston. Include request IDs so you can trace a single HTTP request across all log lines. Without request IDs, correlating logs from multiple services is guesswork. Set up health check endpoints. A simple /health route that returns 200 when the service is running and 503 when dependencies like the database are unreachable. Load balancers and orchestration tools rely on these. Without them you cannot do rolling deployments safely. I once had a situation where our monitoring showed the app was healthy but the database connection pool was exhausted. The health check only verified that the app process was running, not that it could actually serve requests. Adding a database connectivity check to the health endpoint caught that problem within seconds instead of waiting for users to report failures.
Security Basics That People Skip
Input validation is not optional. Use a schema validation library like Zod or Joi. Validate every field from every request. User input is hostile data. Always assume someone will send you malformed or malicious input. Use helmet to set security headers. Configure CORS properly instead of allowing all origins. Hash passwords with bcrypt or argon2, never store them in plaintext. Rate limit your authentication endpoints. A weak password brute-force attempt does not need sophisticated tooling, and without rate limiting you are leaving the door open. One specific issue I encountered involved SQL injection through a surprisingly unconventional path. We were using an ORM but passing raw strings into a custom query builder for a complex report feature. The ORM parameterization did not apply to the custom queries. Switching to parameterized queries throughout the entire codebase, not just the obvious ones, eliminated that risk entirely.

Database Connection Management
Connection pooling is not optional for production. Opening a new database connection per request is slow and wastes resources. Configure your connection pool with sensible limits. A pool size of five to ten connections works for most workloads. Going higher rarely helps and can actually hurt performance due to context switching overhead. Set a connection timeout and a query timeout. Long-running queries can hold connections indefinitely and starve other requests. I had a case where an unoptimized aggregation query held a connection for forty-five seconds. Every other request waiting for a connection was stalled. Adding a query timeout of ten seconds and indexing the collection dropped that query time to under two hundred milliseconds.
Deployment Considerations
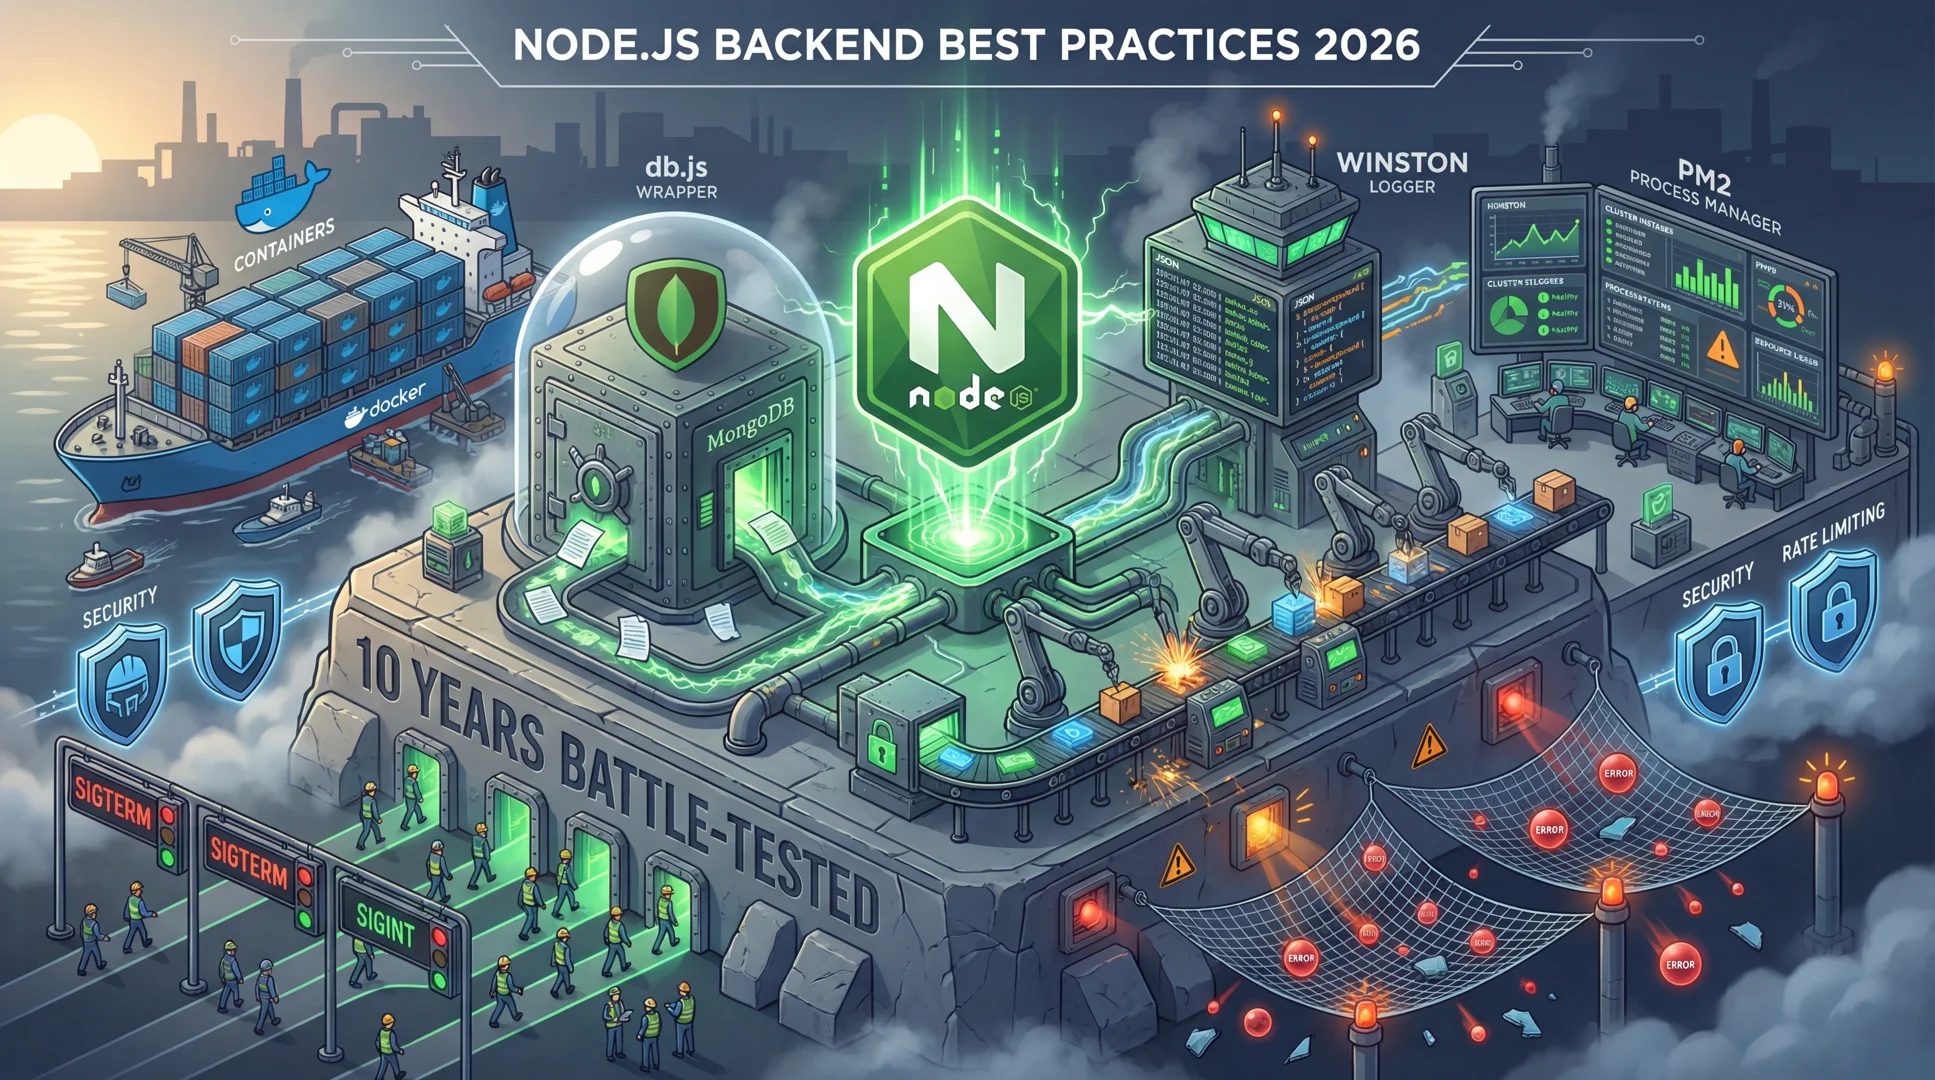
Never run Node.js with the default settings in production. Set the appropriate environment variables. Increase the heap size if your application processes large payloads. Use a process manager like PM2 or run your application through Docker with proper restart policies. Graceful shutdown is important. When your process receives SIGTERM, finish in-flight requests before exiting. A poorly configured shutdown can drop active connections and corrupt in-progress operations. Set up a shutdown handler that stops accepting new connections, waits for existing ones to complete, and then closes database connections. Keep your dependency list lean. Large dependency trees increase build times, attack surface, and the likelihood of a vulnerability appearing in an unused package. Audit regularly. Run npm audit or use a tool like Renovate to keep dependencies updated without manual intervention.
These practices do not make your backend perfect. There is no such thing. They make it predictable. A predictable backend is one where failures are visible, performance is measurable, and code changes do not introduce unknown risks. That is the goal.