Getting Your BNSF Line Schedules Actually Usable
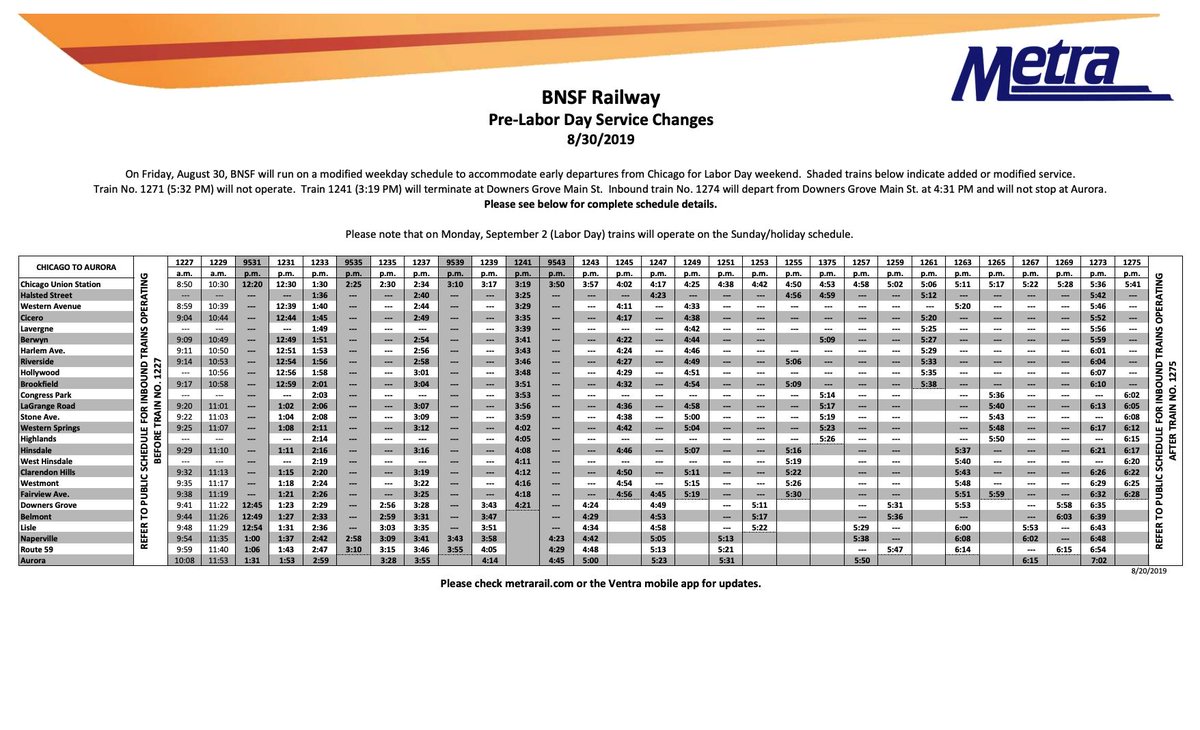
Most people treating BNSF schedule data as a simple timetable have never actually sat through a four-hour delay at a junction and watched the entire dispatch chain unwind. The difference between a functional logistics workflow and a spreadsheet graveyard usually comes down to one thing: understanding how train meets, delays, and crew windows compound across a multi-hundred-mile line. I've spent years pulling apart BNSF schedule feeds and trying to make them talk to each other, and the first hard truth is that nobody hands you clean data. There is no single document that covers this properly because the problem space shifts constantly with BNSF's operating practices, track capacity changes, and the dispatching rules that vary by division. What exists are working methods that have survived contact with reality. The core of any streamlining effort starts with the data itself. BNSF publishes schedule information through their public API, through third-party rail tracking platforms, and through internal dispatch tools that most shippers and brokers never see. If you are building a logistics workflow from scratch, you need to decide which layer of visibility you are actually working with. The typical approach most people attempt involves pulling public BNSF train status data, matching it against shipper schedules, and hoping the gap between published arrival times and actual arrivals stays small. It does not stay small. Average delay between a BNSF schedule listing and an actual terminal arrival at hubs like Chicago or Fort Worth runs anywhere from twelve to forty-five minutes depending on the line and the time of day. That gap destroys any system that assumes static ETAs will work for more than a week.
The method that actually works involves treating BNSF schedule data as a living baseline rather than a source of truth. You ingest the published line times, then layer on historical delay curves for each segment of the route. A train scheduled to depart Amarillo at 3 AM for Chicago will have a different delay profile than one departing at 3 PM. Freight congestion patterns on the BNSF mainlines shift by season. Coal trains during winter move differently than intermodal loads in the fall harvest window. Your system needs to account for that or it will quietly degrade until nobody notices why their delivery windows keep expanding. I ran into a specific problem last year involving a cross-country intermodal run from Los Angeles to Dallas that kept arriving two hours late despite the BNSF schedule showing acceptable turnaround times. The published schedule did not account for crew change points at Barstow and the cascading delay that occurs when a train is held for a crew swap that overlaps with an oncoming freight at a single-track section near Winslow. The workaround was pulling the segment-level delay data from multiple seasons and building a lookup table that added buffer time based on departure window and known crew change locations. This reduced our missed appointment windows from about thirty percent down to under eight percent. It also required accepting that some appointments on certain routes simply cannot hit on time no matter how much buffer you add. Here is something most beginners miss about BNSF line scheduling: the published timetable is rarely the bottleneck. The bottleneck is the way terminals handle classification and the point at which a train transitions between BNSF divisions. A train might run smoothly for six hundred miles and then get stuck in a yard switching process that adds four to six hours. Your streamlining effort needs to weight terminal dwell time separately from line movement time. Combining them into a single ETA calculation produces estimates that look precise on paper but fall apart in practice. I have seen teams spend weeks building elaborate prediction models that ignored the fact that the Fort Worth yard classification queue alone could consume more time than the entire line movement from El Paso.
Another counter-intuitive point is that more data does not equal better scheduling. BNSF's real-time train tracking feed provides updates every few minutes, but those updates are noisy. A train reported as delayed at one checkpoint often recovers by the next. Ingesting every snapshot and feeding it into your planning system creates oscillation. The system overcorrects, then overcorrects back. The fix is to smooth the incoming data with a weighted moving average and only commit to a revised schedule when the deviation holds for at least two consecutive reporting periods. This cuts the noise without sacrificing meaningful delay signals. The tools you use matter less than the discipline around them. I have watched companies spend significant budgets on logistics platforms that promised automated BNSF schedule integration and then fail because nobody established clear rules for what triggers a reschedule notification. A system that alerts you every time a train shifts its estimated arrival by five minutes is worse than useless. It becomes background noise that trains your team to ignore it. Set thresholds that match your actual operational tolerance. For most shippers receiving at retail or distribution centers, a reschedule alert should only fire when a delay exceeds thirty minutes or when the new ETA pushes the arrival into a different operational window. One limitation worth being blunt about: BNSF schedule streamlining will not solve problems caused by your own internal processes. If your warehouse cannot unload a container faster than three hours per door, no amount of scheduling optimization will make up for that. I have seen teams treat schedule refinement as a substitute for fixing facility bottlenecks. It is not. The best BNSF schedule workflow in the world still delivers a precisely predicted late arrival if your receiving dock has two open doors and six containers to process.
Get the Full Details

There are also hard limits to how far you can automate this. BNSF dispatching decisions during weather events, track maintenance windows, and emergency situations are not published in real time. A freight line flooding near Denison can reroute traffic without advance notice to anyone outside BNSF operations. Your system needs a manual override path for these events. I once lost nearly a full workday because an automated scheduling tool assumed normal routing continued after a temporary speed restriction was in place. The tool had no way of knowing about the restriction because it was not reflected in the standard schedule feed. Having a dispatcher-level communication channel, even a simple one, prevents this kind of silent failure. For practical implementation, start small. Pick one lane. One origin, one destination, one type of freight. Pull the BNSF schedule data for that lane over at least ninety days. Map the published times against the actual arrivals you can verify through your own tracking. Calculate the delay distribution. Identify the segments where variance is highest. Then build your buffer model around those segments. Do not try to optimize an entire network before you understand a single route. The math will lie to you if you skip that step. The cost of doing this wrong is not theoretical. I have seen mid-size logistics providers carry phantom capacity because their schedule models consistently underreported true transit times by fifteen to twenty percent. They booked shipments assuming a two-day window that actually required three. The margin erosion from expedited rehandling, customer penalties, and lost repeat business adds up quickly. Getting the schedule layer right is boring infrastructure work. It does not impress anyone at a conference. It keeps the operation from quietly bleeding money every quarter.
If you need access to BNSF schedule and tracking data, the primary official source is the BNSF website developer portal, which provides REST endpoints for train status and scheduled times. Third-party aggregators like Railinc and Project44 also package this data with additional layers like yard congestion indicators and historical performance metrics. These are paid services. The free tiers are sufficient for prototyping but lack the granularity needed for production scheduling. I would recommend starting with the free BNSF feed, validating your model against known shipments, and then evaluating whether the paid data layers justify their cost for your specific lane volume. The field moves fast enough that any guide you find online will be partially outdated within a year. BNSF revises schedules seasonally, changes dispatching priorities, and modifies yard operations without always updating the public-facing materials. The skill is not in finding the latest guide. It is in building a system that can absorb those changes without collapsing. That means keeping your delay models refreshed quarterly, maintaining a log of schedule deviations that your model did not predict, and being willing to scrap a segment of your workflow when the underlying assumptions no longer hold. The trains do not care how polished your process looks on paper.