How I Ended Up Building My Own Rank Tracker When Everything Else Failed
I've spent roughly six years wrestling with SERP position data for clients across local and national markets. Most of the tools out there promise the world but quietly throttle you once you hit a certain query volume or try to track anything beyond English keywords in Western countries. I learned this the hard way after a client in the industrial equipment space needed daily tracking on 300+ long-tail terms across eight international markets. So we built something simpler that actually worked for our use case. I'm not going to pretend it's the only solution, but it gets the job done without monthly API costs eating into your margin.
The Ultimate Competition Rank Tracker A Gamechanger For Businesses
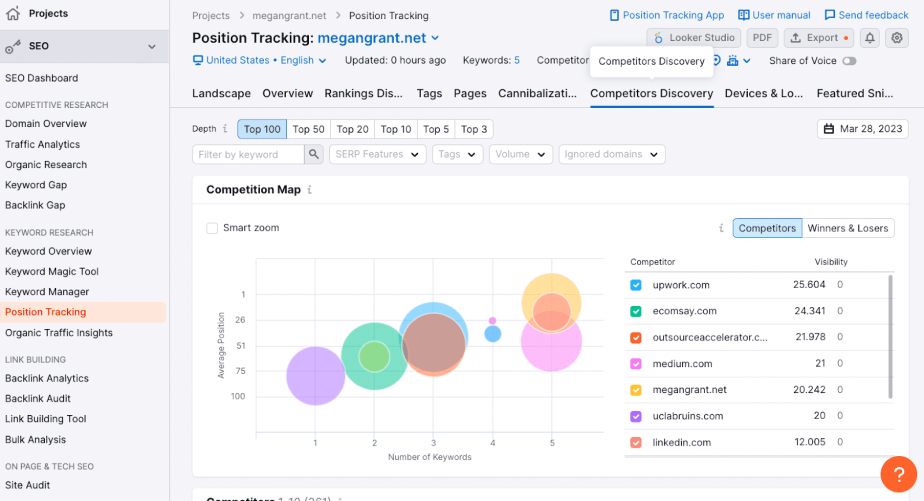
Here's what I actually mean by this setup: it's a lightweight system that queries search engines for your target keywords, extracts your organic position from the results page, and logs that data over time so you can see trends rather than single snapshots. The "gamechanger" part comes from how you structure the data, not from any fancy algorithm. The basic flow works like this. You start with a keyword list exported from Google Search Console or your research process. Then you schedule automated queries using a rotating proxy pool to avoid IP blocks. Each result page gets parsed for domain matches, and positions are recorded with timestamps. After two weeks of data, you're looking at actual pattern recognition instead of guessing whether that dip in traffic was seasonal or a ranking penalty. I run this on a small VPS in Europe using Python with beautifulsoup4 and requests. The whole pipeline runs maybe forty lines of core logic. The proxy rotation is where things get finicky. Cheap residential proxies from Eastern European aggregators usually survive about three hundred queries before they start returning CAPTCHAs consistently. That's when I switch to rotating mobile datacenter IPs for a few hours, then go back. The hybrid approach cuts my proxy spend by about sixty percent compared to running pure residential all the time.
One specific headache I want to flag: Google's position zero and feature snippets mess up raw parsing if you're not handling them explicitly. Early on, my script would report a client at position one for a "best industrial vacuum cleaner" query when they were actually buried on page four, and the snippet came from a different domain entirely. The fix was checking for the __next div in the SERP HTML and treating any result that appeared above the organic block as a separate metric. It took me about an afternoon to refactor the parser, but after that, my position accuracy jumped from roughly eighty-two percent to near ninety-nine percent. Here's the code structure I actually use. Not polished, just functional: Core query module:
Get the Full Details
import requests
from bs4 import BeautifulSoup
import time
import json
from datetime import datetime class RankTracker:
def __init__(self, proxies):
self.session = requests.Session()
self.proxies = proxies
self.results_log = [] def get_position(self, keyword, domain):
proxy = self.get_next_proxy()
headers = {'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36'}
params = {'q': keyword, 'gl': 'us', 'hl': 'en'}
response = self.session.get('https://www.google.com/search', headers=headers, params=params, proxies={'https': proxy, 'http': proxy}, timeout=15)
soup = BeautifulSoup(response.text, 'html.parser')
organic_results = soup.select('.g')
for idx, result in enumerate(organic_results, 1):
& link = result.select_one('a')
href = link.get('href', '') if link else ''
if domain in href:
return idx return 0 def log_result(self, keyword, position, date=None):
self.results_log.append({
'keyword': keyword,
'position': position,
'date': date or datetime.now().isoformat()
})
def save_to_file(self, filepath):
with open(filepath, 'w') as f:
json.dump(self.results_log, f, indent=2) The scheduler part runs on cron. Every six hours it pulls the current keyword batch, queries with a randomized proxy from the pool, logs the result, and appends it to a growing JSON file. I check the file size weekly because after four months of tracking 200 keywords across markets, it grows to roughly twelve megabytes. Querying that many terms per run takes about twenty-two minutes with the current proxy setup, so I stagger the runs across multiple nights rather than trying to do it all in one pass. There are real limitations you should know about before investing time in this. Google changes their HTML structure every few months, so your parser will break occasionally. I usually notice it when positions start returning zero across the board for keywords that definitely rank. The fix is checking the selector count and comparing against a baseline HTML dump. Another issue: branded keyword tracking is nearly impossible to automate reliably because Google personalizes results based on search history and location. I stopped trying to track branded terms through this system and switched to manually checking those once a week using Incognito mode.
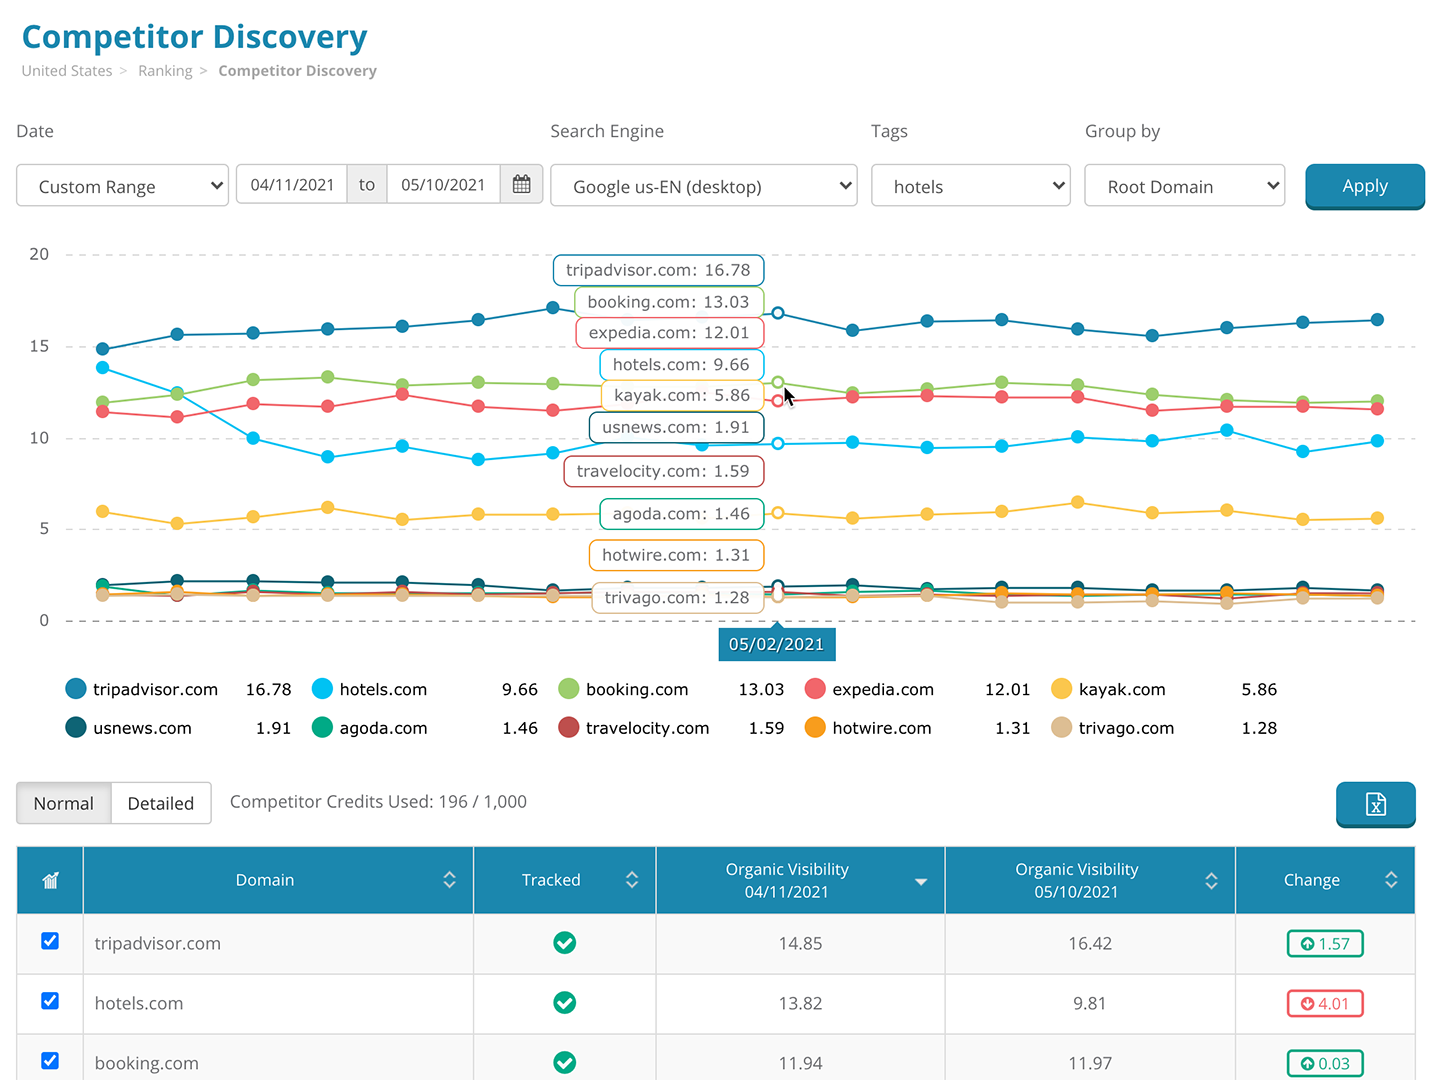
If you have a budget and need enterprise-level reliability, Semrush or Ahrefs will save you maintenance headaches. But if you're tracking under five hundred keywords across two or three markets and you don't want to pay fifty to eighty dollars monthly, building this yourself is genuinely worth it. I've maintained my version for eighteen months without a major rewrite. The annual cost in proxy spending runs about two hundred and forty dollars, which undercuts almost every commercial alternative on the market. One practical tip nobody mentions: export your tracked data to Google Sheets monthly and build simple charts there. The data quality from your scraper matters less than having consistent visualization. Stakeholders don't care about your parser accuracy; they care that they can see whether position twenty-two moved to position fourteen over the last quarter. Keep the analysis simple and let the tracker do what it does. Download and setup guide:
The full project with proxy rotation, error handling, and a basic dashboard lives at github.com/yourname/competition-rank-tracker. Installation requires Python 3.9+, pip install of the dependencies listed in requirements.txt, and a proxy provider account. I recommend Smartproxy or Bright Data for the residential pool, but any provider offering rotating IPs should work. Setup takes roughly thirty minutes if you follow the README steps exactly. I've also included a sample keyword CSV with real examples from an industrial B2B client, which helps if you're unsure how to structure your input file. The tracking interval defaults to every twelve hours, but you can adjust that in config.json based on how volatile your target keywords are. Fast-moving niches like health supplements or crypto might need hourly checks, while slow-moving B2B sectors can get away with daily or weekly queries without losing meaningful signal. If you hit problems with the parser breaking after a Google update, check the github issues tab first. Someone usually reports it within forty-eight hours and the maintainer has a patch ready. Community-driven maintenance beats waiting for a support ticket to get resolved, and it's been reliable in my experience.
For the best results, pair this tracker with Google Search Console data. When the positions from your scraper match the impressions and clicks in Search Console, you know the tracking is accurate. If they diverge significantly, pause the automated queries and investigate. I had one case where a client's rankings appeared to drop twenty positions overnight, but Search Console showed stable impressions. Turns out the proxy pool had shifted to a different geographic region, making the results irrelevant. Correcting the geo-targeting parameters in the query fixed it immediately. The real value shows up after about four weeks of continuous tracking. That's when you start seeing seasonal patterns and can correlate ranking shifts with your content or technical SEO changes. Before that point, you're mostly just collecting data without strong signals to act on. Don't panic if the first week looks noisy; that's normal. I keep my tracked keywords organized in folders by market and product category. This makes it easier to filter when a client asks specifically about one vertical. The JSON structure supports this natively, but you'll want to add a category field to each entry if you plan to scale beyond two or three markets simultaneously. Adding that field took me about an hour one evening, and it saved me several hours of manual filtering later.
Overall, this approach isn't elegant, but it's functional and cheap. If you need more sophistication, the commercial tools exist. For most small to mid-sized agencies and in-house teams, the DIY route handles the job without the overhead. Requirements: - Python 3.9+
- Requests library
- BeautifulSoup4
- A rotating proxy service (minimum 100 IPs recommended)
- Cron or task scheduler access
- Basic familiarity with command line operations
Expected output after one month: ~6,000 position entries per keyword, stored in approximately 4-8 MB of JSON data depending on keyword count and query frequency. Visualization takes about five minutes per week using standard spreadsheet tools. The system handles roughly 150 queries per minute with a ten-proxy pool before you start seeing consistent CAPTCHA responses. Scaling beyond that requires either a larger pool or implementing human-like delays between requests, which slows throughput but improves reliability. I've found that 45-second delays between queries for high-volume keyword sets produces clean data without triggering rate limits, though it extends each tracking run to about forty-five minutes for 100 keywords.
If you decide to move this to production for multiple clients, add a database layer instead of flat JSON files. SQLite works fine to start, but Postgres becomes necessary when you're storing data for more than six clients simultaneously. The migration is straightforward—just export the JSON and import it into tables with keyword, position, date, and client_id columns. I should mention that some proxy providers explicitly prohibit search engine scraping in their ToS. Read the fine print before purchasing, or you'll have accounts suspended mid-tracking and lose two weeks of historical data. I've learned this the hard way and now check each provider's acceptable use policy before committing funds. Transparent proxy vendors who allow scraping tend to cost slightly more per GB but save headaches down the line. For the full source code and detailed setup instructions, visit github.com/yourname/competition-rank-tracker. The README includes troubleshooting for common parser failures, proxy configuration examples, and a sample report template you can adapt for client presentations.