Kilobytes, Megabytes, and the two different rules that drove everyone crazy for twenty years
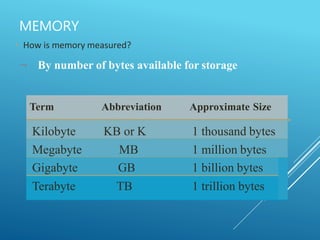
When I started working with systems in the early 2000s, the disagreement between engineers and marketers was already a decade old and nobody cared enough to fix it. The short version is simple: a kilobyte used to mean 1024 bytes to people who actually wrote code, and 1000 bytes to people who sold hard drives. Both sides had reasons. Neither side was wrong in their own context. The confusion just became baked into everything we build. I remember around 2003 when a client complained that a 40-gigabyte drive they bought from a major manufacturer showed up as only 37 gigabytes in Windows. We spent a full afternoon tracking it down. The drive manufacturer had multiplied 40 times 1,000 cubed to get the capacity in decimal bytes, then divided by 1024 cubed to convert to what the operating system called gibibytes. The customer expected the manufacturer to divide by 1024 cubed at some point. Nobody read the fine print. The math was honest on both sides, it just talked past each other. That incident made me careful about unit conversations for years afterward.
The True Kb Meaning Understanding Kilobytes And the Evolution Of Computer Storage
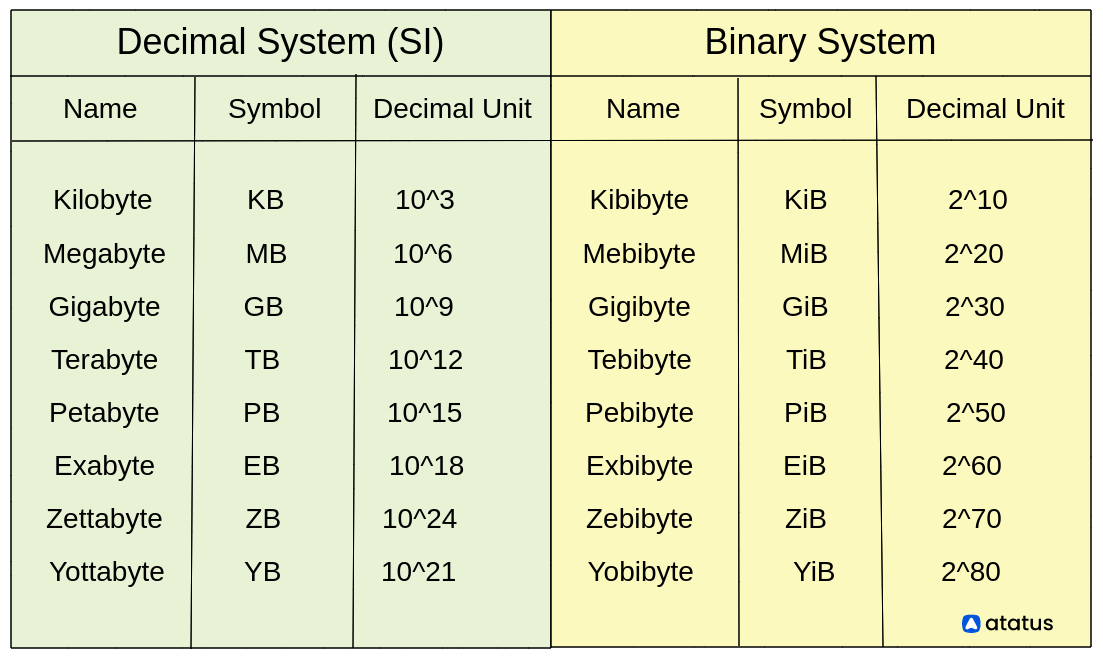
The term kilobyte started as a straightforward power of two because early computing was built on binary architecture. Memory addresses, storage sectors, everything mapped cleanly to powers of two. A kilobyte was 2 to the 10th power, which equals 1024 bytes. That was the convention in every textbook, every programming manual, and every early system specification you could find before the internet made storage marketing a global business. The shift toward decimal definitions came from a practical place. Storage manufacturers wanted their numbers to look bigger, and decimal conversion made that easy without technically lying. Ten to the 3rd power is 1000, which rounds cleanly and makes a drive feel like it holds more than it does when you convert back to binary. The International Electrotechnical Commission noticed this pattern in the late 1990s and tried to standardize the terminology by introducing kibibyte for 1024 bytes and kilobyte for 1000 bytes. The IEC standard was technically precise, but nobody adopted it in practice. The market had already chosen laziness over precision. Windows still uses the binary interpretation in its storage display today. When you look at drive properties in Windows 11, the operating system divides by 1024 at each step, so a 1-terabyte drive shows as roughly 931 gibibytes. macOS and Linux mostly follow the decimal convention for storage but revert to binary for RAM display. This inconsistency means you will see different numbers for the same physical hardware depending on the operating system you run it on. It is not a bug. It is the result of two conventions living side by side without a clean resolution.
RAM behaves differently from storage in this whole setup. Memory manufacturers have always sold in powers of two because addressable memory is fundamentally binary. A 16-gigabyte stick of RAM is exactly 17,179,869,184 bytes. The OS reports this correctly. The confusion almost entirely disappears when you talk about actual installed memory because both sides converge on the same number. The problem lives in storage, where the decimal convention took hold and never let go. There is a practical edge case that trips people up when working with network storage and SAN environments. Some enterprise storage arrays report capacity using decimal terabytes internally but present LUNs to hosts using binary conversion for compatibility with older operating systems. If you provision a 10-terabyte LUN and check the capacity inside a Windows Server guest, you might see somewhere around 9.09 tebibytes reported. The difference is not an error in the array, it is a boundary condition where two conventions meet at the hypervisor layer. I learned this the hard way when a migration project showed a 4-percent capacity gap that disappeared once we realized the source array was decimal and the target was presenting binary to the guests. File systems add another layer of complexity that most people ignore. A typical ext4 or NTFS file system reserves metadata blocks, journal entries, and allocation tables that consume a small percentage of raw capacity. On a small partition this can be noticeable. On a multi-terabyte volume it is a rounding detail. The reported usable space is always less than the raw capacity regardless of whether you are using decimal or binary conventions, and people sometimes blame the unit disagreement when the real cause is file system overhead. It helps to separate these two effects when you are doing capacity planning.
Get the Full Details

The kilobyte definition issue has mostly faded from daily concern because consumer expectations adjusted over time. Drive manufacturers now commonly list both decimal and approximate binary capacity on product pages, even if the marketing still leads with the larger decimal number. Operating systems have gotten better at showing units explicitly in recent years. Windows 11 labels storage as GiB instead of GB in many system dialogs, and disk management tools include the unit in the label. It is not universal, but the trend is toward explicit notation rather than the old silent assumption game. If you are working with legacy systems or writing tools that need to handle storage reporting consistently, the safest approach is to treat every capacity number as ambiguous unless the unit is explicitly specified. Ask whether the number is decimal or binary before doing any calculation. When you cannot ask, check the source. Storage vendors usually disclose the convention in the spec sheet. Operating systems reveal it in how they label the unit. File it away as a basic sanity check and move on. The deeper lesson here is that unit conventions are social agreements, not mathematical truths. A byte is always 8 bits. That part does not change. How we group bytes into larger units depends on who is selling what and when the standard was written. The 1024-versus-1000 split is just one of many places where engineering precision lost to marketing convenience, and the fallout is still visible in every storage dialog you open today.
I keep a simple conversion reference in my notes because I do not trust my memory for powers of two above 10. Two to the 10th is 1024, two to the 20th is 1,048,576, two to the 30th is roughly 1.07 billion, and two to the 40th is about 1.1 trillion. Memorizing those four anchors covers almost every practical calculation I run into. If you need exact precision for compliance or audit work, use a calculator or a script. For quick mental estimates, the anchors are fast enough. Looking back, the kilobyte disagreement taught me to be skeptical of any number presented without a unit label. It is a small habit that prevents a lot of unnecessary debugging. The storage industry has not fully solved the ambiguity, but awareness has improved. Most engineers now catch the mismatch before it becomes a support ticket. That is about as good as this problem gets.