Understanding Active Fault Zones in Infrastructure Planning
The Torn Split Cleft How A Geological Fault Line Is Reshaping Regional Infrastructure And Community Resilience
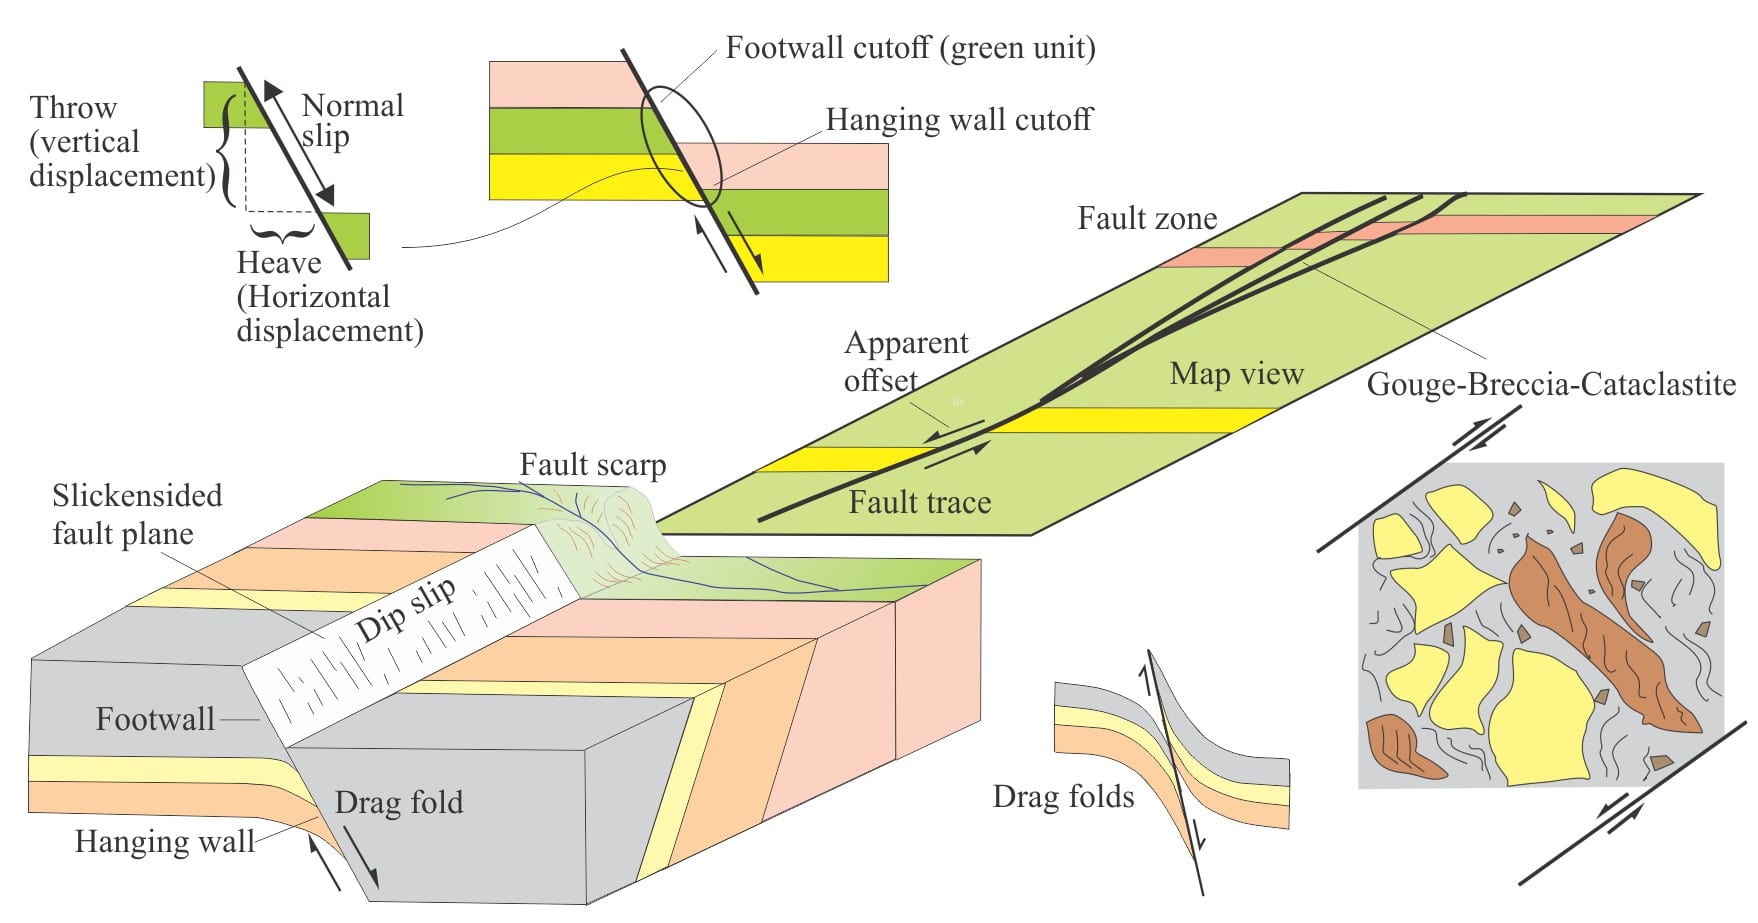
When an active fault runs through a developed area, you stop planning for stability and start planning for movement. This isn't abstract. I spent six months working on a water main relocation project near the Calaveras Fault extension in the Central Valley, and the design process was fundamentally different from anything I've done on stable ground. The problem wasn't predicting if the fault would move—it was deciding how much displacement the infrastructure needed to survive without tearing itself apart. Most engineers approach fault-zone design with a "build stronger" mentality. That approach fails. A reinforced concrete pipe will crack under fault displacement just like an unreinforced one. The trick isn't strength; it's accommodation. You design joints, offsets, and flexible connections that absorb the movement rather than resisting it outright. I've seen municipalities pour millions into rigid infrastructure that did exactly what you'd expect when the ground shifted—everything broke at once because nothing had anywhere to go. The seismic hazard analysis phase used to take us three to four months per project. We cut it down to roughly five weeks by using LiDAR-derived surface slip rates combined with paleoseismic trench data from the California Geological Survey's public database. The caveat is that LiDAR only tells you about surface expression, which means buried or blind thrust faults still catch people off guard. You can't skip the ground-penetrating radar survey even if the surface data looks clean.
Practical Design Strategies for Fault-Affected Zones
The first decision you make is whether to avoid the fault zone entirely, route around it, or cross it head-on. Avoidance is always preferable but rarely available in mature infrastructure corridors. I've worked on projects where the only viable alignment for a new transit line cut directly across a mapped fault trace. In those cases, you switch from conventional design to fault-rupture accommodating design. The core strategy involves two approaches: offset joints and flexible coupling systems. For buried utilities, I recommend bell-and-spigot joints with substantial lateral play—minimum 600 millimeters of movement tolerance per joint for moderate-severity zones. For above-ground structures, base isolation with controlled separation gaps works, but the gap width is where people consistently undercalculate. The rule of thumb is 10 percent of the structure height plus 300 millimeters, but on a recent project with a 40-meter elevated roadway near the San Andreas, our geotechnical consultant pushed us to 800 millimeters because the projected surface offset over the design life exceeded initial estimates. You also need to account for secondary effects. Fault displacement doesn't just break things directly in its path. Liquefaction zones extend well beyond the rupture trace. On a pipeline project I was involved with near Parkfield, we found that the pipe failed not from direct rupture but from differential settlement caused by soil liquefaction approximately 400 meters from the fault trace. That distance surprised everyone on the team until we reviewed the subsurface soil profiles and realized the entire floodplain had loose, saturated deposits from a former river channel.
Community Resilience Goes Beyond Infrastructure
The conversation around fault zones almost always centers on physical infrastructure. That's incomplete. Community resilience depends equally on institutional readiness and economic continuity planning. A town that can rebuild its water main in three days but has no emergency funding mechanism for displaced residents fails the resilience test regardless of how well-engineered the pipe is. I've visited several communities in the Pacific Northwest that underwent aggressive infrastructure fortification after the 2001 Nisqually earthquake. The physical upgrades were real. What they didn't have was a coordinated mutual-aid agreement with neighboring jurisdictions. When the quake hit their primary hospital, they lost power and communication and had no pre-established agreement with the county across the valley to receive patients. It took 18 hours to sort out logistics that should have been documented on paper months in advance. The most effective resilience frameworks I've encountered tie infrastructure hardening to redundant communication pathways and pre-negotiated resource sharing agreements. One county in southern California requires that every critical facility within a fault rupture zone maintain at least two independent communication routes—fiber and microwave, not two fiber lines along the same easement. That detail cost an additional 12 percent on their project budget but proved its value during a real event when a landslide took out their primary fiber corridor.
Get the Full Details

Common Pitfalls and Where Standard Approaches Break Down
The biggest mistake I see repeated is treating fault-zone engineering as a static problem. You design for a specific slip rate and return period and then walk away. Ground movement isn't static. New fault segments activate. Existing segments accelerate. The 2010 Chile earthquake showed us that a fault system you classified as low-activity can redistribute stress to adjacent segments and generate events well outside your original models. Another pitfall is over-reliance on software simulations. I've run finite element models for fault displacement scenarios that predicted acceptable performance, then watched the actual field testing or post-event inspections tell a different story. Soil-structure interaction is harder to model accurately than most engineers want to admit. When I encountered discrepancies between my modeled predictions and observed behavior on a retaining wall project, the fix wasn't to tweak the software parameters further—it was to add more physical instrumentation and recalibrate based on real displacement data. Those instruments cost money but prevented a failure that would have been catastrophic. The approach that actually works combines conservative engineering margins with ongoing monitoring and adaptive management. You accept that your initial assessment will be wrong in some details and build in the ability to detect and respond to those errors before they become failures. I recommend real-time ground displacement monitoring networks for any critical infrastructure within a kilometer of a mapped active fault. The hardware has dropped significantly in cost over the past decade, and the maintenance is straightforward. A single GPS station with quarterly calibration checks costs roughly 8,000 to 12,000 dollars annually per unit, which is cheap compared to replacing a ruptured transmission line.
The reality is that fault zones are going to keep moving regardless of what we build. The engineering question isn't how to prevent damage—it's how to limit consequences and ensure communities recover quickly. The best projects I've worked on treated resilience as a system-level property rather than a checklist of structural requirements.