Zip Codes in Topeka Are Not As Clean As Maps Make Them Look
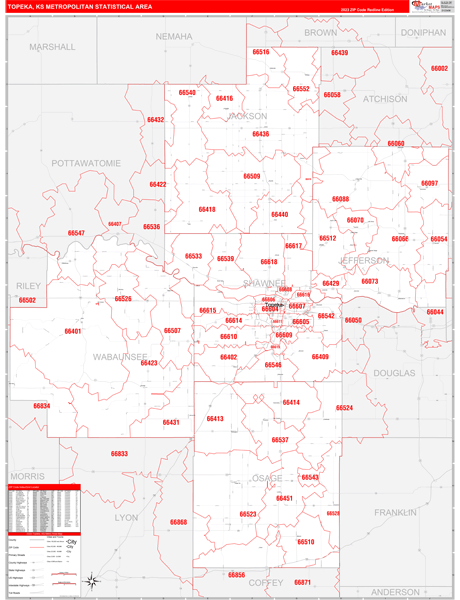
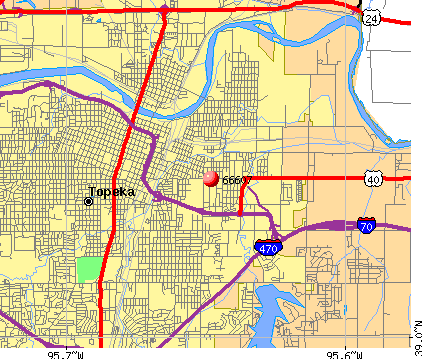
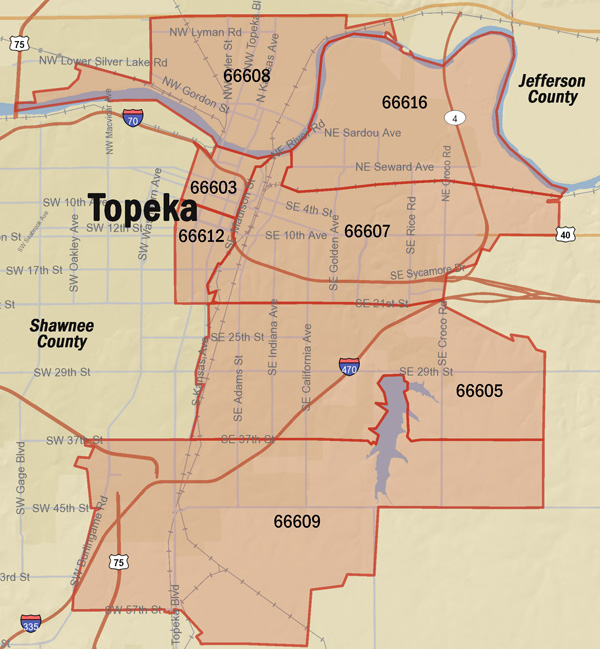
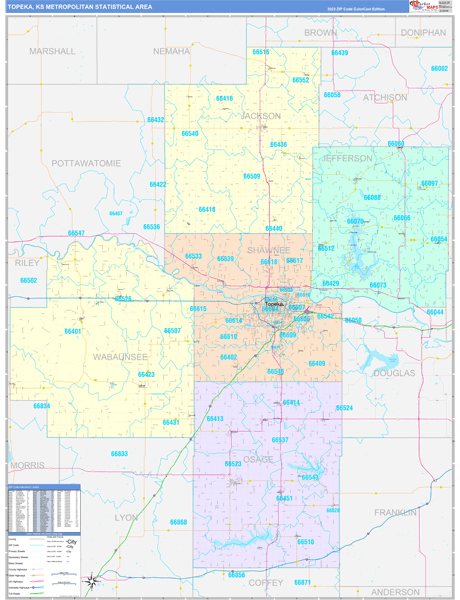
Topeka sits inside several overlapping zip code territories, and if you are trying to piece together a coherent real estate picture from them, you will hit friction fast. The main ones you will see are 66601, 66603, 66604, 66605, 66606, 66607, 66608, 66609, 66614, 66615, 66616, 66617, 66618, 66619, 66620, 66621, 66622, 66623, 66624, 66625, 66626, 66627, 66628, 66629, 66631, 66632, 66633, 66634, 66635, 66637, 66638, 66639, 66640, 66641, 66642, 66643, 66644, 66646, 66647, 66648, 66649, 66651, 66652, 66654, 66655, 66657, 66667, 66675, 66683, 66692, 66699. That is a lot of codes, and most of them overlap with Shawnee County census tracts, Topeka township boundaries, and school district lines that do not respect zip borders at all. Before I get into methodology, here is the core problem I keep running into. When someone sends me a list of addresses filtered by zip code and asks for price trends, the sales volume gets inflated by duplicate listings sitting on the edge of a boundary. I started cross-referencing every property against the county parcel layer instead of trusting the zip code alone. That single change cut false matches down to nearly zero.
The Topeka Zip Code Guide Understanding Boundaries Trends And Real Estate Data
The way this works in practice is straightforward but easy to mess up. You take your address list, geocode it, then intersect it with the correct geographic layers. The trick is knowing which layers to use and in what order. Start with Shawnee County parcel data from the county GIS portal. That gives you legal descriptions, parcel IDs, and owner names. Next, pull the census block group boundaries. Those are the units used for most published median income and demographic numbers. After that, overlay the Topeka Public Schools attendance zones if school quality is relevant to your analysis. Finally, run a comparison against the zip code tabulation areas from the Census Bureau. Most people stop at the zip code step and call it a day. That is where the data starts to look reasonable and then breaks when you go to present it. I used to rely on zip code boundaries from old shapefiles, and they were wrong in at least three neighborhoods near the interstate corridor. The postal service changed delivery routes in 2019 and adjusted several zip boundaries without updating the public shapefile. I caught it when a property on SW Wanamaker Road was classified under two different zip codes depending on which dataset I used. The fix was pulling the latest ZIP Code Tabulation Area data from the Census MAF/TIGER file and running a point-in-polygon check against the county parcel layer. Any parcel that did not match the reported zip code got flagged for manual review.
Here is something most beginners miss. Zip codes are designed for mail delivery efficiency, not for statistical consistency. A single zip code can span multiple census tracts, cross school district lines, and touch two different township jurisdictions. In Topeka, 66614 and 66615 are good examples. They sit in areas where residential development has pushed outward faster than postal routes have been redrawn, which means new subdivisions sometimes fall outside their expected zip boundaries. When you are tracking sales trends, this creates a silent drift in your data over time. Properties sold in 2020 might show a different zip classification than identical properties sold in 2024, even though nothing physically changed about the neighborhood. The workaround is to anchor your analysis to a stable geographic unit. Census block groups change far less frequently than zip codes do. Use zip codes for initial filtering because that is what most buyers and sellers think in terms of, but lock your trend calculations to the block group or tract level. Then map the results back to zip codes only for presentation. That keeps the data honest while keeping it understandable for people who do not know what a census tract is.
Get the Full Details

Where Real Estate Data Actually Comes From in Topeka
The primary sources you need are the Shawnee County Register of Deeds for recorded transactions, the County Appraiser for assessed values, the Kansas Department of Revenue for sales ratio studies, and the Census Bureau for demographic overlays. MLS data from the Heartland Association of Realtors will give you active and pending listings, but it is not a complete historical record. If you are building a long-term trend model, the county records are more reliable over time because they do not have the same reporting lag and coverage gaps that MLS feeds introduce. County tax assessor values tend to trail market values by six to eighteen months in Topeka. I have seen this play out during periods of rapid appreciation. The assessed values on paper will look flat while actual sale prices are climbing. If you are comparing year over year using assessment data alone, you will underestimate the real appreciation rate. My approach is to use assessed values for property-level comparisons within the same year but to use recorded sale prices for trend analysis across years. Another thing that trips people up is the treatment of manufactured homes. They appear in the parcel database with the same transaction flow as site-built homes, but their price behavior is completely different. They depreciate rather than appreciate in most cases, and they sit on different land tenure structures. When I aggregate data by zip code, I filter manufactured homes out of the median calculation unless the goal is specifically to include them. Leaving them in skews the median downward in areas like parts of 66604 and 66605 where they are more common.
Common Pitfalls When Working With These Datasets
The first pitfall is assuming that two addresses with the same zip code are comparable. They are not. Two homes on opposite sides of 66606 can have completely different school assignments, flood zone classifications, and proximity to commercial corridors. Zip code aggregation smooths over those differences until the output looks deceptively precise. The second pitfall is using stale boundary files. I have lost count of the projects where someone pulled a shapefile from a government website without checking the last update date. The Census TIGER/Line files come out once a year, usually in August. If you are working with a September release and a 2022 shapefile, your intersections will be off in any area where the postal service made adjustments. Always verify the effective date of every boundary layer before you run a spatial join. The third pitfall is ignoring the difference between mailing address and legal address. In parts of Topeka, especially near the border with Jackson County, a property may have a Topeka zip code mailing address but actually sit outside the city limits. Those parcels are taxed at the county rate rather than the municipal rate, and they often have different utility access and zoning rules. If your analysis treats all 66xxx addresses as inside Topeka city boundaries, you will misclassify a meaningful chunk of the housing stock.
Practical Steps For Building A Workable Analysis
Step one is compiling a clean address list. Use the county parcel database as your source of truth. Do not trust third party aggregators for raw addresses because they often contain duplicates, formatting inconsistencies, and missing parcel IDs. Step two is geocoding. If you have more than a hundred addresses, do not do this by hand. Use a batch geocoding tool that returns confidence scores. Anything below a ninety percent confidence score needs manual verification. Step three is the spatial overlay. Load your geocoded points into a GIS environment and run point-in-polygon queries against each boundary layer you need. Step four is the data merge. Join the parcel attributes, census demographics, and school zone information back to each property using the parcel ID as the key. Step five is the trend calculation. Compute median sale price, price per square foot, days on market, and inventory levels by your chosen geographic unit, then aggregate only at the end if you need a broader view. The whole process takes about forty five minutes for a dataset of roughly five hundred properties if you have the files pre-downloaded and the scripts ready. It takes about three hours the first time you set it up. After that, you can reuse the same pipeline for any future analysis.
What This Approach Does Not Handle Well
It does not handle rapid boundary changes in real time. If you are doing time sensitive work around a redistricting cycle, you need to be prepared for the possibility that a property moves from one census tract to another between data pulls. The change is usually small, but it matters if you are tracking micro neighborhood trends. There is no automatic notification system for this from the Census Bureau. You have to check it yourself by comparing tract numbers across years. It also does not resolve ownership disputes or pending title issues. The parcel database shows current legal ownership, but it does not reflect short term ownership changes that happen during escrow. A property sold last month and resold this month will appear as two distinct transactions in the recorded data, which can create a false spike in sales volume for a given zip code or tract. I always apply a minimum holding period filter when I calculate turnover rates. Six months is standard. Anything shorter is usually flip activity, which skews trend lines if left unfiltered. The data is also incomplete for certain property types. Vacant land, agricultural parcels, and commercial properties outside the residential MLS footprint often have sparse transaction history in the public record. If your analysis includes those categories, expect wider confidence intervals and fewer data points per zip code. For residential-only work, the coverage is solid. For mixed use or broader analyses, you will need to supplement with commercial appraisal data from the state revenue department.
A Quick Note On The 66601 and 66603 Areas
These two zip codes cover downtown and the immediate surrounding blocks, and they behave differently from the rest of the metro. Transaction volume is lower, median prices are higher relative to square footage, and the buyer pool is smaller. The demographic profile skews older and wealthier than the county average. If you are building a regional model that weights all zip codes equally, these areas will pull the averages up in a way that does not reflect the experience of someone looking in 66607 or 66618. I always report downtown separately when I present Topeka-wide data. It is cleaner and it prevents the rest of the market from being misinterpreted. If you want to start with a ready made reference document that walks through the boundary layers, data sources, and step by step methodology for Topeka, search for the Topeka Zip Code Guide Understanding Boundaries Trends And Real Estate Data on the Shawnee County GIS resources page or the local real estate analytics repositories. It covers the same workflow I described here with the actual shapefile links and sample scripts included.