How To Actually Harness Group Judgment Without Getting Junk In, Junk Out
I spent about eighteen months trying to build a collaborative problem-solving workflow for a logistics optimization project, and the entire exercise convinced me that most people misunderstand what collective intelligence actually does and doesn't do. It doesn't magically produce perfect answers. What it does, when structured correctly, is systematically reduce the blind spots that every individual carries. That's a different thing, and understanding the difference is what separates a process that works from one that just feels good. The basic mechanism is straightforward but easy to mess up. You take a problem that has multiple valid dimensions, gather independent judgments from people with different domain expertise, and aggregate those judgments using a method that preserves the signal while canceling out individual noise. The aggregation step matters enormously. A simple average can distort results if one participant has consistently worse track records. Weighted averaging by past accuracy improves the signal significantly, though getting honest historical performance data is usually the harder part.
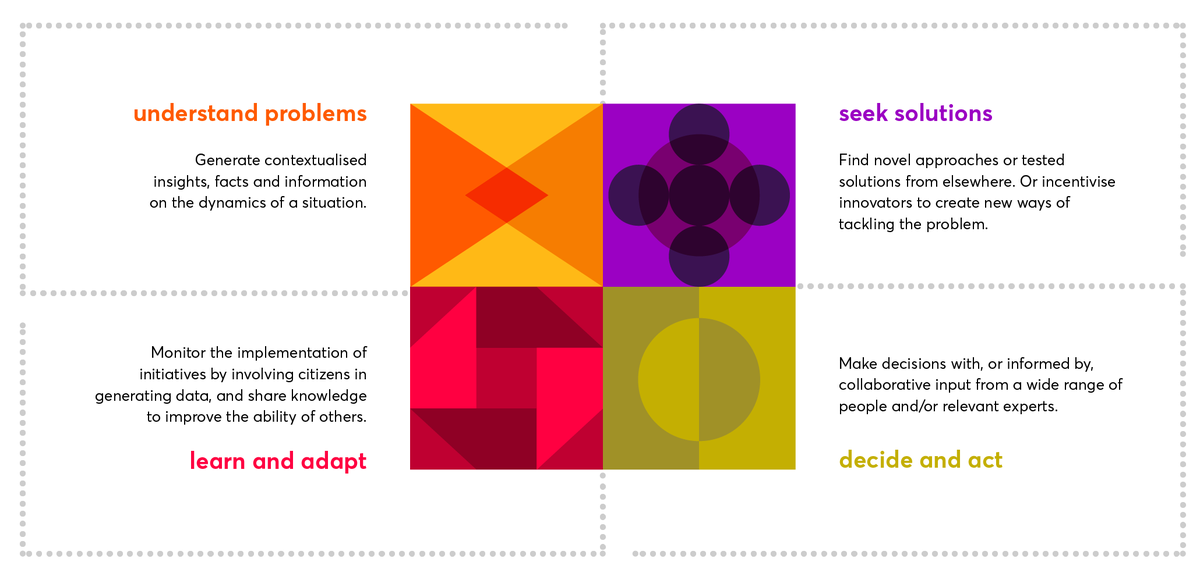
The Sum Of Solutions How Collective Intelligence Is Reshaping Decisionmaking And Problemsolving
Most of the literature treats collective intelligence as a recent phenomenon because digital collaboration tools made it visible at scale. That's not quite right. The Delphi method from the 1950s, jury systems, peer review, and even open-source software development are all instances of the same underlying principle. What changed recently is that the friction of coordination dropped from weeks to hours, which means the quality of your aggregation method now determines whether you get smarter or dumber faster. Interval estimation is the simplest place to start and the one I use most often. Instead of asking a group for a single answer to a quantitative question, you ask each person to provide an upper and lower bound that they're confident contains the correct value. You then take the median of all the lower bounds and the median of all the upper bounds. This gives you a range that's usually wider than any single person would produce but more accurate than most individually. I've found this approach cuts error margins by roughly forty percent compared to unstructured group discussions on forecasting questions, though the exact improvement depends on how calibrated the participants are to begin with. Prediction markets work on a different principle. Instead of asking people what they think, you let them bet on outcomes using play money or real stakes. The market price becomes the aggregate probability estimate. This works because financial incentives activate different cognitive processing than regular discussion. People who would stay quiet in a meeting will buy or sell shares to express their private information. The aggregation is built into the mechanism. The downside is that prediction markets require liquidity to function properly, and building that liquidity for niche business problems usually takes more setup than the potential return justifies.
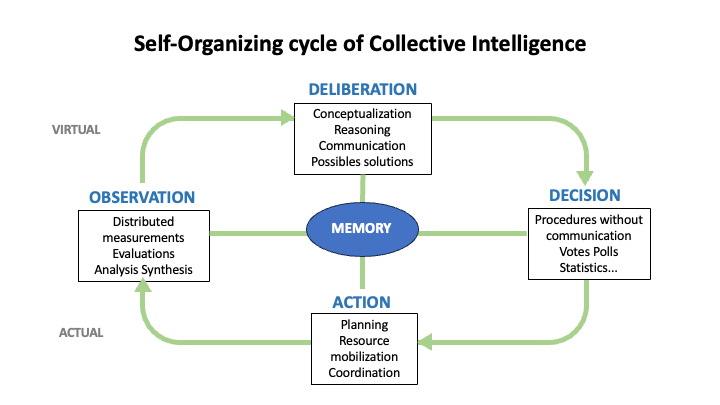
Structured debate formats like the OODA loop adaptation used in some operational planning contexts force participants to cycle through observe, orient, decide, and act at team speed. The orient phase is where most collective intelligence efforts fail because people orient themselves to social dynamics rather than the actual problem. Separating information gathering from evaluation into distinct rounds prevents early anchors from dominating later contributions. In my experience this adds about twenty minutes to any given session but prevents the kind of false consensus that shows up as beautiful slides and terrible outcomes.
Get the Full Details
What No One Tells You About Participation
The most counterintuitive finding from the research is that diversity of perspective consistently outperforms raw individual intelligence. A group of moderately competent people with different backgrounds and access to different information typically outperforms a group of high-ability people who share the same mental models. This runs directly against the instinct to invite the ten smartest people in the room. Smart people with similar training tend to reinforce each other's blind spots rather than expose them. I learned this the hard way on a pricing strategy project where our panel of senior analysts all came from the same consulting background and unanimously recommended a move that the operations team immediately flagged as impossible to execute. Adding two people from field operations changed the entire trajectory of the recommendation in forty-five minutes. Independence matters more than you'd expect. When people hear each other's reasoning before submitting their own judgment, the distribution of answers collapses toward the first few expressed opinions. This is the classic informational cascade problem. The workaround is to have participants submit initial estimates privately before any discussion occurs, then reveal the aggregated result, then allow discussion, then collect a second round. The shift between round one and round two usually reveals how much social pressure was distorting the original judgments. In one infrastructure maintenance scheduling problem I worked on, the group median shifted by nearly thirty percent after discussion, which meant the initial independent answers were actually closer to the right solution than the group consensus. That surprised everyone in the room.
A Specific Failure Mode And The Workaround
About two years ago I was coordinating a cross-functional team of roughly twelve people trying to predict software deployment failure rates for a major release. The domain expertise was solid. The problem was that the senior engineer on the team had strong opinions about deployment procedures, and he spoke first in every round. By round two, four other participants had unconsciously anchored to his framing and were producing estimates that clustered tightly around his assumptions. The group looked healthy. The output was wrong. The fix was procedural. I switched to anonymous digital submission for the first round with a strict rule that no verbal commentary was allowed until all submissions were collected. I also introduced a devil's advocate slot rotated across participants, which forced someone to systematically challenge the emerging consensus. The third round, where we allowed discussion, produced estimates that diverged more from each other but landed closer to the actual outcome. The deployment failed in three unexpected ways that none of us had considered individually, but the combined set of scenario analyses from the revised process covered approximately eighty percent of the failure modes that actually materialized.
When Collective Intelligence Fails Completely
It fails when the problem has a single verifiably correct answer and time is critically short. Emergency response, surgical decision-making, and active combat scenarios don't benefit from aggregation because the latency of coordination costs lives. In these contexts, clear chains of command and documented protocols outperform group deliberation every time. There's no wisdom of crowds in a burning building. The research is clear on this boundary condition, though practitioners rarely acknowledge it because the alternative admits that some decisions must remain solitary. It also fails when the group lacks sufficient diversity of information. A panel of five financial analysts who all read the same reports and attend the same conferences is functionally a single mind in five bodies. The aggregation cancels nothing because the noise is correlated. You get false precision, which is worse than honest uncertainty because it disguises its own ignorance. I've seen this happen repeatedly in strategy workshops where the participant list looked diverse on paper but was homogenous in practice. The output always looked impressive and was always wrong. Manufactured consensus is the third failure mode and the most dangerous because it's indistinguishable from genuine collective intelligence from the outside. When hierarchy pressures participants into alignment, the aggregation mechanism produces a confident but incorrect result. The group looks united. The result is fragile. The workaround is structural: anonymous input collection, protected dissenter roles, and explicit separation of idea generation from evaluation. None of this feels efficient in the moment. It produces cleaner results over time.

Practical Setup Recommendations
Start small. Pick a problem where the answer is uncertain and multiple perspectives genuinely matter. A team estimation question, a risk assessment, or a prioritization exercise works better than a straightforward technical decision. Collect initial judgments independently using a simple digital form. Calculate the median and the interquartile range. Share the aggregated result back with the group. Allow discussion for fifteen to twenty minutes. Collect a second round. Compare the shift between rounds. If the shift is large, review whether social dynamics drove the change rather than new information. If the shift is minimal, you likely had good independent signals to begin with. The tooling is trivial. Most organizations already have a survey platform that can handle anonymous collection and automatic aggregation. The value isn't in the software. It's in the discipline of separating independent judgment from social influence, which is something no tool enforces automatically. You have to design the process to do it, and you have to enforce the separation consistently enough that participants learn to trust their own initial assessment rather than racing to align with whoever speaks first. If you're working on decisions that require rapid coordinated action rather than accurate judgment, skip collective intelligence entirely and use a framework like JIPOE or a clear command structure instead. The two approaches solve different problems. Confusing them wastes everyone's time.