Why Your Professor Made You Memorize This Thing
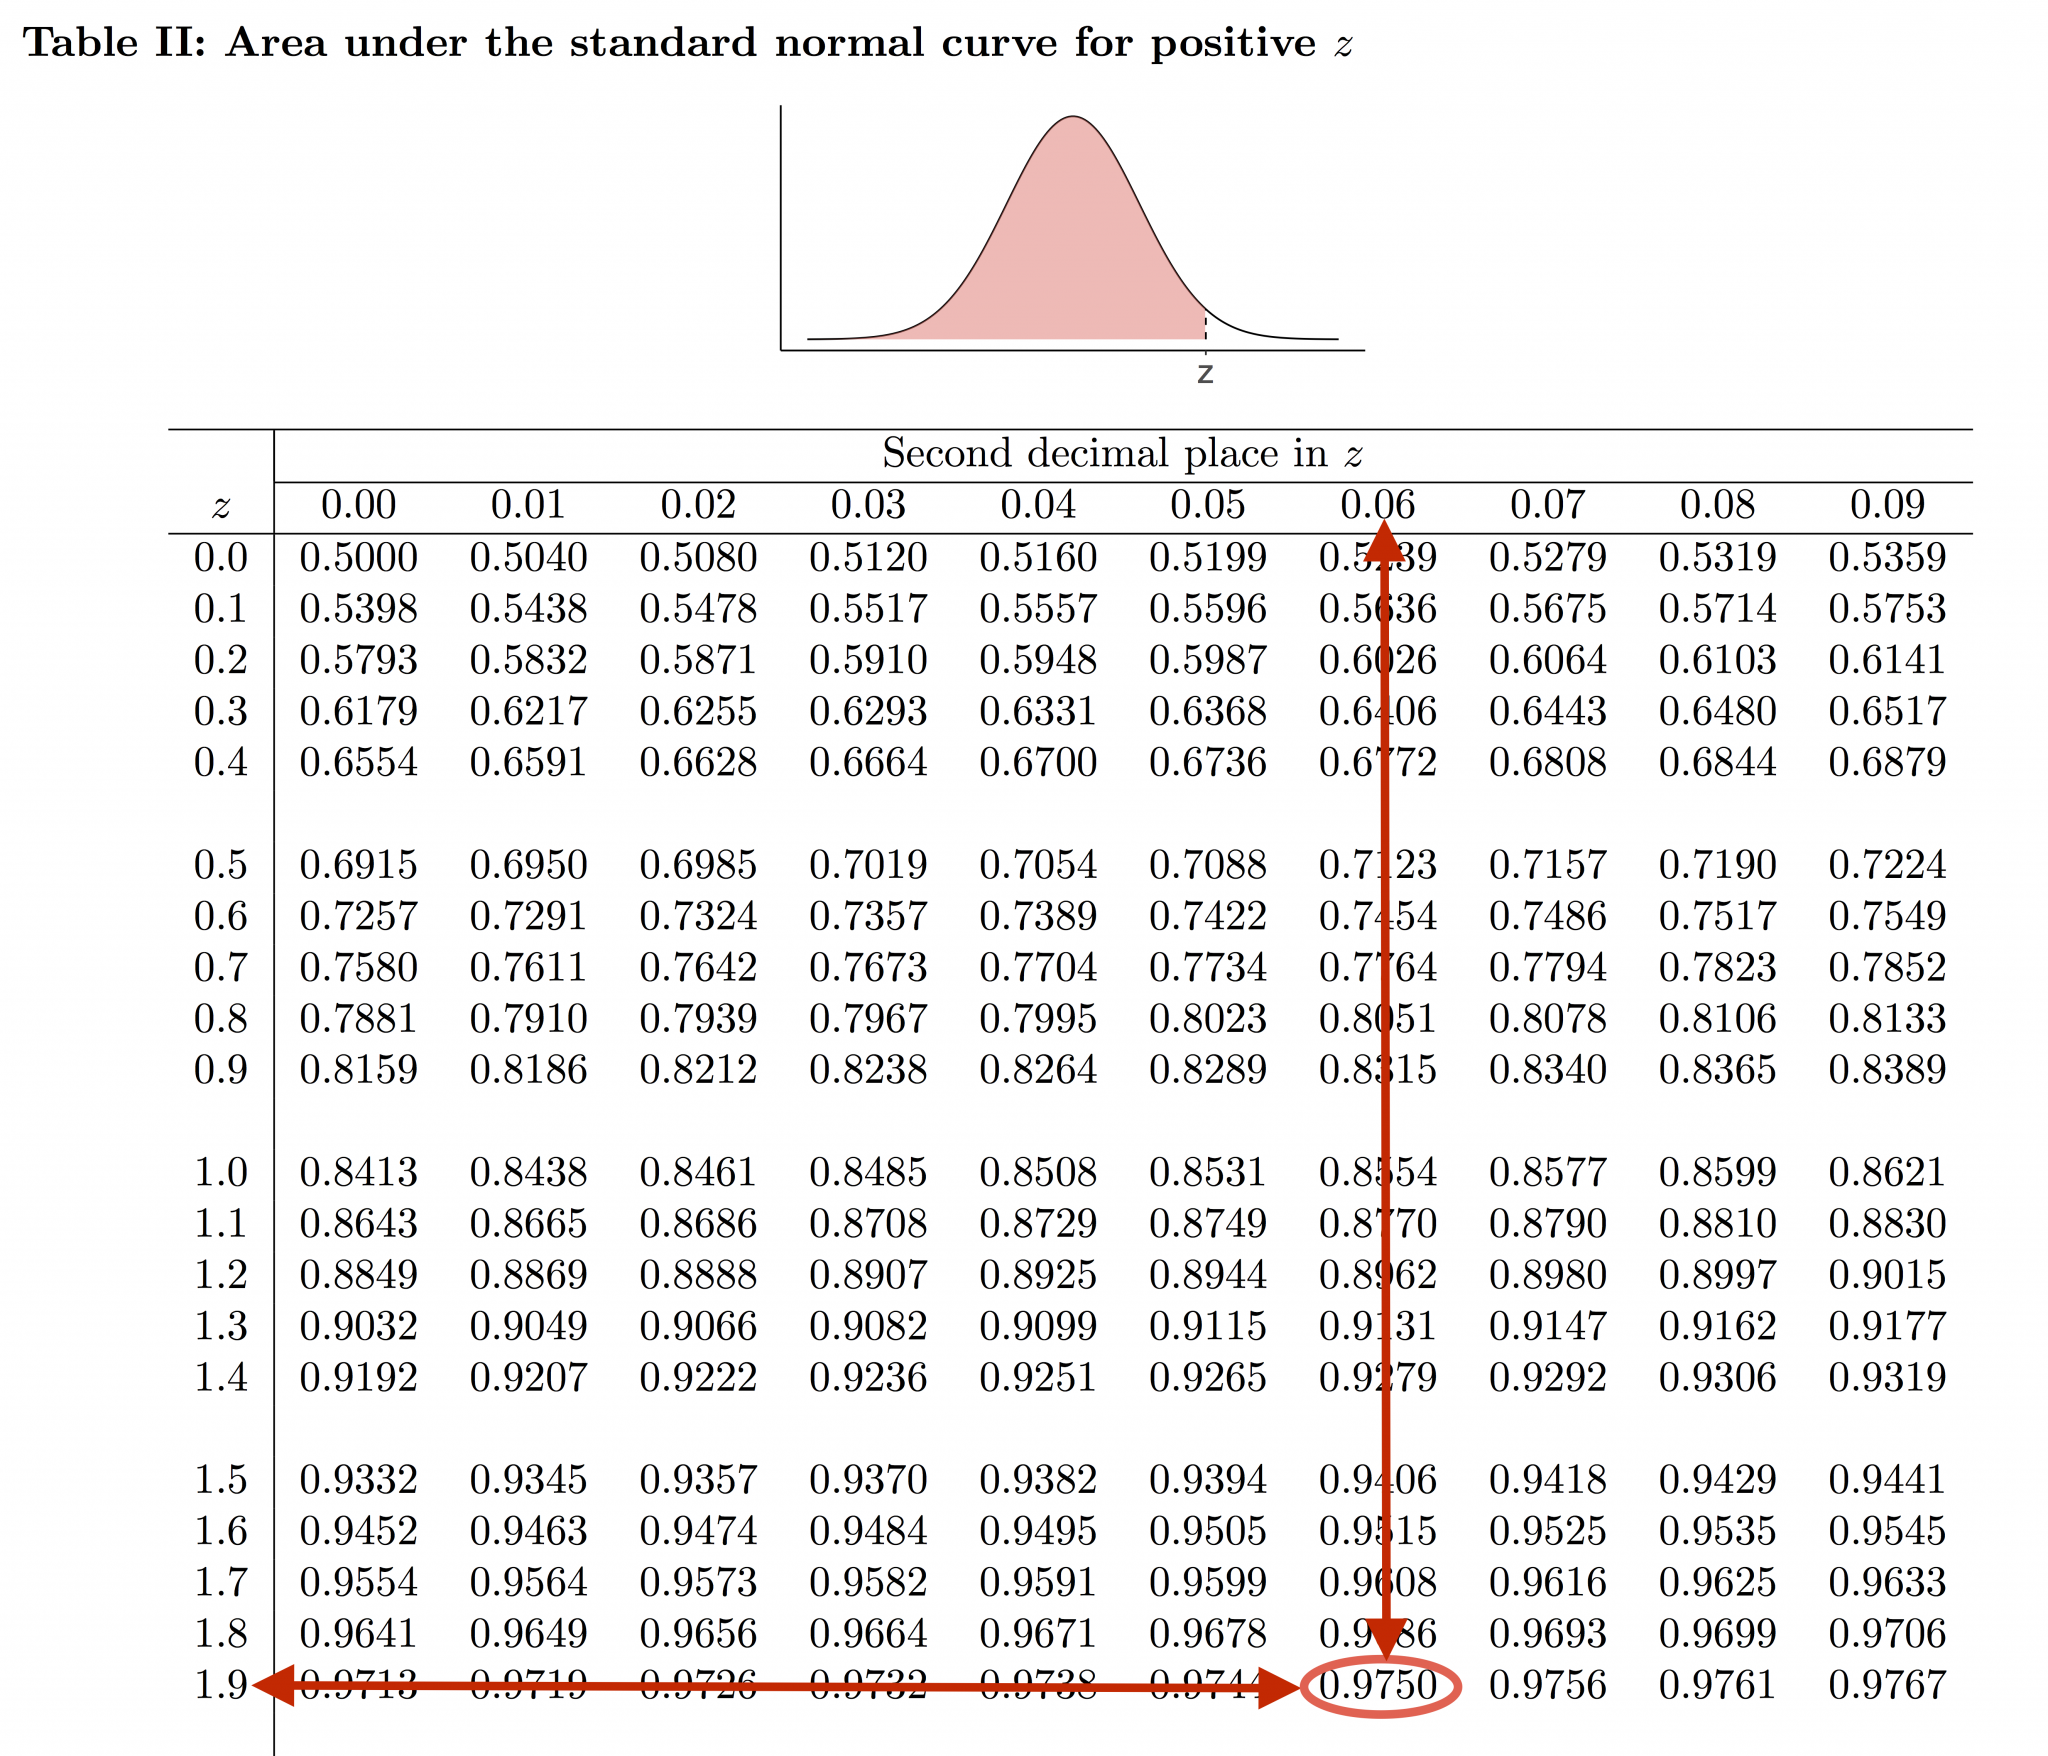
The standard normal table is a lookup grid. It gives you the area under the bell curve to the left of any z-score. That is it. Nothing more fancy than that. When I was taking my first stats course back in 2008, I thought this was useless because everything moved to software eventually. I was wrong about that. Even now, when I am consulting on regression models and hypothesis testing for a biostatistics team, I still reference this table constantly. Sometimes you do not have a computer. Sometimes you need to show your work on a whiteboard in a meeting where someone asks why two groups differ significantly. You pull a printed table from your bag and point at it. It looks silly. It works every time. Here is how you actually use it. You take your raw score, subtract the population mean, and divide by the standard deviation. The result is your z-score. You then find the row for the first two digits of that z-score and the column for the second decimal place. The number at that intersection is your cumulative probability. If your question asks for the area between two points, you look up both z-scores and subtract the smaller probability from the larger one. If you need the area to the right, you subtract the table value from 1. That is the entire mechanism. There are variations depending on which textbook you use. Some tables give you area from the mean to z. Some give you area to the left. Some are symmetric and only show positive values because the curve is mirrored. You need to know which one you are looking at before you start, or you will get the wrong answer every single time.
The Standard Normal Table Your Indispensable Map For Navigating The World Of Statistics
I learned this the hard way during my second year of grad school. I was working on a clinical trial analysis where I had to compare response rates between a treatment group and a placebo group. The dataset had about four hundred participants, and the z-score I calculated came out to something like 2.347. The table only goes to two decimal places. I rounded to 2.35 and used the table value. The difference between 2.34 and 2.35 in the cumulative probability is about 0.001. In most introductory courses that rounding error is invisible. In a clinical setting where your confidence interval borders on significance, a 0.001 shift matters. I ended up using linear interpolation between the two nearest rows. You take the difference between the upper and lower probabilities, multiply it by the fraction past the second decimal place, and add that to the lower bound. So for 2.347, I took the value at 2.34, added 0.7 times the difference between the 2.35 and 2.34 entries. It gave me a more accurate probability without needing a calculator. This is a standard workaround in epidemiology and quality control work. Any experienced analyst does this automatically. There are deeper things people miss about this table. One is that it assumes a perfectly normal distribution. Real data almost never behaves that way. If your underlying data is heavily skewed, applying this table directly to your sample means will give you misleading confidence intervals. I spent an entire quarter dealing with a logistics client whose delivery times followed a log-normal distribution, not a normal one. They wanted to run hypothesis tests on the raw times. I had to log-transform the data first before any z-test was even remotely valid. The table itself was not the problem. The assumption behind it was. Another common mistake is treating small samples as if they qualify for the standard normal distribution. When your sample is under thirty, you should be using the t-distribution, not the z-table. The shapes are close but not identical, and the discrepancy grows as your sample shrinks. I still see people use the z-table for n=15 samples on forums and in casual consultations. It is technically wrong. The t-table with the appropriate degrees of freedom is the correct tool, and the difference becomes substantial at the tails where significance decisions are made. The table also has blind spots. It cannot handle multivariate problems. If you are working with correlated variables, a univariate standard normal table does not tell you anything useful about joint probabilities. You need the bivariate normal distribution or simulation methods. It is also limited by its fixed granularity. Even with interpolation, you are bound to whatever precision the printed table offers. Modern calculators and software give you probability values to six or seven decimal places. The table gives you two or three. For high-stakes work, the table is a rough approximation at best. I recommend keeping one on hand for quick checks and teaching purposes, but relying on it for final reported results is unwise. R, Python, or even a decent scientific calculator will outperform the table in both speed and accuracy within seconds.
If you want a physical copy, most statistics textbooks include an appendix with the table. Some universities still print them as standalone sheets. You can find them through academic publishers or by searching for standard normal distribution tables in PDF format from university statistics departments. A few sites host them, but most of those files are just scanned images of textbook appendices. If you are working offline or preparing for an exam where calculators are prohibited, having a clean printed version helps. Make sure the version you find matches the convention your course or workplace uses. The cumulative-from-minus-infinity layout is the most common, but some older British textbooks use a different layout that only lists positive z-values with an area-from-zero format. Mixing up conventions is an easy way to misread an entire table. The core utility of the standard normal table is speed of reference. It converts a raw calculation into a visual lookup. That visual component matters more than people admit. When you are trying to explain statistical concepts to non-technical stakeholders, pointing at a printed curve and showing where a value falls is more intuitive than reading a p-value from a spreadsheet. It grounds the abstract numbers in something tangible. I have used that approach in boardroom meetings when explaining why a particular marketing channel underperformed against the predicted baseline. The table does not replace computational tools. It is a bridge between the raw math and the interpretation layer. That is why it remains relevant decades after it was first printed in textbooks. It is not about replacing software. It is about understanding what the software is actually doing underneath the hood.
Get the Full Details


