So You Want to Run a Solomon Four-Group Design
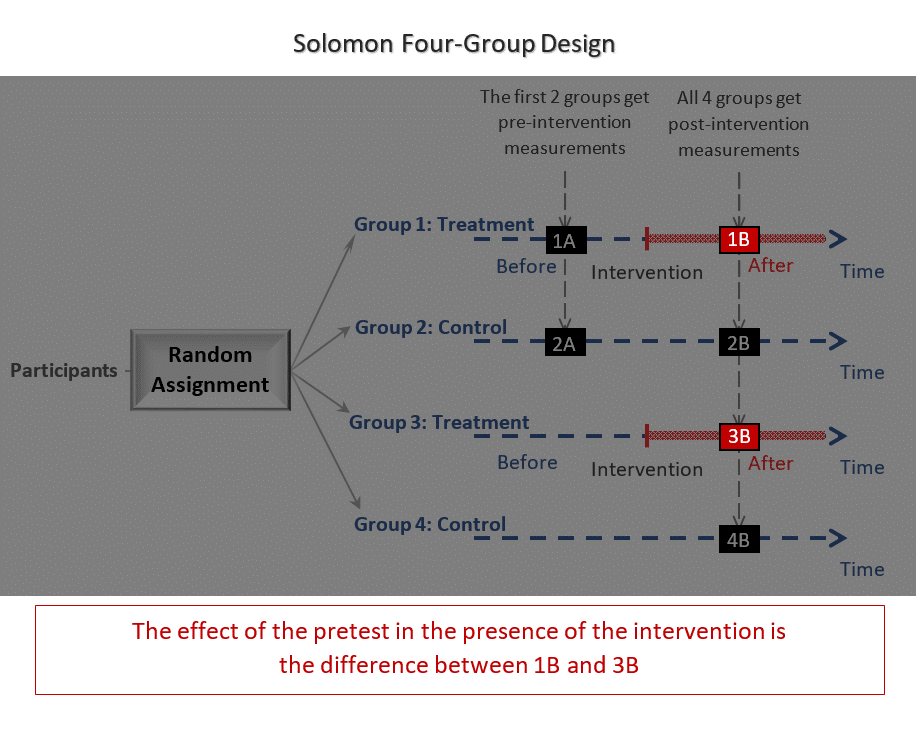
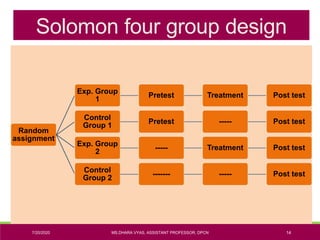
I spent several years running program evaluations for state-level workforce training grants, and the Solomon four-group design showed up more often than you'd think once people realized a simple pretest-posttest control group design was leaving too many holes in the causal story. It's not flashy. It won't make your stakeholders sit up and take notice. But it does something most people don't realize is even possible until they've been burned by a real threat to validity: it lets you untangle whether the program actually caused the outcome or whether something about measuring people before the intervention was silently contaminating your results. The design itself is straightforward on paper. You create four groups instead of the usual two. One group gets a pretest, then the treatment, then a posttest. A second group gets the pretest, no treatment, then the posttest. A third group skips the pretest entirely and just gets the treatment followed by the posttest. A fourth group gets neither the pretest nor the treatment, just the posttest. That's it. The math doesn't get much more complicated than comparing the posttest means across those four conditions while checking whether the pretest itself changed how the treatment landed. The reason people reach for this over a standard pretest-posttest control group design comes down to two specific threats that the simpler design can't separate out. First is the testing effect. When you administer a pretest, you're not just measuring people. You're sensitizing them to what the study is about. They start thinking differently about the topic. That means any change you see at posttest might partly reflect that pretest activation rather than the program itself. Second is the interaction of selection and treatment. If your groups aren't perfectly equivalent at baseline, the pretest can amplify or mask that existing difference in a way that makes your treatment look stronger or weaker than it really is. The Solomon four-group design exposes both problems by including groups that were never exposed to the pretest in the first place.
Let me walk through how I actually used this on a real evaluation. We were assessing a job readiness program for displaced manufacturing workers. The contract specified a pretest-posttest control group design, and we'd already run three cohorts using that structure. The results came back showing a statistically significant improvement in employment outcomes for the treatment group. Then we started getting pushback from the state auditor who noted that the pretest itself was essentially a mini career assessment that taught people how to fill out employer applications. In other words, the measurement was the intervention. We didn't have controls for that. We couldn't go back and redo the earlier cohorts, so for the fourth cohort we restructured everything into a Solomon four-group design to finally isolate what was actually driving the result. Group one received the full pretest, the job readiness training, and the posttest Employment Readiness Score. Group two got the pretest, sat in a holding room doing unrelated paperwork for the same duration, and then took the posttest. Group three skipped the pretest entirely, went straight into the training, and took the posttest. Group four got nothing except the posttest. What we found was interesting enough that it changed how we reported to the funder. The treatment effect in groups one and three was roughly the same size, which meant the pretest wasn't meaningfully interacting with the program. But group two, the pretested control group, actually scored higher on the posttest than group four, the nonpretested control. The pretest itself had given control group participants a small but measurable boost just from being asked to reflect on their employment status. That finding wouldn't have been visible with any simpler design. Here's what the analysis looks like in practice. You're really running a two-way ANOVA with treatment condition and pretest exposure as your two factors. Treatment has two levels: received it or didn't. Pretest exposure also has two levels: yes or no. The cell means are your four group posttest outcomes. The main effect of treatment tells you whether the program works on average. The main effect of pretest tells you whether taking the pretest alone shifted outcomes. The interaction term is the one most people skip over, but it's the most important one: it tells you whether the pretest changed how the treatment worked. If that interaction is significant, you can't just report a single treatment effect. You have to report it separately for pretested and nonpretested participants because they're responding differently.
One thing nobody tells you about the Solomon four-group design is the sample size requirement. You're dividing your total sample into four cells instead of two, so each group needs to be large enough to detect meaningful differences on its own. I always aim for at least fifty participants per cell when the outcome measure is continuous with moderate variance. If you're working with binary outcomes like employed versus unemployed, you need more. I typically don't recommend running this design unless you can get roughly two hundred participants total, and realistically closer to three hundred if you want adequate power for the interaction test. The interaction effect is always the hardest thing to detect, and it's also the thing that makes the design worth using. There's a practical complication that comes up when you're implementing this in the field. Recruiting people into the no-pretest conditions is trickier than it sounds because participants and site staff naturally wonder why they're being treated differently. In our workforce evaluation, I had to rewrite the consent language to explicitly say that all participants were part of a study comparing different ways of delivering employment services, and that some people would complete a short questionnaire before starting the program while others would not. Both approaches were part of the service delivery model being evaluated. Without that framing, people in the no-pretest groups felt like they were getting the short end of the stick, and retention dropped noticeably in those cells. I don't think that's a problem unique to this design, but it's one I ran into directly and had to work around by being upfront about the structure rather than hiding it. Another thing that catches people off guard is data collection timing. With four groups running simultaneously, you need to coordinate when the pretest goes out and when the treatment sessions start so that all four groups finish their posttest windows at roughly the same time. If your treatment group finishes three weeks earlier than your control group, seasonality or external events could introduce confounding that no statistical adjustment can fully clean up. I use a fixed calendar where each group has hard start and end dates, and I build in buffer days for people who miss sessions. The Solomon four-group design doesn't forgive sloppy scheduling the way a simpler design sometimes gets away with it because you're already juggling more moving parts.
Get the Full Details

The main downside of this approach is cost and complexity. You need roughly twice the sample size of a standard control group design, you're running more data collection waves in some cells, and the analysis requires someone who actually understands factorial ANOVA or can work with a statistician who does. I've seen people try to analyze Solomon four-group data by just comparing treatment to control ignoring the pretest factor, which defeats the entire purpose of the design. If you're going to collect the data, you might as well analyze it correctly. There are also scenarios where the Solomon four-group design doesn't help much. If your outcome is stable and your treatment has a very strong effect, a simpler design will give you the same answer with less effort. The value of the four-group structure shows up most clearly when you suspect testing effects or selection-treatment interactions are plausible threats in your context. If you're evaluating something like a curriculum-based intervention where the act of taking a knowledge test before the course is likely to change learning, the design is genuinely useful. If you're evaluating a material benefit distribution where there's no cognitive component to the pretest, you're probably better off with a standard randomized control trial. For software, most people run this in R or SPSS. In R, the basic model is a two-way ANOVA with posttest score as the dependent variable and treatment and pretest exposure as fixed factors. You can also fit it as a linear model and check the interaction term directly. The output gives you cell means, main effects, and the interaction F-test in one pass. If your outcome is binary, you switch to logistic regression with the same predictor structure. There's no special package you need. The design doesn't require anything exotic, which is part of why it's held up since Campbell introduced it in 1951.
What I wish more evaluators understood is that the Solomon four-group design isn't a magic bullet for causal inference. It's a targeted tool for a specific set of validity problems. It handles testing effects and selection-treatment interactions better than almost anything else you can run without a full factorial treatment structure. It doesn't protect against attrition bias, which becomes a real concern when you have four groups and people drop out at different rates across cells. I lost about twenty percent of my fourth-cohort sample to attrition, and the no-pretest treatment group shed significantly more people than the others, probably because some participants expected the questionnaire and were disappointed when it was skipped. That differential dropout is a problem no design fixes on its own, and it's worth tracking carefully from day one. The bottom line is that the Solomon four-group design exists for a reason and it solves real problems that simpler designs quietly ignore. It's not glamorous. It requires more participants and more coordination. But when you need to know whether your program effect is real or partly an artifact of how you measured people beforehand, it's one of the most straightforward ways to find out.