Self-Healing Infrastructure Is Everywhere Now, Mostly Because You Don't Want to Wake Up at 3 AM Again
I spent the first half of my career doing exactly what the title of this thread describes, except nobody called it that back then. We just called it "keeping the site up while your phone goes off." The shift from manual intervention to automated repair loops in infrastructure has been happening so gradually most people don't notice the difference until they're debugging something old and realize it should have been dead simple by now. At its core, this is about systems that detect failures and fix them without a human being reading an alert and opening a terminal. You've probably encountered this already and didn't realize it. Kubernetes rolling restarts on failed pods. Cloud providers automatically routing traffic away from a degraded availability zone. Database replication failing over when the primary node stops responding. These are all forms of the same pattern, just wearing different hats depending on which team built them. The mechanism is straightforward enough that explaining it feels almost insulting. You run a health check on a schedule, you compare the result against an expected state, and when there's a mismatch you execute a remediation action. The complexity doesn't come from the concept, it comes from making sure the remediation action itself doesn't create new problems while fixing the old one.
I ran into this exact issue last year on a production database cluster where the automated failover was working correctly but creating a split-brain scenario because the network partition wasn't clean. The fix required adding a fencing mechanism, specifically a STONITH device or shoot-the-other-node-in-the-head approach, so that the old primary couldn't continue serving writes after it was declared dead. Without fencing, automated repair is just automated data corruption with extra steps. This is the kind of thing that usually only becomes obvious when your application has already written inconsistent data across two primaries.
How the Core Components Actually Fit Together
You need three things working in concert: detection, decision, and execution. Detection is the observability layer, which means metrics, logs, and health checks covering the right scope. Most teams get this wrong by monitoring availability when they should also be monitoring correctness. A service can return 200 OK while silently dropping database writes. That passes your health check and your auto-remediation never fires because nothing is technically broken from the system's narrow perspective. Decision logic is where the automation actually happens. This isn't just a simple if-failure-then-restart rule. You need to account for cascading failures, flapping services that might recover on their own if given time, and the difference between a transient error and a real degradation. Circuit breakers and retry budgets exist for exactly this reason. I've seen people implement auto-restart logic that created a boot loop because there was no backoff strategy between restart attempts, so the service would crash, restart, crash again within seconds, and consume all available resources before anyone noticed anything was wrong. Execution is the actual remediation action, and this is where the hardest decisions live. Should the system restart the container, kill the pod, drain the node, fail over to a secondary region, or roll back a deployment? The answer depends on what actually failed and how confident you are that the failure mode is understood. Blindly restarting a process that is crashing due to a memory leak just makes the problem worse over time because you keep resetting the counter instead of addressing the root cause.
Get the Full Details
Practical Implementation Patterns That Actually Work
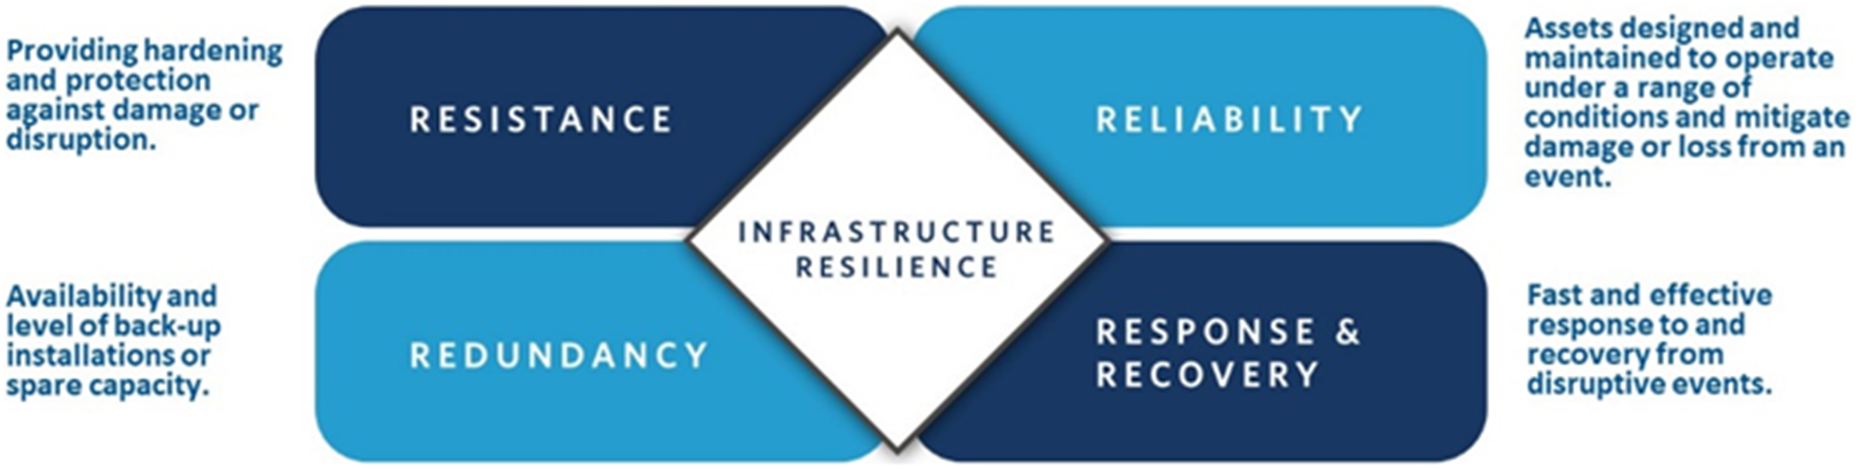
The most reliable approach I've used across multiple environments is a layered defense model. The innermost layer handles individual component failures through health checks and automatic restarts with exponential backoff. This catches the vast majority of issues without any human involvement. The middle layer handles service-level failures using inter-service health probes and circuit breakers, preventing cascade failures from taking down the whole stack. The outermost layer handles infrastructure-level failures with cross-region failover and data replication verification. Each layer needs its own timeout and threshold configuration. This isn't a one-size-fits-all problem. A database replication lag alert needs different timing than a web server health check. I configured one setup where the auto-remediation for database read replicas was triggering during routine maintenance windows because the threshold was set too aggressively. The fix was to add a maintenance exclusion window and require a minimum duration of consecutive failures before any automated action would fire. This reduced false-positive remediation events from roughly twelve per day to about one or two. You also need to think about what happens when the automated system itself fails. This sounds obvious but people rarely implement it. If your auto-healing service crashes, you need another service or a manual override path that can handle the situation. I once worked on a cluster where the auto-scaling and self-healing components ran on the same nodes they were managing, which meant that if those nodes went down, the healing system went down with them and nothing could recover. The workaround was moving the healing orchestrator to separate infrastructure, though even that had complications when the networking layer between the orchestration plane and the worker nodes became the single point of failure.
What This Actually Saves You
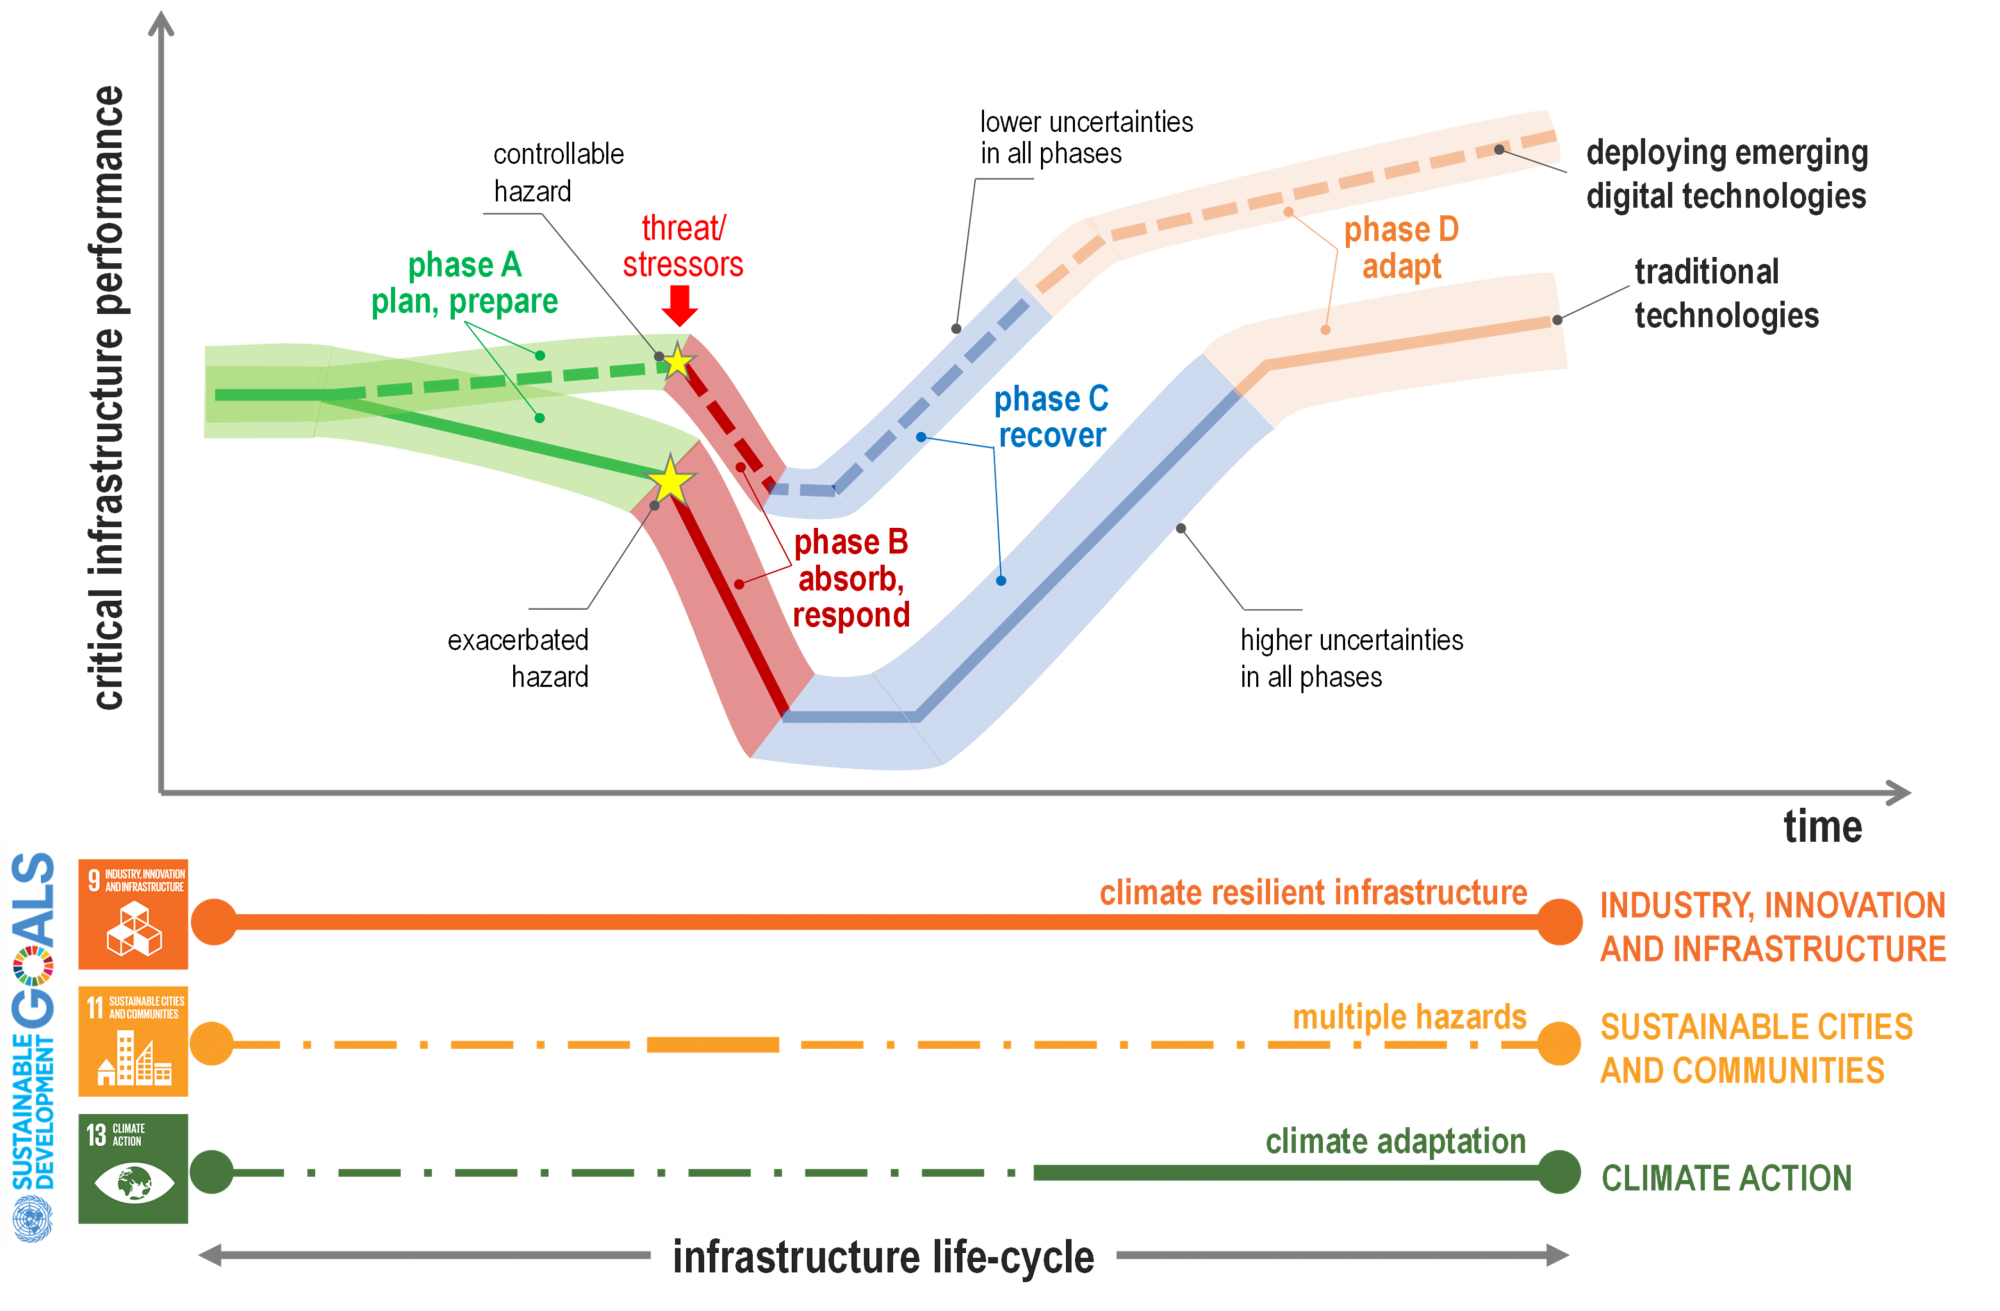
In practice, well-implemented automated repair systems reduce mean time to recovery from hours to minutes for the failure modes they cover. The exact numbers depend heavily on your architecture and how thoroughly you've thought through edge cases, but the difference between a human reading an alert at 2 AM and a system detecting and remediating the issue before anyone notices is measured in orders of magnitude. I've seen production incidents that used to take a team of four engineers thirty minutes to resolve get handled automatically in under two minutes by a properly configured system. The tradeoff is that building and maintaining these systems requires significant upfront investment and ongoing attention. You need comprehensive observability, you need to understand your failure modes, and you need to continuously test the remediation logic because something that worked perfectly six months ago might behave differently after a dependency update or a configuration drift. The systems that look effortless in production are the ones that someone spent probably more hours building and testing than they ever would have spent manually resolving individual incidents. There's also a psychological dimension that people underestimate. Once your team knows the system can handle certain failures automatically, they stop monitoring those failure modes as closely. This is rational but dangerous because it means the automated system becomes the only line of defense for something everyone assumes is handled. I've seen multiple teams become complacent about monitoring coverage for failure modes that had been automated, and when something unusual occurred that the automation didn't account for, nobody had the context to intervene quickly because they'd forgotten how the system was supposed to behave under those conditions.
Where These Systems Fail Hard
Automated repair systems have real limitations that most vendors and article writers gloss over. They work well for known failure modes with clear recovery paths. They work poorly for novel failures, race conditions, and anything that requires contextual understanding of business logic. A database might be healthy from the system's perspective while the application layer is experiencing data integrity issues caused by a bad deployment. The auto-remediation won't trigger because there's no failure to detect at the infrastructure level. Another major limitation is the amplification problem. When automated systems act too quickly or too aggressively, they can turn a minor issue into a major outage faster than a human could. I experienced this on a cluster where the auto-scaling and self-healing logic responded to increased latency by spinning up new instances and restarting existing ones, which actually made the latency worse because the restarts caused connection queue buildup and resource contention during the scaling event. The system was technically doing what it was designed to do, but the design didn't account for the feedback loop between scaling actions and the underlying resource constraints. The best approach I've found is combining automated repair with strong guardrails and human oversight for anything beyond the most straightforward failure modes. Use automation for the boring, predictable stuff and keep humans in the loop for complex or ambiguous situations. This means implementing approval workflows for high-impact actions, maintaining runbooks for scenarios the automation can't handle, and regularly reviewing automated incident reports to make sure the system is doing what you expect it to do rather than something technically correct but practically wrong.

The tools available for building these systems include things like Kubernetes operators, chaos engineering frameworks, custom automation scripts, and various platform-level solutions from cloud providers. None of them are silver bullets. The ones that work well in production are usually the ones where someone actually understands the failure modes they're trying to address and has spent real time testing the recovery paths under realistic conditions rather than just configuring something and hoping for the best.