Why your moderation team keeps getting it wrong
I spent three years running trust and safety for a platform that grew from two million to forty million monthly active users. The scissor effect is what happens when you scale moderation faster than your ability to train people. Content gets cut into two buckets, right and wrong, gone and stayed, with no room for the messy middle where most real violations actually live. Most teams don't realize they're experiencing this until public backlash forces them to look at their own data. The pattern is predictable but easy to miss day to day.
The Scissor Effect Unlocking The Secrets Of Social Media Moderation
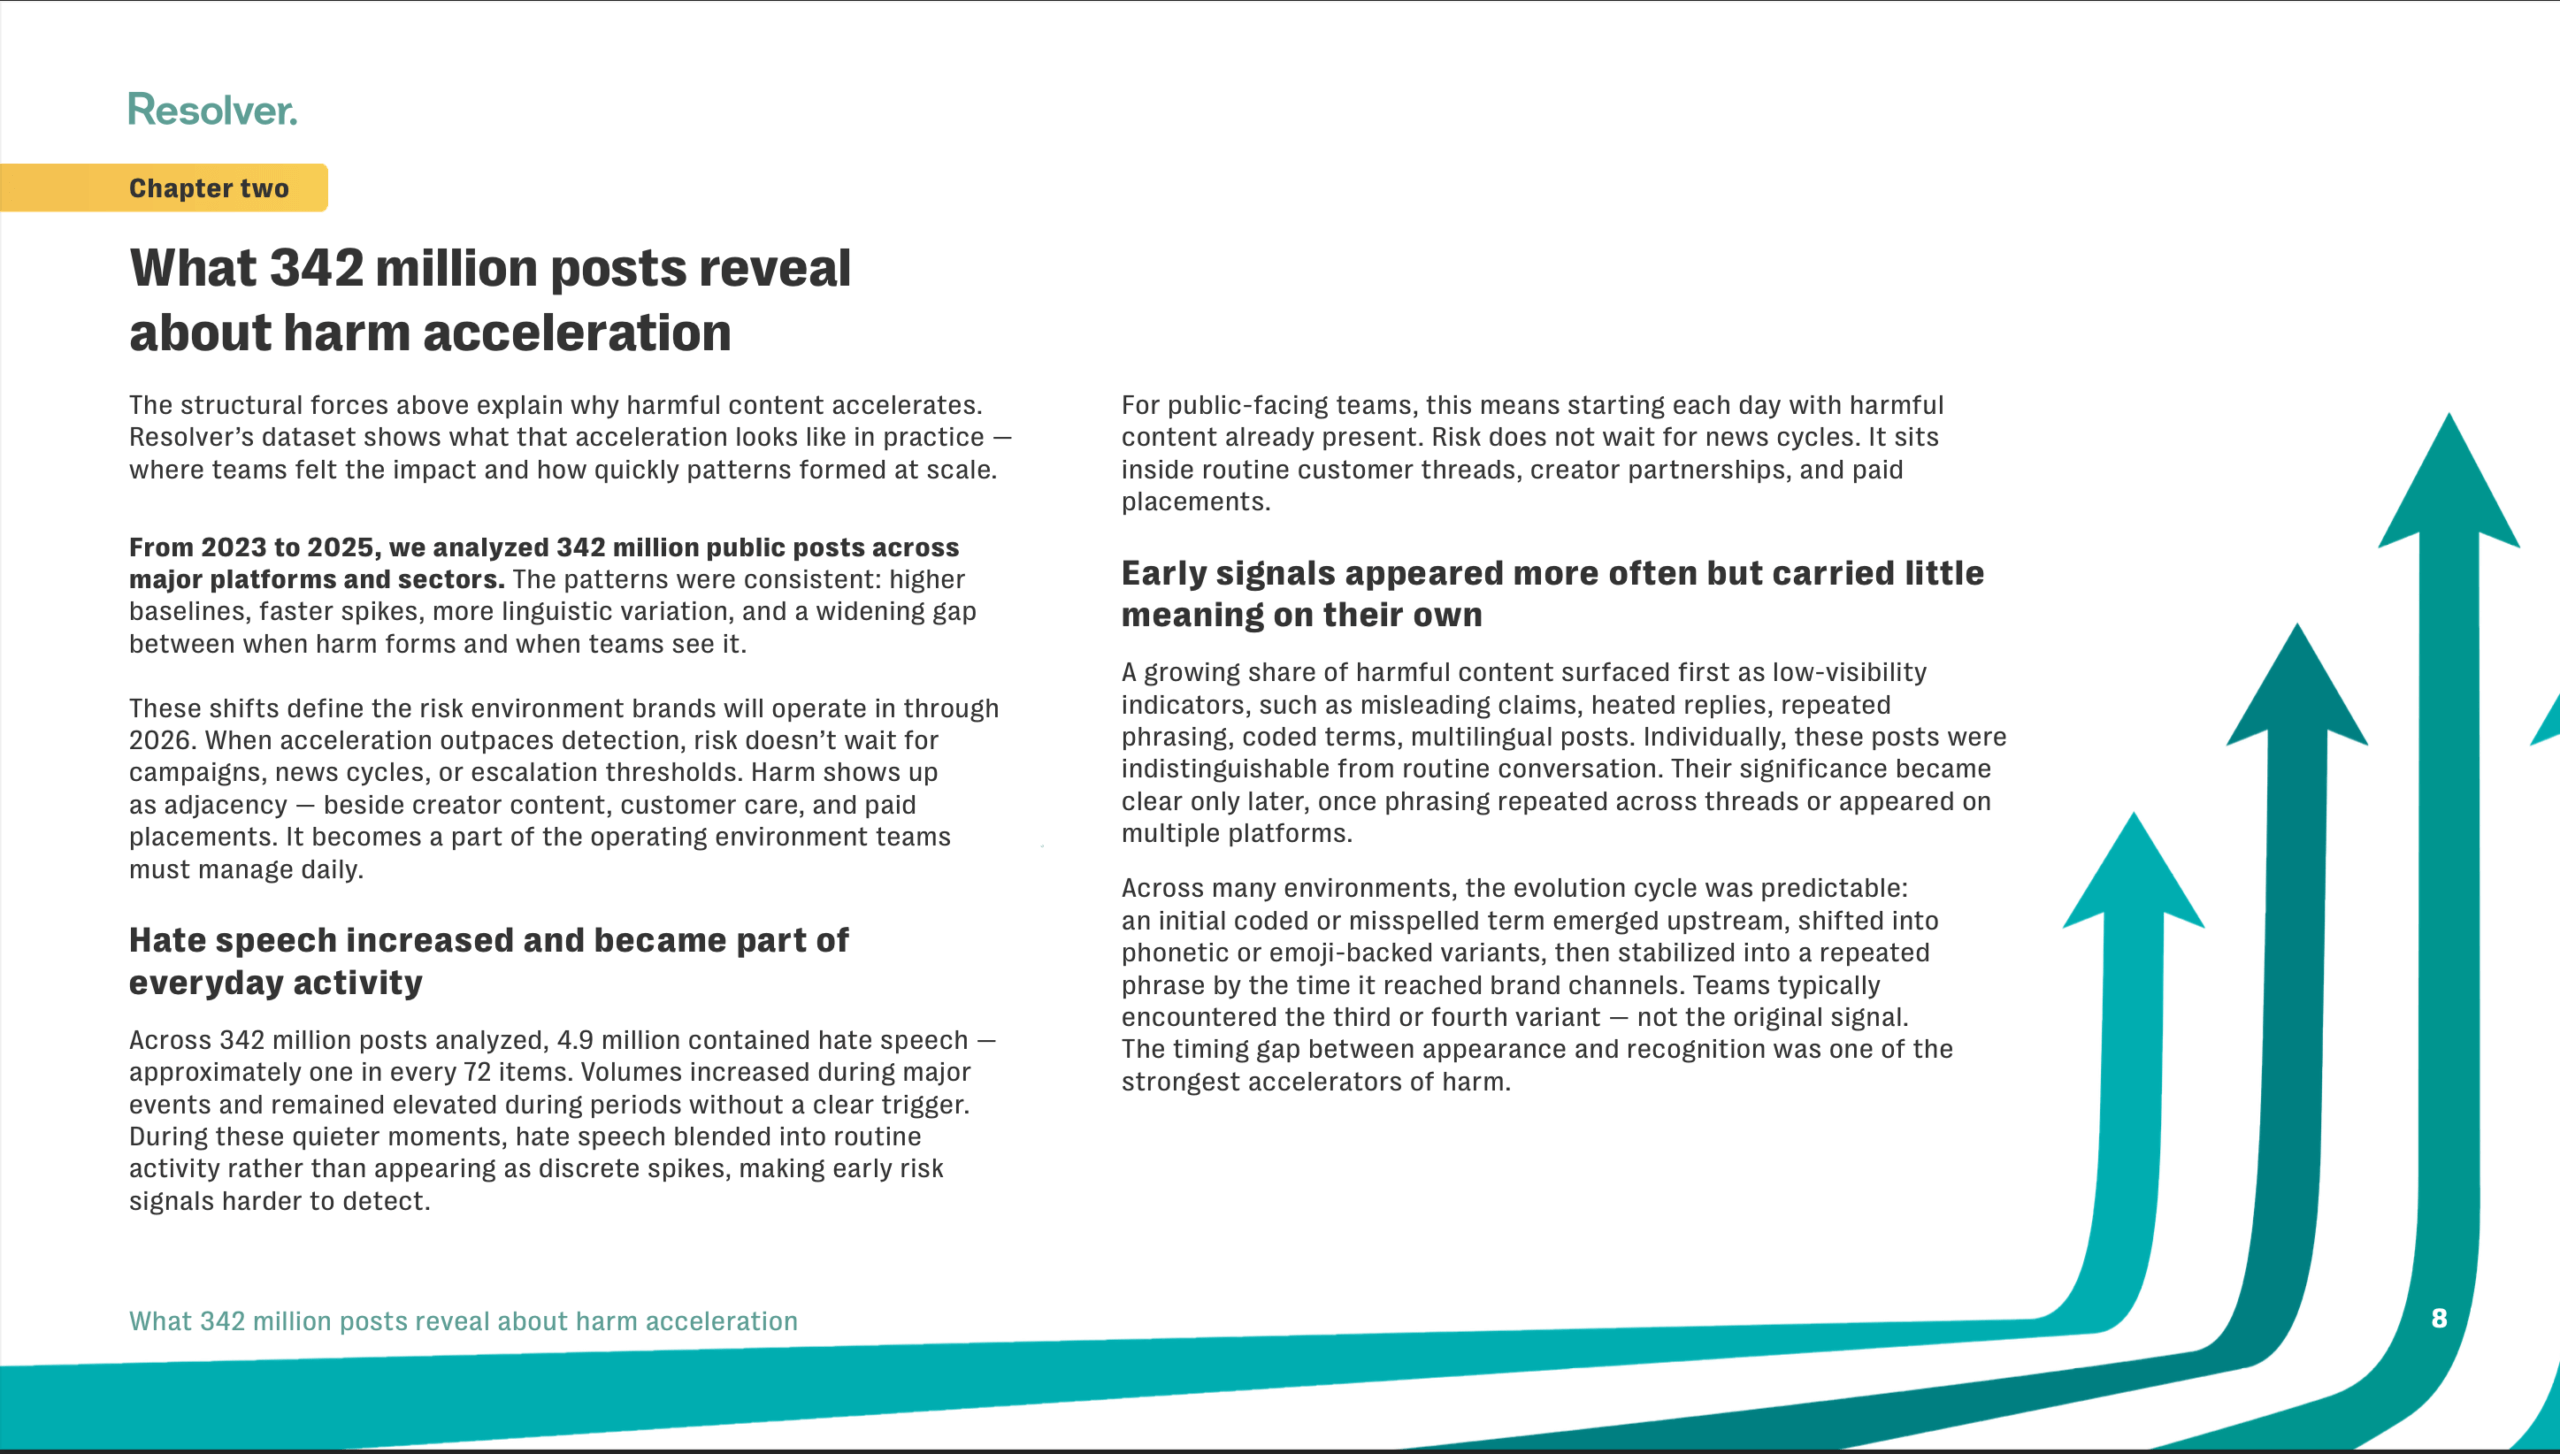
Here is how it actually works in practice. You start with a small team of humans reading everything. A senior moderator sees context, cultural framing, and borderline cases that don't fit neatly into policy. They make nuanced calls, sometimes wrong, often defensible. Then growth hits. You hire contractors. You bring in classifiers. You write more automated rules because humans are expensive and slow. The system starts acting like a pair of scissors. Everything either passes through one blade or the other. The gray area in the middle gets squeezed shut. False positives spike. Context-dependent content dies in large volumes. Real threats slip through because the model only recognizes simplified patterns, not actual harm. I saw this clearly when we migrated from a purely human queue to a hybrid system at a mid-tier social app. The false positive rate on hate speech calls jumped from around eight percent to nearly thirty-four percent within six weeks. The drop in true negatives was worse. We caught fewer genuine doxxing cases because the classifier was aggressively filtering conversational speech that contained keywords the policy had flagged. People talking about their experiences being harassed got the content removed anyway. The quotes got stripped out, the reports got buried, and the affected users left the platform.
The workaround was ugly but it worked. We introduced a tiered routing system. Simple, high-confidence violations go straight through automation. Anything with a confidence score between zero point four five and zero point seven gets reviewed by a human who has completed contextual training, not just the standard four hour onboarding video. That middle band is where the scissor effect does the most damage, so putting humans back there matters more than anything else we tried. It cut false positives back down to eleven percent and improved our doxxing detection by roughly sixty percent over the next quarter. Most people skip this because it slows throughput. They want one clean pipeline, not three. That is why the scissor effect keeps repeating across the industry. Speed wins over accuracy every time unless someone actively fights for the latter.
Get the Full Details
What the scissor effect actually looks like in your metrics
You can see it in the numbers before it shows up in complaints. The most reliable indicator is the gap between your precision and recall over time. When precision climbs but recall drops, or when both metrics look fine individually but violation appeal rates spike, you are losing nuance somewhere in the funnel. Another tell is what your classifiers treat as high risk. Look at the keyword lists your automated system flags most often. If the top terms are verbs like "kill" or "die" or phrases that appear in ordinary conversation, your scissors are cutting too wide. We once had a gaming community moderated by a model that automatically removed any post containing the word "shot" because it associated the term with violence. In that context, ninety percent of those posts were about archery, video games, or photography. We caught that after a content creator posted a thread about his new camera rig and it got removed alongside three separate harassment reports that mentioned actual firearms. The fix there was not better training data. It was adding a category for domain-specific context and routing that domain to reviewers who actually understood it. A generalist reviewer from another vertical would have made the same call either way.
Why automated systems make this worse instead of better
Machine learning classifiers optimize for statistical boundaries, not social meaning. They draw lines where the data separates cleanly. Social violations rarely separate cleanly. They cluster, overlap, and shift depending on audience, geography, and current events. The scissor effect is the natural output of trying to force fluid social dynamics into rigid binary classification. I have seen teams hit a wall trying to tune models past a certain point. No matter how many examples you feed it, the precision recall tradeoff plateaus and then reverses. You add more positive examples to catch nuance and you start misclassifying again. You tighten thresholds and you miss the edge cases that matter most. This is not a data problem. It is a fundamental limitation of binary classifiers applied to social behavior. Human reviewers still outperform models on context dependent violations even when they are fatigued. Fatigue is a real factor in moderation work. Reviewers make mistakes when they process thousands of items per shift. But their mistakes look different from classifier mistakes. Human errors tend to cluster around familiarity bias and desensitization, not systematic keyword mismatches. You can mitigate human error with rotation and calibration checks. You cannot fix a model that was trained on data missing an entire dialect of speech your community actually uses.
Practical steps to reduce the scissor effect in your operation
First, stop treating your content queue as one pipeline. Break it into at least three tiers based on confidence scores and policy severity. High confidence automation. Medium confidence human review. Low confidence escalation to a specialized reviewer or a holds queue pending human assessment. Second, audit your classifier decisions weekly using a stratified sample. Do not just look at overall accuracy. Pull samples by domain, by region, by post type, and by time of day. The scissor effect tends to show up unevenly across these dimensions. What looks fine at the aggregate level often hides severe bias in specific slices. Third, track appeal outcomes separately from initial moderation decisions. Appeals are where your missed nuance shows up. A team I worked with found that twelve percent of all removal appeals were successfully overturned on first review. Most of those appeals were filed by repeat offenders who had been incorrectly flagged in the past, which meant those users were more likely to file future appeals even for legitimate removals. The data looked noisy until we separated repeat appellants from one time appellants. Once we did, the true rate of moderator error became obvious and we could retrain without the signal getting lost in applicant behavior patterns.

Fourth, invest in reviewer training that focuses on edge cases rather than policy restatement. Your team knows the rules. They need practice recognizing when the rules do not apply. Run simulation exercises where reviewers grade borderline content and then compare notes. You will see disagreement rates that reveal exactly where your scissor blades are cutting too aggressively. Finally, accept that some content will always land in the gray zone and build a process for handling it rather than pretending it does not exist. A hold queue with a turnaround target of twenty four to forty eight hours is better than an automated removal that cannot be reversed quickly enough to prevent user churn. I have seen platforms lose significant engagement from simply failing to restore content on time after a reviewer catches the error. The mistake happens fast. The correction takes too long.
When the scissor effect is unavoidable
There are scenarios where you cannot avoid binary outcomes entirely. Live stream moderation during high traffic events, crisis response where harmful content spreads in minutes, and legal compliance deadlines that require immediate action are three cases I dealt with regularly. In these situations the scissor effect is sometimes the best available option because delay causes more harm than precision misses. The trick is to know when you are in that category and when you are not. Most teams misapply crisis protocols to everyday content because it feels simpler to run everything through the same system. It is not simpler. It just feels familiar. Your normal content review pipeline should not be operating at crisis speed unless a crisis is actually happening. The operational drag and the accuracy loss compound over time even when no emergency exists. I stopped tracking whether content was technically correct anymore and started tracking whether the system was proportionate to the situation. That distinction matters more than anything else I learned during my time in this work. The scissor effect is not a bug. It is a structural consequence of scaling moderation without scaling judgment. You can manage it. You cannot eliminate it completely. The teams that perform best are the ones that admit that upfront and design their processes around the constraint instead of pretending the constraint does not exist.