Understanding Carbohydrate Structures Beyond The Basics
When you see CHO written on a label, that's glucose, fructose, or galactose. Same formula, different arrangement. The empiricals are straightforward—any mono- or disaccharide follows the pattern C(HO)—but the structural implications are where most people stop paying attention. They don't need to. The arrangement of atoms determines everything about reactivity, solubility, and biological function. I spent several months working with a mixed-sugar fermentation system where the yeast kept favoring one isomer over another in unpredictable ways. The HPLC traces looked fine, but the yield was always lower than expected. After spending a week troubleshooting the chromatography method, I realized the real issue was mutarotation. I'd prepared my standards from crystalline alpha-D-glucose and dissolved them directly without allowing time for equilibrium. The polarimetry readings came in low because the beta form hadn't developed yet. The bacteria were consuming the alpha form faster than it could equilibrate. Letting the solutions sit for two hours before calibration fixed the problem entirely. No new equipment, no protocol overhaul. Just patience with the chemistry.
The Science Of Carbohydrates Unlocking The Power Of Chemical Formulas
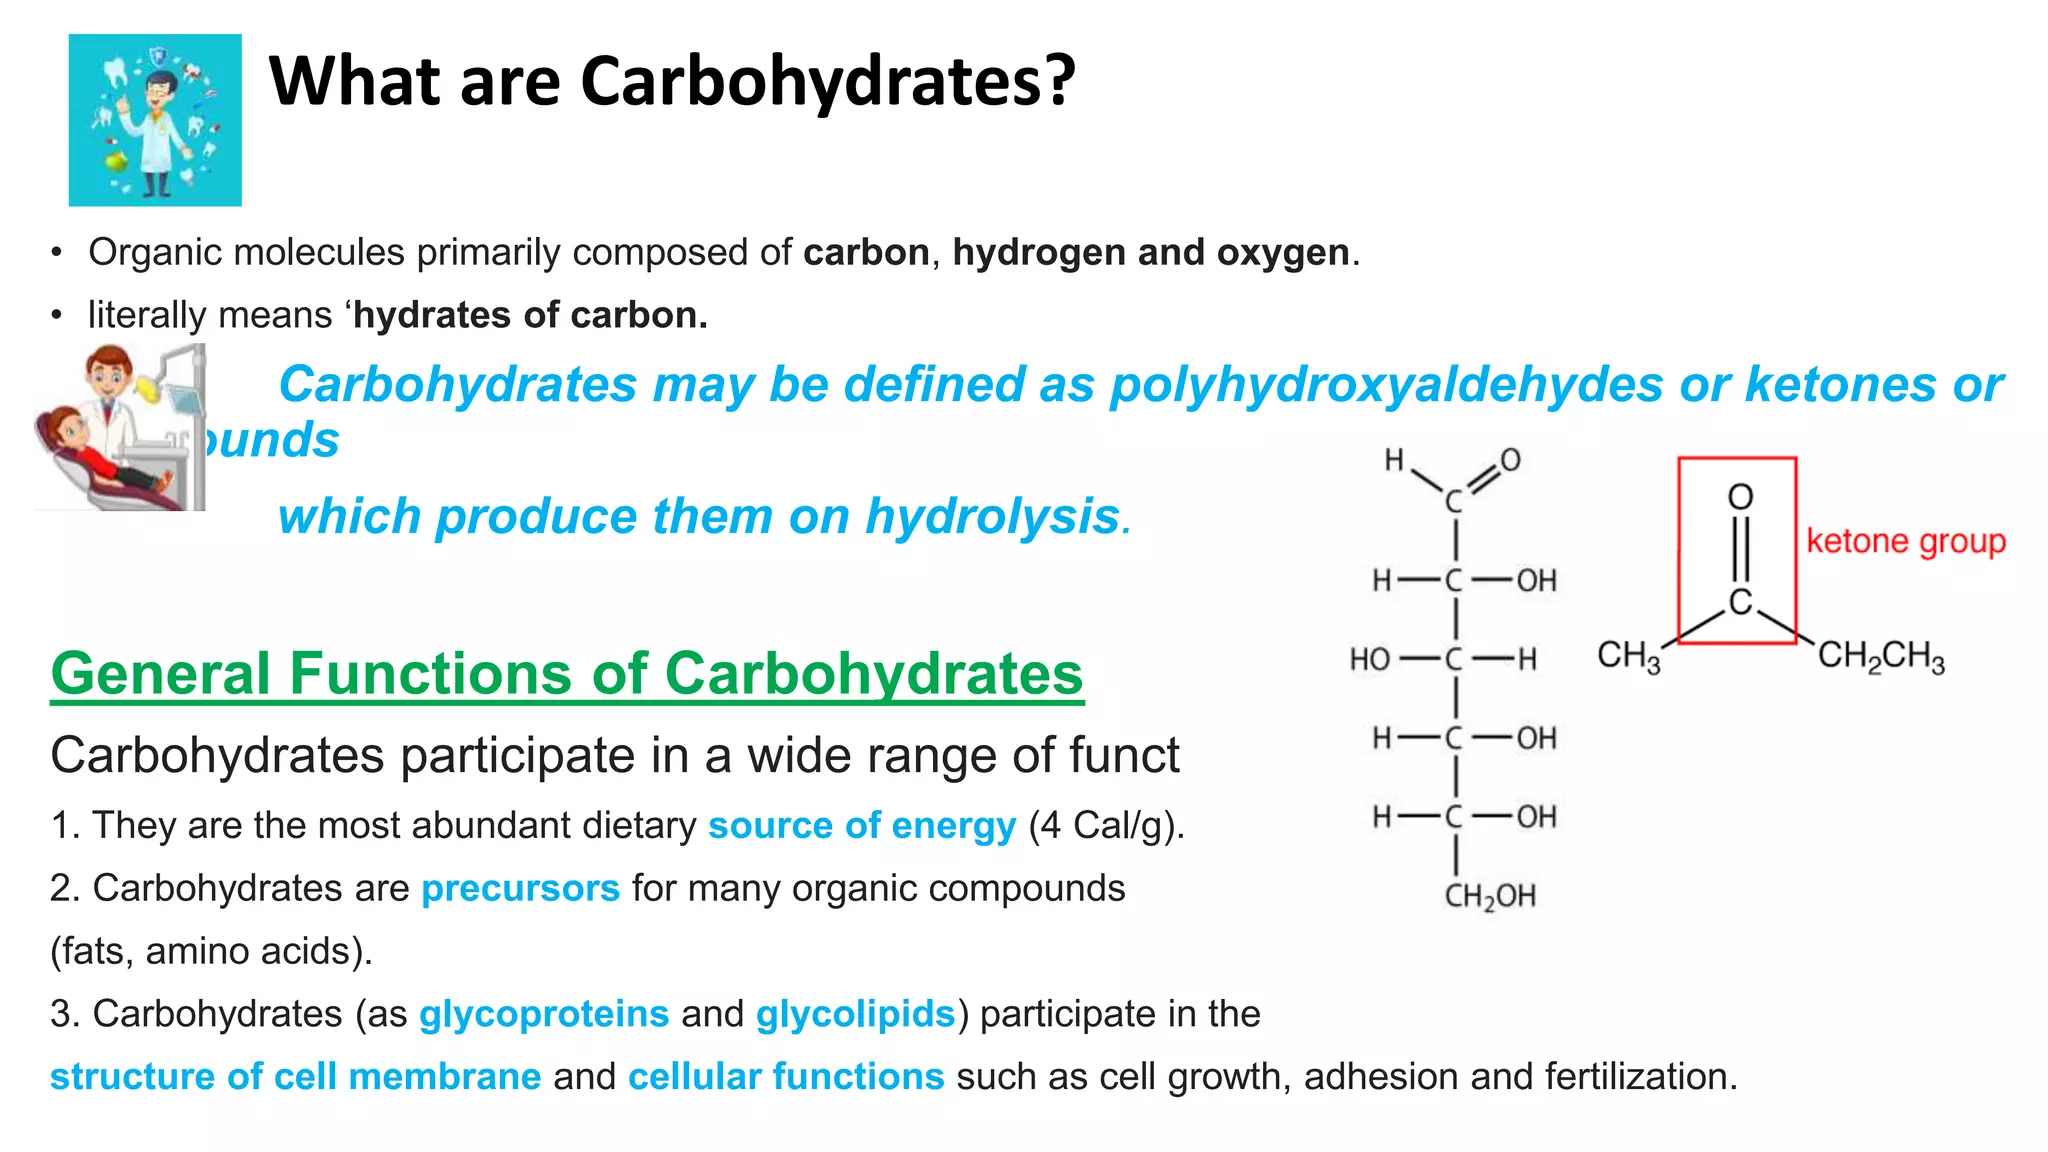
The empirical formula CHO is where everything starts. It's not a coincidence that carbohydrates contain this ratio—it reflects the fact that these molecules are essentially polyhydroxy aldehydes or ketones. That definition covers everything from a single glyceraldehyde molecule to cellulose chains stretching into thousands of units. The challenge is that the empirical formula hides the actual structure. Two compounds with identical formulas can have radically different properties. Consider maltose and cellobiose. Both are CHO, both are disaccharides made from two glucose units. The only difference is the glycosidic bond: alpha-1,4 in maltose, beta-1,4 in cellobiose. Maltose is sweet and digestible. Cellobiose is tasteless and indigestible to humans because we lack the enzyme to break beta linkages. The formula doesn't tell you this. Only the structure does. This is why the word "structure" matters more than "formula" in carbohydrate chemistry. The molecular formula gives you the molecular weight. The structural formula tells you whether a compound will reduce Fehling's solution, whether an enzyme will recognize it, and whether it will form a crystalline solid or a glassy amorphous mass. All of these properties come from how the atoms connect, not just which atoms are present.
Anomeric carbon chemistry is where things get genuinely interesting. When a linear sugar cyclizes, the carbonyl carbon becomes a new stereocenter. This is the anomeric carbon, and it exists in two configurations: alpha and beta. The difference between these two forms is what drives mutarotation, what determines whether you get starch or cellulose from the same monomer, and what makes glycosidic bond formation controllable in synthesis. In solution, the alpha and beta forms interconvert through the open-chain intermediate. For D-glucose at equilibrium, you get roughly 36 percent alpha and 64 percent beta. The ratio varies by sugar. For N-acetylglucosamine, the beta form is significantly more stable due to the anomeric effect—the preference for an electronegative substituent at the anomeric position to occupy the axial orientation. This effect is real, it's measurable, and it matters when you're designing a glycosylation reaction or interpreting NMR data. I encountered this directly when optimizing a glycosyl donor for oligosaccharide synthesis. The literature recommended a specific glycosyl trichloroacetimidate donor expecting predominant beta selectivity based on neighboring group participation. The NMR of the product showed the opposite—an alpha linkage had formed instead. Running through the possibilities, I traced the issue back to the solvent system. The reaction was running in dichloromethane, but switching to a more polar solvent mixture shifted the ion pair dynamics enough to flip the selectivity. The structural prediction from the formula was correct; the actual outcome depended on conditions that the formula couldn't capture. It took me three rounds of optimization to get the selectivity I needed, but the core lesson stuck: formulas predict, conditions determine.
Get the Full Details
Polysaccharides complicate things further because the same monosaccharide can form entirely different materials depending on linkage geometry. Starch and glycogen use alpha-1,4 linkages with occasional alpha-1,6 branches, creating helical structures that pack loosely and are accessible to enzymatic hydrolysis. Cellulose uses beta-1,4 linkages, producing straight chains that stack into microfibers held together by hydrogen bonds. The mechanical strength of cellulose is orders of magnitude higher than starch, and both come from identical glucose units. The degree of polymerization in natural polysaccharides is never uniform. Starch contains amylose chains ranging from a few hundred to several thousand glucose units and amylopectin chains that can exceed a million. Glycogen is more highly branched with an average chain length of 13 to 18 glucose residues between branch points. This heterogeneity is inherent to biosynthetic pathways and affects everything from solubility to enzymatic degradation rates. If you're working with purified carbohydrate samples, there are a few practical details that will save you time. Hydration state matters more than people expect. Many carbohydrate standards and reagents are sold as hydrates, and the water content affects molar calculations. I once prepared a buffer system using the wrong molecular weight because the bottle label listed the anhydrous form while the actual reagent was a monohydrate. The concentration was off by nearly six percent, and the downstream enzymatic assay didn't behave consistently until I recalculated everything from the Certificate of Analysis.
Crystalline carbohydrates often exist in a single anomeric form. When you dissolve alpha-D-glucose monohydrate crystals in water, the solution initially contains almost pure alpha anomer. Over the next several hours, mutarotation drives the system toward the equilibrium mixture. If you're doing kinetic measurements or preparing standards for quantification, the timing of when you make the solution relative to when you use it can introduce systematic error. Standardizing your samples at equilibrium, not immediately after dissolution, removes this variable. NMR is the primary structural tool for carbohydrate characterization. The anomeric proton signal typically appears between 4.5 and 5.5 ppm, and the coupling constant J, distinguishes alpha from beta configuration. An alpha linkage usually gives a coupling constant around 3 to 4 Hz, while beta linkages show 7 to 10 Hz. This is reliable for simple sugars but becomes complicated in larger oligosaccharides where peak overlap and second-order effects interfere. Two-dimensional NMR experiments like COSY, TOCSY, and HMBC resolve most of these issues but require more acquisition time and sample. Mass spectrometry complements NMR well. Electrospray ionization in negative mode works for acidic polysaccharides, and matrix-assisted laser desorption ionization is standard for higher molecular weight glycans. The fragmentation patterns reveal linkage positions and branching points. permethylation followed by MS analysis is particularly powerful—it stabilizes the glycosidic bonds during fragmentation and produces diagnostic ions that map the sequence directly.
There are limitations to every approach. NMR requires relatively large sample amounts—usually at least 5 to 10 milligrams for a good one-dimensional spectrum. Mass spectrometry struggles with isobaric sugars that have identical masses but different structures unless you combine it with chromatographic separation. Elemental analysis, which might seem like the most direct way to confirm a carbohydrate formula, can't distinguish between isomers at all. A proper structural characterization workflow combines multiple methods and cross-validates the results. Computational methods are improving rapidly. Glycobiology software can predict NMR chemical shifts from proposed structures and compare them against experimental data. Molecular modeling can assess the stability of different glycosidic conformations. These tools are useful but not reliable enough to replace experimental validation. A computed structure that looks reasonable on paper can still be wrong if the actual crystal packing or solution conditions favor a different conformation.

What Most People Miss About Carbohydrate Formulas
The first thing is that the standard notation—like writing starch as (CHO)—compresses information that matters. The subscript 5 in the repeating unit reflects the loss of water during glycosidic bond formation. Each bond removes one water molecule from two glucose units. This is stoichiometrically correct but structurally meaningless. It tells you nothing about whether the bonds are alpha or beta, whether there are branches, or how long the chains are. The second thing is that carbohydrate nomenclature encodes structural information that formula notation doesn't. The name "maltose" tells you it's a glucose dimer with an alpha-1,4 linkage. "Raffinose" tells you it's a trisaccharide containing galactose, glucose, and fructose in a specific arrangement. The formula CHO alone conveys far less. Learning to read names as structural descriptors is one of the faster ways to build genuine understanding. The third thing, and this is the one that matters most in practice, is that carbohydrate chemistry is not modular in the way peptide or nucleic acid chemistry is. You can't assemble a disaccharide from two protected monosaccharide building blocks and expect high yield without carefully controlling stereochemistry at the anomeric center. Glycosylation reactions are among the most challenging in organic synthesis because you're creating a new stereocenter while forming a bond, and controlling both simultaneously requires understanding of leaving groups, protecting group strategies, and solvent effects.
The field has moved significantly past the old approaches. Automated glycan synthesizers now exist. Flow chemistry platforms handle glycosylation under controlled conditions. Computational prediction of linkage specificity is improving. But the fundamentals haven't changed. A formula tells you what atoms are present. Structure tells you what those atoms do. Understanding both is what separates someone who can read a carbohydrate paper from someone who can actually work with one.