Why Your Experiments Keep Falling Apart at the Replication Stage
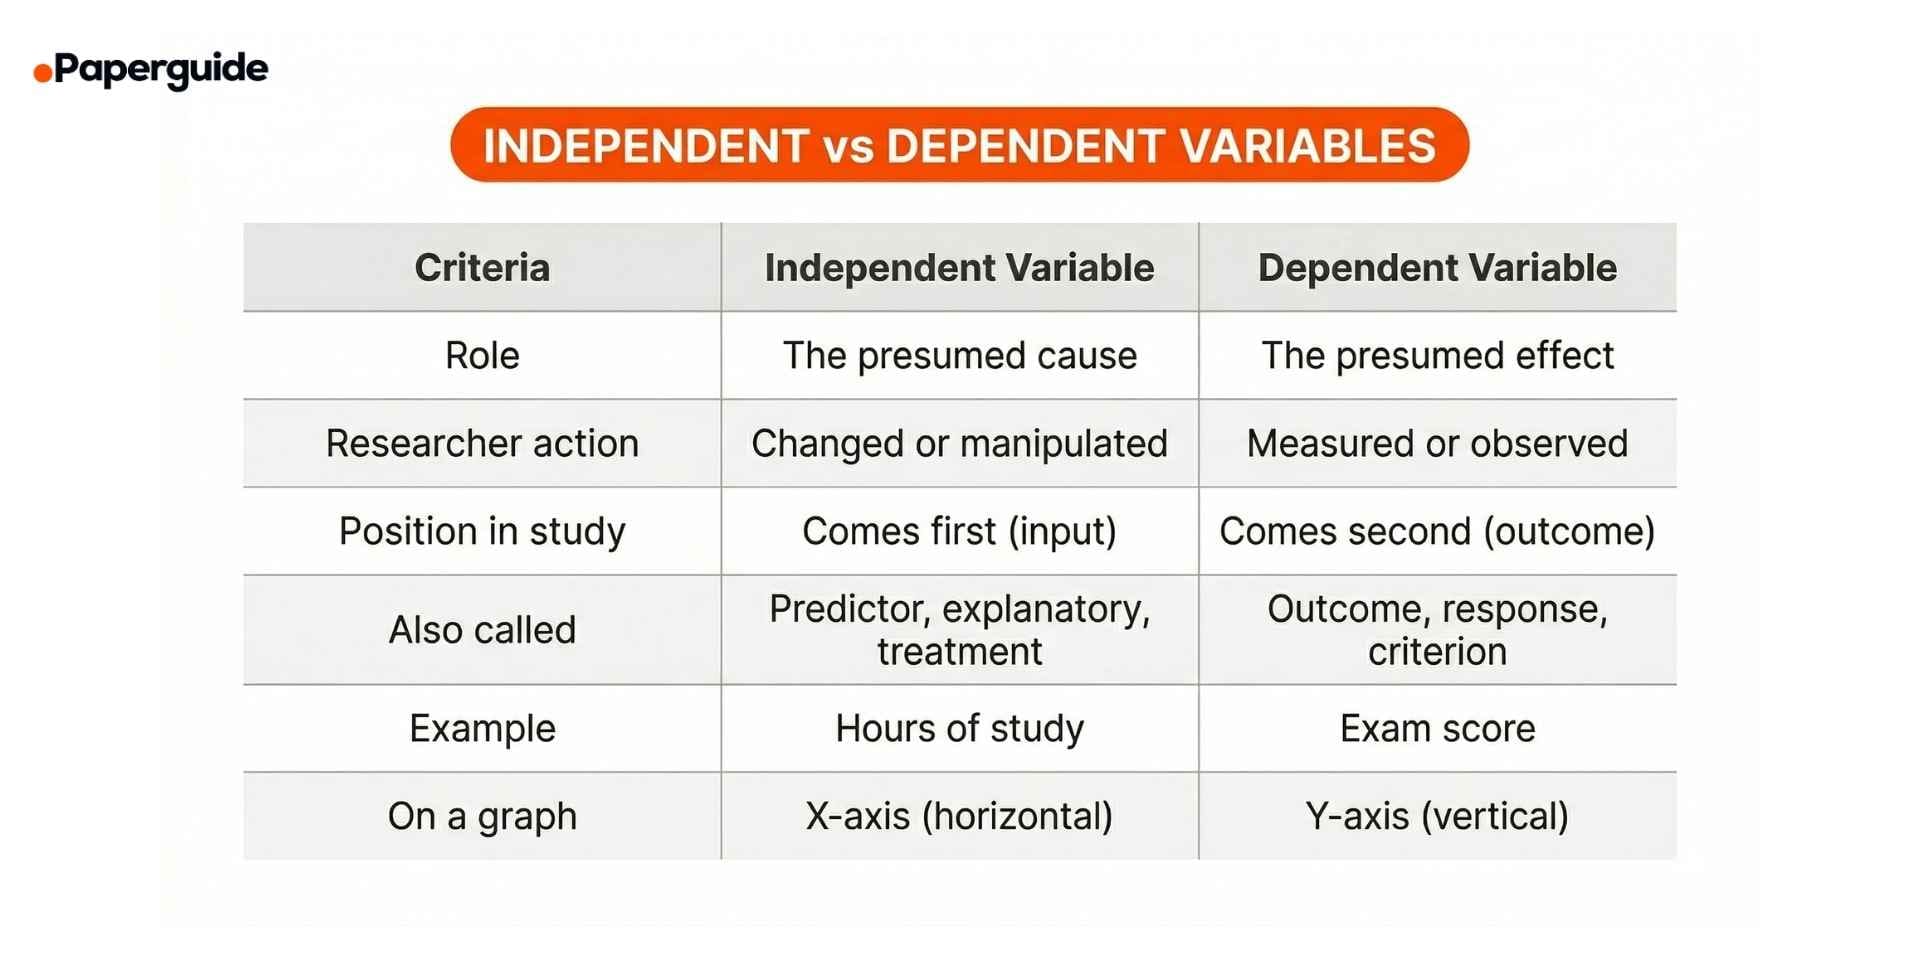
I've spent more years than I care to count watching people run well-funded studies, publish solid-looking results, and then watch everything collapse when another lab tries to reproduce it. The problem almost always traces back to one thing: a sloppy relationship between the independent variable and whatever the researchers are actually measuring. Not the experimental design, not the sample size, not the statistical test. The dependent variable itself. A dependent variable is simply the outcome you're tracking. But in practice, most people treat it as an afterthought. They throw a survey at participants, record a reaction time, or tally up some behavior, and call it a day. What they're missing is that the dependent variable is the entire structural foundation of the study. If it isn't properly isolated — meaning it cleanly reflects only the mechanism you claim to be testing — then every subsequent analysis is built on sand. Here's the practical reality. You pick an IV. You want to see if changing it causes a change in your DV. The DV has to be measurable, specific, and, most importantly, unconfounded by anything outside the causal chain you're claiming. That last part is where most people fail.
I worked on a project a few years back studying how background noise affects working memory performance. We used a digit span task as the DV. Early on, the results looked promising. Noise reduced recall accuracy by about eight percent. We were ready to publish. Then someone on the team noticed the effect wasn't uniform across conditions. The noise wasn't just degrading memory — it was causing people to shift their response strategy from maintenance rehearsal to a more superficial phonological loop. Our DV, as originally coded, couldn't distinguish between those two processes. We had been measuring something real, but we didn't actually know what we were measuring. The fix took us three weeks. We restructured the task to include a dual-tracking component where participants simultaneously held verbal material and tracked occasional visual probes. The probe detection rate served as a clean behavioral marker for attentional capacity separate from verbal storage. That separated the mechanism. The noise effect on pure storage dropped to statistical non-significance. The attentional cost remained significant. Two different findings replaced one vague conclusion. This is what isolating the dependent variable actually looks like in practice. It's not theoretical. It's the difference between a paper that holds up and one that doesn't.
How to Actually Isolate Your Dependent Variable
Start by writing out the causal pathway you think exists between your IV and DV. Don't do this in your head. Put it on paper. Map each step: IV produces change in X, which produces change in Y, which produces the measurable outcome Z. Now ask whether your chosen DV actually captures Y or whether it's picking up noise from somewhere else entirely. If your DV can change for reasons unrelated to your hypothesized mechanism, you haven't isolated it. You've just measured a correlated outcome. The distinction matters because correlation doesn't survive manipulation checks. Operationalize the DV with constraints. Define the exact metric, the exact time window, the exact exclusion criteria. Vague operationalizations are the fastest path to irreproducibility. "Stress level" means nothing until you specify whether you're using cortisol sampling, a validated self-report scale, heart rate variability, or galvanic skin response. Each of those tracks a different physiological system. They correlate imperfectly. Pick the one that maps onto your mechanism and stick to it.
Get the Full Details

Use manipulation checks, not as a formality, but as a diagnostic tool. After you run the IV, verify that the psychological or physiological state you intended to create actually shifted in the predicted direction. If your manipulation check fails, the DV results don't matter. You didn't manipulate anything.
Common Pitfalls That Kill Replicability
The biggest pitfall is conflating a correlate with a cause. You run an intervention, observe a change in the DV, and conclude causation. But if the DV is sensitive to third variables — order effects, participant expectations, environmental drift — you've only demonstrated association. The literature is full of these. A famous example involves priming studies where small contextual shifts completely reversed the effect. The DV was always there. The mechanism it indexed was never isolated. Another pitfall is using composite DVs that bundle multiple processes together. A single score that combines accuracy, speed, and confidence masks which component actually changed. When another lab tries to replicate, they might measure only one of those components and get a null result. Not because the effect doesn't exist. Because the original authors never specified which part of the composite was theoretically meaningful. Then there's the problem of insensitive DVs. When your measurement tool lacks the resolution to detect the effect size you're studying, you get null results that look like failures but are actually artifacts of poor measurement. Standardized tests with floor or ceiling effects are the worst offenders. I've seen labs waste months chasing effects that existed but couldn't be detected because the DV was capped at a maximum score well below where the true effect would manifest.
Advanced Nuance: The DV as a Mediator
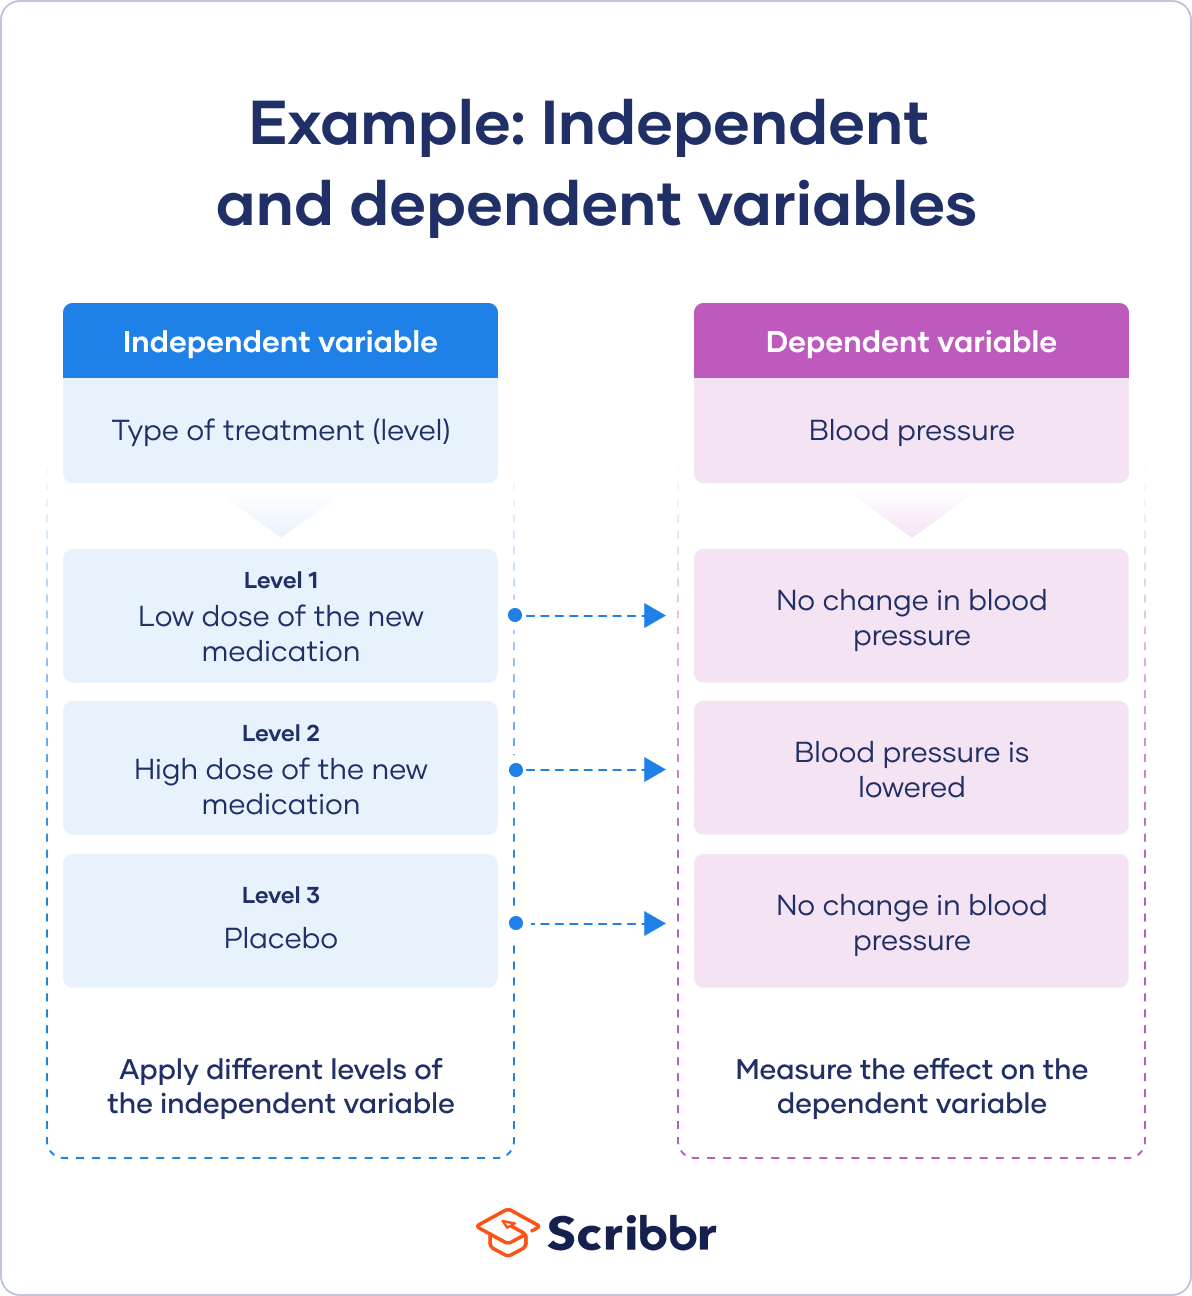
Here's something most introductory methods courses skip. Sometimes your dependent variable should also function as a mediator. Instead of treating the DV as a passive endpoint, design it so you can test whether the IV operates through the DV to produce downstream effects. This turns a simple comparison into a mechanistic argument. For example, if you're studying how sleep deprivation affects decision-making, don't just measure risk-taking as the DV. Also measure prefrontal activation patterns or behavioral markers of impulsivity as intermediate DVs. If sleep deprivation increases impulsivity markers, which then increase risk-taking, you've isolated a pathway. Without that intermediate step, you've only shown a black-box correlation. This approach requires more data collection and more complex modeling. Structural equation modeling or mediation analysis with bootstrapped confidence intervals becomes necessary. But the payoff is a study that tells you something specific about why the effect exists rather than just that it exists.
When Isolating the DV Isn't Enough
Let me be clear about the limits here. Isolating the dependent variable does not guarantee replicability. You can have a perfectly isolated DV and still fail to replicate if your sample is underpowered, your materials are poorly described, or your analysis pipeline contains undisclosed flexibility. The DV is necessary but not sufficient. Also, some fields simply resist clean isolation. Social psychology, clinical psychology, organizational behavior — these domains deal with systems where multiple variables interact continuously. Pretending you can fully isolate a DV in those contexts is naive. What you can do instead is acknowledge the contamination, measure the confounds explicitly, and include them as covariates or control conditions. Transparency about what you can't isolate is better than pretending you have. In fields where precise isolation is genuinely impossible, consider switching to a quasi-experimental design or a within-subjects crossover approach. These designs accept that perfect isolation won't happen and build statistical controls directly into the structure rather than hoping the DV will sort it out later.
A Practical Checklist Before You Collect Data
Before you run a single participant, answer these questions about your dependent variable: What specific construct does this DV index? Write it as a single sentence. If you can't, the DV isn't isolated. What alternative explanations could produce the same DV change? List at least three. If you can only think of one, you haven't thought hard enough.
What is the measurement sensitivity of this DV? Run a quick power analysis. If the smallest effect your DV can reliably detect is larger than the effect you're hypothesizing, you're measuring the wrong thing or using the wrong tool. Can another researcher replicate this DV from your description? If your methods section requires interpretation to implement, it's not specific enough. Getting the dependent variable right is the single highest-leverage decision you'll make in study design. Everything else — sampling, randomization, statistical power — matters less if the outcome you're tracking doesn't actually correspond to the phenomenon you claim to be studying. Spend the time upfront. It saves months of revision and prevents the slow death of a paper that looks fine until someone actually tries to reproduce it.